The number of concerned users regarding data privacy and digital security continues to grow, as the need to evaluate cloud storage options based on data protection rather than only on price & convenience grows. Now, services like Microsoft OneDrive and Proton Drive take very different approaches to cloud storage – one integrated very tightly into a mainstream productivity system, and the other focused on protecting your privacy first.  

When deciding which service to use, one has to assess trade-offs in terms of usability, encryption capabilities, accessibility, and the level of control you want over your own data. As Cloud storage becomes increasingly integrated into everyday workflows, these issues will become increasingly important to both individual users and organizations.  

Cloud Storage in the Age of Data Risk  

With the growing number of individuals using cloud storage services to store, share, and collaborate on documents, and to access their data remotely, there are serious concerns about the security of sensitive personal data stored on these sites. Specifically, users are worried about data breaches, surveillance, and unauthorized access to their data that could occur when storing data on these public cloud storage solutions.  

Therefore, users have begun searching for alternative solutions that offer an easy way to store their data and robust security measures to protect them from these risks, leading many to express interest in “privacy-focused” cloud storage solutions.  

Both Microsoft OneDrive and Proton Drive offer solutions that address some of these users’ needs; however, they approach them quite differently.  

OneDrive: Integration and Accessibility  

Part of the Microsoft ecosystem, OneDrive provides seamless integration with apps including Word, Excel, and PowerPoint, as well as Windows, making it an easy choice for anyone using Microsoft’s productivity suite.  

OneDrive has many features, including real-time collaboration, automatic backups, and syncing of all your devices, making it extremely beneficial for both teams and individuals who need to work efficiently and share files easily.  

Although OneDrive offers security features, such as encryption of data while it is being transmitted and once it has been stored, it does not provide full encryption capabilities by default for all files. Because of this, Microsoft can access your information under certain conditions, which could be problematic for privacy-oriented users.  

Proton Drive: Privacy-First Architecture  

By utilizing end-to-end encryption, Proton Drive provides users with the highest level of security and privacy possible. The files you upload to Proton Drive are encrypted on your own device before they are uploaded; no one else will be able to see them.  

In this way, users can rest assured that their private files are protected from service providers and other individuals who may be watching them from the outside. This feature is especially beneficial for those concerned about their files being monitored or accessed without their permission.  

Proton Drive is part of the Proton product suite, which also offers encrypted email and VPN services. This suite appeals to users seeking comprehensive online privacy and security.  

Comparing Security and Encryption  

When choosing a cloud storage solution, security is one of the biggest factors to consider. While both OneDrive and Proton Drive encrypt your information, they do so in different ways.  

OneDrive uses standard encryption for data in transit and at rest. This suffices for most users, and Microsoft also offers two-factor authentication and ransomware protection.  

On the other hand, Proton Drive uses end-to-end encryption; therefore, only the user can access their data. This provides a higher level of privacy than OneDrive, though some features, such as real-time collaboration, are not available with this method.  

Ultimately, your choice of cloud storage solution will depend on whether you prioritize convenience or data security.  

Usability and Feature Set  

Microsoft’s OneDrive dominates the usability category because of its integration with so many common productivity tools. Users can edit cloud-based documents directly in the cloud, collaborate with others in real time, and access their files easily from any device.  

Proton Drive continues to improve very quickly but has a more streamlined feature set focused on securing and sharing; its user interface is simple but doesn’t offer all the advanced collaboration tools available in OneDrive.  

For users who need extensive productivity features, OneDrive may be the more practical choice, while Proton Drive appeals to those who prioritize privacy over functionality.  

Performance and Accessibility  

When evaluating performance, fast, reliable access to files is an important factor for both consumers and business users. OneDrive uses Microsoft’s global infrastructure, providing fast, high-speed access to your files and reliability.  

Proton Drive’s performance is considered secure, but due to the time required to encrypt all files, users may experience latency while waiting for their files to become available. For many consumers, this is an acceptable trade-off given the increased privacy Proton provides.  

Lastly, the two applications’ accessibility is very different; OneDrive supports more platforms and offers deeper integration with the operating systems on its users’ computers.  

Pricing and Storage Options  

There are different pricing models for each of these services, based on the amount of space you require and the additional functions you would like to add. In most cases, when someone buys the Microsoft 365 suite of products, they get access to OneDrive as part of that purchase, which provides free online storage and the ability to work with the various Microsoft software applications using OneDrive. Proton Drive offers multiple pricing tiers, with all plans based on encrypted, secure files.  

When comparing prices, it’s important for consumers to keep both their storage needs and their budget in mind.  

The Growing Importance of Privacy-First Storage  

As concerns about data security grow, there will be greater demand for secure, privacy-focused methods for storing information. Today’s users are more aware than ever of how their information is stored, and they want access to solutions that give them greater control over their data.  

As a result of this growing awareness, there will likely be continued innovation in the market, with new and enhanced features and capabilities across mainstream storage services as well as smaller, up-and-coming privacy/personal data storage services, leading to more secure and efficient storage options for users at an unprecedented level.  

Conclusion: Balancing Privacy and Productivity  

Comparing Microsoft OneDrive to Proton Drive illustrates an overall trade-off between convenience and privacy in cloud storage. On the one hand, OneDrive is easier to use due to its integration with other Microsoft Office products; on the other hand, Proton Drive provides stronger data protection with end-to-end encryption.  

When choosing cloud storage, each user must weigh their individual requirements against these two factors to make the best possible selection. As our digital world continues to evolve, the balance between productivity and privacy will remain a constant concern when choosing a cloud storage option.
Source: Securely save and share what’s important 

NVIDIA is creating AI-enabled workstation units that leverage the latest technology to run demanding tasks locally, minimizing long-term operating expenses. NVIDIA’s goal is to provide high-powered desktop and notebook computers that can deliver the same level of capabilities, or better, across a wide range of potential uses of Cloud-Based AI.  

The increasing number of companies implementing AI into their daily operations is placing substantial burdens on all companies, as well as on their budgets to run models in the cloud. Therefore, to achieve fast response times, ensure reasonable control over data, and maintain consistent financial cost structures, NVIDIA is focusing on migrating a portion of these workloads to physical equipment.  

The Rising Cost of Cloud-Based AI  

Cloud-based computing has become crucial for AI scaling, providing large amounts of powerful compute infrastructure without requiring upfront capital investments in hardware. But with increased use of cloud services come higher operating costs, including compute time, storage, and data transfer.  

Organizations that operate AI workloads continuously or at large scale can see these costs mount rapidly. Subscription-based pricing models and the demand for high-performance GPUs create significant ongoing costs associated with cloud AI.  

By promoting on-device processing, NVIDIA addresses an increasing need for cost-effective alternatives to reduce reliance on external infrastructure.  

RTX Workstations and Local AI Processing  

NVIDIA’s RTX workstations serve as the foundation for this workforce shift. The RTX workstations have the processing power to run sophisticated AI workloads and other computationally intensive tasks. A few examples of these types of tasks include 3D modeling and rendering, simulation, machine learning, and real-time data processing.  

RTX systems are engineered for Artificial Intelligence and do not use conventional workstation hardware. However, they do possess specialized hardware features designed for artificial intelligence workloads, such as Tensor Cores, that accelerate deep learning and enable users to run or train their models locally, where they were previously limited by speed restrictions in the Cloud.  

NVIDIA’s workstation strategy revolves around enabling individual users and teams to access AI capabilities at the Enterprise level.  

Reducing Latency and Improving Performance  

On-device AI processing has a major advantage by reducing latency. Processing data close to the user means that there is no need to transfer data over a network and wait for a remote server to respond, so actions can be executed much faster.  

This is especially important whenever an application requires real-time operation, such as video editing, simulation, or interactive design, so users can work more productively without disruptions caused by network latency.  

With NVIDIA hardware, high-performance AI capabilities will enable desktop environments to run this type of processing efficiently.  

Enhancing Data Privacy and Security  

Another issue why companies are moving towards localized AI processing is data privacy. Cloud-based systems require data to be transferred and stored outside their premises, which creates potential compliance and security risks for companies.  

Organizations can control their sensitive information by storing it on their local computers. This is important for industries like government, finance, and healthcare, where data protection is of utmost importance.  

NVIDIA’s workstation solutions enable companies to achieve high-performance computing while maintaining their own data governance.  

Supporting Creative and Technical Workflows  

Many professionals use RTX workstations for creative and technical applications, including engineering, architecture, scientific research, and media production. Workflows that use RTX workstations can benefit from AI capabilities, which automate some parts of these processes by providing advanced analysis and automation tools.  

One example of how AI can help with these kinds of workflows is that designers can create photo-realistic renderings with AI by simulating lighting effects. A similarly complex example is that engineers can use AI to run simulations in a fraction of the time it would take without it. Those who make videos can also use AI for tasks such as upscaling, noise reduction, and other effects.  

As a result of this position, NVIDIA is marketing its hardware as relevant and as providing the foundation for people using AI to leverage the local resources they have to do more with them.  

Balancing Cloud and Local Infrastructure  

Although on-device AI can deliver significant value, there is still a need for cloud use; many companies are looking to implement a hybrid approach that makes full use of both their internal computing resources and those available in the cloud.  

By using local resources for all routine operations or where latency is critical and then performing large-scale training or data processing in the cloud, businesses can better align their cost and performance objectives with their actual use case.  

NVIDIA has created products that easily integrate with the cloud, providing customers with multiple options for ongoing deployment.  

Economic Implications for Businesses  

Running AI workloads on-premises could significantly change the economic landscape for many organizations by reducing their reliance on the cloud and making their recurring expenses more predictable through improved budgeting.  

While the initial cost of buying hardware to run these workloads may be high, over time, the savings from reduced reliance on the cloud will offset this initial investment. In addition, on-premise processing of AI workloads can lead to increased employee productivity, thus improving the overall ROI.  

NVIDIA’s workstation ecosystem is well-positioned as a long-term solution for controlling AI-related costs.  

Challenges in Scaling On-Device AI  

Scaling on-device artificial intelligence has benefits; however, there are several hurdles to overcome. Because of their high-performance requirements, workstations require abundant electrical power and cooling, which hinders mobility and complicates operation.  

Managing and optimizing local AI systems will necessitate specialized skills from team members. Organizations must ensure their team members have the skills necessary to use such capabilities effectively.  

NVIDIA will continue to provide software tools/subsidiary support for companies experiencing these challenges.  

The Future of Distributed AI Computing  

On-device artificial intelligence is just one example of distributed computing, in which processing tasks are performed across many local machines rather than relying solely on a single central server. This model has many advantages, including greater power efficiency, fault tolerance, and scalability.  

As processors continue to improve, more types of AI workloads will begin moving to local devices, reducing reliance on large data centers or corporate clouds to run. As a result, we could see a more balanced and much more sustainable computing ecosystem.  

NVIDIA’s strategy for its workstations reinforces this vision with an extreme focus on flexibility and performance.  

Conclusion: Redefining AI Infrastructure Economics  

The drive by NVIDIA for workstations enabling AI computation indicates changing attitudes toward computing infrastructure in organizations. By supporting high-performance processing locally rather than relying on cloud-based technologies, NVIDIA is delivering an alternative model that lowers costs, increases device capability and performance, and improves data control.  

As more organizations implement AI, how they balance local and cloud computing resources will be a key determinant of the direction technology will take in the future. Therefore, workstations with powerful GPUs will constitute an important part of this emerging environment. 

Source: Artificial Intelligence Introducing NVIDIA Ising 

In 2026, artificial intelligence is no longer operating in a regulatory grey zone. Governments are actively shaping how AI systems are built, deployed, and monitored especially in high-risk sectors like finance, healthcare, and national infrastructure. 

Recent updates from the United States Department of the Treasury signal a shift toward stricter oversight, particularly around risk management, transparency, and accountability in AI-driven systems. For businesses, this means one thing: compliance is becoming as important as innovation. 

Business Implications of AI Policy 

AI-based regulations should not only reduce risk but also establish clear boundaries for AI use. Businesses that do not remain aware of policy changes could be exposed to litigation, negative public perception, and/or forced to shut down operations completely for violating these policies. 

AI adoption is increasing rapidly; therefore, regulators overseeing AI systems are increasing their attention to ensure they are safe, fair, and understandable. Policy changes that will have an effect on companies implementing AI technologies fall into five major categories: 

1) Data Governance and Data Usage Rights 

2) Algorithm Transparency Requirements 

3) Bias Detection and Mitigation 

4) Cybersecurity of AI Systems 

5) Accountability for Automated Decisions 

Examples of New AI Policy Guidelines in the US (2026) 

1. The Government of the United States is shifting more towards implementing Regulation Frameworks for the use of AI in a Risk-Based approach versus a uniform regulation model. High-risk AI applications include, but are not limited to, financial decision support, healthcare diagnostics, and recruitment/selection algorithms. These high-risk AI systems now have stricter documentation, validation, and monitoring compliance requirements. 

Categorizing AI systems into Risk-Based categories continues to enable innovation in Low-Risk AI applications while providing increased supervision of High-Risk AI applications. 

2. Mandatory Transparency and Explainability 

One of the biggest shifts in AI policy is the push for transparency. Businesses must now explain how their AI systems make decisions especially when those decisions affect individuals. 

This includes: 

  • Clear documentation of training data 
  • Explanation of algorithmic logic (where possible) 
  • Disclosure when users are interacting with AI 

For companies relying on “black box” models, this creates a significant operational challenge. 

3. AI and Cybersecurity Integration 

AI systems are now considered part of an organization’s cybersecurity infrastructure. This means they must meet the same security standards as other digital assets. 

Policy updates emphasize: 

  • Securing training data pipelines 
  • Protecting models from adversarial attacks 
  • Monitoring AI systems for abnormal behavior 

This aligns AI governance with broader cybersecurity frameworks recommended by agencies like the Cybersecurity and Infrastructure Security Agency. 

4. AI-Resulting Accountability Increase 

Businesses cannot simply transfer responsibility to the algorithms anymore. If any harm or bias arises from the AI systems used, it becomes the responsibility of the company operating them. 

The implications are: 

  • Legal liability for discrimination in outcomes from using AI 
  • Human oversight is required in critical systems that utilize AI 
  • Automatic trace/track for automated decision-making processes 

This shows that the shift in AI technology from experimentation to regulated deployments is underway. 

5. Coordinating AI Policies across Agencies 

No longer is there only one authority overseeing the regulation of AI technology; rather, multiple agencies, such as finance, defense, and consumer protection, are involved with one another. 

This establishes a more inclusive, while complicated, regulatory environment around businesses using AI technologies. 

This means that the companies will have to: 

  • Navigate through overlapping compliance requirements from several authorities 
  • Ensure their AI products and services comply with several different standards 
  • Maintain awareness of regulatory changes across the multiple domains involved. 

What should businesses do now? 

To adapt to AI policy changes, businesses must take a proactive approach. If they wait for an enforcement action, they will have much higher costs and significantly more disruption. 

Some practical actions include: 

1. Conducting AI risk assessments across all systems, 

2. Implementing transparency and documentation processes for AI, 

3. Aligning AI governance with cybersecurity frameworks, and 

4. Training all team members on compliance and the ethical use of AI. 

Not only do these actions help mitigate risk, but they also improve system reliability and increase trust in systems. 

Conclusion 

Although regulation can be restrictive, ultimately it will create a more stable AI ecosystem. When businesses have a clear set of rules for compliant operation, they can confidently scale without worrying about constant uncertainty. 

Businesses that proactively accept policy changes will have a competitive advantage; by building compliant systems, they will create systems that are both innovative and trustworthy.

Source-Treasury Releases Two New Resources to Guide AI Use in the Financial Sector 

Cloud computing now supports most business operations, from daily teamwork to major digital transformation projects. As companies rely more on cloud services, the financial impact grows. Gartner predicts global spending on public cloud services will top $720 billion in 2025, up from nearly $600 billion in 2024.  

The cloud offers businesses great flexibility and scalability, but its pay-as-you-go pricing and complex billing can lead to unexpected costs. Many companies are now developing effective strategies to manage and reduce these expenses. Solving this problem takes more than quick fixes. It requires a broad approach that includes knowing industry trends, using practical cost management methods, and following best practices across the organization.  

Understanding The Types Of Cloud Costs 

To manage cloud costs well, you first need to know where they come from. Cloud pricing can be confusing with options like pay-as-you-go, reserved instances, and custom deals. Each provider has its own pricing model, which makes planning even harder.  

Here are the core cost drivers in cloud computing:  

  • Compute costs are the expenses for the processing power needed to run applications. These are often the highest costs, depending on the type and number of virtual machines and how long they are used.  
  • Storage costs depend on how much data you store and for how long. Choices about storage types and how long you keep the data can greatly affect your total spending.  
  • Data transfer costs are the fees for moving data into, out of, or between cloud services and regions. These costs can add up faster than expected.  
  • Support costs are the fees for choosing higher levels of customer support. More support usually means higher costs.  

Recently, storage costs have risen significantly. Cloud providers now offer more flexible pricing options, but this means customers need to watch their cloud usage more closely.  

Cloud Cost Challenges And Trends 

As companies use more cloud services, they face changing market pressures and internal challenges that raise costs and make management harder.  

A major challenge is the rising cost of cloud services. While providers now offer more flexible pricing, this does not always make things easier. Companies need to be more careful when choosing and using resources, especially since storage costs are rising quickly.  

Hidden Costs 

Hidden costs are also a big problem, especially egress fees, which are charges for moving data out of the cloud. Many businesses overlook these costs and are surprised by large bills when moving workloads or accessing data in different environments. These fees can limit a company’s ability to switch providers and may leave important data unused or isolated, hindering analytics and innovation.  

Hybrid (complexity) 

The growing adoption of hybrid cloud strategies adds yet another layer of complexity. While leveraging multiple providers can make things even more complex, working with several providers can improve performance and resilience, but it also makes tracking and budgeting costs harder. Running without centralized oversight, much like forgotten subscriptions that can quietly drain budgets.  

Lack Of Visibility 

A lack of visibility compounds these issues. Without clear visibility, these problems are worse. Without real-time insight into who uses which resources and why, it is almost impossible to control cloud spending. In fact, only three out of 10 organizations know exactly where their cloud money goes, so most are at risk of waste and surprise costs. (Splunk enables end-to-end visibility, no matter how complex the enterprise. Learn more about our other solutions.) It’s more complex than ever to remain competitive and maintain financial control. Organizations must proactively address both the external forces driving up prices and the internal practices that can lead to waste.  

Smart Strategies for Cloud Cost Reduction 

The good news is that companies can take practical steps to solve these problems and get more value from their cloud spending. Using smart tactics and regular monitoring can lead to big savings and better efficiency.  

Right Sizing 

Right-sizing is one of the best strategies. It means adjusting computing resources to exactly match workload needs. By analyzing how applications use resources, companies can choose the right instance types and sizes, avoiding excess capacity that increases costs.  

Savings Plans 

Another effective tactic is using reserved instances and savings plans. These let businesses commit to a set amount of usage, usually for one or three years, in return for lower prices than on-demand rates. This works best for steady workloads and can save a lot of money over time.  

Regular Audits 

It is also important to regularly check a cloud setup to find and remove waste. This includes:  

  1. Finding idle virtual machines, outdated snapshots, or unnecessary storage  
  1. Removing them to ensure you are only paying for what you truly need. Organizing resources with tags and good metadata management improves visibility and accountability. By tagging resources and by department, project, or application, companies can track usage, assign costs correctly, and find ways to optimize.  

Automation 

Automation is another strong tool for controlling costs. Setting up auto-scaling, scheduling shutdowns for resources you do not need all the time, and using cloud management tools help make sure cost-saving steps are used regularly and effectively.  

Machine Learning and Advanced Technologies for Cost Management 

As cloud setups become more complex, companies are using advanced tools such as machine learning (ML) to better see and control their costs. ML helps analyze usage patterns and spot unusual activity that might otherwise go unnoticed.  

For example, ML algorithms can:  

  • Detect sudden increases in cloud usage that may indicate a problem or inefficiency.  
  • Analyze historical data to forecast future usage and costs, enabling more accurate budgeting.  
  • Recommend optimizing resources by resizing or switching to more cost-effective pricing plans.  
  • Take automated actions, such as scaling resources up or down in real time, to ensure businesses only pay for what they really need.  

By using ML, companies can shift from reacting to costs to a more proactive, data-driven way of managing them. This reduces waste and increases the value of their cloud investments.  

Organizational Practices For Sustained Cost Management 

Good cloud cost management is not just about quick fixes. It also means building cost awareness and best practices into the whole organization.  

Center of Excellence 

Establishing a cloud or observability center of excellence (COE) is a key first step. A COE brings together teams from different areas to set standards, rules, and best practices for cloud use, ensuring that every department works towards the same goals.

Source: Cloud Cost Management & Trends in 2026: Strategies to Optimize Your Cloud Spend 

Speed gives machine learning teams a real edge, but most discussions miss the point. GPU guides usually focus on TFLOPS benchmarks, but what really matters is how quickly you can go from writing code to running it. If a platform can set up a GPU cluster in 30 seconds instead of 20 seconds, it’s not much more convenient. It lets teams experiment more, iterate faster, and get to useful results sooner.  

Cost isn’t just about the hourly rate either. Transferring large datasets can result in egress fees that exceed the cost of GPU usage for a training run. If you’re billed by the hour, finishing a job in 40 minutes still means paying for the full hour. Platforms that bill by the second and don’t charge for egress can be 30% to 40% cheaper than those with lower advertised rates but hidden fees. This review looks at five GPU cloud providers with all these factors in mind.  

Civo 

Civo stands out by offering Kubernetes native architecture, on-demand GPU access, zero egress fees, and sovereign cloud options. Most platforms force you to pick between developer convenience and robust infrastructure, but Civo believes you can have both.  

Clusters are ready in less than 90 seconds. You can get A100, H100, and B200 GPU instances on demand or as preemptible options. The B200 preemptible starts at $2.69 per GPU-hour, which is a good price for Blackwell-generation hardware. Egress is free within the platform, so there are no unexpected costs for large training jobs. Teams running distributed training across several nodes can use Kubernetes native multi-node cluster support, so scaling up doesn’t need extra orchestration tools.  

The $250 free-trial credit is enough for a month of real workloads, not just small test workloads. This lets ML teams test the platform with real experiments before making a decision. For teams in regulated sectors that need sovereign cloud for their AI workloads, which rules out most GPU cloud providers, Civo’s UK and EU sovereign deployments are a practical choice.  

  • A100, H100, and B200 GPU instances; B200 preemptible from $2.69/GPU/hour  
  • Kubernetes native multi-node cluster support; sub-90 second provisioning  
  • Zero egress fees within the platform  
  • UK and EU sovereign cloud options for regulated workloads.  
  • ISO 27001, SOC 2, and Cyber Essentials certified  
  • $250 free trial credit for one month  

RunPod 

RunPod uses per-second billing and offers two options: community cloud for lower costs and secure cloud for teams that need greater isolation. H100 PCIe starts at about $2.39 per hour on the community tier, H100 SXM at $2.69 per hour, and B200 on-demand at $5.98 per hour. There are no egress fees, making it easier to calculate the total cost compared to platforms that charge for outbound data.  

The pre-built AI template library helps teams set up environments faster, which speeds up iteration even if it is not shown in benchmarks. With over 30 global regions, most users get low-latency access. However, RunPod does not offer Kubernetes native orchestration or sovereign cloud options, so it may not be the best fit for regulated workloads or teams that want orchestration built into the platform.  

Best for: ML teams that want per-second billing, pre-built AI templates, and competitive H100 access without enterprise compliance requirements.  

  • H100 PCIE from $2.39/hour community cloud; H100 SXM from $2.69/hour; B200 from $5.98/hour  
  • Per-second billing; no egress fees  
  • Pre-built AI and ML templates; Docker Native  
  • 30 + global regions  

Scaleway  

ScaleWay is the strongest European GPU cloud option in this review. It offers H100, SXM, and L40S instances on demand from Paris and Amsterdam data centers, and Blackwell 300 hardware is available for pre-registration. Managed Kubernetes with Kapsule lets teams orchestrate Kubernetes without managing their own clusters.  

ScaleWay is a French-owned e-provider, so its data remains within the EU, which matters for teams subject to GDPR or other EU regulations. Its commitments to renewable energy-powered data centers are a strong sustainability claim in Europe. Pricing is competitive for EU-based GPU access, and the free tier lets teams try the service without any upfront cost.  

Best for: European ML teams that need EU sovereign G-GPU infrastructure, managed Kubernetes, and competitive pricing.  

  • H100, SXM, and L40S GPU instances on demand; B300 Blackwell in pre-registration  
  • Managed Kubernetes (Kapsule); EU sovereign data centers.  
  • French-owned; GLR-compliant; renewable energy-powered data centers.  
  • Free tier available  

TensorDock  

TensorDock’s H100 SXM5 instances start at $2.25 per hour on demand, with spot pricing from $1.30 per hour. The lower spot price is especially good for training runs that can be checkpointed. The platform uses KVM virtualization and gives full VM access, so it supports Windows workloads and custom OS setups that container-based platforms can’t handle. TensorDock also requires its hosts to meet a 99.99% uptime standard, which is higher than most marketplace-based platforms.  

Egress pricing details are not established, which makes it harder to estimate total costs for large projects. There is no Kubernetes-native option or sovereign cloud support for ML teams that need Windows-based pipelines or have specific OS requirements. TensorDock’s KVM model is a useful advantage.  

Best for: ML teams that need competitive H100 access with full VM control and Windows support, where KVM flexibility matters more than managed orchestration.    

  • H100 SXM5 from $2.25/hour on demand; spot from $1.30/hour; RTX 4090 from $0.37 per hour  
  • KVM virtualization; full VM access; Windows support  
  • 99% uptime standard applied to all hosts.  
  • No managed Kubernetes; no sovereign.   

Vast.ai 

Vast AI’s marketplace can offer H100 instances from about $0.90 per hour and A100 PCIe from about $0.52 per hour. These rates make dedicated platforms look expensive by comparison. For researchers running cost-sensitive experiments that checkpoint often and can handle some interruptions, the pricing is very attractive and genuinely compelling.  

The downside is less reliability and predictability. Hardware quality, host behavior, and egress costs vary by host. There is no platform-wide SLA for production insurance, regulated workloads, or jobs where a failed run would be costly. This risk makes Vast AI less suitable, no matter how low the price.  

Best for researchers running checkpoint-friendly experiments on a tight budget where cost savings outweigh the risk of variable reliability.  

  • At 100 from 0.90/hour marketplace; A100 PCIe from 0.52/hour  
  • Competitive bidding drives the lowest raw rates in this comparison.  
  • Reliability variable by host; no platform-wide SLA  
  • Not sorted for production inference or regulated workloads  

What to Look for in a GPU Cloud Service for Machine Learning 

  • Provisioning speed, time to run a cluster, is a genuine productivity metric. Platforms that provision GPU instances in under a minute enable significantly faster iteration cycles than those with 15 to 20-minute setup times.  
  • Billing model. Per-second billing reduces waste on short jobs. Hourly billing is often fine for sustained training runs, but can add up quickly on jobs that complete in fractions of an hour.  
  • Egress fees. Moving large datasets and model checkpoints can cost money on many platforms. Zero egress platforms eliminate this variable from total cost calculations.  
  • Multi-node support. Single GPU training is fine for smaller models. For large-scale distributed training, the platform needs to support multi-node clusters natively or with minimal configuration overhead.  
  • Regulatory suitability. If the workload involves sensitive data or operates under sector-specific compliance requirements, GPU access is only part of the question. The sovereignty and certification picture matters as much as the compute.  
  • The A100 GPU generation handles most current training tasks well. H100 offers meaningful improvements for transformer-based workloads. B200 Blackwell is the current generation but has more limited availability across providers.

Source: 2026’s Best GPU Cloud Services for Fast, Cost-Effective Machine Learning 

Equinix Inc, a leader in digital infrastructure, has announced Equinix Fabric Intelligence, an AI-based platform for managing network infrastructure. This new solution helps businesses use AI-powered networking across their operations, moving away from older, infrastructure-defined networking to simplify today’s AI workflows. Fabric Intelligence, which supports the Equinix distributed AI hub, brings smart automation to deploying, optimizing, and maintaining global infrastructure. This provides organizations with a stronger, more efficient, and more flexible foundation for their AI workloads.  

“The whole concept of AI is to make processes faster, and manual processes for network monitoring and management are difficult, if not impossible, to scale effectively,” said Jim Frey, principal analyst at Omdia. “Our research shows ninety-three percent of organizations agree that network automation will be essential for keeping pace with future change, and eighty-eight percent also agree that AI itself will be required for effective network automation. With Fabric Intelligence, Equinix is providing enterprises with an AI-driven control plane for deploying, activating, and managing multi-cloud networking to help meet, to help them meet the scale and automation needs of the distributed AI era.”  

AI works best in fast, connected environments, but many companies still use slow, outdated network systems that can’t keep up with modern AI needs. As more businesses use AI, traditional network teams are finding it hard to keep pace. Manual processes cause delays, long setup times, slow growth, and limited visibility, making things harder. AI needs real-time, flexible networking, which is leading to more AI-assisted network operations that can quickly interpret data and respond. This is creating a wider gap between how quickly AI advances and what current networks can handle.  

Fabric intelligence automates how AI workloads connect and run across clouds, data centers, and edge locations. It gives organizations an easier way to handle the complexity of AI by automating the setup, configuration, and maintenance of connections across these environments. This means systems run smoothly without constant manual work, so teams can focus on bigger goals, such as developing new AI features and expanding their operations.  

“All enterprises are focused on leveraging AI to transform their business, but most lack the infrastructure needed to deploy it at scale in ways that drive their growth,” said Jon Lin, chief business officer at Equinix. “As agentic AI matures and inferencing applications proliferate across the enterprise, networking infrastructure needs to be faster and more flexible than before. Fabric intelligence turns infrastructure from a constraint to a competitive advantage by enabling our customers to spend less time managing complexity and more time moving their business forward.”  

Fabric Intelligence offers a set of AI-based tools that let businesses design, deploy, and manage their infrastructure with easy-to-use features such as natural language, automated workflows, and predictive insights. With its network of 280 data centers in 77 cities worldwide, Equinix is helping more businesses adopt AI tools and modern infrastructure. Earlier this year, Equinix became a gold member of the Agentic AI Foundation (AAIF), which supports open and collaborative development of agentic AI. This step will help create a secure and ready foundation for the global autonomous economy.  

Fabric Intelligence is part of the Equinix Fabric portfolio, which serves over forty-four hundred customers worldwide. It includes these main components:  

Fabric Super Agent 

  • This AI super agent lets customers manage their networks independently via simple natural-language requests via Slack, Microsoft Teams, or the Equinix Console customer portal.  
  • Fabric super agent cuts deployment times from weeks to minutes. It removes the need for users to deal with complex interfaces or learn APIs by offering automated recommendations, setup help, and real-time performance insights for designing, deploying, and running networks.  

MCP Server 

  • This is a set of AI-ready management tools that make it easier to connect AI systems to complex networks. It enables fast, high-performance service creation and testing with minimal delays.  
  • Model Context Protocol (MCP) servers enable customers to connect to leading AI clients, including Claude Code, OpenAI Codex, VS Code, Copilot, and Cursor. This allows developers to use their favorite agents within their network operations environment.  

Fabric Application Connect 

  • This is a private, dedicated marketplace where businesses can connect with AI service providers for inference, training, storage, security, and other key AI services without putting sensitive data on the public internet. It helps companies develop and launch new AI applications and workflows securely.  

Fabric Insights 

  • AI-powered network monitoring that analyzes real-time telemetry to predict anomalies and manage network health integrates directly with security information and event management (SIEM) platforms such as Splunk and Datadog, as well as the Fabric Super Agent.  

Fabric Agent is now available for preview. To get more information and request access, please register your interest here. Demonstrations of Fabric Intelligence will be available at the Equinix Booth (7101) at Google Cloud Next 2026 

Source: Equinix Accelerates Enterprise AI Workloads with Launch of Fabric Intelligence 

Artificial intelligence is creating a huge need for computing power. Large language models and self-governing systems all rely on GPUs, which have become the main force behind today’s AI progress. Originally made for gaming, GPUs now set the pace, scale, and cost of deep learning systems.  

Decision-makers often ask which GPU offers better value for AI: AMD or Nvidia. NVIDIA leads with its well-developed CUDA software and large market share. However, AMD’s Instinct GPUs are catching up fast, offering more memory, open-source options, and strong performance at lower prices.  

This article aims to help developers, IT managers, and founders make smart choices. It looks at hardware differences, benchmark results for training and inference, and compares the CUDA and ROCm software platforms. The article also covers GPU costs and highlights new decentralized GPU marketplaces, such as Fluence, as affordable alternatives to traditional cloud services.  

The Contenders: AMD Versus NVIDIA 

The AI hardware market is mainly a competition between two companies. NVIDIA is the established leader, with its GPUs supporting most major AI advances over the past few years. AMD is the challenger using its Instinct series to compete with NVIDIA on both performance and price.  

NVIDIA: The Reigning Champion 

NVIDIA’s strength in AI goes beyond its hardware. Its main advantage is CUDA (Compute Unified Device Architecture), a software platform that has grown over almost 20 years. CUDA works closely with machine learning frameworks, provides optimized libraries, and offers an easy setup that works right away. For most people working in AI, CUDA is the standard choice.  

NVIDIA offers a wide range of GPUs for data centers covering all performance needs:  

  • A100: A solid selection for enterprise AI training and inference.  
  • H100/H200: The latest high-performance models featuring advanced tensor cores and the transformer engine for faster model training.  
  • Blackwell: The next-generation design is made for very large models and efficient operation at scale.  

Because of its cutting-edge hardware and strong software support, NVIDIA remains the top choice for teams that value reliability, a strong ecosystem, and unwavering performance.  

AMD: The Resurgent Challenger 

AMD is making a strong comeback in AI. Its Instinct accelerators, especially the MI200, MI300X/M1325X, and the upcoming MI350X, are serious competitors to Nvidia in the data center market. These GPUs offer high memory capacity and bandwidth, which are important for running today’s large models.  

While NVIDIA focuses on its own stable, proprietary systems, AMD supports open-source solutions. Its ROCm (Radeon Open Compute) platform is a fully open-source alternative to CUDA, giving developers more control and flexibility and helping them avoid vendor lock-in. With lower prices and high performance, AMD offers a high-efficiency, budget-friendly choice for AI infrastructure.  

AMD’s approach is to compete by supplying scalable performance, more memory, and an open ecosystem that stimulates innovation rather than trying to match every NVIDIA feature.  

Architectural Showdown: What Lies Beneath the Silicon? 

NVIDIA and AMD both aim to accelerate AI at scale, but they take very different approaches. NVIDIA uses specialized AI accelerators, such as Tensor Cores and the Transformer engine, designed for deep learning tasks that rely heavily on matrix operations. On the other hand, AMD focuses on raw compute power and high memory bandwidth using many compute units and large memory stacks to boost performance for big models.  

These differences shape what each company does best. NVIDIA aims for precision and efficiency using mixed-precision training to get the most out of performance and memory. AMD prioritizes capacity and parallel processing, enabling larger models to run on a single GPU and reducing the need to split models or use complex parallel setups. NVIDIA focuses on efficiency, while AMD delivers more raw power.  

AMD’s chiplet-based CDNA design offers greater manufacturing flexibility and helps lower costs. In contrast, Nvidia’s single-piece design is more power-efficient and better optimized for AI tasks. Both have their strengths: Nvidia is tuned for efficiency, while AMD is built for handling larger workloads.  

Performance Deep Dive: Benchmarks and Real World Results 

Specs alone don’t give the full picture. Real-world AI tasks show how these designs perform in practice. There are two main ways to measure GPU performance in AI: training, where models learn from large datasets, and inference, where trained models make predictions. Training requires significant computing power, while inference benefits from fast memory and low latency.  

Large Language Model Training 

Independent benchmarks from sources such as MLPerf, SemiAnalysis, and Tom’s Hardware consistently position NVIDIA and AMD neck and neck with distinct strengths.  

  • AMD’s advantage: the Instinct MI300X (192 GB) and MI325X (256 GB)offer unmatched memory capacity, allowing developers to train large models directly on a single GPU without complex tensor or data parallelism. This simplifies the pipeline and reduces interconnect overhead.  
  • NVIDIA’s H100 uses the transformer engine to accelerate mixed-precision (FP8/BF16) training, enabling many large language model tasks to be trained much faster. This focus on precision still gives NVIDIA an advantage.  
  • For comparison, the MI300X is about 14% behind the H100 in raw BF16 TFLOPS, but in some construction-throughput tests, it can be up to 5 times faster, depending on the workload type.  

In practice, AMD’s bigger memory helps researchers train very large models from start to finish. Meanwhile, NVIDIA remains the top choice for teams looking to train models as quickly as possible.  

AI Inference: Latency and Throughput 

Inference has its own challenges, mainly speed and the ability to handle many users at once. Two important measures are latency, which is how long it takes to get the first result, and throughput, which is how many results you get per second. These affect how well the system works for users.  

  • Benchmarks show that the MI300X can have up to 40% lower latency than the H100 for large models like Llama2 70B. This is mostly because the MI300X has higher memory bandwidth (5.3 TBs compared to 3.35 TBs).  
  • This allows AMD to handle larger models with more users simultaneously, reducing wait times. It makes AMD very efficient for real-time inference and situations where many users share the same hardware.  

Overall, NVIDIA is best for fast and efficient training, while AMD is better for running large models in real time. Most organizations should choose based on their needs: pick NVIDIA for faster development, or AMD for more efficient handling of larger deployments.  

The Great Divide: CUDA Versus ROCm Software Ecosystem 

While hardware sets the limits, software decides how easy it is to use. For developers, the main difference between AMD and NVIDIA is the software ecosystem, which affects how productive, compatible, and flexible their work will be.  

NVIDIA CUDA: The Walled Garden Of Stability 

NVIDIA’s lead in AI is not solely due to its hardware. The company has spent almost 20 years building CUDA (Compute Unified Device Architecture), a software platform that is now the standard for machine learning.  

  • CUDA’s libraries and drivers are highly optimized, ensuring reliable performance across different frameworks and tasks. CUDA is still the main platform behind PyTorch, TensorFlow, and most other major AI tools.  
  • Most AI projects are designed for CUDA. Its easy setup and consistent performance let developers spend more time building models instead of dealing with setup issues.  
  • There is a large global community and plenty of documentation for CUDA, so developers can easily find help when they need it.  

However, this stability has a downside. CUDA is proprietary, which means developers and companies are tied to NVIDIA’s project products. For IT managers who want more flexibility in the long run, this can limit hardware options and make it harder to control costs.  

AMD ROC: The Open Source Rebellion 

AMD’s alternative to CUDA is ROCm (Radeon Open Compute), an open source platform that aims to make GPU computing more accessible. It gives developers more control and transparency, along with a growing set of optimized libraries and integrations.  

  • ROCM is open and flexible, helping developers avoid vendor lock-in. It also encourages community input and works across different platforms.  
  • Rapid mature with the release of ROCM 6X support for PyTorch, TensorFlow, and deep speed is now almost as good as CUDA, making ROCM suitable for production use.  
  • Curve, while still requiring more manual tuning and system-level knowledge, ROCM’s developer experience has improved significantly as the ecosystem matures.  

As a result, ROCm is now a real alternative. It works well in production, especially for teams willing to use open source tools and get more value for their money. For organizations focused on cost and flexibility, AMD’s open-source approach offers important benefits beyond computing power.  

The Bottom Line: A Cost Performance Analysis of GPU Rental Marketplaces 

Most teams can’t afford to buy high-end GPUs like the H100 or MI300X since each card costs tens of thousands of dollars. Renting GPUs has become the usual way to get AI computing power. While cloud providers started this trend, decentralized GPU networks are now changing the cost.  

The Shift To Renting 

Renting GPUs lets teams scale up for training and scale down when they’re done, without having to buy expensive hardware. This keeps costs lower and allows teams to stay flexible.  

DePin and the Fluence Advantage 

Decentralized physical infrastructure networks (DePin), such as Fluence, have made high-performance computing more accessible and transparent. Fluence connects developers with data centers worldwide, providing real-time access to GPUs at up to 80% lower prices than those of major cloud providers.  

Conclusion: Making The Right Choice For Your AI Workload 

There is no clear winner between AMD and NVIDIA GPUs. Both offer top performance, but each is better suited for different needs. The best choice depends on what matters most to you: speed, memory, software ecosystem, or cost.  

Actionable Recommendations 

Pick NVIDIA if your team wants to deploy quickly, uses CUDA-based tools, and needs reliable performance. CUDA’s long track record and strong support make it the safest choice for production AI  

Choose AMD if your tasks require a lot of memory, your budget is limited, or you want open-source options. AMD’s powerful GPUs and improved ROCm platform offer great value, especially for training large models.  

The Strategic Third Option 

If your team wants NVIDIA-level performance at a lower price, decentralized GPU networks like Fluence are a strong option. They give you on-demand access to top hardware like the H100 and A100 at prices up to 80% lower than big cloud providers, with clear billing and no vendor lock-in.  

Competition between GPU makers is heating up, but developers benefit the most. With AMD’s progress and new platforms like Fluence, more teams can now afford powerful computing to build, train, and deploy AI at scale.

Source: AMD vs NVIDIA GPU: Which Performs Better for AI Workloads? 

Fiscal year 2026 marks a shift from artificial intelligence experimentation to a focus on measurable economic results. American enterprises no longer accept proof-of-concept projects; they demand platforms that integrate intimately with core business logic to drive top-line growth and bottom-line efficiency. The market is led by a few dominant players who have bridged the gap between raw model capability and enterprise-grade reliability. Achieving high return on investment requires deliberately selecting a platform that manages cost, speed, and ecosystem compatibility. For US businesses, choosing the best enterprise AI platform is a core decision that dictates long-term competitive resilience.  

Microsoft Azure AI: The Ecosystem Collaboration Leader 

Microsoft Azure AI remains the primary choice for large US organizations standardized on the Microsoft 365 stack. Its strength lies in the native integrations that enable AI agents to pull information from Outlook, Teams, and SharePoint to automate complex administrative workflows. In 2026, the platform’s ROI is driven by specialized agentic frameworks that enable the rapid rollout of autonomous assistants while adhering to strict corporate governance. This solution reduces the need for costly third-party middleware, cutting the time to value for new deployments.  

Azure’s partnership with NVIDIA gives businesses early access to efficient hardware, helping manage rising high-performance compute costs. Using sovereign cloud configurations, government contractors and healthcare providers keep data within secure US-based clusters. This compliance is critical for ROI and for preventing legal and reputational risks from data mishandling. Microsoft’s model lets companies scale automation without rebuilding their digital systems.  

Google Vertex AI: The Data-First Performance Champion 

Google Vertex AI is the top choice for data-intensive fields like finance and research, where long context analysis is critical. Its ability to ingest millions of tokens in a single pass enables organizations to query entire internal binaries or multi-year financial records instantly. This helps break down information silos that slow decision-making in large corporations. For businesses with value locked in massive unstructured datasets, Google’s platform offers the most direct path to turning that data into useful insights.  

Vertex AI’s ROI is boosted by Google custom tensor processing units (TPUs), a cost-effective alternative to standard GPUs for high-volume inference. This hardware independence enables Google to offer reliable pricing, protecting enterprises from global chip market volatility. The platform’s unified data foundation integrates with BigQuery, letting companies run models on their data without moving it. This in-place analytics cuts time and reduces egress fees common in intricate cloud architectures.  

AWS Bedrock and SageMaker: Unmatched Scalability and Choice 

Amazon Web Services (AWS) continues to lead for businesses that require architectural autonomy and the ability to swap between multiple high-performance models. Through AWS Bedrock, enterprises use a diverse library of core models, choosing the logic that fits their budget and latency needs. This multi-model strategy helps companies avoid vendor lock-in and stay flexible as new technologies emerge. AWS’s ROI comes from granular control, letting teams optimize deployments down to the chip level. In 2026, manufacturing firms will benefit from the company’s investment in domestic AI data centers, ensuring that US businesses have the low-latency connectivity required for computer vision and edge computing. AWS also provides advanced expense management tools that enable financial officers to monitor and limit spending in real time. This fiscal transparency is key for maintaining a positive ROI as organizations move from limited pilots to enterprise-wide production.  

IBM Watsonx: the Governance and Reliability Specialist 

For businesses in regulated sectors such as banking and defense, IBM Watsonx offers a platform focused on trusted, transparent AI. Its main ROI driver is auditability, creating a clear, documented path for every autonomous agent decision. This is important for compliance with emerging US AI regulations and international standards. By prioritizing responsible AI early, IBM helps companies avoid costly corrections when black-box models behave unpredictably.  

IBM’s hybrid cloud approach grants data sovereignty, running sensitive models on-premises, while non-sensitive tasks use the public cloud. This suppleness lets enterprises maintain control regarding intellectual property without sacrificing cloud scalability. Watson X effectively reduces technical debt, helping developers modernize legacy code bases and integrate new AI logic. This bridge between the old and the new is vital to long-term digital stability in established corporations.  

Defining The 2026 ROI Horizon 

The move to autonomous enterprise operations has changed the unit economics of intelligence. Success is no longer measured by the number of models deployed, but by cycle time reduction and the accuracy of automated decisions. The best enterprise AI platforms of 2026 act as silent, tireless sentinels, holding the organization’s logic family firmly as digital synapses fire with greater autonomy. The line between the software and the business fades. This clear logic ensures that the enterprise’s future is as bright as the data that sustains it.  

We might one day wake up and find the heavy lifting of corporate reality supported by a thousand hidden threads of integrity. This is the goal of the Sovereign AI Shift: an organization always awake, learning, and ready to serve the common good. We are designers of a realm where machines support our ambitions with the grace of life. By choosing the right platform today, businesses secure their place in a future where intelligence is the most valuable and reliable commodity. 

Source: Equinix Newsroom 

Apple is taking a major step toward reinforcing trust in artificial intelligence by expanding its independent audit programs. The initiative focuses on verifying that its AI systems adhere to strict privacy standards an area where user concerns continue to grow. This move positions Apple at the forefront of privacy-first AI development. 

Why Are Independent Audits Important for AI Technology? 

As Artificial Intelligence (AI) becomes part of daily life, conversations about the proper use of data and privacy continue to grow. 

Independent audits can provide: 

  • External verification of security practices 
  • Transparency in how data is managed (data handling) 
  • Accountability in making AI decisions 

These audits help reduce the gap between a user’s technical complexity and the trust the user has in the product being used. 

Changes to Apple’s Audit Process 

Apple’s audit process is expanding to include the following: 

  • Outside, independent verification of AI models 
  • Periodic evaluations of AI security 
  • Public disclosure of compliance with established standards 
  • Increased scrutiny of how data is processed on devices 

The goal is to ensure that AI models are being used in a manner that complies with established privacy limits. 

Privacy as a Competitive Differentiator 

Apple is different from its competitors because it continues to emphasize privacy as a product feature, not just a post-sale feature. 

The increase in Apple’s auditing process will assist the company in achieving the following: 

  •  Distinguishing itself from the crowded AI marketplace 
  •  Establishing long-term trust with its users 
  •  Reducing the risk of compliance violations from regulators 

Apple’s strategy aligns with consumers’ continually growing demand for transparency in the products they use. A major part of Apple’s AI strategy is on-device processing rather than cloud-based processing. 

Advantages of using on-device processing include: 

  •  The amount of data can be obtained using less bandwidth 
  • The time it takes to process 
  • The user has more control over their data 

Independent audits will help verify that computer systems comply with these claims. 

The impact of Apple on the technology industry 

Apple’s decision could become the new template for the entire technology industry. 

Consequently, companies will feel pressure to: 

  • Implement similar auditing frameworks 
  • Provide visibility into the AI function 
  • Prioritize privacy as part of their design 

The result may be the creation of new industry standards and regulations. 

Barriers to Implementation 

There are several barriers to implementing a large-scale auditing framework: 

  • High operational costs 
  • Complexity associated with AI systems 
  • Rapidly changing threat landscape 
  • Maintaining consistent and credible audits is critical. 

The Importance of Third- Party Verification and Accountability 

The use of independent third-party auditors is crucial to Apple’s program. Third-party auditors will add objectivity and independence in the evaluation process. 

In addition, the use of third-party verification will: 

  • Remove potential for internal bias 
  • Enhance the public’s trust in the organization 
  • Maintain compliance with international standards. 

Increased third-party verification will be critical for the AI ecosystem moving forward. 

Increased Consumer Awareness of Data Privacy 

Consumers today are more aware than ever of how their data is collected and stored. Due to numerous high-profile data breaches and misuse cases, privacy has become a priority for many people. 

Therefore, consumers today are: 

  • Expecting better transparency 
  • Buying privacy-oriented products 
  • Asking questions about how non-transparent AI systems are 

Apple’s expansion of its audit program addresses these changes in consumer expectations. 

Laws and Governing Trends for Regulatory Compliance 

Data protection and AI are getting tougher regulations worldwide. Apple’s decision to be part of this global regulatory environment. 

The three areas of focus are: 

  •  Data Minimization Practices 
  •  User Consent 
  • Explainability of AI Decisions 

To prepare for potential new regulations, Apple is strengthening its audit processes in advance. Apple is not completely independent of existing security systems,as the audit framework integrates with the broader security framework. 

Examples of this Integration Include: 

  •  Device-level encryption 
  •  Secure hardware components 
  •  Controlled application ecosystems 

Long-Term Vision for Private AI 

This is an example of how maintaining privacy across the system is an integral part of the platform architecture. Apple’s approach may influence competitors to consider similar measures, as companies differentiate themselves by building customer trust and investing more in transparency and verification. 

These actions may also lead to: 

  •  An overall audit-based industry 
  • Increased privacy-based competition 
  •  Increased accountability for AI-based systems 

As a result of these actions, companies may need to reassess how they build and market their AI-based products. Private AI is how Apple envisions its customers interacting with AI-based systems in the future. 

Source-Read the latest from Apple Security Research 

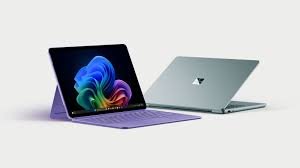
Microsoft is updating its Surface line to highlight the new trend of AI-first personal computers, where AI is more important to performance than just specifications like speed or graphics. Recent Surface products focus on AI in hardware, indicating how PCs will change in their design, marketing, and use.  

Also, many people are using more AI in everyday life, including integrating it into all areas of work, such as productivity, communication, and data creation and analysis. Microsoft no longer measures PC performance by CPU speed; instead, it measures it by the amount of neural processing power and how well the PC integrates with AI, creating an ecosystem that sets its hardware apart from other companies.  

Redefining What Makes a PC Powerful  

Traditionally, when evaluating personal computers over the past several decades, they were assessed using a variety of metrics, such as processor speed, RAM, and storage capacity. Even today, these factors remain significant for personal computers, with the emergence of AI. Artificial Intelligence, new benchmarks on measuring performance have begun to be developed, with a focus on machine learning capabilities.  

The introduction of dedicated Neural Processing Units (NPUs) in the design of devices like Microsoft’s Surface devices enables these devices to perform AI workloads very well, allowing for the integration of real-time AI without relying heavily on cloud processing.  

Therefore, performance on a personal computer now depends as much on how well the device supports A.I.-driven applications as on traditional computing applications.  

The Role of On-Device AI  

The AI-first PC strategy relies heavily on on-device AI, enabling faster response times, improved privacy, and greater reliability than cloud-dependent solutions. By running AI tasks locally on the device, tasks such as voice recognition, image processing, and contextual assistance can be completed in real time without an internet connection, providing users with a better experience and enabling new types of applications.  

In addition, Microsoft has designed its ecosystem around this functionality and subsequently encourages developers to produce software specifically for performing AI processing locally.  

Integration with Windows Ecosystem  

The transition to PCs using AI as the primary focus is happening alongside the evolution of Windows as an operating system. Microsoft is embedding AI capabilities into its OS, so users can access these features across a wide range of applications.  

AI capabilities include intelligent agents, automated processes, and improved search functions driven by on-device AI. By integrating AI into the OS as part of its foundation, Microsoft has ensured that its Surface devices can fully leverage their hardware capabilities.  

By integrating AI and Windows at this level, Microsoft has created a seamless system that delivers advanced functionality through hardware and software working together.  

Changing User Workflows  

New AI-first personal computers are changing how people interact with their devices. They allow users to leverage artificial intelligence to automate tasks previously done manually, such as summarizing documents, analyzing data, and creating content.  

As a result, professionals will be more productive and efficient in their day-to-day tasks. Students will have a much more interactive and customized learning experience. These new devices have also been built specifically by Microsoft for this new workflow and to use AI regularly when you use your computer.  

Hardware Design for AI Performance  

AI-first PC design requires a unique method for developing its hardware systems. The devices need NPUs, power management systems, and memory systems specifically designed for continuous AI operations.  

AI workloads demand significant system resources, which makes battery life an essential factor to consider. Manufacturers need to strike a balance between product performance and energy consumption to make their products suitable for real-world use.  

Microsoft has developed a solution to these problems by improving its hardware designs, which enable continuous AI operation while maintaining device portability.  

Competitive Landscape in AI PCs  

The technology industry experiences competitive pressure because AI-first computing has become the new standard. Multiple companies are introducing devices with integrated AI capabilities, hoping they will become the dominant products in this new market segment. Microsoft’s Surface products serve as a Windows reference platform that other manufacturers use to develop their own AI-capable products. The growing competition between companies will drive faster technological progress, leading to more advanced AI-powered personal computers that are easier to use.  

Challenges in Adoption  

AI-first personal computers face multiple obstacles that prevent their users from adopting the technology. The new device interaction methods require users to learn different ways to operate their devices, as many applications still lack full AI optimization.  

High-end devices become more expensive because advanced hardware components drive up their costs. Organizations need to clearly demonstrate the advantages their AI features offer before achieving widespread user acceptance.  

Microsoft is addressing these problems by expanding its software ecosystem and improving accessibility across its platform.  

The Future of Personal Computing  

The transition to AI-first personal computers marks a major milestone in the development of personal computing. All devices will feature AI capabilities because these technologies will become standard in the future.  

Future PCs will introduce advanced AI assistants that will optimize performance through predictive capabilities and establish stronger connections with cloud-based services. The system will establish a smart computing environment that adapts to user needs.  

Microsoft leads the industry transformation by developing new technologies that will define future market trends.  

Conclusion: A New Era for PCs  

Microsoft’s Surface devices mark a complete transformation in personal computer design and evaluation methods. Microsoft has established a new standard for PC performance by making AI capabilities the main focus of its testing process.  

The growing use of AI in everyday work tasks will make AI-first PCs essential for future computing, as they introduce new features and change how users engage with technology.

Source: Meet the new Surface PCs