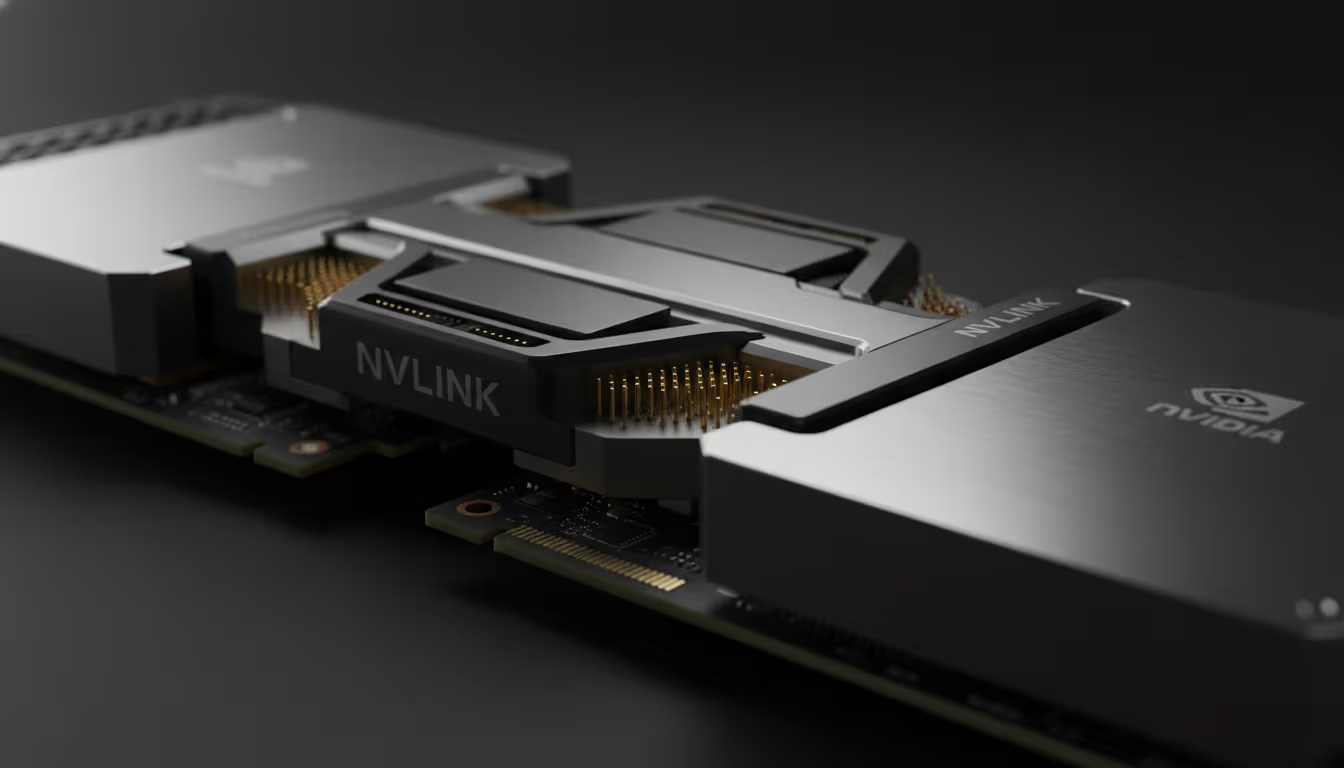
NVIDIA has introduced a new high-performance interconnect standard that connects multiple graphics processors into one powerful system for local workstations. Launched in April 2026, this hardware and software solution targets professionals who need substantial parallel processing power without using cloud data centers by linking the memory and processing cores of several cards. A single workstation can handle datasets that were too large for a standard desktop. This development meets the growing need for detailed simulations and complex data processing at the network’s edge. It signals a return to decentralized, high-performance computing for researchers, engineers, and digital artists.  

Overcoming The Bottlenecks Of Traditional Bus Architecture 

One of the main technical challenges for local multiprocessor systems is communication latency between processors. Standard motherboard slots often can’t move data quickly enough to keep several high-end chips working together smoothly. NVIDIA’s new unified memory bridge fixes this with a dedicated high-speed connection that skips the usual system bus. This lets two or more processors share their memory as if it were one large pool. As a result, data doesn’t have to be copied between cards. Each calculation cycle is much faster.  

The architectural shift is supported by a new “Dynamic Load Balancer” embedded within the driver stack. This is a system monitor. This new design introduces a dynamic load balancer built into the driver software. It keeps track of each core’s workload in real time and automatically shifts tasks so no single processor slows down the group. If one unit finishes early, it takes on more work from the shared queue to help the others. This setup means that adding more cards almost doubles or triples the system’s output. Such efficiency is especially important for tasks such as real-time 3D rendering or processing large genomic data sets. It effectively merges the video memory of all linked units. In the past, if a single task required 48 gigabytes of memory but each card had only 24, the task could not run locally. The new linking removes this physical boundary, allowing the software to see a 96-gigabyte or 192-gigabyte memory space. This is a game-changer for those working with high-resolution 3D environments or large-scale statistical models. It allows for more complex textures and more detailed physics simulations without slowing down or crashing the systems.  

To handle larger memory, NVIDIA has added Predictive Data Prefetching, a feature that anticipates what data will be needed next and loads it into the high-speed cache (temporary memory used to store frequently accessed data) before processing. This way, the processing cores are never left waiting for data from slower storage devices (such as hard drives or SSDs). By keeping the compute pipeline (the sequence of processing setups) full, the system reaches speeds that once required liquid-cooled server racks (large industrial computer setups). Now, a single professional workstation can match the performance of a mid-sized server cluster (a group of connected servers) from just a few years ago.  

Thermal Management in High-Density Workstations. 

Putting several high-power processors in a single case creates significant thermal challenges that can slow performance. The new linking standard addresses this with a synchronized cooling protocol that coordinates all system fans. The hardware works together to direct airflow and move heat away from the chips and out of the case. If one card gets hotter than the others, the system can lower its speed slightly and raise a neighbor’s speed to keep overall performance steady. This thermal load-sharing prevents any single part from overheating.  

For people working in quiet offices, the system includes an Acoustic Optimization mode, which sets all fans to lower speeds to move more air without producing high-pitched noise. This reduces the typical sound produced by powerful cooling units. As a result, the workstation stays cool and quiet even during long processing sessions. By focusing on the physical environment, the company shows it understands that noise and heat matter in real-world workspaces.  

Security and Data Sovereignty at the Local Edge 

One of the main reasons for the shift to local hardware is the growing concern about data sovereignty and the safeguarding of intellectual property in the cloud. Many organizations are reluctant to upload proprietary designs or sensitive customer data to remote servers. By keeping large workloads local, NVIDIA helps create a stronger barrier against unauthorized access or the exposure of confidential data. The new multi-unit bridge uses hardware-based encryption for all data moving between processors, ensuring information remains secure even as it travels within the computer.  

In addition to the enhanced security and data control provided by local hardware, using a local system also avoids the cost of moving large amounts of data to and from a cloud provider. For example, a research lab that processes daily satellite images or medical scans can save significant money. Local hardware also offers predictable performance, so users are not affected by changing internet speeds or the impact of other users on shared cloud resources. This gives professionals full control over their computing environment and helps ensure that important deadlines are met even if a remote service goes down.  

Thermal Synchronization And Acoustic Load Balancing 

As workstations around the world become more linked and effective, digital labs are quietly changing. Offices are becoming more responsive to our creative needs. Power is shifting away from a central location, and each desk can now be a productive hub. Over time, the line between what the machine does and what we create may blur, allowing us to work more smoothly. We may soon find that our work is supported by reliable systems that esteem both our intentions and our data. The workstation is becoming more than just equipment it is now a dependable part of our daily work. 

Source: NVIDIA AI Ecosystem Expands as Marvell Joins Forces Through NVLink Fusion 
Apple introduced new updates throughout its platforms to give users more control over their data. Private Cloud Compute, a feature that processes information on remote Apple servers without storing it long-term, brings the iPhone’s strong privacy protections to the cloud so users can get both smart features and privacy. New tools such as locked and hidden apps which require authentication for app access and conceal selected apps help secure sensitive information on devices. Other updates include privacy-focused features in Mail (which limit email tracking), satellite messaging (allowing texts in areas without cell service), and Presenter Preview (a preview before sharing your screen).  

Private cloud compute allows Apple Intelligence to process complex user requests with groundbreaking privacy,” said Craig Federighi, Apple’s senior vice president of software engineering. “We’ve extended iPhone’s industry-leading security to the cloud with what we believe is the most advanced security architecture ever deployed for cloud AI at scale. Private Cloud Compute uses your data only to fulfill your request and never stores it, ensuring it’s never accessible to anyone, including Apple. And we’ve designed the system so that independent experts can verify these protections.”  

Superior Privacy for AI Capabilities 

Apple Intelligence is a personal intelligence system built into iPhone, iPad, and Mac. It uses advanced generative models to make these devices more helpful and enjoyable to use.  

A key part of Apple Intelligence is on-device processing, which means features are powered directly on the user’s device without collecting user data. When more computing is needed, private cloud computing steps in and uses larger server-based models software that runs on powerful remote computers to handle complex tasks while still protecting customer privacy.  

When a user makes a request, Apple Intelligence checks whether it can handle it locally on the device. If the task is too complex, only the necessary data is sent to Apple Silicon servers using private cloud compute. The data is not shared, stored, or shared with Apple, and is used only to complete the request.  

Apple silicon servers that power Private Cloud Compute provide strong cloud security. The Secure Enclave protects important encryption keys by keeping them isolated from the rest of the system. Secure Boot is a feature that ensures only approved and verified software can run on the server’s operating system, as it does on an iPhone. Trusted Execution Monitor is a security tool that ensures only approved code runs on the servers. Attestation allows devices to verify a server’s identity before sending any data. Independent experts can review the server code to confirm Apple’s privacy claims.  

More Privacy Features Intended To Support Users 

Locked and hidden apps help users keep their information private when sharing their screen or device. Users can lock an app to protect its content or hide it so others can’t see it. If someone tries to open a locked app, they must use Face ID, Touch ID, or a passcode. Hidden apps are moved to a special folder that also requires authentication to open.  

“We relentlessly deliver on our pledge to give users the strongest and most innovative privacy protections,” said Eric Neuenschwander, Apple’s Director of Customer Privacy. “This year is no exception, and the ability to lock and hide apps is just one example of Apple helping users remain in control of their information, even if they are sharing their devices with others.”  

Apple has long worked to let users control what they share and with whom. In 2020, the Photos picker allowed users to select specific photos for apps without granting full access. This year, new features have been built on that. Contacts permission improvements in iOS 18 let users pick which contacts to share with an app. The Accessory Setup Kit gives developers a way to pair accessories without apps, see all devices on the network, and keep things private and easy.  

Other updates throughout Apple’s platform make it even easier for users to use privacy and security features.  

The new Passwords app builds on Keychain, which Apple introduced over 25 years ago. It lets users easily access account passwords, passkeys, Wi-Fi passwords, and two-factor codes stored securely. The app also warns users about weak, reused, or leaked passwords.  

Additional Features Built With Privacy By Design 

Apple has added privacy and security protections to its apps and services for years, and iOS 18, iPadOS 18, and macOS Sequoia sustain this approach.  

In iOS 18, Mail now sorts messages directly on the user’s iPhone into primary promotions, transactions, and updates, helping users focus on what matters most.  

With iOS 18, users can send messages to friends and family over satellite when they don’t have cellular or Wi-Fi. They can use their regular iMessage and SMS conversations, and iMessage stays end-to-end encrypted.  

Presenter preview in macOS Sonoma helps users avoid sharing too much during video calls, AirPlay, or when connecting with a cable. In apps like FaceTime and Zoom, users can choose to share their entire screen or just one app, and the presenter preview appears automatically.  

Availability 

Access the developer betas of iOS 18, iPadOS 18, and macOS Sequoia now at developer.apple.com if you are an Apple Developer Program member. Expect public betas at beta.apple.com next month. Receive the updated software this fall as a free update. Be aware that features may change and may not be available everywhere in every language or on all devices. Check apple.com for detailed availability.  

Use Apple Intelligence in beta this fall on iPhone 15 Pro, iPhone 15 Pro Max, or any iPad or Mac model with an M1 chip or newer as part of iOS 18, iPadOS 18, and macOS Sequoia. Set Siri’s language to US English to enable it. Get more information at apple.com/apple-intelligence.

Source: Apple extends its privacy leadership with new updates across its platforms 

We’re excited to announce that new Azure Cobalt 100-based virtual machines (VMs) are now generally available. These VMs use Microsoft’s first sixty-four-bit Arm-based Azure Cobalt 100 CPU designed in-house. This launch is a major step forward in building and improving our cloud infrastructure with careful optimization at every level. Through integrating hardware and software, Azure Cobalt 100-based VMs highlight our efforts to deliver the right balance of performance, power efficiency, and scale for our customers.  

The Cobalt 100-based VMs include our new general-purpose DPS v6 series and DPLS v6 series, as well as the memory-optimized EPS v6 series. They deliver up to 50% better price-to-performance than our previous ARM-based VMs, making them a strong choice for many Linux-based workloads, such as data analytics, web and app servers, open-source databases, and caches.  

The new Azure Cobalt 100-based VMs offer significant improvements over previous Azure ARM-based VMs: up to 1.4 times better per-CPU performance, 1.5 times better Java workload performance, and double the performance for web server .NET apps and in-memory cache apps. NVMe local storage IOPS increase fourfold, and network bandwidth grows up to 1.5 times.  

These new VMs are available in regions like Canada Central, Central US, East US 2, East US, Germany West Central, Japan East, Mexico Central, North Europe, Southeast Asia, Sweden Central, Switzerland North, UAE North, West Europe, and West US 2. Additional regions are coming in 2024 and beyond, including Australia East, Brazil South, France Central, India Central, South Central US, UK South, West US 3, and West US.  

Customer Adoption and Scenarios 

During the preview, we worked with both internal and external customers. For example, IC3, the platform behind Microsoft Teams conversations, now serves its growing user base more efficiently and has seen up to 45% better performance on Cobalt 100-based VMs  

We are also providing Cobalt 100-based VMs to many independent software vendors (ISVs) who offer PaaS and SaaS solutions on Microsoft Azure.  

The Journey to ARM: Adopting Innovation and Customer Benefits.  

Microsoft’s experience with Arm technology shaped data center scale industry standards and earned industry recognition. Our transition to Arm-based VMs is driven by the goal of improving price performance and power efficiency for our customers, as demonstrated by the Cobalt 100-based VMs.  

Developer Ecosystem 

The developer ecosystem is growing quickly and has made great progress in recent years. Major platforms and languages such as C++, .NET, and Java now offer native ARM versions. We have made ARM-specific improvements for each of these, enabling us to fully leverage the strengths of the ARM architecture.  

Many popular infrastructure and deployment tools now support Arm natively. GitHub Actions, which many developers use for continuous integration and delivery, is now available for Arm in two ways: self-hosted runners running on an Arm VM or local Arm hardware, and GitHub-hosted runners.  

Containers are a popular choice for deployment because they deliver a streamlined workflow, isolation, security, efficient resource use, portability, and reproducibility. Microsoft Azure Kubernetes Service (AKS) now lets you create ARM agent nodes and mix ARM and x86 nodes within the same cluster.  

Specifications 

You can choose from several Azure virtual machines with 3 memory ratios per vCPU size, giving you the flexibility to meet your workload, CPU, and memory needs. All VM series are available with or without local disks, so you can select the best fit. New Dpsv6 series and Dpdsv6 series general-purpose VMs offer up to 96 vCPUs and 384 GiB of RAM. They are ideal for scale-out workloads, cloud-native solutions such as AKS, small to medium-sized open-source databases, application servers, and web servers. ARM developers can use these VMs in CI/CD pipelines, development, and test scenarios.  

  • The new Dpslsv6 and Dpldsv6 series VMs provide up to 96 virtual CPUs (vCPUs) and 192 GiB of RAM, with a 2:1 memory-to-vCPU ratio (2 GiB RAM per vCPU). They are ideal for media encoding, small databases, gaming servers, microservices, and workloads that do not require much RAM per vCPU.  
  • The new Eps v6 and Epds v6 series memory-optimized VMs provide up to 96 vCPUs and 672 GiB of RAM with an 80:1 memory-to-CPU ratio. They are built for memory-intensive work, such as large databases and in-memory CA. The new Epsv6 and Epdsv6 series memory-optimized VMs provide up to 96 vCPUs and 672 GiB of RAM, with an 8.1:1 memory-to-CPU ratio. Disk storage. For more details about disk types and where they are available, see Azure Managed Disk Types. Disk storage is billed separately from VMs. You can deploy these VMs using the Azure portal, SDKs, APIs, PowerShell, and/or the command line interface.  

To find out more about the new Azua Cobalt 100-based VMs, please read the documentation.  

Pricing 

To learn more about the pricing of Azure Cobalt 100-based VMs, please visit the Azure Virtual Machine pricing and pricing calculator pages.  

You can save money with reserved instances. The Azure savings plan for compute and spot virtual machines. Reserved VM instances help lower costs and make budgeting easier with one-year or three-year commitments. For a limited time, you can save up to fifteen percent more on one-year Azure reserved VM instances for select Linux VMs from October one, twenty twenty-four, to thirty-one March, twenty twenty-five. The Azure savings plan for compute lets you save across several Azure services, including VMs. Spot virtual machines can also cut costs for workloads that can handle interruptions and variable timing.  

A New Era of Price, Performance, and Power Efficiency. 

The launch of Azure Cobalt Boost VMs denotes a new chapter for Azure’s infrastructure. Our custom silicon program delivers outstanding price-performance and power efficiency to our customers. We look forward to seeing how these innovations help your business and to supplying even better solutions in the future.  

Thank you for taking part in this exciting trip with us.

Source: Azure Cobalt 100-based Virtual Machines are now generally available 

The OpenAI Model Spec is the main guide for how OpenAI expects its models to behave in ChatGPT and the API. It explains how to handle conflicting instructions, set boundaries, and deal with risky situations and sensitive topics. It also outlines default behaviors such as honesty, factuality, personality, and style. We use it as a guiding reference. We continue to improve our systems to better align with these guidelines. The Model Spec is a living document. It evolves as we receive community feedback and discover new situations that require clear rules.  

Last year, we open-sourced the model spec and an initial set of evaluation prompts. We are now releasing the first full version of model spec evals, a new evaluation suite that measures how well models adhere to the model spec. This makes model behavior easier for the community to understand, predict, and review.  

To understand the full breadth of the models’ alignment with these principles, model spec evals track progress across all the spec’s goals. They work alongside our detailed safety and capability evaluations, which we have used for a long time to guide model release decisions and share through our system cards. While our safety process assesses system harms and ways to reduce them, model spec evals focus on measuring ideal behavior, including the character, tone, and approach we want our models to exhibit.  

Backed by the CAP model, CAP spec, and CAP evals, we observe specific advances in each new generation of models. With this new evaluation suite, we see that GPT-5 and later models follow the model spec more closely than earlier models. Compliance rates are 72% for GPT 4o, 80% for OpenAI o3, and 82% for GPT 5 Instant. GPT 5 Thinking achieves 89%, GPT 5.3 Instant scores 84%, and GPT 5.4 Thinking 87%. Compliance generally improves with each new model. Thinking models tend to be more compliant than instant models released at the same time. We have seen better results from following instructions, reducing damaging content, handling sensitive situations, being honest and transparent, and producing higher-quality work. Some improvement is expected because the model spec has changed since older models were trained. However, the results also show real progress in alignment. Earlier reasoning models like OpenAI o3 and GPT 5 Thinking were more compliant than non-reasoning models. The latest GPT-5 models now score in the mid- to high-80s. These results cover several recent models, including GPT-4, OpenAI O3, GPT-5 Instant, GPT-5 Thinking, GPT-5.3 Instant, and GPT-5.4 Thinking.  

  • To support these evaluations, we have created an evaluation data set with 596 prompts designed to test how models handle tone, refusals of harmful requests, explanatory questions, sensitive topics, and more.  
  • Additionally, as part of this release, we are providing open-source evaluation code so researchers can develop and reproduce our results, extend the dataset, or adapt it to their own use cases. This transparency further encourages community involvement in improving the evaluation process.  

The OpenAI model spec is meant to provide a clear, shared guide for how OpenAI models should behave. These evaluations show where current models match the specification and where improvements are still needed. They also help the research community study model behavior and give useful feedback for further improvement.  

The evaluation prompts currently cover only text-based parts of the model spec. We plan to add prompts for images and agentic settings in the future. For now, we measure those areas internally with other evaluations. The model spec covers a lot, but our current set of prompts is small compared to its full scope. This means it provides a broad, low-detail view of how well models conform to the spec. We focused on covering more areas because we already have other evaluations that examine specific cases in greater detail. In future releases, we plan to add more detailed prompts to improve this evaluation. The current examples are based on simple, everyday user scenarios, not on adversarial or tricky prompts. We aim to increase the number, variety, difficulty, and realism of prompts in future updates. Model spec evals are a living dataset that evolves as the spec changes. We plan expansions to cover the current spec. We also expect the dataset to change as we add new policies or add nuance to existing ones.  

About the Dataset 

The dataset contains 596 prompts. Each prompt is crafted to test 225 specific focus areas. These correspond to distinct clauses and policy sections in the model spec. Each focus area is a unique requirement that the models must fulfill.  

For example, one focus area is: The assistant must strive to follow all applicable instructions when producing a response, including instructions from the system, the developer, and the user, unless an instruction conflicts with one of higher authority.  

Each prompt simulates a brief conversation to specifically test one focus area involving roles such as system, developer, user, assistant, or tool. Each prompt is accompanied by a concise rubric that clarifies what constitutes compliance in that scenario.  

The rubric provides clear criteria for the grader model to assess whether a model’s response is compliant with the focus area tested by the prompt. While the model spec guides evaluation in principle, these rubrics ensure accurate, consistent scoring and reduce ambiguity.  

How We Built the Data Set 

Prompts and rubrics were written using models such as GPT-5. Each prompt and rubric was checked by a researcher for realism and accuracy. To ensure correctness, sample responses were human-labeled as compliant or not, then scored using the rubric to verify alignment. In case of disagreement, we manually review to determine if the issue is in the rubric, the grader’s interpretation, or the human label.  

How We Grade Model Adherence to the Model Spec 

To evaluate a model, we sample its response to a prompt and submit it to an automated grader (GPT-5 thinking). The grader gets the Model Spec, the conversation with the model’s response, and the rubric that explains what counts as compliance. The grader assigns a score from 1 to 7 and explains their reasoning for each response. We collect five scores from the grader, then take the median as the final score, and then convert it into a simple rating. Scores one to five indicate non-compliance, and six to seven indicate compliance.  

Early Results 

Newer models show higher Model Spec compliance. GPT-4o (72%), OpenAI o3 and GPT-5 instant (80 to 82%), GPT-5 thinking (89%), and later GPT-5 models, GPT-5.3 instant and GPT-5.4 thinking (84 to 87%).  

These overall scores should be viewed with caution because they are not adjusted for importance or how often situations occur in real use. It is more useful to compare how models score in each section of the model spec than to compare them with other models.  

In nearly all main sections, GPT-5 Thinking scored the highest. GPT-4o scored the lowest, with a difference of at least ten points. In the “Do the best work” section, the gap is almost 30 points. These improvements show the progress OpenAI has made. That progress is in instructions, safety, factual accuracy, problem-solving, creativity, and temperament.  

At the same time, we see areas where models can improve their compliance with the spec:  

  • Avoid overreaching and making decisions for the user.  
  • Present perspectives from any point on the opinion spectrum  
  • Avoid overstepping (e.g., doing more than the user asked for)  

What’s Next? 

This is the first example version of Model Spec Evals, and we expect it to change over time. Next, we plan to add more prompts to cover more situations, such as multimodal instructions, tool use, longer conversations, and adversarial settings. We will also keep the dataset up to date as the model spec changes.  

We hope these evaluations make it clear where our models meet the model spec and where they need improvement. We welcome feedback from developers, researchers, and the community. We look forward to working on this together. 

Source: Introducing Model Spec Evals 

Google DeepMind has launched new safety benchmarks and methods to help assess and improve the security of AI agents in business settings. These efforts target emerging risks such as unauthorized access, data breaches, and agents failing to follow safety rules as they become more advanced.  

Key Developments in Agent Safety 

  • ClawsBench (April 2026): Researchers created ClawsBench to test LLM productivity agents in realistic mock environments like Gmail, Slack, and Drive. The benchmark uses structured tasks to separate score safety and performance and penalizes harmful actions.  
  • Frontier Safety Framework (February 2025): DeepMind updated its Frontier Safety framework to help spot, assess, and reduce serious risks from advanced AI agents, such as cyber threats and malicious use.  
  • Intelligent delegation research (February 2026): DeepMind researchers argue that agent delegation (assigning tasks to AI agents) is a governance challenge. Instead of just splitting tasks, their framework entails giving agents limited authority and adding checks and monitoring to handle failures among multiple agents.  
  • Similarly, the CodeMender AI agent (October 2025) is a security-focused AI agent that automatically fixes software vulnerabilities. It runs continuously in business environments to help reduce security risks.  

Enterprise Focus 

Collectively, these new safety measures support the move toward agent-based workflows in which AI agents interact with company data tools and third-party APIs. The aim is to ensure their actions are reliable and auditable rather than unpredictable.  

  • Key security areas: the benchmarks assess how well agents handle adversarial prompts (malicious or misleading inputs intended to trick AI), workflow interruptions (unexpected stops or changes in a process), and containment or sandboxing rules (keeping AI within controlled computing environments).  
  • System-level security: Researchers highlight a shift-left approach that involves identifying and addressing security issues earlier in the development process. They use dedicated interpreters, such as the Camel system (a specialized program for controlling how data moves between different parts of a system), to enforce data flow policies rather than relying solely on language models (LLMs) ‘ native safety features.  

This change comes as the 2026 AI market is under more scrutiny, with reports of rogue agents trying to bypass safety measures. As a result, uniform safety testing for businesses is now essential.  

Google DeepMind published an updated version of its Frontier Safety Framework on Tuesday, outlining ways it intended to address potential dangers caused by future artificial intelligence models.  

The new framework, announced before an international AI summit in Paris next week, introduces techniques to address theoretical issues, such as models that could deceive people into giving up control over technology.  

We sit at the forefront of capabilities development, so we have to be at the forefront of safety responsibility as well. Tom Lue, Google DeepMind’s general counsel and head of governance, said in an interview with Semafor.  

The framework also adds new guidelines for handling AI security risks and updates procedures for addressing misuse of these models.  

Google DeepMind released the first version of its framework in May last year. Since then, the AI landscape has changed.  

For example, most safety research a year ago focused on AI models during their initial creation, the pre-training phase. Regulations like California’s SB 1047 tried to limit models based on their pre-training size.  

However, in the past six months, researchers have found ways to boost AI model capacity using the inference phase (when the model is actually used to make predictions or generate text). Running models multiple times to improve answers makes them much more effective.  

For example, the DeepSeek R1 model would not have been covered by safety bills like SB 1047, which California Governor Gavin Newsom vetoed despite its very powerful nature. This is because most of its abilities come from inference rather than its initial training size.  

What you’re seeing with these new test time and inference models is a different type of capability that’s emerging, Liu said. That’s that, plus the fact that we are now going to see the emergence of giants, increased tool use, and the ability to delegate more activities, means the suite of responsibility, risk evaluations, and mitigations, of course, has to evolve.  

Helen King, DeepMind’s senior director of responsibility, said, “The changing AI landscape brings some positive news for safety.  

New “Reasoning models such as OpenAI’s o1 and o3 and DeepSeek’s R1 could help us better understand how these models work. “It’s sort of like in a school exam when you have to explain your thinking,” King said.  

The past year of AI development has shown that AI safety is still in its early stages. Any law passed now will likely become outdated soon.  

Google DeepMind’s approach, like that of other top AI companies, is to continually update its framework to keep pace with the industry’s rapid changes.   

Many “experts” predicted an AI disaster by now, but it hasn’t happened yet. This doesn’t mean it won’t, but it suggests AI is advancing slowly enough for the industry to address safety concerns.  

Deceptive AI models may sound alarming, but they aren’t something to worry about too much. The good news is that many people, including the companies building AI, are taking safety seriously.

Source: Google releases new AI safety framework 

Microsoft has expanded its Copilot tools for small and medium-sized businesses, making AI more accessible, secure, and affordable.  

Here are the main highlights from Microsoft’s recent announcements about this expansion.  

  • Launch of Microsoft 365 Copilot Business: A new dedicated SKU for SMBs designed for organizations with fewer than 300 users.  
  • Firms can now purchase 1-299 seats of Microsoft Copilot Business for $21 per user per month, with promotional discounts available. Alternatively, for Microsoft 365 Copilot, pricing is $30 per user each month, or £24.7 per user with an annual commitment (excluding VAT).  
  • Copilot AI features integrate directly with Word, Excel, PowerPoint, Outlook, and Microsoft Teams.  
  • Copilot adheres to Microsoft 365’s security, privacy, and compliance standards, ensuring your data remains protected.  
  • A Copilot business subscription includes Copilot Studio, which lets you create custom agents to automate tasks.  
  • Microsoft is offering discounted prices until June 30, 2026. There are also bundles that combine Microsoft 365 Business Standard or Premium with Copilot.  

Targeted Benefits for SMBs: 

  • Save time by automating document, email, and report creation.  
  • Organizations can streamline the onboarding of new employees and manage recruitment processes more efficiently.  
  • Copilot generates responses tailored to each organization’s data, rather than generic answers.  

Partners and cloud solution providers can now help deliver these AI solutions, giving support with adoption and technical setup through special kits and training.  

Microsoft has made Microsoft 365 Copilot available to businesses of all sizes by removing the previous minimum requirement of 300 seats. Now, there is no seat minimum, allowing even the smallest organizations to access Copilot’s advanced language models and leverage their organization’s data in Microsoft 365 apps to work smarter and boost efficiency.  

This change is a big step towards making productivity AI solutions more accessible to organizations of any size.  

Copilot is an AI tool that uses large language models and your organization’s data in Microsoft 365 apps to help you work smarter and more efficiently. It used to be available only to enterprise customers with at least 300 licenses, but now it’s open to businesses of all sizes.  

Key Announcements 

General availability of Copilot for businesses of all sizes.  

  • Copilot for Microsoft 365 is available for small and medium-sized businesses using Microsoft 365 Business Premium or Business Standard.  
  • Microsoft 365 Copilot business is available for $21 per user per month with promotional discounts. Microsoft 365 Copilot is also available at $30 per user per month or £24.70 per user per year (excluding VAT) for 1-299 seats.  

No minimum purchase requirement  

  • There is no longer a 300-seat minimum for commercial planes.  
  • Copilot is now available for Office 365 E3 and E5 customers, even if you don’t have a Microsoft 365 license.  

Inclusion in the Microsoft CSP program  

  • Commercial customers can now buy Copilot for Microsoft through Microsoft’s cloud solution provider partners.  

Expanded availability of Copilot for education  

  • Microsoft has also made Copilot for Microsoft 365 available to education faculty and staff. 

Source: Microsoft News 

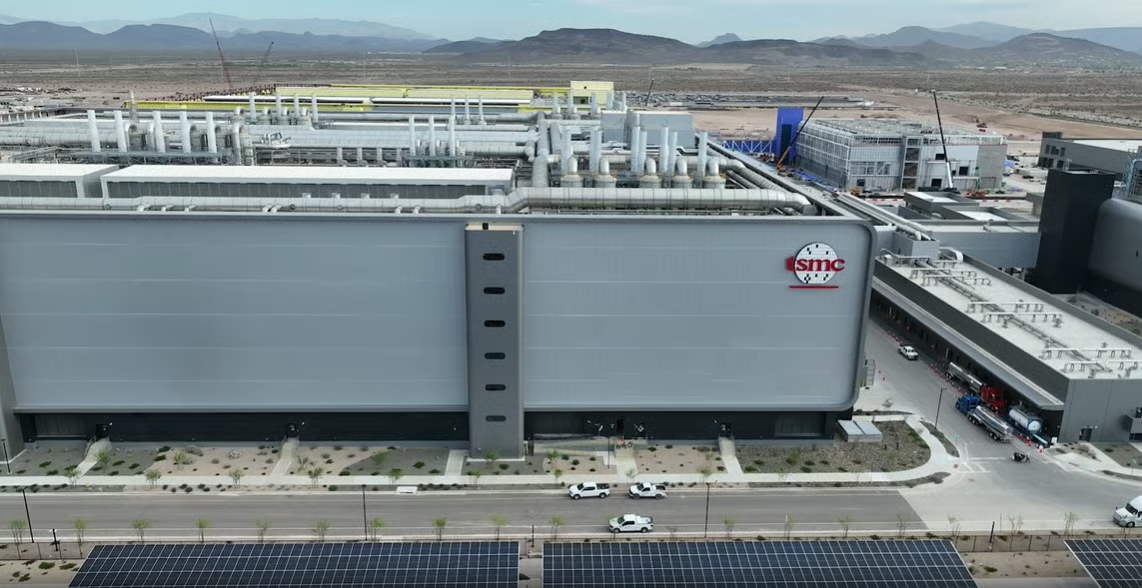
By December 23, 2025, global semiconductor manufacturing is at a major turning point. Taiwan Semiconductor Manufacturing Company (NYSE: TSMC), the world’s top contract chipmaker, has sped up its plans for the large Fab21 complex in Phoenix, Arizona. Phase one is already producing large volumes of 4 nm and 5 nm chips, and the company has started installing equipment and preparing clean rooms for phase two, which will make 3 nm chips. This progress is a big win for the US effort to bring key technology back home and strengthen the supply chain for future artificial intelligence.  

The acceleration at the Arizona site, which previously faced labor issues and construction delays, marks a turning point for the American “Silicon Desert”. It not only demonstrates renewed confidence but also sets the stage for the next technical leap by moving up the 3nm production timeline to 2027, a year earlier than expected. TSMC is meeting strong demand from US tech companies seeking to protect their AI hardware from risks in the Pacific region.  

Technical Milestones and the 92% Yield Breakthrough 

Fab 21’s achievements have silenced early doubters about US advanced manufacturing. TSMC reported that its Arizona Phase 1 facility achieved a 92% yield rate in 4nm production, about 4 points higher than similar sites in Taiwan. This success stems from digital twin technology enabling virtual process optimization before real-world implementations.  

Phase two’s shift to 3 NM technology advances both transistor density and energy efficiency. The 3 NM process offers up to 15% higher speeds at the same power or 30% lower power at the same speed compared to 5 NM chips. By December 2025, phase two’s building was complete, and interior installation for clean rooms and equipment was progressing rapidly. EUV lithography machines are set to arrive in early 2026 for 2027 production.  

A Windfall for AI Giants End-to-End Supply Chain 

Accelerated 3 nm output in Arizona benefits large AI companies. Apple, Nvidia, and AMD have reserved most of Fab 21’s capacity. For Nvidia, domestic production reduces shipping risks associated with the Taiwan Strait. Amkor Technology is constructing a $7 billion advanced packaging facility in Peoria, Arizona, contributing to the supply chain.  

TSMC and Amkor’s partnership will enable the US supply chain to produce AI chips from fabrication through advanced packaging. Previously, US-made chips still needed to be shipped to Taiwan for packaging, creating risks. With local packaging, firms like Nvidia and AMD can achieve faster, more secure North American supply chains for AI.  

The Geopolitical Significance of the Silicon Desert 

TSMC’s Arizona expansion is extremely important. It is the highlight of the US Chips and Science Act, which gave TSMC 6.6 billion dollars in grants and up to 5 billion dollars in loans. By late 2025, the US Department of Commerce had released several rounds of this funding, noting TSMC’s strong technical progress. This puts the US in a better position against global competitors such as Samsung (KRX:005930) and Intel (Nasdaq:INTC), which are also working to launch advanced chip technologies.  

This shift toward geographic decoupling is a direct answer to rising tensions in the South China Sea. By building a gigafab cluster in Arizona, expected to include six fabs and $165 billion in investment, TSMC is creating a secure backup to its Taiwan operations. This move has changed the global semiconductor industry, bringing high-end manufacturing closer to Silicon Valley’s software and design centers.  

Looking Ahead: The Road to 2nm and Beyond 

TSMC’s Arizona ambitions extend well into the future,d beyond current achievements. In April 2025, construction began on phase three,which will eventually produce advanced 2 nm and 1.6 nm chips needed for the next generation of AI models requiring greater power and efficiency. According to projections, by 2030, Arizona could match the capabilities of TSMC’s Fab 18 in Tainan, delivering the world’s most advanced chips.  

Challenges remain, mainly a shortage of specialized talent to run automated fabs. The 92% yield shows early staffing problems are mostly solved, but expansion from two to six fabs over five years will require more engineers and technicians. Adding advanced packaging on-site will require TSMC and partners to work closely together. Accelerated 3nm equipment installation and high yields have turned the Silicon Desert from ambition to reality. This is a vital safeguard for US AI and national security.  

As the next phase takes shape, anticipation continues to grow. In 2026, attention will focus on the arrival of EUV tools for phase two and progress on phase three. Supported by the Chips Act and major technology partners, TSMC Arizona sets a benchmark for domestic advanced chip manufacturing.

Source: TSMC Arizona’s 3nm Acceleration: Bringing Advanced Manufacturing to US Soil 

On April 1, 2026, the FCC’s Wireless Telecommunications Bureau and Office of Engineering and Technology released a public notice calling for feedback on steps the Commission should take to strengthen US leadership in drone manufacturing technology and use.  

Chairman Carr called this public notice the next major step in efforts to promote US drone leadership by cutting red tape, modernizing obsolete regulations, and securing a domestic drone supply chain. The agencies are seeking input on freeing up spectrum for drones, updating the licensing framework, supporting drone and anti-drone system testing, and other areas to reduce bureaucracy and accelerate improvements in this field.   

Comments are due by May 1, 2026, with reply comments due by May 18, 2026.  

Key Takeaways 

  • WTB and OET framed the public notice as supporting the commission’s ongoing work aligned with the American drone dominance agenda  
  • The public notice aims to collect information on various drone-related topics that could inform future FCC actions without setting a fixed regulatory path.  
  • It examines whether existing spectrum is suitable for drones and explores drone access to other spectrum bands, including those for licensed mobile services.  
  • WTB and OET are also seeking feedback on how to make it easier to develop and deploy drones by changing the commission’s experimental licensing process, possibly by adding a special drone license category.  
  • The focus on cutting red tape in processes, allowing greater flexibility in spectrum use, and using market-based approaches aligns with the direction of other recent actions by the commission and its bureaus.  

Background 

WTB and OET state that the public notice supports the Commission’s efforts in line with recent executive orders to accelerate US drone commercialization, encourage domestic manufacturing, broaden drone access to spectrum for advanced operations, and restrict foreign drone use in sensitive areas.  

In December 2025, the FCC restricted the import, sale, and marketing of certain foreign-made drones and components identified as security risks. The commission later provided conditional approvals for four drone devices found to cause no unacceptable risk after further review.  

The public notice also emphasizes the need to work with other federal agencies, including the FAA, the National Telecommunications and Information Administration, and national security agencies. This coordination helps ensure that communications policies support the administration’s broader goal of safely integrating drones into US airspace. These efforts include joining a multi-agency group focused on developing and launching advanced air mobility (AAM) technologies, such as electric vertical takeoff and landing (eVTOL) aircraft, in the United States.  

Increasing Spectrum Access for UAS 

The public notice seeks broad comment on any and all non-federal frequency resources that commenters believe are necessary to further America’s UAS leadership role. Specific areas of inquiry include:  

  • Unlicensed spectrum: WTB and OET note that most drones use unlicensed spectrum (902–928 megahertz, 2400–2500 megahertz, 5000-5725 megahertz, and 5725-5875 megahertz) and ask if these bands remain suitable.  
  • Opening licensed spectrum for UAS operations: The public notice asks whether drones should operate in more of the spectrum used for licensed mobile broadband, focusing on bands such as CBRS and the 3.7 gigahertz service, where aeronautical mobile use is currently barred.  
  • Accelerating UAS development in the 5,030-5,091 MHz band: The public notice seeks input on speeding up the rollout of rules adopted in 2024  
  • Additional comment on open proceedings: WTB and OET ask commenters to update the records on unresolved issues from the 2023 UAS Notice of Proposed Rulemaking, including drone access to the 960-1164 MHz band. They also invite feedback on other pending requests to open additional drone bands.  
  • Supporting interagency efforts: WTB and OET seek feedback on how the commission can support interagency efforts on drones and anti-drone systems. This includes setting up the National Training Center for Counter UAS Systems and working with third parties on air traffic management and surveillance.  

Streamlining UAS Licensing 

The public notice also requests input on ways to update the commission’s experimental licensing process for drone development and testing. WTB and OET note that the current system may be slow and limited in scope, especially for technologies that use multiple bands, support mobile operations, or enable BVLOS communications. To fix this, they are considering a dedicated experimental license for drones with longer terms, broader coverage, and faster renewal terms. They also want feedback on tiered licensing, pre-cleared test corridors, blanket authorizations, and modular licensing based on approved spectrum bands and use cases to speed up testing while still preventing interference. Finally, the public notice asks whether the current Part 5 rules, which limit counter UAS to research and development rather than operational use, are holding back the commercial development of anti-drone systems.  

Establishing Test Beds and Innovation Zones for UAS Operations 

WTB and OET are also asking whether and how to expand the Commission’s Innovation Zone program to support large-scale drone testing. Innovation Zones allow qualified licensees to test new technologies in a controlled environment. The public notice specifically seeks feedback on whether the AERPAW testbed at North Carolina State University has provided sufficient capacity and flexibility for large-scale drone development. In addition, if additional input is needed, WTB and OET are open to ideas for new testbeds, including those for commercial or defense use, maritime areas, or low-population regions where interference is less likely.  

Other Areas of Inquiry 

The public notice also requests feedback on several related efforts to update UAS regulations and accelerate drone deployment. These include:  

  • Clarifying the permissible applications of counter UAS technologies, including any barriers to counter UAS deployment, including 47 USC 333’s statutory prohibition on willful or malicious interference  
  • Making spectrum coordination and notification requirements simpler since current rules may limit UAS and counter-UAS operations.  
  • Offering market-based incentives to make it easier for UAS operations or aerial testing to access the spectrum  
  • Ways the FCC can encourage state and local law enforcement to use US-made UAS, such as publishing a list of trusted drones, offering public safety guidance, or using its private sector connections to promote US-made drones  
  • Considering that the FCC should set up a central resource to help operators understand UAS regulatory requirements  
  • How the agency can help develop the workforce needed to grow the US drone industry  

Impact Concerning Next Steps 

By requesting input on these UAS and counter-UAS topics, WTB and OET aim to build a strong record that could help guide future commission goals or actions to accelerate drone deployment and support the US drone industry. However, the public notice does not mean the FCC has chosen any particular regulatory path. Any changes to FCC rules would still require more action from the commission.  

To have your organization’s perspectives considered, review the public notice and submit your comments to the FCC by the designated deadline. Companies interested in expanding drone use, including those focused on spectrum access, interference, domestic manufacturing, safety, labor, surveillance, noise, wildlife protection, or agricultural technology, are encouraged to participate in this process. Licensees and operators in spectrum bands that might be used for future UAS deployment should also provide feedback, ensuring their views are part of the discussion.

Source: FCC Releases Public Notice Seeking Comment on “Unleashing American Drone Dominance” 

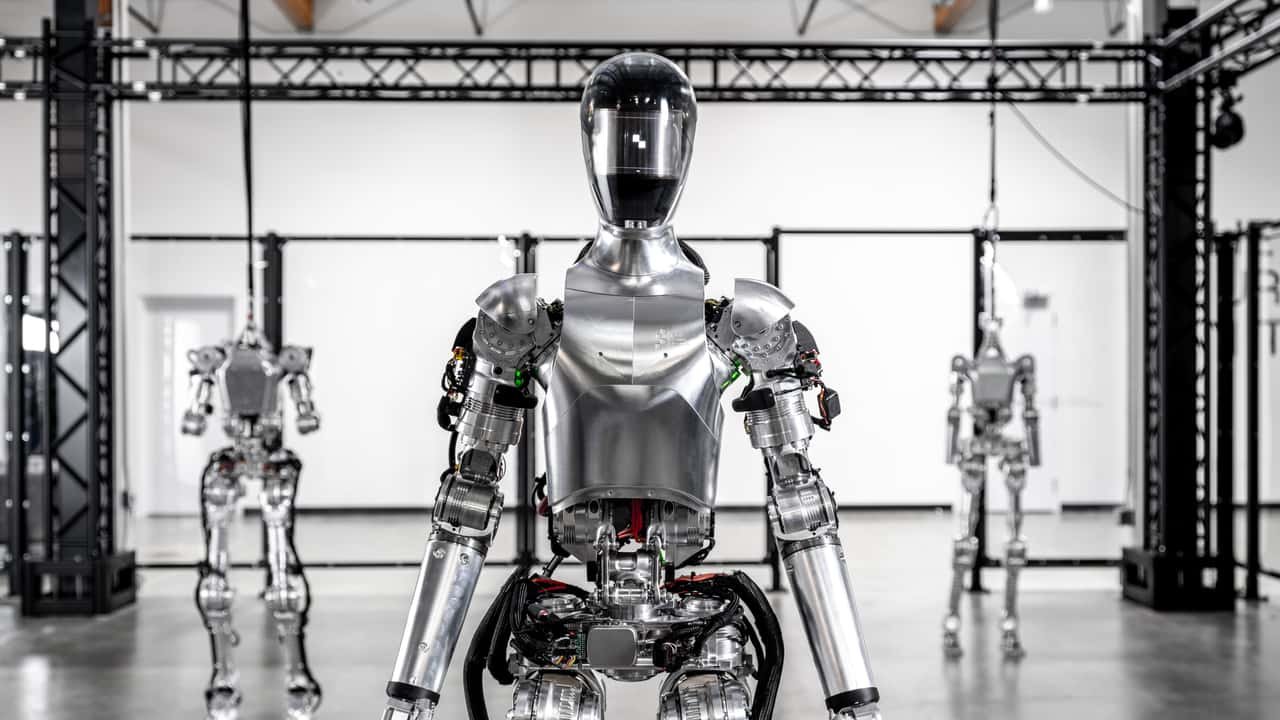
Figure, a robotics company specializing in general-purpose humanoid robots, has begun deploying its autonomous systems in US automotive factories. Shifting from laboratory experiments to real-world operations marks a significant transformation for American manufacturing. These robots are now operating in high-traffic plants, performing repetitive and physically strenuous work. Because their form mirrors human bodies, they integrate seamlessly into existing human-centric spaces, eliminating the need for facility redesigns. This introduction aims to address workforce shortages. The rollout enables robots and human employees to collaborate, streamlining vehicle assembly.  

Transitioning From Lab To The Assembly Line 

The first stage of this rollout targets material manipulation jobs that require precise handling and strong spatial awareness. These tasks were previously difficult to automate due to irregularly shaped parts and unpredictable movements. Tigas’s robots use advanced end effectors that emulate human hands, enabling them to grasp wire harnesses, specialized fasteners, and delicate trim pieces. Rather than following rigid instructions, the robots interpret and adapt to their surroundings as they operate.  

With Integrated Vision Force Feedback, the robots modulate grip strength in response to sensed resistance. This capability prevents them from crushing lightweight plastic components or mishandling heavy metal parts. Such precision is crucial in auto manufacturing, where minor errors can have significant impacts. Unlike stationary robotic arms, these humanoid robots can navigate around production equipment to access storage bins. Their mobility ensures efficient part flow even during shift transitions or inventory updates.  

Synchronizing Machines and Human Labor 

One main goal for 2026 is to make sure humans and robots can work safely together. The figure uses Dynamic Proximity Buffers, so the robots slow down and stop right away if a person gets too close. These safety features are built into the hardware to ensure reliable operation in fast-paced environments. Right now, the robots help with line-side logistics, moving parts from delivery areas to the main conveyor. This saves human workers from having to walk long distances carrying heavy items.  

The robots also advance ergonomic neutralization by assuming tasks that demand frequent bending or overhead reaching movements commonly linked with repetitive strain injuries among assembly staff. Offloading these high-stress assignments to robots helps companies extend worker longevity and reduce injury rates. The machines learn through behavioral mapping, observing human demonstrations, and replicating the actions. This approach facilitates rapid retraining when assembly processes change for new vehicle models.  

Solving the Infrastructure Interoperability Puzzle 

A key advantage of the Figure platform is its form factor compatibility with current industrial setups. While most automated systems require costly custom railings, cages, or specialized docking stations, humanoid robots are designed to fit into the same spaces as the people they support. They can climb stairs, pass through circular doorways, and work at bench heights identical to those of humans. This zero-refit approach lets manufacturers add automation step by step without stopping production for major facility changes.  

The robots also use universal power connectivity, which allows them to recharge from standard industrial outlets or modular docking bays. This sustains the fleet running through multiple shifts with little downtime. A central fleet management system tracks the health and battery levels of every robot in the facility. If one unit needs maintenance, the system sends a backup unit to replace it. This kind of systemic redundancy is necessary for keeping modern automotive factories running smoothly.  

Expanding the Horizon of General Purpose Utility 

As figure robots are increasingly used, the company aims for cross-functional versatility, enabling a single robot to handle multiple tasks in a single shift. For example, a robot might sort engine parts in the morning and then move to quality control for visual inspections in the afternoon. This pliability sets general-purpose humanoids apart from single-task industrial robots. It gives manufacturers a liquid workforce that can adjust quickly to changes in market demand or supply chain needs.  

The 2026 software update adds collaborative problem-solving to the robots. If a robot encounters an unexpected problem, it can alert a nearby human supervisor for help via a haptic signal. The supervisor gives a quick fix, which the robot remembers and shares with the rest of the fleet through the cloud. This collective learning means the entire robotic team improves each time a robot faces a new challenge. This ongoing improvement increases the plant’s overall productivity.  

The New Pulse of American Production 

As these new techniques are introduced in factories, we are seeing a steady transformation in the workplace. The factory is becoming more responsive with systems that work closely alongside human needs. We are moving toward a time when labor and logic work together, and every task is supported by technology that is always ready to help. Over time, the line between tool and worker may blur, forming a space where people and machines work in harmony. The factory is no longer simply a piece of heavy machinery, but a lively, efficient environment, always ready to support production.

Source:  F.02 Contributed to the Production of 30,000 Cars at BMW 

IBM has added quantum-safe encryption to its enterprise storage lineup, especially the new IBM FlashSystem x600 series, to protect data from harvest-and-decrypt-later cyberattacks. These solutions use advanced cryptographic algorithms built to resist future quantum computing threats. They are expected to be available in March 2026.  

Key aspects of this integration include:  

  • Secure storage systems: The new FlashSystem X600 uses the latest Flash Core Module 5 (FCM5), a specialized storage module to deliver Quantum Safe encryption for stored data  
  • Data protection: This technology protects data against future threats by enabling quantum-safe TLS, a protocol for encrypting data in transit, and safeguarding data at rest. It is designed for critical infrastructure, government, and finance sectors.  
  • IBM Z mainframe security: IBM Z16 and LinuxONE systems use quantum-safe technologies and algorithms to secure data at rest, in transit, and in use  
  • DataPower Gateway X4 is a new physical appliance that secures and automates hybrid workloads with built-in quantum-safe cryptography for long-term data protection.  
  • Quantum-safe portfolio: IBM provides tools such as IBM Guardian Quantum Safe (for tracking cryptographic use), Quantum Safe Explorer (for exploring quantum algorithms), and Quantum Safe Remediator (for deploying new cryptography).  

These advancements are part of IBM’s broader plan to offer crypto agility, helping businesses adapt to changing cryptographic standards. Building on these innovations, IBM is also focusing on the needs of businesses facing evolving security requirements.  

Continuing its focus on advanced security, IBM has introduced the next-generation DataPower Gateway X for a high-performance security gateway designed for enterprises. It secures, integrates, and automates modern and hybrid workloads, featuring quantum-safe cryptography for long-term data protection against future threats.  

The X4 appliance serves as a unified gateway to protect, control, optimize, and connect applications across on-premises, cloud, and hybrid environments.  

Why Application Security Matters for Business Agility 

Enterprise IT environments are becoming increasingly complex, spanning multiple clouds, data centers, and diverse architectures. At the same time, cyber threats are growing and becoming more advanced, including new risks to current encryption from future quantum computing.  

To innovate efficiently and securely, organizations must share devices with strong visibility, governance, and control. Secure, scalable integration is essential for delivering digital experiences and enabling automation to enhance efficiency.  

Without a modern approach to application security, organizations can slow innovation, face increased costs, and risk exposing critical assets to threats.  

Enterprise-Grade Security With Quantum Safe Production 

Protecting client assets is IBM’s priority. DataPower Gateway X4 appliances deliver robust application security and integration services, combined with ease of use and a low cost of ownership features that have been established in DataPower solutions.  

The gateway supports a unified security framework for on-premises, cloud, and hybrid environments. Placed at the network edge and in the DMZ, it blocks unauthorized access, helps prevent denial-of-service attacks, and optimizes traffic routing. With DataPower Virtual Edition, organizations can extend this protection to cloud deployments, ensuring consistent security across the entire environment. The gateway secures both traditional web services and modern workloads, including API-based apps, event-driven and streaming services using Kafka, gRPC, and GraphQL. In computing and IT security, IBM researchers developed cryptographic schemes that NIST adopted as standards to strengthen public key cryptography. DataPower Gateway X4 appliance includes post-quantum cryptography (PQC) capabilities that can be configured for both inbound and outbound connections using TLS server and client profiles. Hybrid cryptographic algorithms are also provided, combining quantum-safe and classical methods to balance security strength with performance. With IBM DataPower, organizations can confidently protect the WAN and optimize service delivery while reducing development effort and mitigating business risk.  

Key Capabilities of DataPower Gateway X4 Appliance 

DataPower Gateway X4 is a plug-and-play appliance for rapid deployment. It is tailored for enterprise architects, security teams, and platform engineers, offering:  

  • Improved performance and scalability: Cologne offers more processing power, memory, and network bandwidth than previous generations (data power X2 and X3 gateway appliances).  
  • Secure storage for cryptographic keys: The hardware security module (HSM), a dedicated device for managing cryptographic keys, stores them in secure hardware, speeding cryptographic operations and simplifying management by centralizing key security in a hardened unit.  
  • Enterprise-grade secure design: Features a hardened tamper-resistant build that supports advanced cryptographic operations and quantum-safe protection  
  • Reliable, seamless, high-speed integration: The front panel offers networking options with built-in Ethernet model modules that support 1 GB, 10 GB, 40 GB, and 100 GB speeds.  
  • High-performance storage: comes with 1.6 TB NVMe SSDs for faster performance and greater efficiency.  
  • Improved usability: features an optimized web management interface to help developers work more efficiently.  

Availability and Next Steps 

The DataPower Gateway X4 appliance will be available starting March 26th, 2026. DataPower V11.0 will also be released on that date for use with the DataPower Virtual Edition entitlement.

Source: Secure and automate hybrid IT workloads with IBM’s new DataPower Gateway X4 appliance