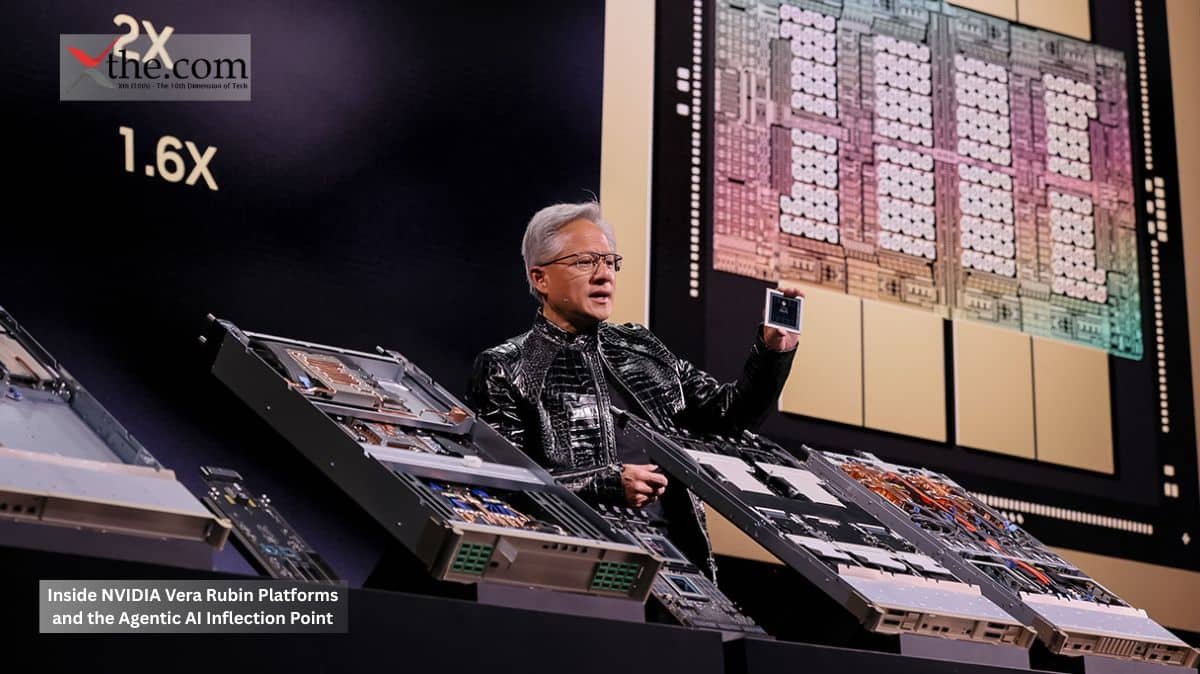
San Jose, California  

Today’s enterprise AI clusters can respond to chatbot questions in milliseconds, but they often struggle with and will be challenged: running thousands of self-directed workflows simultaneously without human help. Because of this, artists in this group, IT bands, are shifting their focus from single benchmark scores to ongoing, reasonable performance. NVIDIA Vera Rubin is designed to meet this need.  

This new platform differs from traditional GPU servers, which handle one task at a time. Instead, it works more like an always-on industrial system for AI thinking. It brings together the Vera CPU, Rubin GPUs, high-speed memory, and closely connected NVL72 Racks into one system built for long-range autonomous reasoning. This change puts agentic influence at the heart of modern data centers.  

Why Agentic Inference Changes in Infrastructure Economics 

Traditional LLMs handle prompts one at a time. A user asks something, the model replies, and then the system waits for the next request. Autonomous AI agents work differently. They plan, gather outside data, carry out tasks, check their results, work with other agents, and keep repeating these steps nonstop.  

This way of working creates a completely different demand on computing resources.  

For example, one AI coding agent might run multiple reasoning processes in parallel while testing software changes in the pharmaceutical industry. A research agent could keep memory graphs active for weeks while conducting simulations. When thousands of these agents run together in a company, traditional GP areas can’t keep up.  

This is where Nvidia Vera Rubin separates itself from earlier accelerator generations.  

This system is built to keep inference running smoothly over time, not just handle quick bursts of prompts. NVIDIA focused on memory speed, strong connections, and fast coordination between CPUs and GPUs. The goal is to assist ongoing work by many agents, not just single responses.  

The Role of the Vera CPU in Autonomous Reasoning Pipelines. 

Most people talk about the Rubin GPUs, but the Vera CPU could actually be more important for businesses using this platform.  

Agentic systems are always managing schedules, retrieving data, syncing memory, and directing workloads. These tasks put a lot of pressure on CPUs; older x86 servers often slow down when thousands of agents compete for memory and network access.  

The Vera CPU solves this problem by working more closely with Nvidia’s accelerated computing tools rather than operating separately. The CPU is part of a unified system for reasoning. This is important because autonomous agents don’t follow simple straight paths. They branch out, pause, start new processes, and go back to earlier steps.  

NVIDIA’s design philosophy appears intended to minimize those coordination penalties.  

A large insurance company uses autonomous agents to process claims. Each agent must review documents, check fraud databases, interact with customer systems, and forward unusual cases to specialized models—all simultaneously. The main challenge isn’t a lack of powerful GPUs; it’s ensuring that all these tasks remain coordinated and run quickly, even when thousands run at once.  

That operational profile aligns directly with the architectural priorities behind agentic inference systems.  

How NVL72 Racks Turn Data Centers Into Persistent AI Engines 

The scale story becomes clearer inside NVIDIA’s NVL72 racks design.  

Unlike regular GPU arrays made from loosely connected parts, these rack‑scale systems operate as tightly coupled computing units designed for very fast communication. NVIDIA treats the whole rack as one big computer.  

That design has major consequences for enterprise infrastructure spending.  

These systems use much more power and need stronger cooling. Networking becomes a main concern, not just an add-on. Many older data centers weren’t built to handle non-stop, high-use, autonomous insurance like this.  

This explains why infrastructure buildout has become one of the most aggressive spending categories among hyperscalers and Fortune 500 cloud operators.   

More and more analysts call future AI centers AI factories because they look more like industrial plants than old-style server rooms. The term makes sense. These systems are always producing large-scale reasoning results.  

AI Factories and the Shift Away From Training-Centric Spending 

The economics behind AI factors are changing quickly.   

For a long time, most cloud budgets were spent on training models. Companies competed to build bigger base models. Now, more money is being invested in infrastructure because autonomous agents constantly use computing power.  

Training runs eventually stop. Agentic reasoning rarely does.  

This difference is important for investors, CIOs, and infrastructure providers. Persistent inference systems need ongoing hardware, electricity, and networking resources.  

In practice, companies using Nvidia Vera Rubin aren’t just buying servers. They’re setting up infrastructure meant to run nonstop and handle heavy workloads for a long time.  

Evaluating NVIDIA Vera Rubin Platform Agentic AI Hardware Specs 

The most important aspect of the NVIDIA Vera Rubin platform agentic AI hardware specs is not peak benchmark performance; it is architectural balance.  

NVIDIA seems to have designed the platform with three main needs of self-driving AI in mind. They are massive inter-agent communication, persistent memory interaction, and continuous inference scheduling under heavy concurrency.  

This mix sets Rubin apart from earlier GPUs, which were mostly focused on training large models.  

The impact goes beyond NVIDIA. Now, software companies, cloud providers, robotics firms, cybersecurity teams, and banks can all use infrastructure that enables large-scale autonomous digital work.  

The next stage of AI computation might not be about building the biggest model. Instead, it could be about who runs the most efficient autonomous reasoning systems. NVIDIA’s Vera Rubin brings that future closer than many companies thought possible.

Source: Nvidia Investor 
San Diego, California 

Over the years, top-of-the-line smartphones have become even pricier due to their highly advanced cameras, processors, and display technology. A good number of premium phones today can easily cost $1000, which makes consumers hold off on getting new phones until absolutely necessary. 

All of that frustration may be about to shake up the smartphone market. 

People do want speedy performance and smart AI capabilities in their phones, but not necessarily at premium prices like those found in flagships. This opens up a lot of room for businesses that have the capability to integrate technology in budget-friendly devices. 

And here is where Qualcomm Snapdragon processors come into play. 

The tech company is actively working towards offering AI-capable mobile processors in mid-range smartphones. 

Why AI Features Will Make People Buy More Smartphones 

Artificial intelligence is set to become a very important factor in making today’s smartphones more appealing. These days, artificial intelligence technologies enable devices to use AI voice assistants, photo enhancements, translations, productivity apps, smart batteries, and on-the-fly personalization. 

Users are coming to see such features as default rather than high-end options. 

As a result, companies have to put AI processing technologies into their smartphones. 

  • Photo and video enhancements 
  • AI voice assistants 
  • Smart batteries 
  • Translation tools 
  • App and task suggestions 

Mobile AI is changing people’s perception of smartphones. 

How Qualcomm Snapdragon Processors Are Revolutionizing The Industry 

The new AI chip initiative from Qualcomm is all about enhancing AI performance without a major hike in manufacturing cost. 

It entails creating chips that will be able to support the execution of complex AI operations in the smartphone itself as opposed to being solely reliant on cloud computing. 

In addition, this strategy will help to introduce premium attributes within lower-priced products. 

And this might make a significant impact on Smartphone Prices for years to come. 

Instead of locking advanced AI features to pricey smartphones, firms will increasingly be providing such intelligence across price ranges. 

Objectives for the expansion of AI chips by Qualcomm 

  • Introducing AI capabilities in low-priced smartphones 
  • Boosting efficiency within mobile AI operations 
  • Minimizing dependency on cloud-based AI processing 
  • Enhancing battery efficiency performance 
  • Expanding premium characteristics in mid-range phones 

Why On-Device AI is Important 

One of the most important areas Qualcomm focuses on in its development is on-device AI processing. 

In the past, many artificial intelligence applications were powered by connected cloud technologies. It was not very effective because it could lead to delays, privacy concerns, and increased data consumption when working with AI. 

However, on-device AI technology enables these operations to be performed independently of the cloud and directly on users’ smartphones. 

  • Benefits of on-device AI processing 
  • Immediate reaction to real-life situations 
  • Privacy of sensitive data 
  • No need for an Internet connection to perform AI tasks 
  • Lower latency when processing data 
  • Increased battery life when working with AI tasks 

Today, companies consider on-device AI processing as a key factor for successful smartphone development. 

Why Do Customers Care About Phone Pricing? 

Due to inflation and increasing living standards worldwide, people are becoming more careful about their technology expenses. 

Customers begin to wonder whether expensive flagship smartphones truly deserve their exorbitant prices when even affordable phones keep getting better. 

This trend is changing the approach manufacturers are taking to their products. 

People are increasingly preferring practicality and usefulness over luxury and experimental innovations in the tech world. 

That is why Qualcomm’s product portfolio aligns perfectly with customer demands, helping manufacturers achieve better performance at lower cost. 

How Mobile Hardware is Changing with Artificial Intelligence 

The mobile market is no longer fighting for better cameras and faster CPU. Instead, smartphone AI capacity becomes an integral part of development and future innovations. 

Nowadays, chip manufacturers design CPUs for efficient machine learning, generative AI, and contextual computing. 

Key areas where AI-specific chipsets enhance smartphone functionality 

  • Camera functionality and photo processing 
  • Speech recognition and digital assistants 
  • Productivity and work optimization 
  • Gaming optimization and enhanced performance 
  • Energy and thermoregulation efficiency 

Reasons Why the Mid-Range Market May Face Increased Competition 

If sophisticated chips are cheaper, the gap between the top-tier and mid-range segments of the Smartphone market may decrease greatly. 

Such developments may lead to major upheavals across the Consumer Electronics industry. 

Companies that can deliver a premium artificial intelligence experience at lower prices will secure significant competitive advantages among cost-sensitive buyers. 

On the other hand, the ability of premium companies to explain high prices will be limited to exclusive software, camera technologies, and luxury hardware design. 

The term “Qualcomm Snapdragon budget AI phone processors” has become increasingly popular as buyers seek cheap, effective AI-compatible devices. 

Why Investors Should Pay Attention to Qualcomm 

The AI-powered Smartphone race is one of the key areas of interest for tech investors. 

Qualcomm occupies a particularly significant position because it is the producer of processor units used in numerous global smartphones. 

Reasons Why Qualcomm’s approach matters from a financial perspective 

  • Increasing AI phone demand 
  • Giant mid-range markets worldwide 
  • AI processing capacity gains commercial value 
  • Replacement rate of smartphones slows down 
  • Premium affordability is attractive to consumers 

The next stage of smartphone competition seems to hinge on balancing AI capabilities with affordability. 

Conclusion 

The latest move by Qualcomm with its Snapdragon chips shows how artificial intelligence is revolutionizing the smartphone market from within. By integrating their advanced AI capabilities into budget phones, Qualcomm is allowing device makers to offer the best features associated with high-end phones, even though they do not charge for them like flagship smartphones. With consumers now seeking better value and performance, Qualcomm’s AI-enabled chips could define smartphone pricing in the future.

Source- Qualcomm Newsroom 

SEATTLE, WASHINGTON —  

AWS Nitro Enclaves represent the most architecturally complete confidential cloud computing solution that Amazon has deployed at production scale, a framework that creates isolated execution environments so structurally sealed that not even a root-level administrator on the parent EC2 instance, nor any AWS cloud operator, can access or view the decrypted data being processed inside. For enterprises in finance, healthcare, and government that must demonstrate to regulators that sensitive data is protected not only from external attackers but from internal staff with elevated system access, Amazon AWS Nitro isolated compute security setups provide the hardware-enforced isolation boundary that software access controls and network segmentation alone cannot credibly deliver.  

What AWS Nitro Enclaves Actually Are  

AWS Nitro Enclaves is an Amazon EC2 feature that allows customers to create isolated execution environments called enclaves from Amazon EC2 instances  separate, hardened, and highly constrained virtual machines that provide only secure local socket connectivity with their parent instance, have no persistent storage, interactive access, or external networking, and whose data and applications cannot be accessed by the processes, applications, or users including root or admin users of the parent instance.  

The four limitations in the Nitro system’s design are not software-based, as an administrator cannot change them. Instead, they come from how the system was designed and constructed, as enforced at the silicon level by the Nitro Hypervisor. The AWS Nitro System was built on a completely different architecture than prior generation hypervisor architectures so as to provide customers with confidentially computing protection for all of their Nitro-based Amazon EC2 instance without requiring customers to modify any of their application code in order to have that protection. 

The zero-trust infrastructure implication is direct: the confidential cloud protection that AWS Nitro Enclaves deliver does not depend on trusting any individual with administrative credentials. Trust is removed from the human operator layer entirely and relocated to the hardware verification layer, the only layer that cannot be socially engineered, credential compromised, or administratively overridden.  

How Cryptographic Attestation Enforces Zero Trust Infrastructure  

The mechanism by which AWS Nitro Enclaves verify that only authorized code is executing within the sealed environment, and by which external systems confirm that authorization before releasing sensitive data is cryptographic attestation. AWS NitroTPM and AWS Nitro Enclaves allow customers to attest to system state, securely generate and manage cryptographic keys, and prove platform identity, with the Nitro System controls that prevent operator access forming part of the AWS Service Terms and the Nitro System having received independent affirmation of its confidential computing capabilities.  

The attestation process operates through a document generated by the Nitro Hypervisor that contains a cryptographic measurement of every component running inside the enclave, the operating system, application code, and configuration state at the moment of execution. Each enclave generates an attestation document that includes a cryptographic measurement of the enclave’s contents, signed by the Nitro Hypervisor and verifiable by AWS KMS or an external system, ensuring that only trusted enclaves can perform sensitive operations.  

When an enclave requests that AWS Key Management Service release a decryption key, KMS verifies the attestation document before releasing the key. If any component inside the enclave does not match the expected cryptographic measurement because code has been tampered with, an unauthorized library has been inserted, or the boot process has been modified, KMS refuses the key release request, and the sensitive data remains encrypted and inaccessible. The cryptographic attestation mechanism converts the zero-trust infrastructure principle from a network policy into a mathematically verifiable runtime property.  

Corporate Data Security Use Cases and Server Isolation Architecture  

Nitro Enclaves provide cryptographic attestation for multiparty collaboration, enabling many parties to access and process data with extreme sensitivity while providing no access or visibility into the actual data. This option allows customers to further restrict their own users and the software they use from accessing exactly the same types of data that previously could have been accessed. 

The multiparty computation capability extends corporate data security beyond the insider threat protection scenario, enabling an entirely new class of collaborative enterprise workflows. Two competing financial institutions can jointly analyze combined transaction datasets to identify systemic fraud patterns without either institution’s data analysts being able to view the other party’s raw records, because the combined dataset is processed exclusively within an AWS Nitro Enclaves environment that neither party’s staff can access. The analysis result exists in the enclave; the underlying data never does.  

AWS Nitro Enclaves is now available in all AWS Regions at no additional cost beyond the cost of the underlying Amazon EC2 instances and any other AWS services used alongside Nitro Enclaves. The global regional availability, combined with zero incremental cost, removes the two procurement friction points: geographic constraint and budget justification, which have historically slowed enterprise adoption of confidential computing capabilities in organizations that recognized the insider threat exposure but lacked a deployable, cost-justified solution.  

Amazon AWS Nitro Isolated Compute Security Setups for Enterprise Deployment  

A Nitro Enclave is a fully isolated virtual machine created from an EC2 instance, with its own kernel, memory, and CPU cores carved out from the parent instance. The critical difference from a regular virtual machine is the absence of network access, persistent storage, and interactive access.  

For enterprise security architects designing Amazon AWS Nitro isolated compute security setups, the configuration discipline required centers on minimizing the trusted computing base within the enclave itself. Best practices require avoiding general-purpose logic within enclaves and focusing only on the specific high-security task: securing the parent EC2 instance, as it is the only entry point for managing the enclave lifecycle, and encrypting communication over the vsock channel using additional protocols when data sensitivity requires it.  

Communication between a parent EC2 instance and its enclaves is done via the VSock interface; there are no other ways to connect these entities. Since the only data that flows through the VSock is input data encrypted upon entry and output data after processing, the VSock provides a high level of server isolation. When the enclave processes some data, it produces an output and then terminates completely, leaving no evidence that could be used by an insider to deductively infer the computation performed. 

Conclusion  

AWS Nitro Enclaves neutralize local insider threats through a server isolation architecture that removes human trust from the data access equation, entirely  replacing it with hardware-enforced boundaries, cryptographic attestation verified by AWS KMS at the moment of key release, and a four-constraint execution model that makes root-level administrative access to the parent instance structurally irrelevant to the security of the data being processed inside. Corporate data security requirements across healthcare, financial services, and government that mandate protection of data in use, not just at rest and in transit, are addressable through Amazon Web Services Nitro Isolated Compute security configurations without requiring custom hardware, bespoke cryptographic infrastructure, or modifications to existing application code. As zero-trust infrastructure becomes the regulatory baseline rather than a voluntary security posture, the confidential cloud architecture that AWS Nitro Enclaves delivers at no incremental cost across all AWS Regions positions Amazon’s isolation framework as the most accessible hardware-enforced insider threat mitigation available to enterprise cloud operators in 2026.

Source: AWS Announces General Availability of Nitro Enclaves 

MOUNTAIN VIEW, CALIFORNIA —  

Gemini 3.5 Flash is Google’s most consequential lightweight AI model release since the Flash tier was introduced, a system that outperforms larger and more expensive frontier models on the model benchmarks that enterprise developers and code automation teams evaluate most seriously, while delivering four times the output speed at less than half the cost of comparable frontier configurations. Announced at Google I/O on May 19, 2026, Gemini 3.5 Flash achieves 76.2% on Terminal Bench 2.1, 1,656 Elo on the GDPval AA real-world agentic benchmark, and 83.6% on MCP Atlas for multi-step tools reliability  scores that not only surpass its predecessor Gemini 3.1 Pro but position a lightweight AI model as the most capable agentic coder in Google’s portfolio. For investors and developer-efficiency-focused enterprise buyers, the arrival of Google Gemini 3.5 Flash developer benchmark scores at this performance level reframes what cost-efficient AI inference can deliver in production.  

What the Google Gemini 3.5 Flash Developer Benchmark Scores Actually Demonstrate  

On Terminal Bench 2.1, a coding benchmark, Gemini 3.5 Flash scored 76.2%, and on GDPval AA, they scored 1,656 Elo; they also scored 83.6% on MCP Atlas and 84.2% on CharXiv Reasoning. 

The MCP Atlas score deserves particular attention from developer efficiency-focused enterprise buyers. Gemini 3.5 Flash ranks third out of 117 models in agentic tool use and computer tasks benchmarks, with an average score of 97.3, placing it among the top performers in this category. A lightweight AI model ranking third globally in agentic tool use, the benchmark category most directly relevant to multi-step tools orchestration and code automation pipeline reliability, is the architectural outcome that validates Google’s design decision to optimize 3.5 Flash for action rather than raw knowledge retrieval.  

The financial reasoning benchmark improvement is equally significant for enterprise deployment teams. The Finance Agent v2 benchmark shows a 14.9 percentage point improvement over Gemini 3.1 Pro, and an 81.0% SWE Bench score puts Gemini 3.5 Flash ahead of Claude Opus 4.6 at 80.8% and meaningfully ahead of Grok Build at 70.8%. SWE Bench measures a model’s capacity to resolve real GitHub software engineering issues, not synthetic coding questions, but the actual debugging, patch writing, and code modification tasks that developer efficiency in enterprise environments demands continuously.  

Why Lightweight AI Architecture Outperforms Larger Models on Multi-Step Tools  

The architectural efficiency that allows Gemini 3.5 Flash to outperform larger frontier models on multi-step tool benchmarks is grounded in a deliberate design orientation toward agentic execution rather than breadth of general-purpose reasoning. Building on the strong multimodal foundation of Gemini 3, Gemini 3.5 Flash generates richer, more interactive web interfaces and graphics, executes multiple concepts in parallel to build complete branding concepts, and generates different interface approaches for a checkout flow in just 60 seconds on AI Studio.  

While the benchmarks used to evaluate models typically do not give an adequate measure of how well models support parallel execution, parallel execution is a key performance differentiator for models; for instance, when a model processes a multi-step tool call serially, it incurs a compounding latency cost that increases with the number of steps in the process. Unlike traditional models, the Gemini 3.5 Flash addresses this issue by coordinating sub-agents through simultaneous processing of the automation libraries associated with each sub-agent in a tool chain, rather than sequentially. This execution model generally delivers at least twice the performance of traditional models in highly complex workflows that require agentic actions and decision-making capabilities. 

The 3.5 Flash release is the opening move in what Google is calling a new model family built around agentic execution, with Gemini 3.5 Pro already in internal use and expected to roll out the following month  and the Gemini 3 series having established Google’s current position in the frontier model race through Gemini 3.1 Pro, which led the Artificial Analysis Intelligence Index at launch and scored 77.1% on ARC AGI 2.  

Developer Efficiency and Enterprise Deployment Availability  

Now that the Gemini 3.5 Flash is available globally, anyone can access it directly from the Gemini App, the AI Mode in Google Search, and Google’s Antigravity and Gemini APIs for developers in AI Studio & Android Studio. While it may not yet provide access to the enterprise version, developers will receive immediate improvements in developer efficiency by eliminating the need to wait in long lines, access through limited quotas, or a phased rollout of the new models. 

Gemini 3.5 Flash is now the default model for the Gemini app and AI Mode in Search globally, and the new Gemini Spark personal AI agent, which runs continuously, helping users navigate digital tasks and take action under user direction, uses 3.5 Flash as its foundational model. Deploying a lightweight AI model as the default inference layer for Google’s largest consumer surfaces billions of daily Search interactions and the full Gemini app user base is the production scale validation that enterprise code automation buyers rely on as proof of operational reliability before committing their own workloads.  

Conclusion  

Gemini 3.5 Flash has formally established that a lightweight AI architecture optimized for agentic execution can outperform larger, more expensive frontier models on benchmarks that actually depend on developer efficiency and code-automation performance. The Google Gemini 3.5 Flash developer benchmark scores  76.2% on Terminal Bench 2.1, 97.3 average score in agentic tool use across 117 models, and 81.0% on SWE Bench, documenting a multi-step tools performance profile that enterprises building production code automation pipelines can rely upon at $1.50 per million input tokens and four times the output speed of comparable frontier configurations. For enterprise API customers whose infrastructure costs scale directly with inference volume, the architectural efficiency that Gemini 3.5 Flash delivers at these model benchmarks converts developer efficiency from a performance aspiration into a measurable line-item reduction across every production-agentic workflow it replaces.

Source: Gemini 3.5: frontier intelligence with action 

SANTA CLARA, CALIFORNIA —  

AMD Advancing AI 2026 is the most formally structured declaration of AMD’s counteroffensive against proprietary AI infrastructure that Lisa Su Strategy has produced to date, a flagship summit scheduled for July 23, 2026, at the San Francisco Moscone Center Tech venue that will deliver AMD Advancing AI open source ecosystem blueprints for building, deploying, and scaling AI powered by AMD from silicon to software. The event positions Open Source AI development, ROCm Software maturity, and end-to-end Corporate Hardware integration as the three pillars of AMD’s answer to NVIDIA’s closed CUDA ecosystem, a strategic architecture that Lisa Su has been assembling through acquisitions, developer investment, and hyperscaler partnerships across the past three years, and will formally present to the global AI developer community in July.  

What AMD Advancing AI 2026 at Moscone Center Will Deliver  

AMD announced that Advancing AI 2026, its flagship global AI event, will be held both in person and livestreamed from the San Francisco Moscone Center on July 23, 2026, with the event providing the AI open ecosystem with blueprints for building, deploying, and scaling AI powered by AMD, as AMD leaders join Chair and CEO Dr. Lisa Su alongside AI ecosystem partners, customers, and developers to share how the company’s end to end AI solutions from silicon to software are reshaping the AI and high performance computing landscape.  

The Moscone Center Tech venue selection is deliberate, the same location where the industry’s most consequential developer conferences have historically defined platform directions. In addition to announcements, Advancing AI 2026 will host talks, networking, and hands-on events that give attendees the chance to engage directly with AMD’s AI researchers and engineers. AMD’s next-generation 2nm EPYC Venice Zen 6 CPUs are expected to launch alongside the Instinct MI400 in 2026. The MI400 architecture, built on TSMC’s 2nm process and designed to compete directly with NVIDIA’s next-generation Rubin platform, represents the Corporate Hardware foundation upon which the AMD Advancing AI open-source ecosystem blueprints that July’s summit will distribute are intended to run.  

Why ROCm Software Is the Strategic Center of Gravity  

Rather than build a walled garden where the technology is controlled by a single entity, AMD has gone down the open source route with ROCm, which integrates with other open source projects such as vLLM to allow for faster innovation, and AMD Vice President of AI Software Anush Elangovan stated directly that the company could try to build something closed source but would not get the velocity of an open ecosystem.  

The ROCm Software maturity trajectory that Lisa Su’s strategy has funded over the past two years is the most operationally significant development in the Open-Source AI infrastructure landscape outside of model development itself. ROCm 7 introduces full support for lower precision data formats such as FP4 and FP8, enabling developers to run modern AI models significantly faster without sacrificing accuracy, with AMD promising up to a 3.5 times improvement in inference performance compared with previous generations, while also expanding accessibility under the ROCm Everywhere initiative with support broadened to include Windows-based systems and consumer-grade Radeon graphics cards.  

The ROCm Everywhere initiative is the Lisa Su Strategy move that most directly addresses the developer adoption gap that has historically constrained ROCm Software growth. A developer who can write and test AI code on a consumer Radeon gaming GPU before deploying to an Instinct data center accelerator faces no platform transition cost between development and production, the same framework APIs, the same model compatibility layer, and the same debugging toolchain operate identically across both environments. AMD has strengthened its integration with the broader ecosystem by offering day-zero support for popular tools such as PyTorch and vLLM, enabling developers to work immediately with new hardware releases.  

Open-Source AI Validation Through Hyperscaler Adoption  

The AMD Advancing AI open-source ecosystem blueprints that the July summit will formalize are not theoretical proposals awaiting market validation; they are documentation of deployment patterns that hyperscalers have already adopted at production scale. Meta discussed how it is already deploying MI300X GPUs for inference and plans to utilize MI350X for training workloads, citing AMD’s total cost of ownership advantages and high memory capacity as key differentiators particularly for models with 100 billion or more parameters, and Meta representatives noted that ROCm is finally ready for prime time production, while Microsoft through its Azure division confirmed it utilizes AMD GPUs for both the inference and training of OpenAI models.  

The confirmations by Meta and Microsoft have strategic implications beyond the monetary value of the purchases each company made. The world’s largest social media AI platform, Meta, and the enterprise-level cloud company that provides the backend for the OpenAI production workloads, both confirm ROCm Software is ready for production use for inference and training tasks of frontier models, changing how the developer community thinks about the risks associated with moving to the type of Open Source AI parts infrastructure based on AMD. Developers will no longer question whether ROCm Software can accommodate the workload; they will ask whether their existing investments in tooling to support CUDA-based applications are justified by the cost of switching to an AMD open ecosystem. 

What Lisa Su’s Strategy Means for Corporate Hardware Buyers  

AMD SVP and GM of Adaptive and Embedded Computing Salil Raje stated plainly that AMD was not traditionally a software company but has turned its attention to software with ROCm and an explicit push to be more open source friendly so the developer community can work with it at scale, representing a subtle but massive shift from the old AMD whose playbook leaned on a sound chip and hoped the ecosystem would follow, with AI having taught the entire industry that the ecosystem must be engineered, funded, and obsessively supported.  

For Corporate Hardware procurement teams evaluating AI infrastructure investments ahead of AMD’s July summit, the AMD Advancing AI event represents the most important opportunity to assess whether the AMD Advancing AI open source ecosystem blueprints Dr. Lisa Su presents in San Francisco align with the deployment requirements and budget constraints that Open Source AI infrastructure must satisfy to displace incumbent NVIDIA configurations across the enterprise tier.  

Conclusion  

AMD Advancing AI 2026 at the Moscone Center Tech venue on July 23, 2026, formalizes the Lisa Su Strategy, which has been assembled through ROCm investments, hyperscaler validation, and open-ecosystem partnerships over three years of deliberate infrastructure execution. ROCm Software version 7 with FP4 and FP8 precision support, day zero PyTorch and vLLM compatibility, and consumer GPU accessibility establishes the Open-Source AI developer foundation that AMD Advancing AI open-source ecosystem blueprints will document and distribute to the global developer community attending in person and via livestream. Corporate Hardware buyers who treat the July summit as a passive product announcement will miss its structural significance. It is the moment AMD formally presents the complete alternative to the proprietary AI infrastructure that Meta, Microsoft, and OpenAI have already chosen, and the enterprise tier is now positioned to adopt it at scale.

Source: AMD Announces “Advancing AI 2026”

SAN FRANCISCO, CALIFORNIA —  

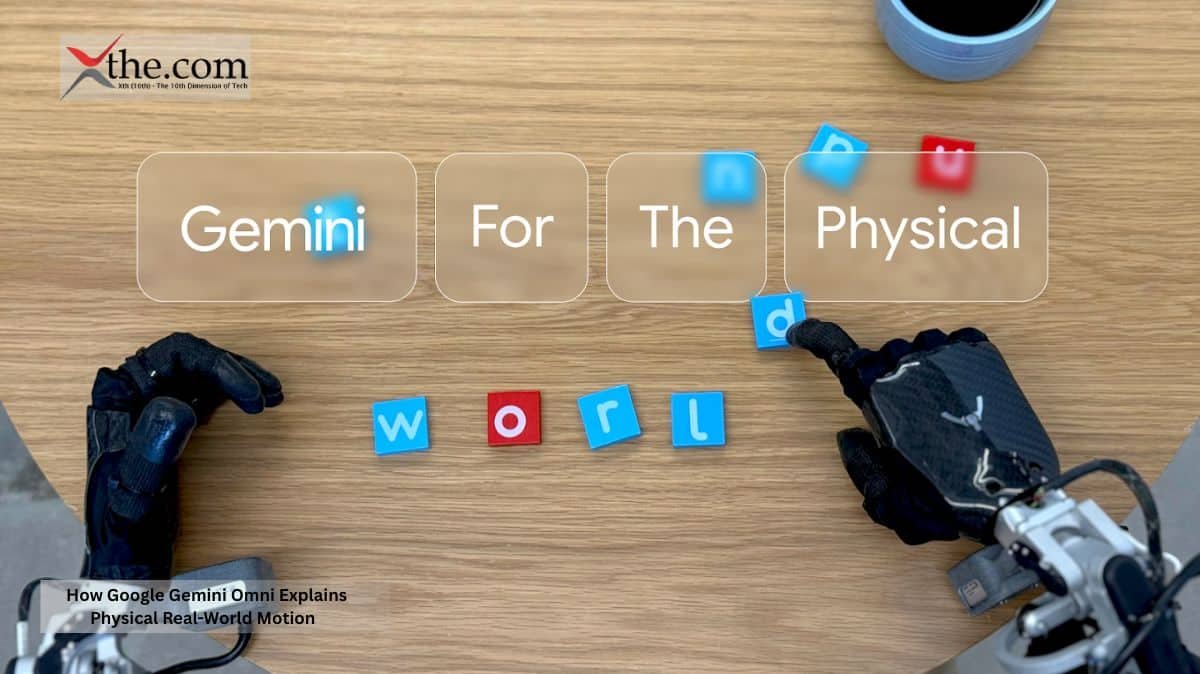
Gemini Omni is not a video generator in the conventional sense; it is a world model, the most technically ambitious multimodal system Google DeepMind has publicly deployed, and it approaches physical video AI from a fundamentally different architectural premise than any generative video tool that preceded it. Initially presented on May 19, 2026, at Google I/O 2026, Gemini Omni uses an intuitive model of gravity, motion, and fluid behavior as part of its content-generation process so that the resulting video-generated content adheres to the same physical rules as real-world video versus simply matching patterns of pixels to create visually plausible results for a limited number of frames before breaking down completely. For video generation tech professionals working on YouTube, developers of classic/stock video content, and enterprise users evaluating video-development tools, the addition of Google Gemini Omni Flash’s global physics model significantly expands the potential for AI-generated video to transition from an interesting showcase to an established creative-application environment. 

What the Gemini Omni World Model Architecture Actually Does  

Despite most conventional video generators translating text-based prompts into non-contiguous pixel placement, Gemini Omni integrates inputs from multiple media types, including textual prompts, photographic references, videos, and sound recordings. In addition, it has an underlying understanding of basic principles of physics, such as kinetic energy, fluid dynamics, gravity, and the weight of materials. As such, due to their understanding of these concepts and the resulting object(s) created by these forces, the finished products produced by Gemini Omni will exhibit structural realism instead of an appearance of being illusory or warped. 

The architectural disconnect between understanding how physical forces behave and simulating how they will manifest visually is the primary issue addressed by the development of an Omni Flash world model of physics. The official public release site for Google’s Omni product states that it offers a significantly superior, intuitive understanding of various forces than existing video creation products and enables users to create more realistic scenes. Evidence of this significant capability enhancement was provided on stage by Demis Hassabis, who claimed that the creation of Omni represents a step towards providing an AGI product. He also stated that Gemini represents a world-model-based form of AI capable of both understanding and recreating the world’s physical characteristics. As such, the way in which Hassabis suggested a change in how technology could be used to represent reality, versus creating entertaining content visually appealing on screens, is not simply intended to be queried as a commercial statement; rather, it is a clear statement of architectural purpose, and the design intent to use Gemini Omni as a physical reality modeling infrastructure will be the basis of how video is produced for many future applications. 

Google Flow and the Physics Engine AI for Creative Professionals  

The production surface through which Gemini Omni delivers its physics engine AI capability to creators and developers is Google Flow, the dedicated AI filmmaking platform that received substantial updates alongside the Omni Flash launch at Google I/O 2026. The Google Flow platform received additional updates alongside Omni Flash, including a Flow Agent for brainstorming and batch generation, a custom Tools feature for shareable no-code workflows, and Flow Music support for full music video creation and style transformation.  

The conversational editing architecture that Google Flow enables through Gemini Omni is the most operationally significant capability for YouTube creator tech professionals who previously spent hours iterating on video edits through separate tools and re-rendering. Gemini Omni gives creators an easier way to edit video with natural language, where every instruction builds on the last, characters stay consistent, the physics hold up, and the scene remembers what came before, allowing a video to become the starting point for something that could never have been filmed conventionally.  

The World Model Foundation enables consistent video across multiple edits during a conversation, allowing users to change the background and lighting. The model uses reasoning to completely re-evaluate the physical environment rather than simply layering on top of it. For tech professionals creating videos for YouTube, shadows, reflections, and other material interactions are adjusted to the new lighting conditions in post-production, rather than producing visual artifacts like typical compositing does when physical consistency is not modeled from first principles. 

Physical Video AI Availability and the YouTube Creator Ecosystem  

The Gemini Omni Flash was the first Gemini Omni product released, launching on May 19 in India. The Gemini Omni Flash was made available to everyone for free through Google Apps, but you can subscribe ($7.99/month) to gain access to the Google AI Plus program and Gemini Omni Flash. This decision to make Gemini Omni available through YouTube’s creation surfaces is a strategic initiative by Google to redefine how videos are created, using physical video AI technology as the new baseline for content creation on YouTube, without requiring expensive professional production equipment.  

The broader video generation competitive context clarifies the significance of that distribution choice. Google positions Gemini Omni as filling gaps left by tools like OpenAI’s Sora while competing with ByteDance’s Seedance series, with the model accepting combinations of text, images up to five or more references, audio, and existing video clips and the key differentiator being that generative video output looks good for the first second and then falls apart when objects move naturally or scenes need logical continuity, which Omni is specifically designed to reduce.  

Every output of the Gemini Omni includes a watermarked SynthID embedded in the file, intended to authenticate its contents, given the level of authenticity required to create realistic videos at scale. The watermark created during the production of the video via Google’s SynthID system is not a logo or a removable metadata tag; it’s built directly into the video’s pixels at the time of production and is not visually detectable to human eyes but is detectable by Google’s authentication system. The authentication provided through this non-optimal layer will meet the requirements of any content governance provisionary tools that many enterprise customers may use to deploy physical video AI within regulated communications environments. 

Conclusion  

Gemini Omni has formally advanced physical video AI from pattern-matched visual approximation to world model physics simulation, establishing gravity, fluid dynamics, and kinetic momentum as internal architectural properties rather than emergent statistical patterns derived from training data. Google Flow delivers the conversational editing infrastructure that enables physics engine AI capabilities to reach YouTube creator tech professionals and enterprise video generation teams simultaneously, with free access through YouTube Shorts, ensuring that the production baseline for the world’s largest video platform shifts toward physics-aware generation within the current content cycle. The Google Gemini Omni Flash world model physics architecture that DeepMind CEO Demis Hassabis formally positioned as a step toward artificial general intelligence at Google I/O 2026 represents the most consequential advancement in generative video generation since the category emerged  not because it produces better looking output at launch, but because it models the physical world from first principles in a way that every subsequent generation of the Omni family will build upon.

Source: Introducing Gemini Omni 

REDMOND, WASHINGTON —  

The Azure Cobalt 100 from Microsoft represents Microsoft’s largest investment in securing architectural systems across all platforms since migrating from generic chips to using custom chips, which are designed specifically to provide hardware-level isolation, enable computing in secure enclave mode, and ensure that all data sovereignty is guaranteed through structural means rather than contractual commitments. The embedded security features associated with Microsoft Azure’s Cobalt 100 chip establish a zero-trust computing and storage cloud environment at the processor level, providing security below the OS and hypervisor levels – the primary levels of vulnerability for companies using the cloud for their enterprise computer network environments historically. For enterprise customers, government agencies, and industries subject to regulations that require a secure computing network and cloud environment, the Cobalt 100 provides the best evidence of security, with security statements embedded in the physical infrastructure of Microsoft Azure, rather than providing security through software layers placed on commodity computing and networking hardware. 

What the Azure Cobalt 100 Custom Silicon Architecture Delivers  

Cobalt 100, the first generation in the Azure Cobalt series, is a 64-bit 128-core chip that delivers up to 40 percent performance improvement over current generations of Azure ARM chips and powers services such as Microsoft Teams and Azure SQL. The 128-core configuration is not simply a throughput specification; it reflects a deliberate cloud architecture decision to maximize parallel workload density within the physical security boundary that custom silicon enables, allowing enterprises to run a greater number of isolated workloads on a single physical host without expanding the attack surface that shared infrastructure traditionally creates.  

Microsoft services such as Teams and Microsoft Defender Endpoint have seen up to 45 percent better performance on Cobalt 100 instances, and leading software vendors, including OneTrust and Databricks, have reported significant performance efficiency improvements alongside cost savings. The security and performance gains are not separate outcomes achieved through separate architectural choices; they are the combined product of purpose-built silicon that optimizes for the specific workload characteristics of enterprise cloud environments rather than adapting general-purpose server processors to cloud security requirements after the fact.  

How Secure Enclaves Enforce Zero Trust Cloud at the Hardware Layer  

The Microsoft Azure Cobalt silicon security features that most directly address enterprise security requirements operate through Trusted Execution Environments, the hardware-enforced isolation regions that the processor itself maintains independently of any software running on the system. These TEEs, referred to as secure enclaves, are cryptographically isolated from the rest of the system, including the operating system, the hypervisor, other applications, and even the cloud provider itself, with the processor hardware enforcing this isolation so that only authorized code running within the enclave can access the data.  

The practical impact of confidential computing for enterprise workloads is critical. Sensitive enterprise data processed in the secure enclave of Azure’s confidential computing service is encrypted while it is stored at rest and transmitted over networks, as well as while it is being computed. Azure confidential computing provides the capability to create enclaves that protect data during processing within the CPU by encrypting it and isolating it in memory, preventing access by the operating system, hypervisors running with escalated privileges, or Azure operators. This protects against attacks in which bad actors obtain elevated access to cloud infrastructure via compromised administrative credentials or hypervisor vulnerabilities; such attack vectors are not addressed by traditional encryption-at-rest and in-transit protections. 

Data Sovereignty and the Zero Trust Cloud Compliance Case  

Data sovereignty within the Azure Cobalt 100 architecture is enforced through the Sovereign Landing Zone framework that Microsoft has built around its confidential computing infrastructure. Azure Sovereign Public Cloud uses policy sets and the Sovereign Landing Zone to codify controls, such as service location and confidentiality options, so deployments can be configured and monitored consistently. Confidential computing provides attestation so workloads can verify TEE hardware and software measurements before releasing secrets or handling sensitive data.  

The attestation mechanism is the technical underpinning that provides the practical basis of data sovereignty guarantees. Before releasing sensitive data or processing regulated data in a secure enclave, a workload performs cryptographic verification of the hardware and software environment in which it operates, verifying that the execution environment is as expected and has not been tampered with by any entity, including the cloud operator. Azure’s approach reduces reliance on the trustworthiness of cloud providers and other privileged layers by enforcing hardware-based isolation and verification. Providing memory-encrypted compute via confidential VMs with attestation affords many workloads protection with little to no changes required in their source code. 

For government agencies, or regulated enterprises that must comply with national data localization requirements, this attestation functionality gives the organization the ability to demonstrate that their data is “in-scope” within the committed jurisdiction through auditable, verifiable means, enabling them to provide evidence to regulators or auditors that at no time did the organization’s data leave the authorized jurisdiction nor was it accessed by unauthorized parties while processed through the organization’s operations. 

What the Cobalt 200 Roadmap Signals for Enterprise Cloud Architecture  

At IgniAt Ignite 2025, Microsoft announced Cobalt 200, the next generation in-house-developed ARM processor for Azure VMs, featuring more cores, larger caches, and faster memory, built on the latest ARM architecture and 3nm TSMC process technology for better performance and efficiency balt 200 with 132 cores delivers up to 50 percent more performance than its predecessor, and the roadmap trajectory it establishes signals that Microsoft intends to advance custom silicon security capabilities alongside raw compute performance with each successive generation.  

Microsoft’s position in the custom-designed silicon ecosystem is further solidified by the competitive landscape surrounding that investment. Through its Graviton 4 processor, Amazon Web Services operates with similar levels of custom silicon at the same time as Google Cloud uses its Axon chip for its service, while Oracle’s Cloud Infrastructure uses Ampere Computing’s custom processors, making it clear that the development of custom-designed silicon has become an established norm in the architectural framework for secure architecture of hyperscale cloud infrastructure, rather than being merely a differentiating experiment by one vendor. The Azure Cobalt 100 and the roadmap to the Azure Cobalt 200 give Azure the advantage of being a robust provider of custom-designed silicon, with the distinction that Azure’s confidential computing implementations and zero-trust enhanced cloud security architecture are among the best-documented and compliance-validated solutions currently available in the enterprise cloud environment. 

Conclusion  

Azure Cobalt 100 has established custom silicon as the foundational layer, enabling zero-trust cloud enforcement as a hardware guarantee rather than a software policy, embedding secure enclaves, cryptographic attestation, and memory-isolated processing directly into the processor architecture that powers Azure virtual machines and containers. Data sovereignty within the Azure Cobalt 100 framework is enforced through Sovereign Landing Zone policy sets, hardware-rooted attestation, and Trusted Execution Environments that remain simultaneously cryptographically inaccessible to cloud operators, hypervisors, and operating systems. The Microsoft Azure Cobalt silicon security features that deliver 40 percent better performance than prior generation ARM instances, while providing hardware-level confidential computing capabilities, resolve the fundamental tension that enterprise cloud adoption has historically faced: the requirement to choose between the performance and economics of public cloud infrastructure and the security assurances that regulated industries and government agencies are required by law to maintain.

Source: Microsoft Latest news 

NEW YORK, NEW YORK — 

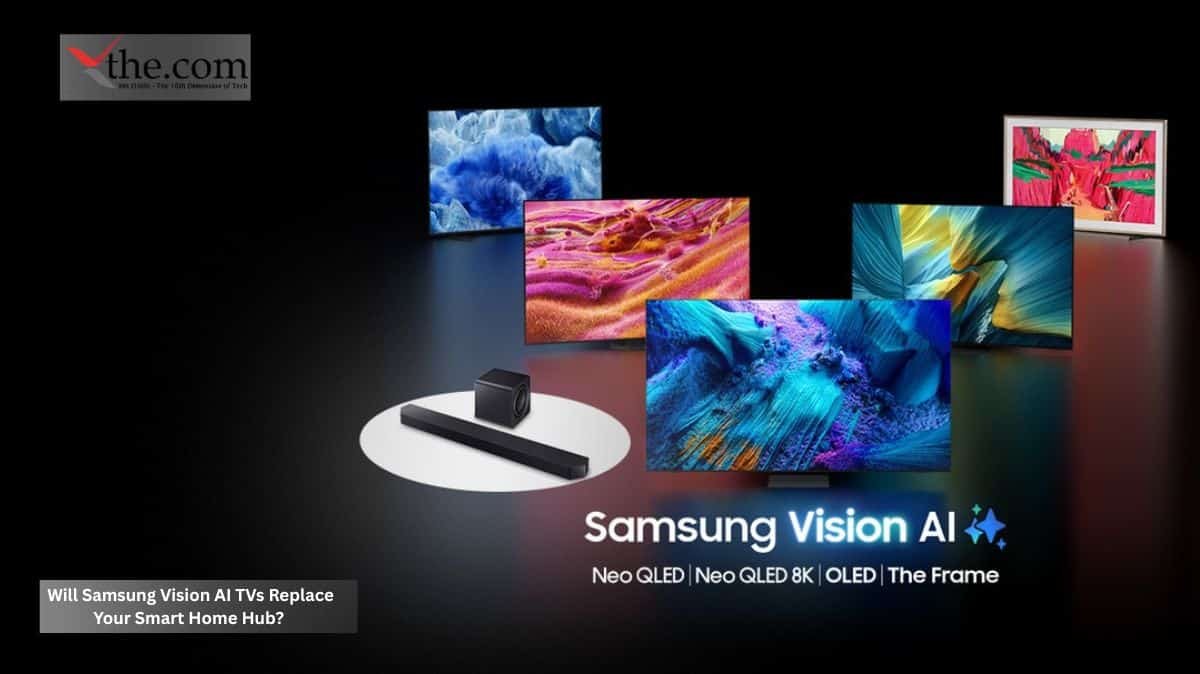
Samsung Vision AI is no longer simply a television feature; it is a full platform bid to become the primary intelligence layer of the modern American home. The 2026 Samsung Vision AI Companion TV lineup, anchored by the flagship Micro RGB TV series and extending across OLED, Neo QLED, and Mini LED models, integrates Bixby, Perplexity, and Microsoft Copilot directly into a single screen that simultaneously manages entertainment, answers questions, controls connected appliances, and coordinates smart home devices through SmartThings positioning Samsung’s premium television lineup as the most serious challenge to Amazon Alexa and Google Nest hubs that the consumer electronics market has seen in a decade. 

What the Vision AI Companion Platform Actually Delivers  

Vision AI Companion brings together Samsung’s broadest range of AI service platforms, including Bixby, Perplexity, and Microsoft Copilot, to make the TV experience more intelligent and personalized, designed to work alongside users as an entertainment companion that can help guide what to watch, what to eat, and what to listen to, extending the role of the TV beyond viewing alone.  

The three AI platforms embedded in the Vision AI Companion architecture serve distinct functions that, together, cover the full scope of what a household information hub is expected to do. Bixby handles conversational interaction and smart home control through natural language commands. Perplexity delivers deep search and research capabilities directly on-screen without requiring the viewer to open a separate browser or device. Microsoft Copilot and Perplexity are also available as separate apps, giving viewers yet another way to engage with their television as an intelligence platform. The combined effect is a television that functions as simultaneously an entertainment display, a research terminal, a smart home controller, and a productivity assistant, all accessible without leaving the couch.  

Samsung Micro RGB TV and the Display Technology Foundation  

Samsung’s Micro RGB TV lineup is the crowning achievement of Samsung’s 2026 investment in display technology, and it serves as the hardware platform on which the Vision AI Companion delivers its highest performance. The R95H and R85H Micro RGB series use the Vision AI Companion paired with the Micro RGB AI Engine Pro, which optimizes color, motion, and depth, and the Micro RGB Precision Color 100, which produces richer, more lifelike colors. The televisions will also feature the Micro RGB Color Booster Pro and the Micro RGB HDR Pro, which optimize colors and contrast on a scene-by-scene basis. 

The display intelligence embedded in the Micro RGB TV architecture will use AI Upscaling Pro technology, which has been one of the most frustrating parts of owning a modern TV. AI Upscaling Pro uses artificial intelligence to analyze and upscale low-resolution content, adding greater detail, depth, and contrast in real time. In addition, Color Booster Pro uses color categories to analyze the content of individual frames, resulting in vibrant, lifelike colors. This means that for consumers who subscribe to streaming services, the lower-resolution content of older movies and shows will be improved to match the visual quality of natively produced new content.  

Neo QLED, AI Upscaling Pro, and the Broader Consumer Electronics Rollout  

Samsung’s Vision AI Companion TVs are much broader than the flagship Micro RGB TVs. They are now available for mainstream consumers in Neo QLED and Mini LED form factors. The Neo QLED QN70H is offered in sizes from 55 to 85 inches (140cm to 215cm). These TVs feature Real QLED technology to deliver 100% Color Volume and accurate color and clear detail even in brightly lit environments, and Quantum Mini LED technology that provides both depth and clarity in all scenes. The Neo QLED QN70H also features Vision AI Companion Technology, 4K Upscaling, and a 144Hz refresh rate, powered by the New NQ4 AI Processor. 

The breadth of the 2026 rollout 72 models spanning Micro RGB TV, OLED, Neo QLED, Mini LED, and Crystal UHD configurations reflects Samsung’s strategic determination to embed Samsung Vision AI capability at every price point rather than confining it to flagship hardware accessible only to premium buyers. Samsung is extending Vision AI Companion features across its TV lineup in 2026, offering AI-powered viewing experiences across more categories and screen sizes to meet the demands of consumers looking beyond exceptional picture quality and sound.  

The Smart Home Center Question  

The most consequential strategic question the 2026 lineup raises for consumers and investors is whether a Samsung Vision AI television can functionally replace the dedicated smart home hub that currently occupies a shelf or counter in millions of American households. The Vision AI Companion transforms Samsung TVs into interactive smart home hubs that respond to on-screen content in real time, from suggesting recipes to assisting travel planning, with Samsung positioning itself against Amazon Alexa Care Hub and Google Nest in the projected $174 billion smart home market.  

The technical infrastructure supporting that ambition is already deployed at scale. SmartThings now fully supports Matter 1.3, the new standard that unifies all smart home ecosystems, meaning consumers can use Matter devices from any manufacturer, including Apple, Google, Amazon, and IKEA, without restrictions, with Samsung supporting Matter over Thread and Matter over WiFi. As of December 2025, SmartThings serves more than 430 million users a user base that gives Samsung the ecosystem depth and behavioral data that competing smart home platforms have not yet matched. Samsung Vision AI Companion lets viewers ask their TV anything and get instant, personalized answers, whether about a scene playing on screen, ideas for dinner, or help planning an upcoming trip. The platform is supported for up to 7 years of OS updates, ensuring continued access to the latest apps and services.  

Conclusion 

Samsung Vision AI has formally expanded the definition of what a television is expected to do in 2026, and the Samsung Vision AI Companion TV lineup features that the Micro RGB TV, Neo QLED, OLED, and Mini LED models deliver collectively, making the case that the living room screen is the most natural location for a Smart Home Center to operate from. AI Upscaling Pro, Color Booster Pro, and the multi-agent Bixby, Perplexity, and Microsoft Copilot platform address picture quality, information access, and smart home control simultaneously through a single interface that 430 million SmartThings users are already equipped to adopt. Whether Samsung Vision AI fully replaces the dedicated smart home hub depends on how much of the household’s connected device management consumers are willing to anchor to a screen, but the 2026 lineup makes a stronger argument for that transition than any consumer electronics platform has previously assembled.

Source: Samsung Newsroom 

Austin, Texas 

There has been an exponential increase in size, complexity, and energy consumption due to AI. Companies that develop intelligent systems need substantial computing power to run large datasets continuously without overheating. 

Modern cooling systems can’t manage such extreme temperatures generated by the new generation of intelligent computer hardware. 

To solve this problem, companies have had to completely reconsider the construction of data centers. 

Dell is tackling this problem head-on with its growing Dell AI Factory, which focuses on designing large-scale AI systems for today’s companies, cloud platforms, and intensive computing. 

It sees AI growth transforming data center design in the future. 

How the Dell AI Factory Systems Operate 

The Dell AI Factory system integrates powerful servers, AI-friendly networking, advanced cooling, and management software to deliver scalable infrastructure. 

This type of technology solution is designed for businesses that want to run their AI workloads at enterprise scale. 

Also, Dell is currently emphasizing automation in order to simplify the operation of increasingly complex computing environments. 

Dell thinks that future enterprises will require infrastructure capable of supporting AI training, analytics, cloud, and automation simultaneously. 

Components found in Dell’s AI Infrastructure solution include: 

  • High density AI server setups 
  • Advanced cooling and thermal management capabilities 
  • AI networking systems 
  • Cloud integration systems for enterprises 
  • A scalable hardware architecture 

Dell aims to become the go-to infrastructure provider for the age of AI. 

Why Liquid Cooling Has Become Critical 

The biggest transition in the construction of current data centers is the growing importance of Liquid Cooled Server technology. 

Traditional cooling solutions depend largely on fans and airflow to cool the processor and GPUs. Nevertheless, in terms of thermal generation, the hardware used in artificial intelligence today has reached an extremely high level, making air cooling no longer sufficient. 

The use of liquids enables greater heat removal, thus increasing the computing power of the server. 

Liquid cooling is essential when deploying large numbers of GPUs for performing AI operations. 

Advantages of Liquid-cooled Infrastructure for Artificial Intelligence 

  • Effective heat removal for powerful hardware 
  • Greater energy efficiency in data centers 
  • Lower cooling costs in operation 
  • Greater computing density 
  • More stable performance during high loads 

According to industry experts, liquid cooling could become a common practice in advanced AI facilities. 

Reasons Why Companies are Investing Billions into Infrastructure 

The competition around artificial intelligence has sparked a wave of exponential growth in enterprise tech spending globally. 

Finance, healthcare, manufacturing, cybersecurity, and cloud companies have invested heavily in AI infrastructures to stay ahead of the competition. 

This trend has led to significant growth in capital expenditures in the technology industry. 

Organizations have stopped purchasing servers merely for storage or regular application usage. Instead, enterprises now require infrastructure optimized specifically for AI applications. 

Dell hopes that through this infrastructure expansion, they can become one of the main beneficiaries of this expenditure. 

How Dell PowerEdge Servers Contribute to This Strategy 

The Dell PowerEdge server family is crucial in Dell’s AI infrastructure approach. 

These servers are used by enterprises to perform AI workloads, improve scalability, enhance security, and increase reliability inside data centers. 

Dell is incorporating more AI optimization technologies into its servers to improve performance. 

Thus, organizations using Dell servers do not need to build a new infrastructure to run sophisticated AI programs. 

Expected Industries to Increase AI Infrastructure Investments 

  • Cloud computing companies 
  • Banks and financial institutions 
  • Healthcare and pharmaceutical companies 
  • Manufacturing companies 
  • AI and software developers 

The rise in AI systems has raised concerns about electricity use and its environmental effects. 

Such systems consume large amounts of energy, which might strain local utilities and increase operational expenses. 

This is why it is vital for companies to focus on energy-efficient cooling and infrastructure designs. 

The term “Dell AI factory liquid cooled server cost” has gained attention recently since people wonder if it is worth spending so much money initially for higher efficiency in the long run 

Many firms have found it essential to weigh the balance between high-performance computing and environmental concerns. 

Why Is There An Interest In AI Infrastructure Among Investors? Why Is There An Interest In AI Infrastructure Among Investors? 

The AI infrastructure market has become one of the industries in global technology markets attracting significant investor attention today. 

They know that any significant AI system requires certain components to be installed and working effectively behind the scenes. 

Reasons for market interest in AI infrastructure 

  • Demand for enterprise AI keeps growing fast 
  • Rapid expansion of data centers worldwide 
  • Special hardware systems are required for AI 
  • Cloud vendors increase their infrastructure spending 
  • Fast-growing markets for cooling technologies 

The corporate hardware sector is undergoing a transformation based on the needs of AI computing. 

Conclusion 

The growth of Dell’s AI factory demonstrates the evolution of artificial intelligence towards its use in the hardware aspect of enterprise computing. With new server architectures, advanced cooling solutions, and scalable infrastructure platforms, Dell is placing itself right where it belongs – at the heart of the burgeoning AI industry. As businesses increasingly use AI, effective infrastructure systems may prove to be a key competitive advantage in the years to come.

Source- Dell Press 

Seattle, Washington 

For many years, online shopping has been based on elements such as search boxes, filters, customer ratings, and scrolling through millions of products. People may easily waste hours looking for the required item and studying various specifications and ratings. 

However, artificial intelligence is starting to change the shopping process and, most likely, make it much easier. 

In place of having customers search through millions of products, the use of systems that can understand natural language and provide individual recommendations is a growing trend in the industry. 

In this context, Amazon Rufus becomes an absolutely crucial innovation in the realm of digital commerce. 

Indeed, the artificial intelligence-powered shopping assistance is designed to help consumers find what they need in a conversational way. 

What Amazon Rufus Really Does 

Rufus is an AI Shopping Assistant integrated into Amazon’s shopping ecosystem. Rather than entering search terms in search engines, customers can make inquiries. 

For instance, one may be interested in finding the perfect laptop for college, face creams suitable for sensitive skin, and gadgets for small kitchens. 

The technology analyzes customer reviews, product specifications, product descriptions, and shopping trends to generate recommendations. 

Features enhancing the shopping experience with Rufus 

  • Product recommendations via a conversational interface 
  • Comprehensive AI comparisons of similar products 
  • Customer-oriented shopping recommendations 
  • Ease of identifying specialized products 
  • Simplification of the consumer decision-making process 

This is why Amazon is seeking to transform the shopping experience from a typical online buying experience to something akin to interacting with a personal shopping assistant. 

Why Do People Need Such Systems? 

Modern e-commerce platforms have millions of products vying for attention. Consumers find it increasingly hard to make decisions due to information overload. 

“Choice overload” is a term used to describe the modern situation in which consumers become confused by the abundance of available products. 

AI-based shopping systems are therefore intended to alleviate some of the frustrations consumers experience. 

However, retailers have already utilized the recommendation engine concept for quite some time. Yet, Personalized AI goes far beyond this basic concept by incorporating a broader range of contextual insights, such as intent recognition, conversational analysis, need-based shopping, and behavioral analysis. 

As a result, a completely new level of automation is being developed, relying on recommendation engines and predictive shopping algorithms. 

Competition to control consumer personalization emerges. 

How AI personalization changes e-commerce 

  • Enhanced recommendations that reflect users’ real-life needs 
  • Faster product discovery for buyers 
  • Less time required for comparing offers 
  • Improved product matching for shoppers 
  • More conversational experience of online shopping 

For retailers, the ability to personalize online commerce can be an effective way to engage customers and streamline their purchase experience. 

Why Smart Retail Is Gaining Momentum As A Key BattlefrontWhy Smart Retail Is Gaining Momentum As A Key Battlefront 

The retail industry is becoming increasingly product-discovery-intensive as recommendation engines greatly influence purchasing behavior. 

The sheer size of Amazon’s market allows the system to accumulate tremendous amounts of data about online shoppers, their preferences, and behavior. 

The rapid growth of Smart Retail systems is also pushing major retailers to invest heavily in AI-driven customer engagement tools. 

Risks Associated with AI in E-commerce 

Even as AI shopping is hailed as the future of retail, numerous experts are sounding the alarm bells regarding how recommendation engines could affect consumer behavior. 

AI recommendations may be biased toward larger brands or higher-margin products, rather than being purely impartial. 

AI recommendations will make it difficult for independent retailers, who may lose out as algorithms favor market leaders. 

  • Algorithmic bias in recommendation algorithms 
  • Less visibility for small independent companies 
  • Influencing consumer choices through AI recommendations 
  • Overreliance on AI technology managed by the platform 
  • Lack of transparency in determining product ranking 

In the coming years, controversies revolving around fairness and visibility in AI-powered recommendations will only become more pronounced. 

AI-based shopping assistants are just one of a series of E-commerce trends currently transforming online retail. 

Today’s consumers demand instant access to information, quick responses to their questions, and easy online shopping. 

The old method of search-based shopping is set to be replaced by AI shopping assistants as consumers increasingly embrace the technology. 

How Rufus Could Change Consumers’ Shopping Behavior 

The introduction of AI into that ecosystem would have a great impact on the consumer buying process and decisions. 

This particular term, “Amazon Rufus assistant features USA rollout,” is relevant because it shows how quickly conversational AI is gaining traction. 

Instead of manually searching for products, customers can rely more on AI-powered recommendations. 

Areas where Rufus could affect shoppers 

  • Comparing and researching products 
  • Purchasing products for personal use 
  • Shopping for electronics and gadgets 
  • Assistance during gift shopping 
  • Lifestyle-based product recommendations 

By implementing an AI system in their business, retailers are taking a big step towards changing the way products are searched for, using dynamic assistance rather than catalogs. 

The rise of AI-driven shopping systems is also reshaping the future of Consumer Tech experiences across digital marketplaces. 

Conclusion 

Rufus Amazon shows that technology and artificial intelligence will change the way we shop and discover products online in the future. By integrating conversational search, personalized retail recommendations, and AI-powered assistance for product discovery and comparisons, Amazon aims to make online shopping easier and less stressful for customers.

Source- Amazon Press