NEW DELHI, INDIA — 

Atomic Answer: Amazon (AMZN) has rolled out its updated Lens AI image search engine alongside its Rufus shopping assistant, introducing advanced look-matching tools to its expanding premium product market. The tool maps product images locally on consumer devices to instantly identify and recommend premium matches without requiring manual text search entries. This personal computing feature reshapes mobile shopping by turning simple photos into direct purchase options, accelerating checkout times while significantly boosting order discovery beyond major tech hubs.  

The Amazon Lens AI image search Rufus shopping 2026 rollout reframes mobile commerce discovery from keyword-dependent text search to visual intent recognition, meeting consumers at the moment of inspiration rather than requiring them to translate visual desire into search vocabulary. As Amazon’s visual product discovery mobile checkout AI converts photographs into purchase pathways without manual text entry, and Amazon Lens premium store image match recommendation extends this capability into premium beauty and personal care categories, brand sellers who have not optimized product catalog imagery for visual search indexing are invisible to a discovery channel that increasingly drives high-value order completions. 

Why Visual Search Disrupts Text-Based Product Discovery 

Amazon visual product discovery mobile checkout AI addresses the translation friction that text search imposes on visually-driven purchase intent  a consumer who photographs a beauty product on a friend, in a magazine, or at a retail counter cannot always translate what they see into the keyword combination that returns the right product in a text search. The gap between visual inspiration and text search vocabulary has historically been where purchase intent dissipates, leading to abandoned search sessions and missed high-value transactions.  

With visual inputs alone through the new Amazon Lens, based on a person’s device, visual images can be used to locate a product’s features like color, texture, and packaging design without the user needing to provide any description in writing. Using the same device, Amazon’s Rufus shopping assistant can filter visual search results by price range, brand, or ingredient profile for consumers. 

Amazon Lens premium store image match recommendation capability in premium beauty categories specifically addresses the high-value segment where visual fidelity matters most  luxury and prestige beauty consumers who make purchase decisions based on formulation, packaging design, and brand presentation signals that text descriptions cannot fully convey the benefit of most from visual search that evaluates those signals directly. 

How On-Device Image Mapping Works 

How does Amazon Lens AI image search engine work with Rufus shopping assistant to convert consumer photos into direct product purchase recommendations without manual text search is answered by the local processing architecture that on-device image mapping enables  visual feature extraction that occurs on the consumer’s device before network transmission reduces the round-trip latency that cloud-only image processing would introduce into the visual search response time that mobile checkout conversion requires.  

Amazon Lens catalog image format search indexes visual feature vectors extracted from consumer photos against the product catalog’s indexed image feature database  matching color profiles, texture signatures, shape characteristics, and design element patterns to identify the specific product or the closest available catalog equivalent. Amazon image search consumer buying pattern analytics generated from visual search sessions provide the behavioral data that catalog optimization and inventory positioning decisions require identifying which product categories generate the highest visual search volume relative to text search volume reveals where catalog image quality investment delivers the highest discovery revenue return.  

The mobile shopping assistant for Amazon Rufus product discovery will identify the best option to purchase after you identify your ideal image by refining your search using visual attributes. However, a visual search alone will not lead to completing the sale without additional information on price, available stock, experience rating, and perhaps other alternatives. By providing this information along with the photo you used for visual searching, Amazon Rufus makes it easier than ever to buy impulse items based on what you’ve found using visual matching and to have them shipped quickly. 

Catalog Image Optimization for Visual Search Indexing 

Why should brand sellers optimize product catalog image formats for Amazon Lens AI indexing to capture higher order discovery values driven by automated visual recommendations in 2026 is answered by the indexing quality dependency that visual search accuracy creates  catalog images that capture the visual feature signals that Lens AI extracts for matching will return as accurate visual search recommendations, while images that obscure product characteristics through poor lighting, cluttered backgrounds, or low resolution will either not index accurately or return as low-confidence matches that Rufus deprioritizes in recommendation ranking.  

Amazon Lens catalog image format search indexing optimization requires product catalog images that expose the visual features consumer photography captures  primary product views that show packaging design, color, and texture under neutral lighting conditions that match the ambient lighting consumer device cameras produce in typical use environments. Studio images optimized for text search thumbnail display that use dramatic lighting, heavy post-processing, or heavily stylized backgrounds may not match consumer photographs of the same product under natural lighting.  

Amazon image search consumer buying pattern analytics from optimized catalog images provides the performance data that brand sellers need to validate indexing quality visual search impression rates and click-through rates that increase after catalog image optimization confirm that the updated images are indexing accurately and returning as relevant visual search recommendations. 

Inventory Synchronization and Supply Chain Response 

Amazon visual product discovery, mobile checkout, AI demand generation, and inventory velocity patterns that differ from text search demand  visual search discovery surfaces products that consumers were not actively searching for, generating demand spikes for catalog items that inventory systems provisioned for predictable text search demand levels may not anticipate.  

Amazon Rufus shopping assistant product discovery mobile recommendation patterns that concentrate discovery traffic on specific SKUs within a catalog require local inventory system synchronization that adapts supply counts to changing search trends driven by automated recommendations  brands whose inventory management systems operate on historical text search demand patterns will encounter stockout events on visually discovered products that demand forecasting did not anticipate.  

Amazon Lens premium store image match recommendation traffic concentration in premium beauty categories reflects the high average order value that visual search drives in prestige product segments  inventory investment in premium SKUs that visual search discovery surfaces generates higher revenue per unit of inventory commitment than commodity SKUs that text search price comparison commoditizes. 

Privacy Compliance and Consumer Browsing Metrics 

Amazon Lens AI image search Rufus shopping 2026 device-local image processing architecture reduces the personal data transmission that cloud-only image search would require  visual feature extraction that occurs on-device before network transmission limits the consumer biometric and environmental data that image processing might capture to the local device rather than transmitting raw imagery to cloud infrastructure.  

Amazon image search consumer buying pattern analytics that brand sellers access through Amazon’s seller analytics platform must be evaluated against corporate data protection rules and regional privacy frameworks  India’s Digital Personal Data Protection Act requirements that govern consumer behavioral data collection and processing apply to the analytics that Amazon provides to brand sellers alongside the discovery traffic that visual search generates.  

Digital storefront link configuration that handles incoming traffic from image search tools smoothly requires technical validation that product detail pages load completely on the mobile browsers and app environments that visual search referral traffic arrives through  page load failures or incomplete rendering that only affects visual search referral sessions create conversion losses that standard desktop browser testing does not surface. 

Conclusion 

The Amazon Lens AI image search Rufus shopping 2026 platform converts visual purchase intent into checkout velocity without the text search translation friction that has historically caused high-value discovery moments to dissipate before purchase completion. Amazon’s visual product discovery mobile checkout AI creates a discovery channel that brand sellers cannot participate in effectively without the catalog-image optimization that Amazon Lens requires for its catalog-image-format search indexing.  

Amazon Lens premium store image match recommendations concentrate in premium beauty categories, driving high average order values that inventory synchronization and supply chain responsiveness must accommodate to capture the revenue visual discovery generates. Amazon Rufus shopping assistant product discovery mobile conversational refinement closes the gap between visual match and informed purchase decision that raw image search results alone leave open. Amazon image search consumer buying pattern analytics provide the performance data that catalog optimization, investment, and inventory positioning decisions require to maximize visual search revenue capture. As how does Amazon Lens AI image search engine work with Rufus to convert consumer photos into direct product purchase recommendations defines the discovery mechanism, and why should brand sellers optimize product catalog image formats for Amazon Lens AI indexing to capture higher order discovery values defines the seller action, the text search vocabulary barrier that has historically limited premium beauty discovery has a visual search resolution that on-device image mapping makes instantaneous. 

Enterprise Procurement Checklist 

  • Audit: Review online brand assets to ensure product catalog images are formatted for optimal Amazon Lens AI indexing. 
  • Sync: Align local inventory systems to adapt supply counts to visual search-driven recommendation demand changes. 
  • Configure: Update digital storefront links to handle incoming image search referral traffic without friction. 
  • Check: Verify customer browsing metrics comply with corporate data protection rules and regional privacy frameworks. 
  • Review: Track quarterly sales fluctuations to measure direct revenue impact from automated product discovery features. 

Primary Source Link: indiatimes.net 
SEATTLE, WA — 

Atomic Answer: Microsoft (MSFT) has expanded its open-source Azure Linux operating system offerings at North American development summits, targeting lower host system computing overhead across massive server networks. The immutable container architecture strips out non-essential software packages to reduce security exposure while dramatically speeding up individual cluster launches. This update provides cloud administrators with a highly optimized foundation that drops operational spending by reducing unnecessary background processor usage.  

The Microsoft Azure Linux Open Source Container OS 2026 Expansion will also reduce the operational overhead that General Purpose (GP) Linux Distributions create with software bloat on container workloads  and Re-Use cannot use any of the background processes, package managers, or system utilities that GP OS Design is able to use due to Administrative Flexibility but Azure Linux Immutable Host Zero Trust Infrastructure has been designed to remove as these are not necessary, therefore, reducing attack surface and compute waste, while the overall cost of launching an Azure Linux cluster continues to reduce as the costs of launching an Azure Linux cluster continues to drive down Infrastructure Spending due to the Minimal OS Architecture to where the Procurement Justifiable Migration from previously could be an experimental optimization becomes now through procuring an Azure Linux Cluster now will save on overall Infrastructure Spending Vs before/previously. 

Why General-Purpose Linux Creates Container Overhead 

Azure Linux non-essential package removal to reduce security exposure starts with understanding which general-purpose distributions include components that container workloads never use. Standard Linux distributions designed for interactive server administration include package managers, system logging daemons, network diagnostic tools, compilers, and dozens of background services that container orchestration environments have no operational requirement for  but that execute on every host node, consuming CPU cycles, memory allocation, and attack surface that security frameworks must defend against.  

Azure Linux immutable container background processor cut removes this overhead at the OS design level rather than through post-installation package removal an immutable architecture that ships only the software components container execution requires means background processor utilization by general-purpose OS daemons is structurally absent rather than present but disabled. Microsoft Azure Linux open-source container OS 2026 cluster environments, where hundreds of nodes each eliminate background process overhead and achieve the aggregate CPU and memory reductions required for meaningful infrastructure cost savings.  

Azure Linux cluster launch speed cost reduction from package minimization reflects the reduced initialization work that minimal OS startup performs  nodes that launch without initializing unused services, loading unnecessary kernel modules, or executing package manager startup routines reach container-ready state faster than general-purpose OS nodes that complete a full service initialization sequence before workloads can execute. 

Immutable Architecture and Security Exposure Reduction 

How Microsoft Azure Linux’s immutable container architecture strips non-essential software packages to shrink security exposures and speed up cluster launch times in 2026 is answered by the security consequence of OS immutability  a host OS that cannot be modified after deployment cannot be compromised through the package installation, configuration modification, or binary replacement attack vectors that mutable OS architectures expose.  

Azure Linux immutable-host, zero-trust infrastructure enforcement means that the attack-surface reduction from package removal is permanent an attacker who gains partial access to an immutable Azure Linux host cannot install additional tooling, modify system binaries, or establish persistence through OS-layer changes that security monitoring might miss. The immutable OS design reduces the post-compromise capabilities attackers depend on for lateral movement, making Azure Linux nodes structurally more resistant to persistence techniques that general-purpose, mutable OSes enable.  

Removing non-essential Linux packages on Azure reduces security exposure by quantifying CVE surface reduction  each removed package eliminates the vulnerability surface represented by its CVE history. General-purpose Linux distributions that include hundreds of packages that container workloads never invoke carry CVE exposure for every included package, requiring security teams to track and patch vulnerabilities in software that the workload never uses. A minimal OS architecture eliminates this tracking and patching overhead, along with the vulnerability exposure itself. 

Federal Zero-Trust Compliance Architecture 

Azure Linux federal zero-trust data protection compliance alignment reflects the immutable OS architecture’s structural compatibility with zero-trust principles mandated by federal deployment requirements an OS that cannot be modified by processes running on it enforces a system integrity guarantee that mutable OS architectures cannot provide without additional integrity monitoring infrastructure.  

Why should cloud administrators switch to Microsoft Azure Linux as the standard base for all container networks to reduce unnecessary background processor costs and meet federal zero-trust requirements is answered by the compliance architecture efficiency that immutable OS design provides federal zero-trust mandates that require demonstrable OS integrity assurance are satisfied structurally by immutable architecture rather than through continuous integrity monitoring overlay that mutable OS deployments require to achieve equivalent assurance.  

Azure Linux immutable-host zero-trust infrastructure federal compliance documentation is therefore simpler than equivalent mutable OS compliance documentation  the immutable design provides categorical integrity assurance that audit frameworks accept as stronger evidence than monitoring-based integrity detection that identifies violations after they occur rather than preventing them architecturally. 

Automated Patching for Immutable Host Infrastructure 

Azure Linux immutable container background processor cut operational model requires automated update routines that replace entire immutable OS images rather than applying incremental patches to running systems  the patching model that mutable OS administration uses cannot be applied to immutable hosts, where the running OS cannot be modified.  

Microsoft Azure Linux open-source container OS 2026 automated update architecture replaces running immutable host images with updated images through node rotation  workloads migrate to new nodes running the updated OS image while old nodes are decommissioned, providing patch deployment without the workload disruption that in-place patching on mutable OS hosts requires, and without the maintenance windows required by in-place patching on mutable OS hosts.  

Azure Linux cluster launch speed cost reduction from rapid node initialization compounds the automated update efficiency  the fast cluster launch speed that minimal OS architecture provides accelerates the node rotation cycles that immutable OS patching requires, reducing the time that automated update routines consume from the operational schedule and the infrastructure capacity that node rotation temporarily requires. 

Application Compatibility Validation 

Removing non-essential Linux packages in Azure Linux reduces security exposure, but requires application compatibility validation before production migration  containerized applications with undocumented dependencies on OS-level packages Azure Linux removes will encounter runtime failures that compatibility testing identifies before they occur in production.  

Azure Linux cluster launch speed and cost reduction from a minimal OS baseline are realized only after application images are validated against the minimized system layer  images that include compatibility shims for packages the general-purpose OS provides, but Azure Linux omits the compatibility layer overhead that defeats the background process elimination it delivers.  

Azure Linux federal zero-trust data protection compliance validation for migrated workloads should confirm that application behavior under immutable OS constraints matches security policy requirements applications that require OS-level write access for logging, temporary file creation, or configuration modification may require architectural adjustment before immutable OS deployment achieves the compliance posture that federal zero-trust requirements mandate. 

Conclusion 

The Microsoft Azure Linux open-source container OS 2026 expansion delivers Azure Linux cluster launch speed, cost reduction, and reduced security exposure through an immutable, minimal OS architecture that eliminates the general-purpose OS overhead container workloads carry without benefit. Azure Linux non-essential package removal reduces security exposure permanently through an immutable design, rather than relying on post-compromise monitoring to detect modifications after they occur.  

Azure Linux immutable host zero-trust infrastructure provides a federal zero-trust compliance architecture that an immutable design satisfies categorically, rather than through a monitoring overlay that mutable OS deployments require. Azure Linux immutable container background processor spans large container node fleets, delivering the aggregate CPU and memory savings required for meaningful infrastructure cost reduction at cloud operational scale. Azure Linux federal zero-trust data protection compliance documentation efficiency reduces the audit overhead required by mutable OS integrity assurance. Application compatibility validation before production migration ensures that Azure Linux cluster launch speed and cost reductions are captured cleanly, rather than offset by compatibility-layer overhead. As how does Microsoft Azure Linux immutable container architecture strip non-essential software packages to shrink security exposures and speed up cluster launch times defines the technical value, and why should cloud administrators switch to Microsoft Azure Linux as the standard base for all container networks to reduce background processor costs and meet federal zero-trust requirements defines the migration case, the general-purpose OS overhead that container infrastructure has historically carried has a minimal immutable alternative that security, performance, and compliance requirements all simultaneously support. 

Enterprise Procurement Checklist 

  • Update: Adopt Microsoft Azure Linux as the standard base OS for all new container network deployments. 
  • Test: Validate current application images for complete compatibility with the minimized Linux system layer. 
  • Set up: Configure automated image rotation routines to push OS patches across immutable hosts without disrupting active workloads. 
  • Verify: Confirm system deployment blueprints comply with updated federal zero-trust data protection rules. 
  • Measure: Calculate cluster resource cost reduction to document ROI for IT infrastructure budget justification. 

Primary Source Link: Microsoft News 

Source: Microsoft Source Newsroom / Azure Linux Documentation 

Bozeman, MT.  

Atomic answer: Snowflake’s (SNOW) new data engine utilizes zero-copy federation to let analytical applications scan external database files directly without creating expensive duplicate copies. This setup removes the need to maintain complex data-moving pipelines, lowering cloud storage costs across multiple platform environments. By pulling information straight from its original storage location, companies can run large data analysis jobs quickly while avoiding duplicate storage fees.  

A multinational retailer found that almost 38% of its annual cloud analytics costs stem from duplicate datasets across three major cloud providers. Finance blamed engineering, and engineering pointed the finger at governance policies. At the same time, reporting pipelines slowed down due to the extra storage. This situation shows why Snowflake zero‑copy federation is now a key part of modern data cloud migration strategies.  

Companies now face a new challenge: not just moving data, but also paying for it repeatedly.  

Why Cloud Storage Duplication Became a Budget Problem 

For years, companies copied data between regions, warehouses, and analytics systems because there were few other options due to latency and compatibility issues. This led to large, complex infrastructures that drove up storage costs, computing needs, and administrative work. Now, many organizations are feeling a new wave of cloud cost pressure, especially from AI workloads and analytics across different platforms.  

This pressure has grown with the rise of agentic data clouds, where AI systems constantly access operational, financial, and customer data. Each duplicate table incurs ongoing costs, and each additional data transfer incurs an additional charge.  

Snowflake Zero-Copy Federation helps change this cost dynamic.  

Instead of copying datasets across environments, Snowflake lets organizations use shared data without creating extra copies. This setup reduces storage waste while maintaining governance, tracking, and access controls.  

The benefits show up right away. With less copied data, storage costs are lower, fewer sync tasks are required, and fewer mismatches between environments occur.  

How Snowflake Zero Copy Federation Works in Practice 

Traditional federation systems often create hidden copies of data in the background. Snowflake takes a different approach by using metadata-driven access and centralized governance.  

With Snowflake zero-copy federation, teams can share datasets across departments, clouds, and regions while maintaining a single source of truth. The platform points to existing storage rather than creating new copies.  

Take a healthcare provider running analytics on both AWS and Azure. Before using federation, the company kept copies of patient analytics data in both places to support regional AI acts. This caused monthly storage costs to rise and made compliance audits harder.  

After switching to Snowflake’s zero-copy federation, the organization reduced duplicate storage by almost 42% over the course of a year. Audit prep time also decreased because governance remained centralized rather than being spread across different copies.  

This is important for CFOs managing infrastructure budgeting. Storage costs often grow faster than expected. As companies scale up AI, duplicate datasets can multiply rapidly across training, testing, and analytics systems.  

The Connection Between Federation and Enterprise AI 

AI costs are now a big topic in boardrooms. Leaders want clear results, not just experimental spending.  

The link between enterprise AI ROI and data architecture is now clear. Tools such as large language models, recommendation systems, and predictive analytics require steady access to structured data. If that data exists in many copies, AI costs add up fast.  

A federated setup helps reduce this waste.  

Even more centralized governance makes data more reliable. AI systems do worse when teams use different versions of the same data. Business data organizations are now a financial benefit, not just a technical choice.  

Snowflake’s approach also aligns with broader enterprise migration goals. Many organizations pursuing data cloud migration initiatives want portability across cloud providers without maintaining several parallel storage environments. Federation provides that flexibility while limiting infrastructure sprawl.  

Why CIOs Are Prioritizing Cloud Migration Reduction 

Over the past decade, tech leaders moved workloads to the cloud as quickly as possible. Now, many are shifting focus to cutting back on unnecessary migrations.  

This shift towards reduced cloud migration indicates increasing skepticism about excessive data movement. Each transfer causes latency risks, governance complications, and additional fees. Companies increasingly prefer architectures that limit movement while increasing accessibility.  

This trend is growing across financial services, manufacturing, and telecom, where large data sets often flow between AI tools and reporting systems. Raising the benchmark for success is no longer about how much data moved. Instead, executives ask a more financially disciplined question: how little movement is necessary?  

This way of thinking is driving greater interest in long-term deployment models like Snowflake Horizon’s zero-copy federation deployment cost for 2026. Companies now considering future cloud strategies consider not just short‑term storage savings, but also long‑term governance, AI growth, and compliance costs associated with federated setups.  

Governance And Cost Efficiency Now Move Together 

In the past, tech buyers targeted governance and infrastructure spending as separate subjects. Now, those lines have blurred.  

Centralized federation models make oversight easier because there are fewer duplicate datasets outside policy controls. Security teams can view permissions and data history more clearly. Finance teams can better predict storage usage, and engineering teams spend less time fixing broken data.  

This leads to better enterprise AI ROI as organizations can allocate more of their cloud budget to computing and analytics rather than maintaining additional storage.  

Snowflake’s overall strategy shows this change. The company now presents federation as not just a technical feature, but as a financial tool that supports AI growth and better operations.  

As companies continue to improve their data cloud migration strategies, the most successful ones will move away from the old idea that every workload needs its own data copy. The future of cloud costs may depend more on how effectively organizations avoid data duplication than on where the data is stored.  

Enterprise Procurement Checklist 

  • Coordinate with Snowflake (SNOW) technical teams to link external cloud databases directly to your data platform. 
  • Clean up your older data-moving pipelines to stop paying for unnecessary duplicate storage spaces. 
  • Apply strict data tracking rules within the central directory to control who can view connected files. 
  • Ensure your shared database connections comply with regional data location rules and corporate privacy plans. 
  • Calculate your annual cloud storage savings to show a clear return on investment to financial leaders. 

Source:  Snowflake Newsroom 

Costa Mesa, CA  

Atomic answer: Anduril Industries has upgraded its Lattice AI software engine, allowing teams of autonomous defense drones to coordinate search and security tasks without relying on a central command link. This platform uses edge computing to process tracking data locally, allowing individual units to adapt to changing field threats even during heavy radio jamming. By handling processing choices entirely on the vehicle hardware, the security grid can protect remote bases without experiencing system communication delays.  

A swarm of drones crossing a contested border can overwhelm a terrestrial command center in under 90 seconds. Human analysts cannot keep up with tagging, classifying, and responding to dozens of moving targets as quickly as machines can. This gap is why Anduril Lattice AI has become a key focus in modern defense procurement. Militaries are no longer asking if software will guide air defense decisions, but which software can handle electronic warfare, disrupted communications, and complex battlefield conditions.  

The growth of autonomous defense systems shows a tough military truth. Centralized command structures often fail under pressure. Modern air battles now rely on distributed intelligence working at the front lines.  

Why Anduril Lattice AI Changes the Decision Cycle? 

Traditional air defense systems rely on layers of communication between sensors, operators, and command centers. This approach worked when aircraft flew on predictable routes, and missile threats were limited. It does not work well as an autonomous drone, a cheap loitering munition, or an AI‑powered targeting system.  

Anduril Lattice AI turns the observe-orient-decide-act cycle into a software-driven process. Rather than sending every signal to a far‑off command center, the platform processes data locally using edge robotics processing, radar, infrared, electronic surveillance, and drone data, all combined to create a real‑time operational picture.  

This is important because delays can ruin defense effectiveness.  

A hypersonic projectile at Mach 5 travels about one mile each second. Even brief communication delays can cause interception failures. Systems that use edge-robotics processing rely less on cloud infrastructure and continue to operate even if satellites or long‑range networks fail.  

The Military Shift Toward Distributed AI 

Teams now typically prefer distributed systems over centralized ones because attackers often target communication points first. During electronic jamming, isolated units can lose contact with command headquarters. Systems built with infrastructure isolation principles continue to function despite these disruptions.  

This design philosophy sits at the center of Anduril Industries’ latest software for autonomous drone air defense integration in 2026, which defense analysts expect to shape procurement choices across NATO programs. The platform supports independent decision-making layers that continue to track and sort threats even when cut off from higher command.  

This kind of operational independence changes how tactics are planned.   

A forward-positioned ground defense unit with autonomous systems can spot hostile aircraft, sort targets, and plan interception routes without waiting for approval from higher up. In today’s air battles, every second counts more than following the chain of command.  

The Strategic Importance of Classified AI Infrastructure 

Military AI is very different from commercial AI. Consumer AI focuses on convenience and scaling up. Defense AI is built for survival and keeping operations secret.  

This difference is why there is more investment in classified AI systems.  

Civilian machine learning platforms use open cloud environments, but military AI requires compartmentalized computing environments that comply with strict security boundaries. Data leakage in combat scenarios creates catastrophic risks. A compromised targeting model could reveal surveillance habits, response plans, or weak spots.  

Anduril Lattice AI tackles these issues with a segmented design and secure physical transport layers that limit network exposure. Instead of using internet‑connected systems, defense teams often move important data between secure areas using isolated transport methods.  

The focus on physical transport security comes from lessons learned in cyber warfare over the last 10 years. In many contested areas, it is still easier to break in digitally than physically. Because of this, militaries are keeping operational AI separate from public communication systems.  

Why Security Boundary Compliance Matters? 

Defense contractors are under increasing scrutiny from regulators and military buyers regarding compliance with security boundary standards. AI systems that handle classified surveillance data must work with strict authorization rules.  

A failure in security boundary compliance does not merely create technical problems. It creates geopolitical consequences.  

Picture a group of countries working together with shared air defense systems. Each country has its own rules for classifying information, sharing intelligence, and making decisions. AI platforms must adhere to these boundaries while still working together to spot and respond to threats.  

Managing this balance is what will shape the next phase of military AI competition.  

Autonomous Defense Systems and the Future of Air Dominance 

Autonomous defense systems are important for more than just drones or missile defense. They can also change the economics of military force.  

A standard surface-to-air missile can cost millions of dollars, while an autonomous attack drone might cost less than $50,000. Defenders cannot keep up with these uneven costs forever. AI‑guided interception systems aim to address this imbalance by leveraging automation and reducing operating costs.  

This cost pressure is why governments continue to accelerate investment in classified AI systems, resilient infrastructure, and decentralized battlefield computing.  

In the future, air superiority will not just go to the country with the most planes. It will go to the force capable of processing information fastest under degraded conditions. This is the strategic logic behind Anduril Industries’ Lattice software for autonomous air defense in 2026 and the wider move toward AI‑driven military teamwork.  

Air superiority now relies as much on strong software as on firepower. The next big advantage might not come from a new jet or missile, but from an autonomous network that keeps working even if all regular communication channels go down.  

Enterprise Procurement Checklist 

  • Align your defense facility modernization plans with Anduril hardware availability and delivery timelines. 
  • Ensure your field facilities have secure, isolated spaces to store and maintain autonomous equipment. 
  • Configure local communication networks to handle data sharing between autonomous units safely. 
  • Check all automated hardware plans against federal military electronics and air space safety standards. 
  • Factor the long-term facility protection benefits against the upfront cost of deploying autonomous security systems. 

Source: NGC2 at Scale: How Team Anduril and the Army Took Lattice Across the 4th Infantry Division 

SAN JOSE, CA —  

Atomic Answer: Databricks Unity Catalog enterprise governance is halting the unstructured data lake drain that AI infrastructure investment is accelerating by delivering multi-platform data lineage tracking, open format Apache Iceberg integration, and centralized policy enforcement that eliminates the ungoverned unstructured data vectorization pipeline costs enterprises accumulate when AI workloads replicate and re-process the same data assets across disconnected storage tiers without visibility into which copies are active, redundant, or orphaned. For CIOs navigating the tension between AI scalability and enterprise data warehouse TCO optimization, Unity Catalog’s governance architecture provides the cost-control mechanism to optimize enterprise data lake spend at scale, where unmanaged replication becomes the primary budget leak.  

Enterprise governance for Databricks Unity Catalog is solving one of the highest cost structural failings in AI Infrastructure at present date; namely, the cost of the compute (processing power) to train and/or serve a model is not nearly as expensive as the lack of structure (governance) associated with unstructured data that exists quietly inside of an enterprise using AI pipelines without any level of governance visibility. Unstructured data is estimated to be growing at a rate of 55% – 65% per year and will continue to grow because of the training of both traditional AI models as well as generative AI models, and cloud object storage is predicted to have a near tripling of its market value from $6.5 Billion in 2023 to $18 Billion by 2031. The rate at which unstructured data vectorized pipelines lack governance visibility will result in these manageable line items being converted into nine-figure ongoing infrastructure liabilities before most enterprise data teams become aware of the issue. 

Why Multi-Platform Data Lineage Tracking Stops AI Storage Sprawl 

Multi-platform data lineage tracking is the governance capability that converts Databricks Unity Catalog enterprise governance from an access control mechanism into a cost control mechanism  because lineage visibility that reveals which data assets feed which AI pipelines, across which compute engines and cloud environments, is the prerequisite for identifying the redundant copies, stale embeddings, and duplicate vectorization jobs that unstructured data vectorization pipeline costs accumulate through. Unity Catalog delivers end-to-end automated column-level lineage for data and AI assets to simplify impact analysis, troubleshooting, governance, and AI audits, and enables discovery, querying, and governance of data across warehouses, catalogs, and databases  including MySQL, PostgreSQL, Salesforce, SAP, Amazon Redshift, Snowflake, Azure SQL Database, Azure Synapse, and Google BigQuery without data migration.  

The multi-platform scope of that lineage coverage matters specifically because enterprise data warehouse TCO optimization failures occur at the seams between platforms  the points where data moves between environments without governance handoff, generating copies that neither the source platform nor the destination platform tracks as billable replication. Unity Catalog provides a centralized governance solution for data and AI assets across Databricks workspaces, enabling fine-grained access control, data lineage tracking for visibility into data transformations and dependencies, and centralized metadata management that simplifies data discovery and governance across all workspaces. Without that cross-platform lineage surface, how to optimize enterprise data lake spend becomes an audit exercise rather than a governance capability  retrospective cost attribution rather than prospective cost prevention. 

Open Format Apache Iceberg Integration and Multi-Cloud Governance 

Open format Apache Iceberg integration within Databricks Unity Catalog enterprise governance eliminates the table format lock-in that previously forced enterprises to choose between governance quality and storage flexibility  a tradeoff that compelled expensive data migrations and created the format-siloed environments where unstructured data vectorization pipeline costs proliferate precisely because no single governance layer could see across format boundaries. Unity Catalog is now the most complete catalog for Apache Iceberg and Delta Lake, enabling open interoperability with governance across compute engines, and adds unified semantics and a rich discovery experience through full support for Apache Iceberg tables, including native support for the Apache Iceberg REST Catalog APIs. 

The open format Apache Iceberg integration that Unity Catalog delivers protects enterprise data warehouse TCO optimization investments from format obsolescence risk  the governance policies, lineage graphs, and access controls that enterprises build on Unity Catalog’s open standard foundation remain portable across compute engines as infrastructure strategy evolves, preventing the rearchitecting costs that proprietary format dependencies historically imposed. Unity Catalog unifies Delta Lake and Apache Iceberg, eliminating format silos to provide seamless governance and interoperability across clouds and engines establishing the industry’s only unified governance solution for data and AI across formats, clouds, and engines.  

For multi-cloud enterprises where AI workloads span AWS, Azure, and Google Cloud simultaneously, multi-platform data lineage tracking at the open format Apache Iceberg integration layer means that unstructured data vectorization pipeline costs generated in one cloud environment are visible to the governance controls enforced in another  closing the cross-cloud visibility gap that previously made optimizing enterprise data lake spend a cloud-specific exercise with no enterprise-wide cost control mechanism. 

Enterprise Data Warehouse TCO Optimization and the CIO Calculus 

Chief Information Officers (CIOs) must manage a wider range of enterprise data warehouse total cost of ownership (TCO) optimization strategies for the scale of today’s enterprise AI workloads than they have done previously by not only handing over service-level agreements (SLAs) and operational keys to their traditional data warehouses containing structured tables which have formerly defined the economics of traditional data warehouses, but also those unstructured data volumes that are produced via AI training, embedding and vectorization pipelines in addition to structured data tables. In 2025 alone, we saw enterprise AI infrastructure expenses grow by approximately 166%  indicative of increasing demand for larger models, real-time analytics, multimodal architectural approaches, and continuous retraining in both production AI and ML operations (MLOps) pipelines while also witnessing a situation where the rate at which storage budgets grew outpaced enterprise AI roadmaps due to everything being tossed together without first establishing clearly defined and tiered lifecycle and storage provisioning rules. 

Databricks Unity Catalog enterprise governance addresses that TCO pressure by extending governance to the asset classes created by AI infrastructure, but traditional data catalog tools were never designed to manage them. Unity Catalog unifies discovery, access, lineage, monitoring, auditing, semantics, and sharing across all data and AI assets in open formats, including Delta, Apache Iceberg, Hudi, Parquet, and CSV, while automating critical performance-tuning tasks such as file compaction, data clustering, and statistics collection, which directly lead to faster query execution and reduced storage overhead. The automated file compaction and clustering that Unity Catalog applies to governed data assets directly reduce the storage footprint that unstructured data vectorization pipelines accumulate  compacted, well-clustered storage consumes fewer bytes, generates fewer scan costs, and requires fewer vectorization re-runs than the fragmented, small-file accumulations that ungoverned AI pipelines leave behind. 

Conclusion 

Databricks Unity Catalog enterprise governance halts the drain on unstructured data lakes that enterprise AI investment creates by converting multi-platform data lineage tracking from an audit trail into an active cost-control mechanism  one that makes unstructured data vectorization pipeline costs visible before they compound, rather than after they appear in cloud billing statements. Open-format Apache Iceberg integration eliminates the format-boundary gaps that previously allowed AI storage sprawl to accumulate across compute environments that no single governance layer could see. Enterprise data warehouse TCO optimization at AI scale requires the lineage depth, format flexibility, and multi-cloud policy enforcement that Databricks Unity Catalog enterprise governance delivers as a unified architecture rather than a collection of point tools. For CIOs whose primary infrastructure question has shifted from how to build AI capability to how to optimize enterprise data lake spend without constraining the AI scalability that competitive strategy requires, Unity Catalog’s governance architecture provides the control plane that enables both objectives to be achieved simultaneously.

Source: https://www.databricks.com/product/unity-catalog 

SAN JOSE, CA — 

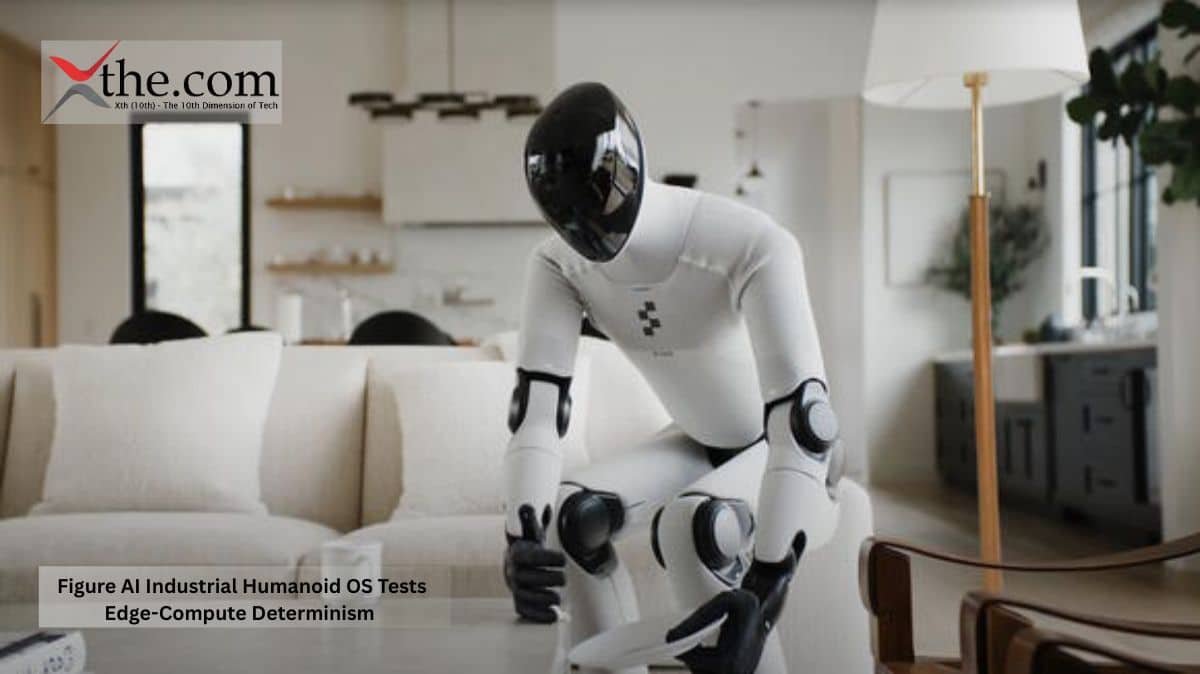
Atomic Answer: Figure AI industrial humanoid fleet deployment is testing the deterministic limits of sub-millisecond edge inference networking at production scale  establishing that edge computing infrastructure for industrial robotics is not a connectivity optimization problem but a real-time compute architecture requirement that ruggedized industrial edge server nodes, vision language action model parameter scaling, and factory floor real-time telemetry must resolve simultaneously to make autonomous humanoid operation reliable enough for U.S. manufacturing environments.  

The Figure AI industrial humanoid fleet deployment represents the most structurally demanding test of edge computing infrastructure for industrial robotics yet attempted in production not because Figure’s robots are the most powerful compute platforms in the humanoid category, but because Helix, Figure’s generalist Vision-Language-Action model, runs entirely onboard embedded low-power-consumption GPUs, making it immediately ready for commercial deployment  a design choice that places the full burden of deterministic real-time inference on ruggedized industrial edge server nodes rather than distributing it across cloud infrastructure that factory floor latency constraints cannot tolerate. 

Why Sub-Millisecond Edge Inference Networking Determines Factory Automation Reliability 

The key architectural constraint distinguishing humanoid robots capable of reliable factory automation from others that demonstrate remarkable performance during a controlled demo before failing under unpredictable timing constraints in live environments is sub-millisecond edge inference networking. The basic barriers to modern industrial networking continue to be due to inference latency, rendering real-time control impossible, as well as network outages over the internet, crippling every single smart facility. Cloud technology provides powerful computational resources for enterprises; unfortunately, they are too far removed from the actual manufacturing process on the factory floor to be of significant use for real-time control applications. 

Figure’s Helix architecture resolves this constraint through a dual-system design built for onboard determinism. System 2 operates as an onboard internet-pretrained VLM at 7–9 Hz for scene understanding and language comprehension, enabling broad generalization across objects and contexts, while System 1 translates the latent semantic representations produced by System 2 into precise continuous robot actions at 200 Hz. The 200 Hz control loop that System 1 sustains is only viable under sub-millisecond edge inference networking conditions  cloud-dependent inference at equivalent frequency is physically impossible across any realistic wide-area network latency profile, making onboard ruggedized industrial edge server nodes the non-negotiable compute substrate for humanoid factory deployment at production reliability standards. 

Vision Language Action Model Parameter Scaling and the Onboard Compute Tradeoff 

Vision-language-action model parameter scaling defines the capability ceiling that Figure AI’s industrial humanoid fleet deployment can achieve at any given onboard compute budget and the architectural choices Helix makes in managing that tradeoff reveal the engineering logic that edge computing infrastructure for industrial robotics at humanoid scale requires. System 2 is built on a 7B-parameter open-source VLM pretrained on internet-scale data, processing monocular robot images and robot state information after projecting them into a vision-language embedding space, while System 1  an 80M-parameter cross-attention encoder-decoder transformer  handles low-level control at a higher frequency to enable more responsive closed-loop operation.  

The asymmetry between System 2’s 7B-parameter vision language action model parameter scaling and System 1’s 80M-parameter reactive policy reflects a deliberate edge compute optimization the semantic reasoning that requires large model capacity runs at lower frequency where its latency is acceptable, while the motor control that requires deterministic timing runs at a parameter count that onboard hardware can execute within the sub-millisecond budget that factory floor real-time telemetry and physical safety constraints demand. Helix coordinates a 35-DoF action space at 200Hz, controlling everything from individual finger movements to end-effector trajectories, head gaze, and torso posture. 

Factory Floor Real-Time Telemetry and Fleet Orchestration 

Factory floor real-time telemetry from Figure AI industrial humanoid fleet deployment at production scale generates the operational data stream that fleet orchestration, safety monitoring, and continuous model improvement depend on  and the infrastructure architecture that manages this telemetry without introducing the cloud-round-trip latency that would compromise real-time control defines the edge computing infrastructure for industrial robotics investment that enterprises adopting humanoid labor augmentation must plan for. Figure 02 was deployed at BMW’s Spartanburg plant in 2025, supporting the production of more than 30,000 BMW X3 vehicles, working 10-hour shifts Monday through Friday, and helping load more than 90,000 sheet metal parts.  

The real-time telemetry from BMW’s deployment factory floor over numerous production shifts validated ruggedized industrial edge server nodes to be the feasible architectural platform for the management of humanoid fleets at automotive manufacturing reliability levels – manufacturing environments that subject hardware to stress profiles due to vibration, thermal variability, electromagnetic interference from welding/machining operations, and continued utilization across multiple shifts of each Humanoid. When using a hybrid edge-cloud artificial intelligence (AI) architecture, companies are reporting 40% reduced response times for critical operations combined with 30% – 50% reductions in cloud costs, thereby confirming the economic rationale behind creating a locally anchored, deterministic control framework with Figure AI’s industrial humanoid fleet deployment while leveraging the cloud for the development of training & long-horizon analytics and synchronicity of models across multiple facilities. 

Edge Computing Infrastructure for Industrial Robotics and U.S. Manufacturing Modernization 

Edge computing infrastructure for industrial robotics is emerging as the foundation on which U.S. manufacturing modernization depends as humanoid labor augmentation transitions from pilot programs to fleet-scale deployment. In 2025, $1.2 trillion in investments toward building out U.S. production capacity was announced, led by electronics providers, pharmaceutical companies, and semiconductor manufacturers, with the nation’s leading companies relying on physical AI and simulation to accelerate manufacturing.  

Figure AI surpassed $1 billion in committed Series C funding at a $39 billion post-money valuation to accelerate the deployment of its general-purpose humanoid robots. The funding is aimed at scaling BotQ production, expanding Nvidia GPU infrastructure for Helix AI training, and increasing multimodal data collection to improve robot performance. BotQ’s first-generation production line targets 12,000 humanoid robots per year  a volume at which factory floor real-time telemetry aggregated across the deployed fleet becomes the primary data asset that vision language action model parameter scaling improvements depend on, closing the loop between deployment economics and model capability in a way that cloud-dependent architectures with higher inference latency cannot replicate. 

Conclusion 

Figure AI industrial humanoid fleet deployment has established sub-millisecond edge inference networking as the non-negotiable determinism requirement that separates humanoid robots viable for factory automation from those limited to controlled environments. Ruggedized industrial edge server nodes provide the onboard compute substrate that vision language action model parameter scaling at Helix’s architecture requires  7B-parameter semantic reasoning paired with 80M-parameter 200 Hz motor control that cloud infrastructure latency profiles cannot support. Factory floor real-time telemetry from BMW’s Spartanburg production deployment validates the fleet orchestration architecture that edge computing infrastructure for industrial robotics must deliver at automotive manufacturing reliability standards. As U.S. manufacturing modernization accelerates toward humanoid labor augmentation at scale, the Figure AI industrial humanoid fleet deployment architecture — onboard deterministic inference, edge-local telemetry, and vision language action model parameter scaling optimized for embedded compute  defines the infrastructure specification that enterprise buyers entering industrial humanoid deployment will inherit across the next hardware generation.

Source: The future of home help is here 

SAN JOSE, CA — 

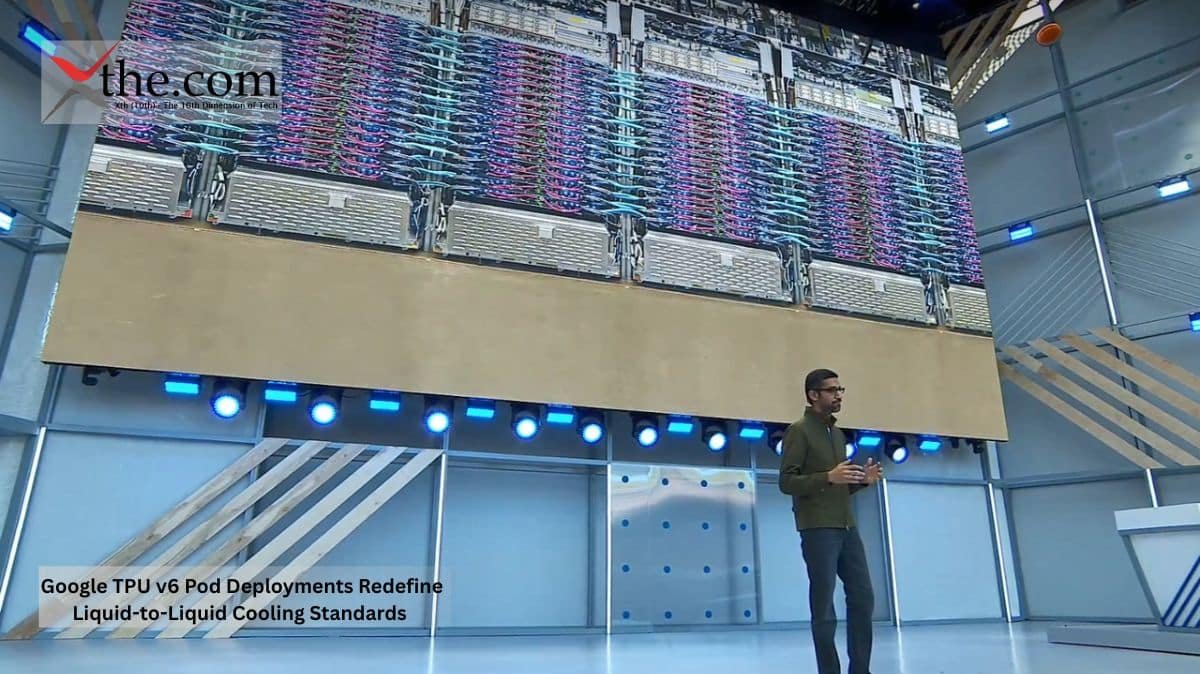
Atomic Answer: Google TPU v6 infrastructure deployment is redefining data center liquid-to-liquid cooling systems as the mandatory thermal architecture for frontier model training at scale not as an incremental efficiency upgrade, but as the engineering prerequisite that v6 chip thermal design power levels require to sustain peak compute performance continuously. By integrating optical circuit-switch network topologies with a liquid-cooled pod architecture, Google’s TPU v6 deployment establishes the infrastructure template that next-generation AI data center cooling requirements will inherit across the hyperscaler tier.  

The Google TPU v6 infrastructure deployment represents the most consequential convergence of silicon thermal engineering and data center cooling architecture since liquid cooling migrated from theoretical advantage to operational necessity  because Trillium TPUs achieve a 4.7x increase in peak compute performance per chip compared to TPU v5e, with doubled High Bandwidth Memory capacity and doubled Interchip Interconnect bandwidth, the v6 chip thermal design power envelope that these performance gains require has made data center liquid to liquid cooling systems the non-negotiable infrastructure foundation rather than an optional efficiency enhancement. 

Why AI Power Density Escalation Makes Liquid Cooling Mandatory 

AI power density escalation has crossed the threshold at which next-generation AI data center cooling requirements cannot be satisfied by air-cooling economics or physics. As GPU rack densities surge past 50kW with next-generation systems demanding 100kW and beyond  traditional air cooling has reached its fundamental physical limits. The v6 chip thermal design power envelope that Google’s Trillium architecture operates within places TPU pod deployments squarely in the density range where air-cooling failure is not a risk to manage but a physical constraint to engineer around.  

Google notes that water has a thermal conductivity approximately 4,000 times that of air the physical foundation on which Google TPU v6 infrastructure deployment at pod scale becomes operationally viable. Google’s seven-year journey with liquid-cooled TPUs has yielded the industry’s most comprehensive dataset, deploying closed-loop systems across 2,000+ TPU Pods at gigawatt scale, achieving 99.999% uptime, and demonstrating 30x greater thermal conductivity than air. The frontier model training energy-efficiency argument for liquid cooling strengthens as v6 chip thermal design power levels reflect performance capabilities that air-cooled infrastructure cannot sustain under continuous training workloads at the utilization rates required by gradient descent across trillion-parameter models. 

Data Center Liquid-to-Liquid Cooling Systems at Pod Scale 

Data center liquid-to-liquid cooling systems at Google TPU v6 infrastructure deployment scale operate through Coolant Distribution Units that exchange heat between the facility water supply and the chip-level cooling loop without the two liquid supplies mixing  a closed-loop thermal architecture that spans racks rather than being contained within individual servers.  

Google’s Project Deschutes CDU design delivers 2 megawatts of cooling at an aggressive 3°C approach temperature difference, with 80 PSI available pressure to enable advanced cold plate designs suited for high-power AI processors, and fully redundant power feeds for each pump circuit alongside 0.2 micron filtration to maintain coolant quality for extended uptime. The 2MW CDU specification defines the cooling infrastructure capacity required by next-generation AI data center cooling at the rack density levels TPU v6 pods create, and Google’s fifth-generation CDU design will be contributed to the Open Compute Project, accelerating industry-wide adoption of these thermal standards.  

The liquid-to-liquid thermal separation that CDU architecture creates between facility water infrastructure and chip-level coolant loops solves the contamination and pressure management challenges that direct contact cooling would create  enabling data center operators to maintain the coolant quality that v6 chip thermal design power reliability requires at scale. 

Optical Circuit Switch Network Topologies and Training Architecture 

Optical circuit switch network topologies within Google TPU v6 infrastructure deployment enable the interconnect reconfigurability that frontier model training energy efficiency requires across pod-scale deployments. The OCS architecture dynamically reconfigures the interconnect topology to accelerate model performance, routes around failed components so that long-running training tasks can utilize thousands of processors for weeks at a time, and achieves this with optical components that represent less than 5% of system cost and less than 5% of system power.  

Cloud TPUs support frontier model training through high-speed Inter-Chip Interconnect, optical circuit switch network topologies, and the Virgo Network, enabling accelerators to operate as a unified, highly reliable system. The optical circuit-switch network topology that ties TPU v6 pods into cohesive training clusters resolves the latency and bandwidth bottlenecks that electrical switching at equivalent port counts would introduce  requiring no optical-to-electrical-to-optical conversion and eliminating power-hungry network packet switches in the process. Trillium doubled the Interchip Interconnect bandwidth over TPU v5e, expanding the collective communication capacity that AllReduce operations across frontier model training require for energy-efficiency optimization at a thousand-chip-pod scale. 

Frontier Model Training Energy Efficiency and Hyperscaler Competition 

Frontier model training energy efficiency at Google TPU v6 infrastructure deployment scale represents the convergence of v6 chip thermal design power optimization with liquid cooling’s operational advantages over air-cooled alternatives. Trillium delivers 67% higher energy efficiency and 4.7x higher peak compute performance per chip compared to TPU v5e  a per-watt gain that translates directly into reduced training costs at the utilization levels Google’s pod infrastructure maintains continuously.  

TPU v6e starts at $0.39–1.375 per chip-hour, compared to H100 GPUs at over $3 per hour, a cost differential that reflects both purpose-built silicon efficiency and the infrastructure economics enabled by Google’s vertically integrated TPU cooling architecture at scale. Hyperscaler competition around AI compute scaling has made frontier model training energy efficiency a strategic infrastructure differentiator the operators who establish thermal management architectures capable of sustaining next-generation AI data center cooling requirements gain deployment optionality that competitors constrained by air-cooling density limits cannot access. 

Conclusion 

Google TPU v6 infrastructure deployment has established data center liquid-to-liquid cooling systems as the mandatory thermal architecture for frontier model training at scale — the v6 chip thermal design power envelope that Trillium’s 4.7x performance gains require has made next-generation AI data center cooling requirements a structural infrastructure specification rather than a procurement preference. Optical circuit switch network topologies provide the interconnect reconfigurability and power efficiency that pod-scale TPU deployment demands across sustained training workloads. Frontier model training energy efficiency at TPU v6 deployment scale  67% better per chip than the prior generation  demonstrates that thermal engineering investment and silicon optimization are inseparable at the performance levels the AI training market now requires. As next-generation AI data center cooling requirements define the infrastructure envelope that hyperscalers and enterprise AI buyers must plan for, the liquid-to-liquid cooling standards established by the Google TPU v6 Pod deployment will define the thermal architecture specification that the hardware generation following Trillium inherits.

Source: News, tips, and inspiration to accelerate your digital transformation

AUSTIN, TX — 

Atomic Answer: Oracle’s EU Sovereign Cloud delivers physically isolated European cloud infrastructure that processes and stores data exclusively within EU jurisdictions, operated by EU-resident personnel under EU legal governance. The architecture provides multinational enterprises and US-based SaaS vendors with a compliant deployment path that satisfies GDPR data residency requirements, Schrems II transfer restrictions, and the emerging national digital sovereignty mandates that are progressively tightening cross-border data flow permissions across European member states.  

The Oracle EU Sovereign Cloud compliance architecture arrives as the regulatory gap between what standard hyperscale cloud deployments offer and what European data protection law actually requires has widened to the point that contractual data residency commitments no longer satisfy the regulatory scrutiny imposed by GDPR enforcement actions and national sovereignty legislation. As cross-border data transfer legal frameworks continue to tighten under Schrems II jurisprudence and EU member state digital sovereignty initiatives, sovereign cloud data protection strategies that rely on policy commitments rather than physical infrastructure isolation are accumulating regulatory exposure that Oracle’s architecture specifically eliminates. 

Why Standard Cloud Deployments No Longer Satisfy European Requirements 

Cross-border data transfer legal frameworks have evolved beyond what standard cloud-provider data-residency-region selection can structurally accommodate. The Schrems II ruling invalidated the Privacy Shield framework and established that data residency commitments  where data is stored at rest do not address the transfer exposure that cloud provider support access, telemetry routing, and operational management create when those functions traverse non-EU jurisdictions.  

Oracle EU Sovereign Cloud compliance addresses this at the operational layer that standard cloud deployments leave exposed not just where data is stored but who can access it, under what legal jurisdiction access requests are evaluated, and whether the personnel with operational access to the infrastructure are subject to EU legal governance rather than US law that CLOUD Act provisions could compel data disclosure under.  

Isolated sovereign database management within Oracle’s EU Sovereign Cloud ensures that database administration, performance monitoring, and incident response access are restricted to EU-resident personnel operating under EU employment law eliminating the extraterritorial access pathway that US-based cloud operator personnel create for European customer data, regardless of where the data physically resides. 

GDPR Pressure and the Compliance Architecture Gap 

SaaS data residency controls that US-based SaaS vendors implement through standard cloud provider region selection satisfy the data storage location requirement that GDPR Article 44 governs  but do not satisfy the broader data processing governance requirements that GDPR Articles 28 and 32 impose on data processors regarding the security measures, access controls, and subprocessor governance that cloud infrastructure operations involve.  

Oracle EU Sovereign Cloud compliance provides US-based SaaS vendors with a deployment architecture that satisfies the full GDPR compliance requirement stack rather than the storage-location subset that standard data residency region selection addresses  enabling SaaS vendors to present EU enterprise customers with a compliance posture that data protection officers and regulatory auditors accept without requiring legal interpretation of whether standard cloud operations satisfy GDPR’s operational requirements.  

Multi-cloud compliance audit automation within Oracle’s sovereign cloud generates the continuous compliance evidence that GDPR audit requirements demand not point-in-time certification snapshots but ongoing documentation of data processing activities, access control enforcement, and data residency maintenance that supervisory authority investigations require when assessing GDPR compliance for specific data processing operations. 

Sovereign cloud data protection strategies are no longer driven exclusively by GDPR compliance national digital sovereignty initiatives across France (SecNumCloud), Germany (C5), and EU-wide EUCS certification frameworks are establishing sovereignty requirements that go beyond data residency into infrastructure ownership, operational control, and legal governance criteria that US-headquartered cloud providers cannot satisfy without purpose-built sovereign deployment architectures.  

Cross-border data transfer legal frameworks are increasingly reflecting geopolitical concerns that treat cloud infrastructure as a strategic national asset rather than a commercial service. European legislative trends that require critical national infrastructure to run on EU-sovereign cloud platforms effectively exclude US hyperscalers from public-sector and regulated-industry markets that do not operate sovereign cloud deployments.  

Oracle EU Sovereign Cloud compliance positions Oracle competitively in European markets where sovereignty requirements are progressively restricting financial services firms subject to DORA requirements, healthcare organizations processing health data under EU health data space regulations, and public sector entities subject to national sovereignty mandates represent procurement opportunities that sovereign cloud architecture creates and that non-sovereign deployments cannot access, regardless of technical capability. 

Operational Burden of Regionalized Cloud Infrastructure 

Isolated sovereign database management operational requirements create infrastructure management overhead that multinational enterprises must account for when evaluating sovereign cloud migration  separate operational procedures, distinct access control frameworks, isolated monitoring infrastructure, and dedicated support personnel that sovereign cloud compliance requires represent ongoing operational investment beyond the migration project itself.  

Multi-cloud compliance audit automation reduces the most significant operational burden component the continuous compliance documentation that sovereign cloud deployments generate for regulatory purposes. Manual compliance documentation that sovereign operations require without automation consumes security and compliance team capacity that scales with audit frequency rather than infrastructure complexity, making automation investment the operational efficiency lever that sovereign cloud deployments require to remain manageable alongside standard cloud operations.  

SaaS data residency controls implementation for US-based SaaS vendors deploying on Oracle EU Sovereign Cloud requires application architecture review that identifies the data flows, telemetry calls, and support access pathways within SaaS application code that may create inadvertent data transfers to non-sovereign infrastructure  application-level sovereign compliance requires more than infrastructure-level sovereign deployment when application code itself generates cross-border data transfers through logging, analytics, or support tooling. 

Multinational Enterprise Strategy for Sovereign Compliance 

Sovereign cloud data protection strategies for multinational enterprises operating across EU and US jurisdictions require a data classification architecture that identifies which data categories require sovereign cloud processing and which can remain on standard cloud infrastructure. Comprehensive sovereign cloud migration that moves all workloads to sovereign infrastructure creates operational costs and performance tradeoffs that data classification-based selective migration avoids.  

Oracle EU Sovereign Cloud compliance selective deployment for regulated data categories  personal data subject to GDPR, financial data subject to DORA, health data subject to EU health data space requirements allows multinational enterprises to satisfy sovereign compliance requirements for the specific data categories that regulation mandates without the full operational overhead of migrating standard business workloads that regulatory requirements do not restrict to sovereign infrastructure.  

In order to determine compliance with legal frameworks regulating the transfer of data between countries (i.e. cross-border transfers), it is necessary to perform a data flow mapping project on selectively deployed sovereign deployments to ensure that all regulated categories of data are only being processed in sovereign data centers and all other (non-regulated) categories of data are only being processed in non-sovereign data centers or in standard cloud infrastructure. 

Conclusion 

To comply with the requirements of the European Data Protection Regulation (GDPR), Oracle’s EU Cloud Compliance provides physical infrastructure isolation, operational control by EU-resident entities, and legal governance by EU law. Many organizations use standard clouds, but they contain little or no survivability for cross-border data transfer in accordance with the GDPR; therefore, there exists a significant risk to compliance resulting from national digital sovereignty initiatives, increased pressures regarding compliance with cross-border data transfer regulations, and the invalidation of cross-border data transfer regulatory frameworks under Schrems II, inter alia. 

Sovereign Database Maintenance in Isolation Reduces Extraterritorial Access Risk to European Customer Data by Reducing the Number of Employees of a Cloud Operator Based in the United States Who Access Data in Europe. Automation of Compliance Audits for Multi-Cloud Reduces Ongoing Operations Required to Provide Regulatory Compliance Evidence in a Sovereign Cloud Environment. Establishing Data Residency Controls for a US-based SaaS Vendor or Provider Requires Review of the Flow of Application-Level Data. Infrastructure-based architecture will not provide the required application-level data review. A Sovereign Data Protection Strategy based on selective sovereign cloud deployments, aligned with data classification, balances operational costs with the ability to meet compliance requirements when operating on a multinational basis across EU and US Jurisdictions. As Legal Structures for Cross-Border Data Transfer Become More Restrictive and National Digital Sovereignty Requirements Move Beyond GDPR, Developing Sovereign Cloud Architecture Will Prevent Forced Migration Timelines Resulting from the Enforcement of Regulatory Actions Against Organizations That Delay.

Source: Oracle EU Sovereign Cloud 

SANTA CLARA, CA — 

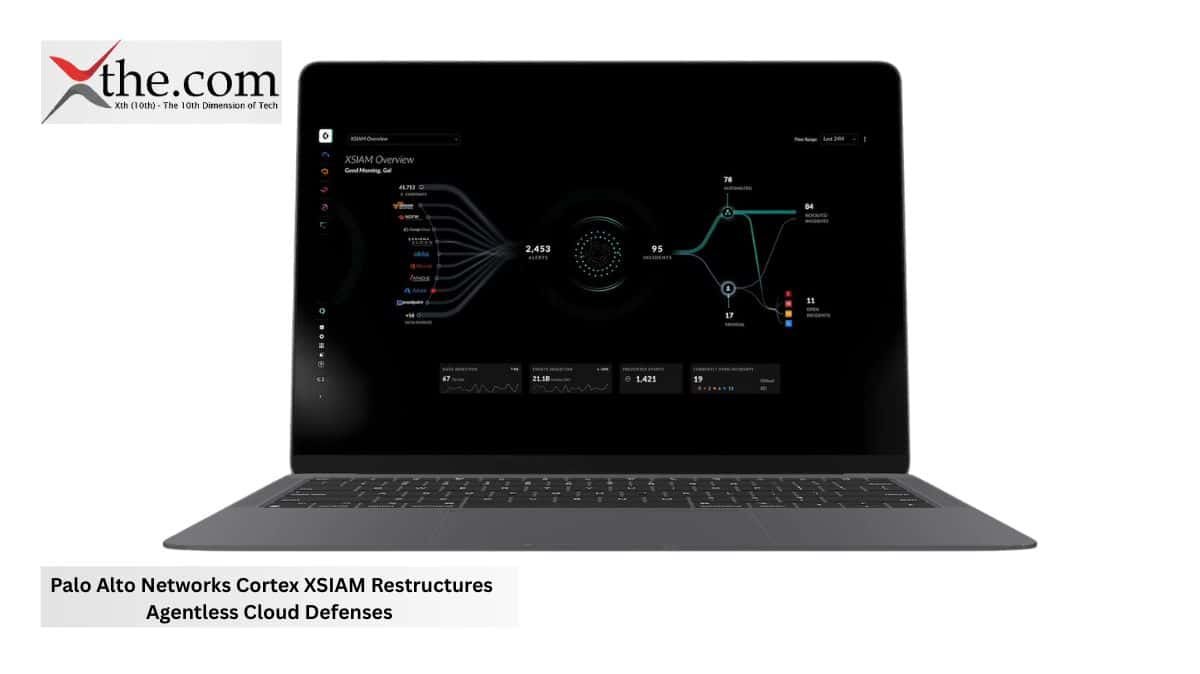
Atomic Answer: Palo Alto Networks has expanded Cortex XSIAM with agentless runtime workload protection and graph-based attack surface management, eliminating the deployment friction of agent-based cloud security without sacrificing detection depth. The platform’s AI-driven SOC automation compresses alert triage from analyst-hours to machine-seconds, directly addressing the alert fatigue crisis that has made human-scaled cloud security operations structurally insufficient to withstand the cloud-native attack velocity.  

The Palo Alto Networks Cortex XSIAM cloud security expansion reframes enterprise cloud defense around the premise that agent-dependent security architectures structurally resist the idea that cloud workload protection should be as dynamic as the cloud environments it protects. As automated threat detection AI operations eliminate the alert triage bottleneck that has made SOC analyst capacity the binding constraint on cloud security response speed, and agentless runtime workload protection removes the deployment overhead that agent-based coverage has always traded against scalability, the enterprise cloud security transformation strategy that US enterprises have been building toward has a platform architecture that operationalizes it. 

Why Agent-Based Cloud Security Creates the Coverage Gap It Tries to Close 

Agentless runtime workload protection addresses the fundamental contradiction of agent-dependent cloud security the environments that move fastest, scale most dynamically, and carry the highest breach risk are precisely the environments where agent deployment discipline breaks down. Ephemeral containers, serverless functions, auto-scaled workload instances, and developer-provisioned cloud resources that appear and disappear faster than agent deployment pipelines can track create the unprotected surface that cloud-native attacks systematically target.  

Graph based cloud attack surface management within Cortex XSIAM maps the relationships between cloud resources, identities, configurations, and network paths that individual workload monitoring cannot surface  an attack that traverses misconfigured IAM permissions to access an unprotected storage bucket through a compromised container does not generate a single high-severity alert in any individual monitoring system, but appears as a connected attack path in graph-based attack surface analysis that correlates the relationship between each component.  

Zero-trust identity mesh enforcement across cloud workload access ensures that the implicit trust previously conferred by the cloud-internal network is replaced by continuous identity verification for every workload-to-workload communication  removing the lateral movement pathway that compromised cloud workloads exploit through trusted internal network access that perimeter controls never scrutinized. 

AI-Driven SOC Automation and Alert Fatigue Resolution 

Automated threat detection AI operations within Cortex XSIAM directly address the alert fatigue problem that has made human-scaled SOC operations insufficient for cloud security at enterprise scale. Security operations centers monitoring cloud environments generate alert volumes that analyst teams cannot process at the rate that cloud-native attack campaigns require response  the median enterprise SOC processes a fraction of its daily alert volume through human review, leaving the remainder uninvestigated until retrospective analysis surfaces the alerts that preceded a confirmed breach.  

Palo Alto Networks Cortex XSIAM cloud security AI automation changes the alert processing model from human triage of individual alerts to AI correlation of alert clusters into incident narratives  reducing the analyst cognitive load from evaluating thousands of discrete alerts to reviewing dozens of pre-packaged incident summaries that identify attack campaign scope, affected resources, recommended containment actions, and confidence scoring that focuses analyst judgment on decisions rather than triage.  

An enterprise cloud security transformation strategy that relies on hiring additional SOC analysts to manage alert volume growth is not a sustainable security architecture  the scale and velocity of cloud environments, and the pace of attack automation, outpace analyst hiring capacity. Automated threat detection AI operations that process alert volume at machine speed while surfacing analyst-ready incident summaries are the only operationally viable response to cloud security alert volumes that continue scaling with cloud adoption, regardless of analyst headcount investment. 

Graph-Based Attack Surface Management for Cloud-Native Threats 

Graph-based cloud attack surface management provides the topological visibility that linear alert correlation cannot deliver for cloud-native attacks that chain multiple low-severity indicators across different cloud services into high-severity compromise sequences. A cloud attack that uses a misconfigured storage bucket to stage malware, exploits an overprivileged service account to move laterally, and exfiltrates through an unmonitored egress path generates alerts in three separate cloud monitoring systems that individually appear unremarkable  but that graph analysis connects into an attack path that attack surface management surfaces before exfiltration completes.  

Zero-trust identity mesh integration with graph-based attack surface analysis enables Cortex XSIAM to identify the identity-permission relationships that make specific attack paths exploitable not just detecting that an attack traversed a permission boundary, but identifying which permission configurations created the traversable boundary that remediation should close. Agentless runtime workload protection telemetry that graph analysis incorporates ensures that workload behavior data contributes to attack path analysis without requiring agent deployment, which ephemeral cloud environments cannot sustain.  

Enterprise cloud security transformation strategy built on graph-based attack surface management shifts the cloud security posture from reactive incident response to proactive attack path elimination  identifying and remediating the configuration relationships that enable specific attack paths before threat actors execute them, rather than detecting execution after it begins. 

Compliance, Operational Efficiency, and AI-Assisted Incident Response 

US enterprises balancing cloud security compliance requirements against operational efficiency constraints face a platform selection challenge that Palo Alto Networks Cortex XSIAM cloud security addresses through consolidated compliance evidence generation  every agentless workload scan, every graph-based attack surface finding, and every AI-automated incident response action generates audit trail records that compliance frameworks require without the manual evidence compilation that separate security tools demand.  

Automated threat detection AI operations compliance integration ensures that AI-assisted incident response actions are documented with the decision context that audit frameworks require  automated containment decisions that lack documentation of the behavioral evidence that triggered them create compliance gaps that regulators identify as insufficient incident response governance, regardless of technical containment effectiveness.  

Zero-trust identity mesh compliance documentation provides the continuous verification evidence that federal zero-trust mandates require, beyond a point-in-time architecture certification. Continuous identity verification records generated by Cortex XSIAM demonstrate ongoing zero-trust enforcement that audit frameworks increasingly require, rather than accepting architecture documentation as sufficient compliance evidence. 

Agentless Deployment and Cloud-Native Attack Coverage 

Agentless runtime workload protection deployment across cloud environments eliminates the coverage gap timeline that agent-based security creates between workload provisioning and security coverage activation. Cloud workloads that launch without agents are exposed during the deployment and configuration window that agent installation requires a window that cloud-native attacks actively target through the automated scanning that identifies newly provisioned unprotected resources within minutes of launch.  

Graph-based cloud attack surface management agentless coverage ensures that every cloud resource that Cortex XSIAM discovers through cloud provider API integration is immediately incorporated into attack surface analysis without requiring agent deployment that resource ephemerality may not accommodate serverless functions, container instances with sub-minute lifetimes, and auto-scaled workloads that terminate before agent installation completes all contribute to attack surface graph analysis through agentless telemetry.  

An enterprise cloud security transformation strategy that relies on agentless coverage for dynamic cloud environments, while maintaining agent-based depth for persistent infrastructure that agent deployment can sustain, provides the coverage architecture that cloud-native attack surfaces require  not agentless-only or agent-only, but coverage architecture matched to the deployment characteristics of each cloud workload category. 

Conclusion 

Palo Alto Networks Cortex XSIAM cloud security expansion establishes agentless runtime protection, graph-based attack surface management, and AI-driven SOC automation as the cloud security architecture that cloud-native attack velocity requires. Automated threat detection AI operations resolve the alert fatigue crisis that human-scaled SOC operations cannot address through analyst hiring  machine-speed alert correlation that delivers analyst-ready incident summaries removes triage from the analyst workflow and focuses human judgment on containment decisions.  

Agentless runtime workload protection eliminates the coverage gap that agent deployment discipline cannot close in dynamic cloud environments, where ephemeral workloads launch and terminate faster than deployment pipelines can track. Graph-based cloud attack surface management surfaces the attack paths that individual alert correlation misses connecting the configuration relationships, identity permissions, and workload behaviors that cloud-native attacks chain across multiple cloud services into breach sequences. Zero trust identity mesh enforcement removes the implicit trust that cloud-internal network position confers  replacing it with continuous verification that lateral movement cannot exploit. As enterprise cloud security transformation strategy matures from architectural aspiration into operational deployment, the platform that operationalizes agentless coverage, graph-based attack surface analysis, and AI-automated SOC response simultaneously provides the consolidated cloud security foundation that US enterprises require to balance compliance, operational efficiency, and cloud-native threat defense in 2026.

Source: Control the chaos. Secure every identity. 

SANTA CLARA, CA — 

Atomic Answer: MediaTek and NVIDIA have formalized their Copilot+ silicon partnership, introducing an ARM-based neural processing architecture into the Windows enterprise laptop market, a market x86 silicon has dominated for 4 decades. The collaboration delivers dedicated client-side NPU capability that enables local AI inference without cloud dependency, forcing enterprise IT procurement teams to reconcile application compatibility constraints against battery efficiency gains and total cost of ownership advantages that MediaTek NVIDIA enterprise WoA deployment delivers over refreshed x86 alternatives.  

The MediaTek NVIDIA enterprise WoA partnership arrives as procurement teams consider their most consequential laptop decision in a generation. This decision matters not simply for incremental hardware improvements, but because the silicon architecture is categorically different. As Windows on ARM app compatibility gaps narrow with frequent driver updates from major vendors, the choice of the best AI PC for corporate fleet deployment no longer defaults to x86. Now, enterprise TCO analysis over a 3- to 5-year refresh horizon makes ARM financially compelling for more workforce segments. 

Why ARM Silicon Is Now an Enterprise Procurement Decision 

Windows on ARM corporate application compatibility has historically been the disqualifying constraint that ended ARM enterprise evaluation before TCO (total cost of ownership) analysis could begin. Enterprise application portfolios built on x86 assumptions  legacy line-of-business applications, security agents with kernel-level x86 dependencies (security programs needing direct hardware access on x86 only), and developer toolchains requiring native x86 compilation (software tools needing to run directly on x86 chips)  created compatibility exposure that procurement teams treated as an absolute deployment barrier regardless of ARM’s performance and efficiency advantages.  

MediaTek NVIDIA enterprise WoA deployment changes this evaluation by pairing MediaTek’s ARM silicon efficiency with NVIDIA’s AI inference acceleration. The result: a Windows-native deployment target that meets Copilot+ NPU benchmark requirements and leverages NVIDIA’s familiar driver ecosystem. This combination lowers the software compatibility risk seen in earlier ARM Windows deployments, which lacked NVIDIA’s driver infrastructure depth.  

The hybrid AI PC local inference capability that ARM Copilot+ devices deliver represents the enterprise deployment property that changes the compatibility risk calculus enterprise applications that previously required cloud AI API calls for intelligent features can execute locally on NPU silicon that ARM Copilot+ devices provide, reducing the cloud dependency that security-sensitive enterprise deployments treat as a data handling risk rather than simply a performance inconvenience. 

x86 Versus ARM Fleet Management Cost Comparison 

In order to accurately compare the two fleets’ deployment costs it is necessary to consider a full total cost of ownership (TCO) perspective; this analysis should include all of the above listed factors including: initial startup costs (i.e., hardware), operating costs (i.e., electricity), technical support costs due to battery-related issues on x86 AI PC machines; differences in security patches between architectures; costs associated with running local network processing unit (NPU) solutions for workloads that have corresponding cloud based application interface (API) solutions. 

Custom client-side NPU benchmarks on MediaTek-NVIDIA Copilot+ devices demonstrate local inference throughput that eliminates the per-query API costs that cloud AI features impose on enterprise deployments at scale  an enterprise deploying Copilot+ AI features across 10,000 devices that each eliminate 50 cloud API calls daily generates API cost avoidance that compounds into meaningful infrastructure budget reduction over a three-year device lifecycle.  

To deploy AI PCs with the lowest Total Cost of Ownership (TCO), the TCO model must include: API Cost Avoidance; Battery Efficiency Gains; Reduced Charging Needs; and Acquisition Cost. Therefore, ARM Copilot+ devices will be chosen for segments of the workforce that meet compatibility validation standards. The upfront cost of ARM devices above the base x86 cost is frequently recouped through reduced operational costs over the device’s lifetime—this is not true for x86 devices. 

Battery Efficiency and Hybrid Workforce Productivity 

With recent advances in Windows on ARM application compatibility, ARM’s battery performance will positively impact more workforce segments. Because hybrid workforce segments (field sales, consultants, executives who travel, remote employees) depend on all-day mobile productivity, the ARM battery will enable these employees to work throughout the day rather than just be a technical figure.  

Using hybrid AI PC local inference on ARM Copilot+ devices removes the dependency on a network for AI functions in the cloud; thus, devices that use local AI inference are more efficient than those that rely on a network to connect to cloud API functions. ARM silicon has improved efficiency through architecture and local processing.  

For hybrid workforce segments who are using extended battery packs, chargers, or additional electrical connections (or facilities) because of their x86 AI PC battery limitations, because of their improved efficiency, ARM will not need these types of support devices, thus further reducing the amount of resources that will be required by IT. In addition, many businesses overlook the importance of these factors when comparing technology specifications, yet they will directly impact the business’s operations and budget. 

Security Architecture Advantages for Enterprise Deployment 

MediaTek and NVIDIA enterprise WoA deployment security architecture benefits from ARM’s memory-safe execution environment and the reduced attack surface that Windows on ARM’s smaller driver ecosystem creates relative to the decades-accumulated x86 driver surface that enterprise security teams must monitor and patch continuously.  

Custom client-side NPU benchmarks for security workload acceleration on ARM Copilot+ devices demonstrate local threat detection inference that endpoint security vendors are actively optimizing for NPU execution behavioral analysis, anomaly detection, and threat classification workloads that previously consumed CPU cycles on x86 endpoints execute on dedicated NPU silicon that leaves CPU resources available for productivity workloads without compromising endpoint security monitoring depth.  

Security agent application compatibility is the primary valid requirement for enterprise ARM deployments (EDR tools, data loss prevention, and identity verification). There are still kernel dependencies that require x86 native execution. These are the main obstacles to deploying NPU performance or battery savings. 

CIO Procurement Strategy for Copilot+ Fleet Rollout 

Segmenting the workforce is necessary before rolling out a CIO’s Copilot+. Employee type (workforce segment), application compatibility, mobility, and the intensity of AI workloads will determine which segments are eligible to deploy ARM (and when), and which will continue to deploy on x86 until gaps are closed. 

An analysis of the total cost of ownership (TCO) should consider three different workforce tiers: 
1. Group 1: Mobile knowledge workers deploying modern applications; qualify for ARM now. 
2. Hybrid workers deploying a mixture of apps require compatibility checks before ARM will be deployed. 
3. Specialized workers (e.g., construction workers, technicians) relying on legacy systems (devices and applications) must remain on x86, regardless of the benefits for other groups deploying on ARM.  

MediaTek, NVIDIA, and enterprise WoA deployment pilot programs that deploy ARM Copilot+ devices to the first workforce tier before full refresh commitment provide the production compatibility evidence that procurement decisions for the second tier require  compatibility issues that affect mobile knowledge workers with modern application portfolios would surface in pilot deployment before they affect the broader fleet commitment. 

Conclusion 

MediaTek and NVIDIA have partnered to move their Work from Anywhere (WoA) enterprise ARM Windows chipset initiative out of experimental status and into formal development. Their combination of NVIDIA’s driver software, MediaTek’s energy-efficient chipsets, and Copilot+ certification now provides solid confidence in enterprise deployment. As Windows on ARM applications become more compatible with one another as they mature, the time gap that once prevented enterprises from evaluating ARM until TCO analyses were performed will close. 

Client-side benchmark testing on purpose-built NPUs has shown that local inference throughput can eliminate API costs associated with fleet-sized deployments in cloud environments. Additionally, hybrid AI PCs using local inference will provide enterprises requiring stringent security with an architecture that does not rely on WAN resources, thereby satisfying their inability to accept such a WAN dependency for completed deployments. TCO modeling for enterprise endpoints, including API cost avoidance, reduced battery infrastructure, and reduced operational expenses, consistently supports comparing Copilot+ to alternative solutions for mobile workers whose application portfolios have passed their compatibility examination. Maturing enterprise AI PC evaluation frameworks for corporate fleet deployments (incorporating NPU performance / local inference economics and total lifecycle TCO along with traditional technology performance comparisons) will provide enterprises with a structurally credible ARM alternative to the x86 architectures that have dominated enterprise procurement for nearly 40 years.

Source: Nvidia Newsroom