San Jose, California 

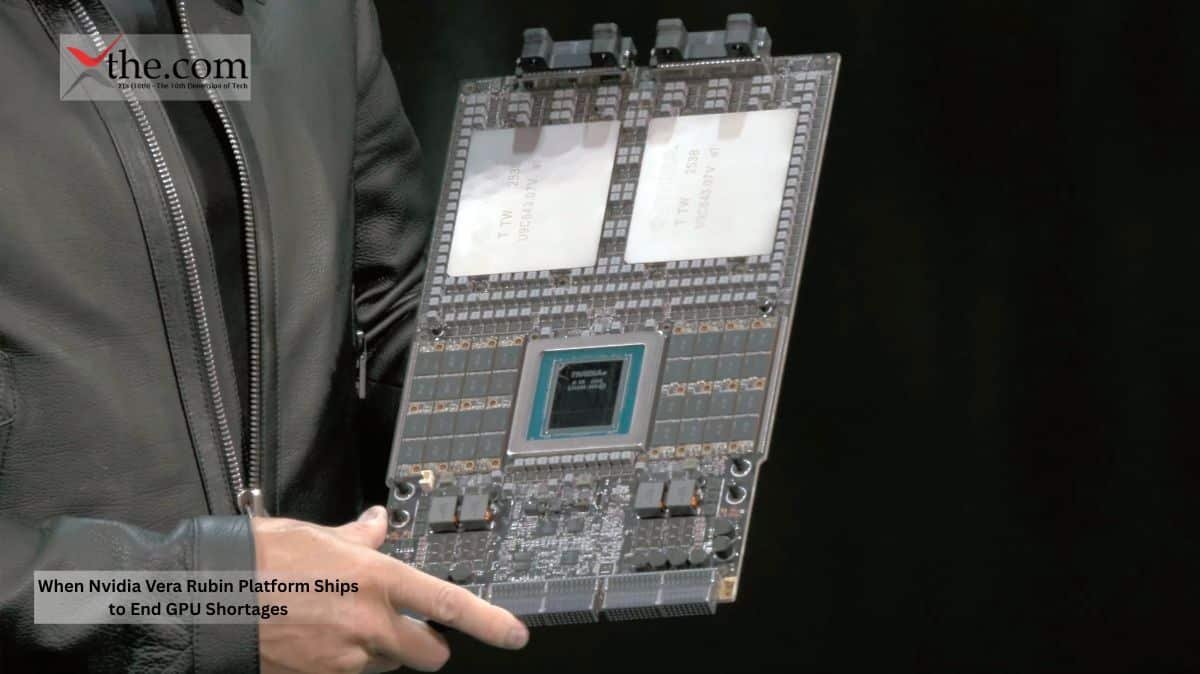
Demand for enterprise-level AI infrastructure is approaching record-highs as companies seek to ensure next-gen computational capabilities before the next shortage cycle drives supply even tighter. With Nvidia’s latest Nvidia Vera Rubin platform emerging as the focal point of that global buying craze, Nvidia’s leadership has issued warnings that demand for that architecture could persist in an undersupply position throughout its lifetime. 

Those warnings come after Nvidia posted one of its best growth quarters in data center revenue, driven by expansion in hyperscale AI infrastructure, sovereign AI initiatives, and enterprise-level generative AI capabilities. The broader AI infrastructure market is also increasingly dependent on advanced networking systems such as Cisco Nexus 9000 800G GPU cluster networking 2026 platforms because modern AI clusters require massive synchronized communication between accelerators.  

Now, enterprises must begin preparing for yet another wave of platform shifts with the introduction of the Rubin architecture and next-gen memory. 

For procurement leaders hoping to know when Nvidia Rubin chips will be available, the answer may lie in future-oriented infrastructure contracts more than ever before. 

Why Rubin Has Created So Much Demand 

The new Nvidia Vera Rubin system is the largest infrastructure upgrade the company has ever made. 

The architecture is likely to deliver significant gains in AI training efficiency, inference speed, and distributed computing capabilities. According to industry experts, Rubin machines may serve as the core of trillion-parameter AI applications and future independent AI ecosystems. 

There are several drivers of the demand: 

  • Increased complexity of AI models 
  • Increased adoption of AI by enterprises 
  • Investments in sovereign AI infrastructure 
  • Inferencing demands 
  • Distributed computing demands 

At the same time, advanced networking technologies like RoCEv2 non-blocking data stream AI training latency optimization are becoming essential because AI workloads increasingly depend on synchronized GPU communication across massive infrastructure clusters.  

That is important because memory throughput has become one of the most significant bottlenecks in AI model training and inference. 

HBM4 Transforms the Equation for Infrastructure 

One of the key upgrades in the NVIDIA Vera Rubin platform is its integration of cutting-edge hbm4 memory subsystem technology. 

High Bandwidth Memory, or HBM, provides significant improvements in data processing speed and lowers the chances of bottleneck formation in distributed modeling processes on AI accelerators. 

Some of the key advancements enabled by the implementation of HBM4 include: 

  • Enhanced memory bandwidth 
  • Quicker model synchronization 
  • Low latency communication 
  • Greater energy efficiency 
  • Improved scalability for AI workloads 

The increased use of HBM4 memory subsystem integration technologies has become especially vital, as frontier AI models today require massive amounts of memory bandwidth to operate efficiently. 

This challenge has also accelerated interest in Cisco 800G high-density fabric packet drop prevention systems because networking stability and memory synchronization are now tightly interconnected in hyperscale AI cluste  

That is one reason why Nvidia’s new platform is being perceived as a generational shift in infrastructure building. 

GPU Shortage Redefining Procurement Approach 

The AI infrastructure industry has been facing acute hardware shortages for the past few years. 

Procurement delays, escalating leasing costs, and the scarcity of accelerators led many businesses to either delay their AI deployments or enter bidding wars to secure infrastructure deals. 

The continued emergence of supply-constrained server hardware ecosystems is set to redefine how companies plan for long-term technology adoption. 

This is because organizations are beginning to focus more on: 

  • Long-term procurement contracts 

Reserved capacity of infrastructure 

Supplier diversification 

Flexible leasing arrangements 

Partnerships for early access 

The upcoming release of the NVIDIA Vera Rubin system is expected to further increase momentum behind this trend, as demand for the product appears to exceed its production capacity. 

Experts predict that future procurement of AI infrastructure will require long-term supplier contracts due to the anticipated shortage. 

NVDA datacenter revenue Q1 2026 growth is yet more proof that enterprises have been ramping up AI spending at an incredible rate. 

The following technologies are being prioritized by companies in a variety of fields: 

  • Generative AI applications 
  • Sovereign clouds 
  • AI-supported automation 
  • Large language models training 
  • Enterprise-level autonomy workflows 

Such heavy spending is driving huge demand for state-of-the-art AI accelerators and distributed computing infrastructures. 

Consequently, Rubin will enter the market during one of the boldest data center expansions in tech. 

Indeed, many infrastructure players are completely rethinking their facilities and architecture based on the requirements of next-gen AI applications, which include: 

  • Increased power density 
  • New cooling solutions 
  • Improved networking fabrics 
  • Enhanced memory capacity 
  • AI-orchestration layer 

Overall, the shift to next-generation infrastructure is changing procurement strategies across enterprises globally. 

At the same time, networking optimization technologies such as Cisco Nexus RoCEv2 RDMA converged Ethernet scheduling are becoming equally important because inefficient networking fabrics can severely reduce expensive GPU utilization rates.  

Supply Constraints Could Be Enduring 

Though production increases have been aggressive, several experts see continued shortage potential for years to come. 

There are a number of reasons that supply constraints are enduring: 

  • Advanced packaging constraints 
  • HBM memory supply issues 
  • Hyperscale demands 
  • Complicated semiconductor manufacturing schedules 
  • Sovereign AI infrastructure initiatives 

The increasing difficulty in determining when Nvidia Rubin chips will be available for purchase is a function of the current environment. 

In some cases, companies are negotiating hardware reservation contracts years down the road to lock up their future AI compute access. 

The ongoing nature of the supply-constrained server hardware market also means that alternative accelerator options are being explored as enterprises look to diversify their infrastructure beyond reliance on a single vendor solution. 

AI Infrastructure Becomes a Strategic Asset for Enterprise 

AI infrastructure is no longer considered standard computing equipment. 

Rather, advanced computing equipment has become a strategic asset for organizations, as it is integral to organizational competitiveness and automation processes. 

Future competitive advantages for organizations could come from: 

  • Access to adequate AI compute hardware 
  • Infrastructure scalability 
  • Memory bandwidth access 
  • Energy efficiency 
  • Procurement resiliency 

Companies unable to acquire enough computing hardware will likely find themselves hamstrung in terms of their development and automation processes. 

This shift also explains rising interest in the broader question of how does Cisco Nexus 9000 800G RoCEv2 scheduling algorithm maintain non-blocking data streams between GPU server clusters to prevent the 50% performance drop caused by packet loss.  

Conclusion 

The coming NVIDIA Vera Rubin platform launch is definitely one of the most significant infrastructural launches in the contemporary era of AI. Given the combination of state-of-the-art HBM4 memory systems and next-gen accelerator systems, Nvidia is gearing up for yet another surge in demand for enterprise AI implementation. 

At the same time, technologies such as Cisco Nexus 9000 800G GPU cluster networking 2026, RoCEv2 non-blocking data stream AI training latency, and Cisco Nexus RoCEv2 RDMA converged Ethernet scheduling are becoming increasingly essential components of modern AI infrastructure ecosystems. 

The rise of GPU cluster 50% performance drop packet loss fix solutions also demonstrates how networking efficiency is now directly tied to the economics of hyperscale AI deployments. 

Organizations seeking information on when NVIDIA Rubin chips will be available for procurement may find the answer depends on future strategic decisions.

Source- Nvidia Newsroom 
San Jose, California 

The rapid development of infrastructure for large-scale AI applications is creating one of the sector’s greatest hidden challenges: network congestion in massive GPU clusters. With ever-larger training systems for developing cutting-edge AI models, organizations are discovering that network latency and packet loss significantly affect computational efficiency, even when the hardware is still fully functional. 

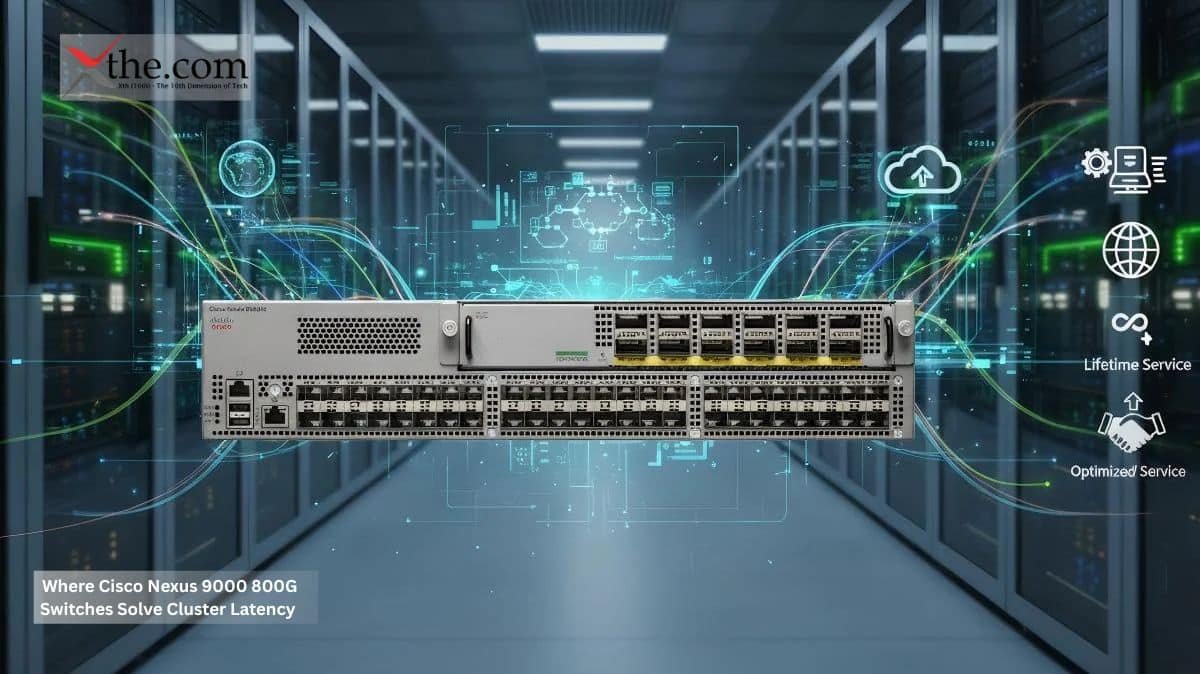
Cisco’s latest introduction of the Cisco Nexus 9000 800 G switches is intended to tackle precisely this kind of infrastructure challenge. The company’s new switching system architecture ensures stable connectivity in large AI clusters, where many GPUs perform calculations while exchanging information. 

At the same time, broader semiconductor trends involving Tesla custom AI chip Intel 14A foundry 2026 initiatives are reshaping how AI infrastructure providers think about real-time processing, distributed computing efficiency, and hardware optimization.  

This makes Cisco’s latest platform a leading candidate for the best switches for massive backend GPU clusters. 

Why AI Clusters Are Running Into Network Barriers 

The traditional networks in enterprises were not designed to handle east-west data flows in the modern AI environment. 

Large language models used for training require a lot of data to be exchanged between GPUs, storage, and computing nodes at very low latency. Any disruption in the process can decrease efficiency. 

Research shows that any packet drops in the AI network can decrease compute performance efficiency by almost half. 

This trend is driving up demand for stronger packet-drop protection in enterprise AI cluster strategies. 

The new Cisco Nexus 9000 800 G system intends to increase stability by: 

  • Increasing throughput 
  • Effective congestion management 
  • Optimized traffic scheduling 
  • Quickly recovering packets 
  • Enhancing synchronization processing 

This will be essential for organizations using thousands of GPUs for AI training purposes. At the same time, the emergence of Tesla FSD sub-2nm silicon neural network edge development highlights how real-time AI processing requirements are influencing infrastructure design far beyond the automotive sector.  

High-Density AI Networking Emerges 

Another critical aspect of the upcoming generation of infrastructure for AI is high density. 

Modern data centers deploy many more accelerators in much less space, thereby making networking more complex. This trend makes high-density fabric data center switching necessary to achieve non-blocking communication within a large-scale computing fabric. 

Cisco’s new approach to architecture emphasizes expanding bandwidth and avoiding communication congestion in hyperscale AI deployments. 

Advantages of high-density fabric data center switching include: 

  • Higher utilization of GPUs 
  • Lower communication latency 
  • Workload balancing improvements 
  • Rapidly distributed training 
  • Improved scaling of infrastructure 

TThe rise of Tesla 14A lead customer automotive chip manufacturing initiatives also reflects the growing importance of optimized communication systems for AI-heavy environments where latency directly impacts operational efficiency.  

RoCEv2 Is Critical for AI Infrastructure 

Among the key technologies that underpin Cisco’s recent switching strategy is the scaling of ROCEv2 network transport. 

RoCEv2, otherwise known as RDMA over Converged Ethernet, enables direct data transfer between server memory units without relying heavily on CPUs. This means reduced latency and improved throughput in a distributed computing environment. 

Scaling RoCEv2 network transport is critical because modern AI training machines generate significant overhead when performing synchronized tasks. 

This helps improve performance by providing: 

  • Low-latency memory access 
  • Enhanced inter-node communications 
  • Improved CPU utilization 
  • Effective synchronization of processes 
  • Increased networking capacity 

The recently released Nexus system from Cisco features enhanced scheduling algorithms designed to optimize RoCEv2 flows from AI workloads. 

These improvements are particularly important for increasingly complex AI environments similar to those required for Tesla FSD architecture real-time processing loop silicon systems where synchronized inferencing and decision-making must occur continuously without interruption.  

Ultra-Low Latency – A Source of Competitive Advantage 

With the global expansion of AI infrastructure, network performance has become a decisive factor in competitiveness. 

In the past, enterprises focused only on accelerator acquisitions and the availability of computational resources. However, today, networking infrastructure plays as big a part in deciding AI training speed as any other factor. 

This phenomenon is well reflected in the emergence of ultra-low-latency hardware fabric infrastructure. 

AI clusters demand: 

  • Deterministic communication latencies 
  • Minimum number of retransmissions 
  • Throughput stability 
  • Quick congestion resolution 
  • High-bandwidth synchronization 

By designing its latest solutions to reduce communication latencies in distributed AI training computations, Cisco seeks to improve the performance of its ultra-low-latency hardware fabric offerings. 

This is particularly critical for frontier AI algorithms that comprise trillions of parameters and require synchronized processing. 

Packet Loss Is Turning Into a Multi-Billion Dollar Issue 

With rising AI training costs, infrastructure inefficiencies are resulting in substantial financial losses. 

Any 1% drop in GPU utilization amounts to millions of dollars in lost operational expenses for hyperscale companies operating large AI training facilities. 

A number of factors can be at fault: 

  • Network congestion 
  • Ineffective buffer management 
  • Poor traffic scheduling practices 
  • Inconsistent sync time settings 
  • Oversubscribed fabrics 

Cisco’s new networking solution aims to mitigate these issues by improving traffic management and dynamic congestion control in large-scale AI infrastructure. 

AI Data Center Design Is Rapidly Evolving 

The rapid development of generative AI is changing how companies design data centers today. 

Priorities in infrastructure planning are shifting from cloud-based hosting architectures to AI-optimized computing fabrics designed exclusively for distributed machine learning. 

This can explain the growing need for state-of-the-art switches for large backend GPU clusters optimized for future AI infrastructure needs. 

Future AI data centers will rely heavily on: 

  • Ultra-wide bandwidth connections 
  • Traffic management automation 
  • Distributed memory optimization 
  • Low latency switching fabric technology. 
  • AI-specific networking protocols 

The evolution of AI hardware ecosystems also raises an important industry question: how does Tesla signing as lead customer for Intel 14A sub-2nm process node impact the real-time processing loop of Full Self-Driving neural network architecture. Cisco’s latest launch of Cisco Nexus 9000 800G aims to establish itself as a leader in this emerging market. 

Conclusion 

The development of Cisco Nexus 9000 800 G systems underscores the growing significance of networking architectures in the AI infrastructure competition. In other words, the optimization of high-density fabric data center switching, rocev2 network transport scaling, and packet drop prevention AI clusters capabilities by Cisco aims to address one of the main operational bottlenecks associated with current AI technologies. 

Since the implementation of distributed AI workloads, network efficiency is no longer secondary in the infrastructure. Ultra-low-latency hardware fabric systems are becoming crucial components of efficient AI model training environments. 

In such a way, organizations searching for the best networking switches for their massive backend GPU clusters should pay close attention to their switching infrastructure in order to ensure the proper functioning of their expensive AI technologies.

Source- Hit the switch and see the light 

Austin, Texas 

Tesla’s most recent semiconductor plan has created waves in the automotive and AI infrastructure industries after it was discovered that Tesla was a key customer for next-gen 14A manufacturing capability. This decision is part of Tesla’s grand vision to build an autonomous driving computer system through a fully vertical supply chain for silicon. 

 Analysts monitoring enterprise AI infrastructure have compared the complexity of Tesla’s onboard systems to large-scale cloud defense frameworks such as Amazon GuardDuty EC2 runtime monitoring SOC 2026 because both rely on continuous behavioral monitoring and real-time response systems.  

Over the last few decades, there have been increasing computational challenges in creating complex autonomous driving systems due to their reliance on increasingly large and fast neural networks. Tesla’s newest hardware product addresses those concerns by creating a specialized silicon architecture for executing AI operations. 

This further heightens industry discussions about the future of silicon used in the design of autonomous vehicles, as manufacturers seek a competitive advantage through computing efficiency rather than battery or manufacturing capacity. 

Why is Tesla Investing in Custom Silicon?Why is Tesla Investing in Custom Silicon? 

Today’s self-driving cars constantly generate immense amounts of data from various sensors. 

All cameras, radars, ultrasound sensors, navigation, and AI inference must operate simultaneously with minimal latency. Off-the-shelf hardware is not very efficient at handling such complex workloads. 

That is why Tesla continues to invest in its custom AI chip design. 

Specifically, Tesla aims at designing hardware that will be optimized for tasks like: 

  • AI inference in real-time 
  • Self-navigation of cars 
  • Fusion of sensors 
  • Decision-making based on predictions 
  • Neural processing on the edge 

Custom silicon offers better control over software optimization, power consumption, and hardware integration than a completely dependent hardware ecosystem built around third-party processors. 

Some cybersecurity experts believe the operational model resembles AWS GuardDuty privilege escalation zero-day block systems because Tesla’s driving stack must instantly identify unsafe behavior before it escalates into catastrophic decision-making. Furthermore, this solution helps the company scale up its infrastructure of a fully self-driving computer cluster used for training AI algorithms. 

Importance of 14A Manufacturing Process 

One of the key points of this new deal is the use of advanced 14A node wafer manufacturing processes. 

Node shrinkage enables higher transistor density while improving efficiency and computational performance. 

It is very important for the case of automotive AI applications. 

The advantages that come with advanced 14a node wafer manufacturing include the following: 

  • Reduced power consumption 
  • Increased neural network performance speed 
  • Decreased heat dissipation 
  • Increased computational density 
  • Inference latency improvement 

All of these factors will have an immediate effect on the performance of autonomous cars, as their AI must process sensor data within milliseconds to keep driving safely. 

Researchers comparing autonomous system security models have also referenced GuardDuty VM process memory crypto-mining detection techniques because Tesla’s onboard systems must continuously analyze active processes while preventing malicious or unstable workloads from affecting driving behavior.  

Foundries Competitiveness Is Rising 

The manufacturing approach taken by Tesla represents a more significant strategy within the semiconductor industry itself. 

In the past, just a few fabrication providers held the keys to new manufacturing technologies. Increasingly, geopolitical uncertainties and the need for AI infrastructure are compelling firms to diversify their manufacturing relationships. 

The arrival of Tesla on the scene as an Intel foundry risk production customer demonstrates increasing confidence in manufacturing ecosystems outside the usual supplier network. 

This trend is important because any disruption to chip availability would delay vehicle production schedules and impact software deployment plans. 

According to industry experts, the relationship between Tesla and its supplier offers several benefits to both firms: 

  • Diversified manufacturing portfolio 
  • Reduced risks from a concentrated supply chain 
  • More control over manufacturing schedules 
  • Higher chances of obtaining silicon in the long run 
  • Added bargaining power while procuring goods 

Similar diversification discussions are taking place in cybersecurity infrastructure surrounding AWS GuardDuty serverless container threat detection and distributed AI monitoring systems.  

Edge Processing is Increasingly Vital For AI 

Autonomous driving systems cannot rely entirely on cloud technology for decision-making. 

There must be fast processing onboard to enable operations without latency. Such needs have led to significant investments in neural network edge-acceleration technologies that enable local AI inference. 

Some of the areas where Tesla’s new hardware design will focus include: 

  • Speed of object detection 
  • Route prediction in real time 
  • Hazard detection 
  • Decision-making processes are autonomous 
  • Sensor synchronization 

Industry analysts have linked these developments to GuardDuty credential exfiltration VPC spread prevention frameworks because autonomous systems increasingly require internal isolation mechanisms that stop compromised processes from spreading across connected environments.  

Such advancements become even more necessary as cars become highly sophisticated devices that perform inference operations continuously while driving at high speeds. 

Economics of Autonomous Vehicle AI Technology Are Transforming 

Fast-changing economics characterize today’s autonomous vehicle AI technology. 

Historically, companies were more interested in economies of scale and batteries. Now, AI performance capabilities have become a critical competitive edge in AI systems. 

The investment in tesla custom AI chip infrastructure by Tesla indicates its understanding of the need for huge computing power in future autonomous cars. 

Tesla’s full self-driving computer cluster system is currently performing big computations on driving data, enabling the training of sophisticated autonomous vehicles. 

The future growth of autonomous fleets worldwide will drive demand for next-generation silicon technology for autonomous cars at an accelerated rate. 

Experts think that future vehicle competition may lie in the following areas: 

  • Inference efficiency of AI 
  • Thermal efficiency 
  • Latency processing 
  • Scalability of neural networks 
  • Edge autonomy 

Another growing concern is AWS GuardDuty privilege escalation zero-day block style protection, particularly as connected vehicles become vulnerable to increasingly sophisticated cyberattacks targeting onboard AI processors.  

Conclusion 

Tesla’s recent semiconductor strategy represents a significant revolution in the technology needed to develop autonomous driving platforms. By actively developing their Tesla custom AI chips through advanced 14a node wafer technology, Tesla appears set to compete fiercely in future AI-based transportation systems. 

By appearing as an Intel Foundry Risk Production customer, the new trend signals the industry’s move towards diversifying semiconductor production and building a resilient supply chain. When combined with advances in edge acceleration for neural networks, these trends might represent a paradigm shift in how autonomous vehicle systems process real-time intelligence. 

As manufacturers compete to develop smarter, safer autonomous systems, next-generation silicon for autonomous vehicles will become one of the major battlefields of the future.

Source- Tesla Blog 

San Jose, California  

In the past, most American data centers used about 5 to 10 megawatts of electricity. Now, NVIDIA’s latest AI campuses talk about power in gigawatts. A single site can use as much electricity as a mid-sized city. This huge jump in demand is at the heart of the NVIDIA‑Iren data‑center partnership, which marks a new stage in the push to build generative AI infrastructure before the power grid reaches its limits.  

In the past, data center executives sought land with strong fiber connectivity and tax breaks. Now, having the right to connect directly to utilities is more important than the size of the land. A property with direct access to substations that can handle hundreds of megawatts can be as valuable as prime downtown real estate.   

The market has changed. The main limits are no longer computer chips, but electricity, cooling water, and transmission infrastructure.  

The Nvidia-Iren Data Center Partnership Changes the Economics of AI 

The NVIDIA‑Iren data center partnership focuses on building large-scale AI computing campuses that use Blackwell GPU systems. Iren, known for its Bitcoin mining infrastructure, already controls large energy‑connected sites in regions with abundant renewable power. NVIDIA supplies the compute architecture. Together, the companies aim to support a multi‑gigawatt cluster deployment that could eventually reach 5 gigawatts in AI capacity.  

This scale completely changes the discussion.  

A typical cloud region might use 300 to 500 megawatts. Building out 5 gigawatts for AI is on the same scale as a utility. Utilities now have to consider upgrading transformers, expanding high‑voltage transmission, adding backup generators, and improving water infrastructure simultaneously.  

This is where the pressure from AI infrastructure power‑grid limits becomes impossible to ignore.  

Northern Virginia is already dealing with transmission bottlenecks because of rapid data center growth. Some areas of Texas struggle to balance power during peak seasons. Arizona and Nevada face water supply issues linked to cooling systems. The growing demand for AI exacerbates all these problems.  

Why Blackwell Clusters Push Electrical Systems to the Edge 

Latest NVIDIA Blackwell racks offer a lot of computing power in a small space. This high density creates tough engineering challenges for operators pursuing aggressive NVIDIA Blackwell cluster scaling strategies.  

One advanced AI rack can use over 100 kilowatts of power. When you multiply that by tens of thousands of GPUs, the total power needed rises fast. A facility running advanced training models might need dedicated substations connected to 230 kV or 345 kV transmission lines, redundant transformer yards, liquid-cooling distribution networks, backup gas turbine generation, and on-site battery storage systems.  

Cooling is just as challenging. Older data centers mostly used air cooling, but Blackwell systems require operators to use direct‑to‑chip liquid cooling and advanced heat-rejection systems, as traditional airflow cannot remove enough heat.  

Now, the conversation about data center cooling capacity goes beyond just HVAC engineering. Water rights, thermal discharge rules, and city infrastructure planning are becoming increasingly important for securing site approvals.  

Imagine a 1 gigawatt AI campus in the Midwest. Even with advanced liquid cooling, operators might need millions of gallons of water each day. During heat waves, utilities have to supply both residential air conditioning and AI clusters that use steady large amounts of power. This quickly adds significant stress to the system.  

Power Access Has Become the New Silicon Valley 

For years, tech companies competed for skilled workers and access to venture capital. Now, they are competing to be close to two substations.  

This change shows why the NVIDIA‑Iron data center partnership is important beyond just NVIDIA. The deal highlights a bigger trend in the infrastructure market. Future AI leaders will need to secure access to energy before they can control computing power.  

Land close to high‑capacity transmission lines has suddenly become very valuable. Old industrial areas with unused utility infrastructure are attracting renewed investor interest. Now, energy developers, utilities, and AI computing companies are working together more often instead of one after another.  

This also helps explain why there is growing interest in small nuclear reactors, on-site power generation, and renewable energy campuses specifically built for AI facilities.  

Now, the main question for operators is whether they can buy GPUs. It is how to secure power capacity for AI data centers before grid connection wait times become too long.  

In some places, getting approval to connect to the utility grid can already take 5 to 7 years. This slow process does not match the fast pace that AI markets require.  

AI Infrastructure Power Grid Limits Create Political and Economic Tension. 

The pressure from AI infrastructure power grid limits extends beyond engineering. It creates political debates as regulators decide whether to prioritize industrial AI campuses or residential growth.  

When a governor approves a multi‑gigawatt AI project, they are also agreeing to new transmission lines, changes in land use, and higher water use. More communities are starting to ask if their local grids should take on the risks that come with private AI expansion.  

At the same time, economic benefits remain difficult to overlook. Large AI campuses create jobs, bring in utility revenues, and add long-term tax income. States that want AI investment know that waiting too long could mean losing billions of potential capital to other places.  

This tension defines the next phase of infrastructure planning. Companies that pursue NVIDIA Blackwell cluster scaling need far more than semiconductors. They also need political support, a partnership with utilities, and reliable energy resources.  

The competition to lead generative AI will not be settled in software labs alone. It will be decided at substations, along transmission lines, and in cooling plants where electricity is the true currency of computing power.

Source: Nvidia Newsroom 

San Francisco, California.  

Expensive semiconductor IPOs are nothing new, but it is unusual for investors to give a ninety‑five billion‑dollar valuation to a company taking on NVIDIA with just one massive chip. The strong response to the Cerebras IPO listing price shows more than just hype. Many large companies are frustrated with the costs and complexity of connecting thousands of GPUs in today’s AI clusters.  

This frustration is why procurement teams at banks, pharmaceutical companies, and government AI labs are now watching Cerebras closely.  

Cerebras is not just offering another accelerator; it is promoting a new way to build AI infrastructure.  

The Cerebras IPO Listing Price Reflects a Bet on Simplicity 

Wall Street was surprised by the valuation implied by the Cerebras IPO listing price, given Nvidia’s dominance in the market. Still, investors see potential in Cerebras’ very different hardware approach.  

Traditional AI training setups connect thousands of GPUs via networks such as InfiniBand. This method works, but it causes problems such as delays, additional synchronization, wasted power, and complex software. Training large language models on these GPU clusters often means having engineers focused solely on workload management.  

Cerebras takes a completely different approach to this problem.  

Its Wafer-Scale Engine hardware architecture places an enormous amount of compute and memory bandwidth onto a single silicon wafer rather than splitting workloads across countless smaller chips. The result is a monolithic processor system designed to reduce node-to-node communications issues that plague large GPU deployments.  

This difference can have a big financial impact on enterprise buyers.  

For example, a pharmaceutical company training protein-folding models might spend months fine-tuning how GPUs communicate before achieving stable performance. Cerebras says its system can speed up deployment because having fewer connected nodes means fewer synchronization problems and less software tweaking.  

This promise directly affects how companies decide which infrastructure to buy.  

Enterprise Buyers Want Predictable AI Economics 

The buzz around the Cerebras IPO listing price also shows that companies are worried about rising operating costs. AI infrastructure expenses go far beyond just buying chips. Firms now have to consider networking, cooling, rack space, power upgrades, and engineering labor.  

This is where enterprise computer cluster procurement becomes increasingly strategic.  

A large GPU cluster with 20,000 accelerators requires multiple networking layers to keep everything running smoothly. Each extra layer adds more power use, cooling needs, and delays. Now, CIOs look at the total cost of running a cluster, not just how fast it can compute.  

Cerebras presents its design as a way to simplify these operational layers.  

The company says that using a single wafer-scale system can make training easier and reduce communication problems that often lead to costly infrastructure upgrades. While it is still debated if this works for every load, the financial argument appeals to procurement officers who need to justify AI spending.  

The discussion around AI training server unit economics, therefore, becomes central to the broader market debate.  

Training costs can rise quickly when companies move from testing to full-scale AI systems. A big multinational running constant inference and retraining can spend millions each year just on electricity. Even small improvements in efficiency can make a big difference.  

Custom AI Silicon Alternative NVDA Gains Momentum 

NVIDIA has stayed on top for years because its CUDA software ecosystem gave it a huge advantage. This ecosystem is still very important, and many enterprise workloads are highly tuned for NVIDIA hardware.  

With demand for a viable custom AI silicon alternative, NVDA continues to grow because enterprises fear dependence on a single infrastructure vendor.  

The growth of Cerebras, Groq, Tenstorrent, and custom silicon projects from big cloud providers signals a broader market shift. Companies now want accelerators built for specific AI tasks, not just general‑purpose GPUs.  

Cerebras gains from this trend because its platform is designed for large‑scale model training, where problems with distributed GPUs are most obvious.  

Take, for example, a government AI project training multilingual foundation models on huge datasets. Traditional GPU clusters require highly complex interconnects to run efficiently at scale. A wafer‑scale system could reduce this complexity by consolidating more computing within a single processor.  

This potential is sparking new interest in alternatives to NVIDIA GPUs for enterprise deep learning, especially among organizations with large infrastructure budgets.  

Compiler Readiness May Decide The Real Winner 

Hardware by itself will not determine whether Cerebras can maintain its momentum after the excitement over its IPO listing price fades. The real challenge is having mature, reliable software.  

NVIDIA has spent years making CUDA the standard for enterprise AI development. Engineers trust it because there are already tools, frameworks, debugging options, and optimization libraries available worldwide.  

Cerebras still has a tough job ahead: it needs to show developers that its computer can handle real enterprise workloads without causing deployment problems.  

This challenge is significant and should not be overlooked.  

Many CIOs say they would like better alternatives to custom AI silicon and NVDA as long as the switch is not too complicated. However, retraining engineers, rewriting optimization processes, and ensuring everything works reliably in production are high risks for large companies.  

This is where the next stage of competition will probably take place, not in benchmark scores, but in software ecosystems and how these systems are actually deployed. The rounding of the Cerebras IPO listing price ultimately reflects a broader truth about AI infrastructure markets. Enterprises are no longer searching only for faster chips. They are searching for systems that reduce operational friction, stabilize long-term costs, and simplify deployment at an enormous scale.  

If, therefore, scale computing can consistently deliver these benefits, the power dynamics in enterprise AI infrastructure could shift faster than most investors expect.

Source: The Future of AI is Wafer Scale 

San Jose, California  

Wall Street was ready for another strong quarter from Nvidia, but almost no one saw numbers this big coming. NVIDIA’s first-quarter financial results 2027 showed revenue of $81.6 billion. That figure quickly changed how corporate boards, hyperscalers, and governments think about AI infrastructure spending. This wasn’t a typical semiconductor earnings report. It was a clear signal about where global tech investment is heading.  

For CEOs who are already having a hard time justifying infrastructure budgets, this quarter sent a clear message: If you delay AI purchases now, you could face much higher costs later.  

Why NVIDIA’s First Quarter Financial Results 2027 Matter Beyond Earnings? 

NVIDIA’s first-quarter 2027 financial results shattered assumptions about the durability of enterprise AI demand. Analysts tracking NVDA revenue Wall Street expectations had already raised forecasts repeatedly over the past year. Even so, the company outpaced consensus estimates by a margin large enough to reset valuation models across the chip manufacturing sector.  

This matters because NVIDIA’s revenue is not simply about GPU sales to a few big companies. Now, the spending is spreading into healthcare, finance, telecom, defense, and government‑led AI projects.  

Ten years ago, companies focused on moving to the cloud and updating cybersecurity. Now, boards are signing off on one‑billion‑dollar AI infrastructure budgets, expecting generative AI to become a core part of their operations.  

Fortune 500 CIOs feel this pressure most when leaders delay major IT upgrades amid the uncertain economy of 2023 and 2024. Now, those delayed budgets are quickly moving toward the purchase of more advanced computing power.  

Blackwell Systems Redefine Procurement Cycles 

The clearest sign in the earnings report was the strong demand for Blackwell systems. Companies are no longer just buying GPU clusters. They are investing in full-scale AI factories. New land. The emergence of Blackwell delivery pipeline tracking has become a significant issue for enterprise purchasers, as delivery schedules now directly impact competitive standing. For instance, major financial institutions are progressively reserving AI capacity 6 to 12 months in advance of deployment.  

This approach looks more like the supply chain strategies used in the energy industry than what’s typical in enterprise IT.  

Rolling out a large‑scale Blackwell system can mean installing tens of thousands of GPUs, special networking, liquid cooling, and upgraded power systems. Procurement teams must manage chip supply, obtain utility approvals, and handle facility engineering simultaneously.  

This is where the wider enterprise technology infrastructure market‑cap discussion becomes relevant. Investors are increasingly valuing infrastructure providers not as cyclical hardware vendors but as long‑term strategic utility platforms supporting AI economies.  

NVIDIA is at the heart of this change because its ecosystem goes beyond chips. It also covers networking, software management, and system design.  

Sovereign AI Sphere Metrics Become a Strategic Defense Layer 

The biggest long-term story might not be about the major cloud providers at all.  

The accelerating growth in sovereign AI spend metrics demonstrates how governments increasingly view AI infrastructure as national strategic infrastructure alongside energy grids and telecommunication networks. Countries across Europe, the Middle East, and Asia are now financing domestic AI clusters to reduce dependence on foreign cloud providers.  

This trend gives Nvidia a strong advantage against one of Wall Street’s main worries: big cloud companies developing their own custom chips.  

Amazon is building Trainium chips. Google is expanding its TPUs. Microsoft continues to invest in Maia accelerators, while Meta advances its own AI chip plans. These moves have made some worry that big cloud companies could rely less on Nvidia in the future.  

But growing government demand for AI changes the situation.  

Most governments don’t have the engineering resources to quickly build their own advanced AI chips. They need ready-to-use systems, proven software, and reliable manufacturing right away. NVIDIA offers all of these.  

As a result, sovereign AI spend metrics increasingly serve as a stabilizing force, supporting long-term demand visibility even as hyperscaler purchasing patterns fluctuate.  

Forecasted Cloud Infrastructure Spending for Big Tech Continues Rising 

The earnings report is reshaping assumptions about forecasted cloud infrastructure spending for big tech companies over the next five years.  

Before this quarter, many investors thought that AI spending by big cloud companies would level off after the first round of deployments. Instead, spending keeps growing. Cloud providers are still racing to lock in computing power before enterprise demand really takes off.  

Think about the challenge for a big cloud provider: a generative AI assistant serving hundreds of millions of users needs to run nonstop, handling constant inference tasks. Unlike search indexing, inference requires significant continuous computing power.  

This reality is driving capital spending into new and unfamiliar territory.  

New data center operators are talking about expanding by gigawatts, installing advanced liquid cooling, and signing renewable energy deals as basic requirements. The impact goes far beyond chips, affecting utilities, construction, networking, and real estate investment trusts.  

The impact on enterprise technology infrastructure market cap valuations could persist for years if AI demand continues expanding at this pace.  

NVIDIA’s latest quarter showed that, beyond strong earnings, the AI economy is moving from small experiments to the construction of real infrastructure. Investors now see AI hardware as essential, much as broadband and cloud computing were in the early 2010s.  

The companies that lock in computing power, energy, and deployment capacity first could lead the enterprise world for the next decade, well before slower competitors catch up. 

Source: Nvidia Newsroom 

Seattle, Washington 

The cloud security operations center is under pressure to address the challenges posed by increasingly advanced, automated attacks on enterprise infrastructure today. Security teams that operate large-scale AWS installations face attacks that can elevate their privilege levels, steal credentials, and launch malicious workloads within the production environment before they can be detected by traditional security tools. 

The expansion of Amazon GuardDuty EC2 runtime monitoring SOC 2026 capabilities aims to address this growing challenge by introducing deeper runtime visibility directly inside EC2 workloads . It offers improved runtime detection capabilities directly on EC2 instances, enabling the organization to detect abnormal activity in the workload before it becomes dangerous. 

The update represents a new trend in the cloud computing market, focusing on defending against cyberattacks by continuously monitoring their infrastructure. 

The increased sophistication of these attacks has prompted companies to wonder what they should do to stop data theft through EC2 instances. 

Why Runtime Monitoring is Necessary 

Conventional cloud security tools typically focus on network traffic, user logins, and other attempts to gain external access. Modern hackers, however, have shifted their focus to operating from a compromised workload after bypassing the company’s perimeter defenses. 

Runtime visibility is hence critical. 

With the current Amazon GuardDuty runtime monitoring features, AWS users can gain insight into the system activities running across their workloads. 

They can now detect: 

  • Active process 
  • Kernel-level activity 
  • Malicious memory execution 
  • Any privilege escalation 
  • Any credential abuse patterns 

The rise of GuardDuty VM process memory crypto-mining detection features is particularly important because attackers increasingly deploy stealth cryptocurrency mining workloads directly inside compromised cloud systems.  

Another effect of the increased sophistication of modern cyberattacks is the need for enterprises to be equipped with more robust tools to protect credentials from exfiltration. 

SOCs Face Operational Challenges 

Security Operations Centers overseeing cloud-based architectures are processing massive volumes of alerts each day. It is difficult for some enterprises to differentiate between actual threats and ordinary activity. 

The new and improved Amazon GuardDuty runtime monitoring platform aims to alleviate this problem by using behavioral analysis and automated threat prioritization. 

This problem is made worse by the fact that the new threats launched against cloud environments include: 

  • Fileless malware 
  • In-memory execution 
  • Cryptocurrency mining in stealth mode 
  • API injector 
  • Lateral movement 

This is because these attacks tend to bypass most monitoring systems since there are no traceable files on the disk. 

The Amazon GuardDuty runtime monitoring, therefore, monitors the actual behavior of processes executing within workloads. 

The platform also strengthens real-time malware signature EC2 runtime scanning AWS capabilities to improve detection of suspicious runtime behavior as attacks unfold.  

Runtime Analysis is Crucial for Containers 

Containerized infrastructure adds a new level of complexity for enterprise cybersecurity professionals. 

In modern clouds, there are often many dynamically orchestrated systems in which containers are constantly created and destroyed. These processes can cause cybersecurity challenges that adversaries tend to exploit more often. 

This is why Amazon has been working to extend its capabilities for AWS serverless container threat detection, along with EC2 runtime analysis. 

Some areas of focus are: 

  • Kubernetes workloads 
  • Serverless services 
  • Microservices 
  • Containers are distributed through several nodes. 
  • Multiregion clouds 

The rise of AWS GuardDuty serverless container threat detection demonstrates how runtime security is evolving beyond traditional virtual machines into highly dynamic orchestration environments.  

Attacks targeting containers usually exploit poorly configured permissions, exposed secrets, or vulnerabilities to gain entry into the wider infrastructure. 

This is why continuous runtime analysis is useful for detecting these threats before forensic investigations take place. 

Credential Hijacking: An Ongoing Problem 

A cloud attack approach that poses a severe risk to businesses is credential hijacking. 

Attackers can quickly move about in the cloud after gaining control of credentials, including API tokens, authentication keys, or high-privilege session credentials. 

As a result, it is no surprise that cloud security technologies have begun focusing on protecting against credential exfiltration. 

The Amazon monitoring engine looks for indications of malicious credential activity, including: 

  • Irregular token activities 
  • Unexpected use of APIs 
  • Strange geographic access patterns 
  • Privilege escalation attempts 
  • High-risk authentication procedures 

These features are crucial since attackers nowadays emphasize stealth and persistence rather than disruptive approaches. 

Security experts caution organizations to ensure runtime behavioral monitoring is in place, given the extended periods during which compromised credentials can go unnoticed. 

Enterprise Cloud Security Optimization 

The rapid growth of artificial intelligence deployments and the adoption of multi-cloud strategies complicate enterprise security operations tremendously. 

This requires improvements in: 

  • Detection speed for threats 
  • Coverage of runtime telemetry 
  • Automation of incident response 
  • Prioritizing vulnerabilities 
  • Visibility in all environments 

The expansion of cloud security posture optimization frameworks represents a significant shift from conventional static security frameworks. 

The recent upgrade to Amazon GuardDuty enables continuous runtime monitoring and anomaly and threat detection. 

Data Exfiltration Attacks Remain Increasingly Threatening 

Cloud-native technology has led to a massive increase in the potential ramifications from active attacks involving data exfiltration. 

It no longer takes system destruction for an attack to wreak havoc. It is now easier to steal confidential data without being detected, with significant financial and legal consequences. 

This is what concerns companies about stopping data exfiltration before they get attacked in other ways. 

The following factors make the matter worse: 

  • Increased cloud storage size 
  • Automated attacks at a rapid rate 
  • Exposure of APIs 
  • Automation threats using AI technologies 
  • Connectivity among services 

This broader challenge also raises an important industry question: how does Amazon GuardDuty EC2 Runtime Monitoring track internal process memory inside virtual machines to block zero-day vulnerabilities and crypto-mining scripts before they spread to adjoining VPCs.  

Conclusion 

The development of runtime monitoring capabilities for Amazon Guard Duty provides a major innovation in cloud cybersecurity practices. The combination of runtime behavioral monitoring, enhanced threat detection capabilities against AWS serverless containers, increased automatic exfiltration credentials protection, and improved malware signature scanning in real time is helping enterprises boost their cloud visibility capabilities. 

The growth of real-time malware signature EC2 runtime scanning AWS systems further demonstrates how runtime security is becoming essential for defending modern cloud infrastructure.With continued focus on cloud security posture optimization, runtime monitoring is becoming increasingly critical for protecting enterprise systems across the cloud. 

As far as stopping active data exfiltration activities from EC2 instances, runtime monitoring will likely play a very critical role.

Source- Amazon GuardDuty 

Armonk, New York 

A number of enterprise-level security experts are beginning to brace for a looming cybersecurity issue that will bring changes to digital infrastructure worldwide, even though it has not happened yet. The problem is about the emergence of quantum computer technologies that will be able to break the encryption protocols securing financial networks, healthcare facilities, military communication systems, and even the cloud. 

IBM’s latest cybersecurity initiative aims to address this challenge through expanded IBM quantum-safe cryptography enterprise storage 2026 strategies designed to secure sensitive enterprise data against future quantum-enabled attacks. This corporation has decided to include post-quantum encryption in its enterprise storage solution to protect information from being stolen in advance, with the aim of decrypting it later. 

It is perhaps one of the major transitions underway in the realm of cybersecurity right now. 

Companies start actively seeking ways to transition to post quantum security within their own networks before it becomes impossible due to outdated protocols. 

Reasons Behind the Increased Risk Associated With Quantum AttacksReasons Behind the Increased Risk Associated With Quantum Attacks 

Current cybersecurity technologies rely heavily on encryption techniques that are very difficult for traditional computer systems to crack. If highly advanced quantum technology is developed, it will be able to break encryption much more quickly. 

This has influenced the decision making process regarding enterprise security. 

Several cybersecurity experts have advised that any data collected by attackers and stored in encrypted form could prove vulnerable even years down the line, once decoded using quantum techniques. 

Some of the industries thought to be vulnerable include: 

  • Financial institutions 
  • Military systems 
  • Hospital systems 
  • Government communications systems 
  • Industrial control systems 

As part of its expanding cybersecurity strategy, IBM is strengthening IBM quantum-safe cryptography enterprise storage 2026 capabilities to improve resilience against both current and future cryptographic threats.  

The approach is geared at enhancing cryptographic solutions capable of providing resistance to classical and future quantum attacks. 

Mathematical Lattices Become the Core of Cybersecurity Infrastructure 

One of the main components of the new IBM cybersecurity program includes the implementation of lattice cryptography algorithms. 

In contrast to conventional encryption methods that rely on factorization, lattice algorithms employ mathematical structures so complex that they are presumed to retain their resilience even in the face of future advances in quantum computing. 

It is because of their advantages, such as: 

  • Greater resistance to encryption over a long period 
  • Increased security in the post-quantum world 
  • Flexibility when implemented in cloud environments 
  • Adaptability to enterprise IT systems 
  • Scalability 

The increasing use of post-quantum lattice mathematics cloud communication systems demonstrates how enterprise cybersecurity is shifting toward quantum-resistant architectures.  

The reason for that is that large corporations operate highly distributed networks, where such a replacement would lead to operational disruption and incur high expenses. 

Enterprise Infrastructure Needs Long-Term Protection 

One of the most significant problems in quantum cybersecurity is protecting long-term enterprise data. 

Some forms of information need to be kept safe for several decades, such as: 

  • Government intelligence databases 
  • Transaction history 
  • Medical files 
  • Intellectual property 
  • Military communication channels 

The current strategy adopted by IBM regarding infrastructure is aimed at enhancing the security posture for post-quantum data. 

The rise of IBM post-quantum sovereign cloud CISO compliance initiatives reflects increasing enterprise demand for cryptographic frameworks aligned with emerging national security and data sovereignty regulations.  

According to IBM officials, waiting until quantum attacks become profitable could mean businesses have already lost valuable data collected years ago. 

Storage and Network Hardening Becomes a Priority 

In addition, IBM is implementing security safeguards across its enterprise storage infrastructure through state-of-the-art hardening capabilities for enterprise storage networks. 

These efforts aim to build infrastructure that can withstand future cryptographic attacks without requiring the reconstruction of existing business environments. 

They include the following elements: 

  • Key lifecycle management 
  • Quantum-safe communication protocols 
  • Data storage encryption 
  • Authentication checks 
  • Data integrity testing 

Enterprise storage network hardening is a topic of growing interest due to the industry’s increasing concerns about the potential vulnerabilities of existing infrastructure to advancing quantum computing. 

The expansion of post-quantum lattice mathematics cloud communication frameworks is also helping organizations secure distributed cloud environments against future cryptographic threats.  

Increased Adoption Due To Sovereign Cloud Regulations 

The other significant reason for the rapid adoption of post-quantum cryptography is the increasing requirement of greater data sovereignty globally. 

Countries are establishing stringent compliance requirements to protect their infrastructure and communications from external threats. 

There has been an increased need for sovereign cloud compliance regulations worldwide, especially for organizations operating in regulated industries. 

Some of the compliance requirements include: 

  • Data localization 
  • Strong encryption requirements 
  • Cloud regulation in compliance with national regulations 
  • Protected cross-border communication channels 
  • Safe long-term archival processes 

IBM’s strategy for post-quantum cryptography aligns well with existing sovereign cloud compliance laws that require stronger cryptographic measures for critical infrastructure. 

As geopolitical dynamics continue to shape technology policies across the world, quantum-resistant security systems can become essential for many industries. 

Migration Challenges That Lie Ahead 

Despite the growing need, shifting to post-quantum infrastructure is a complex task. 

A large number of companies are using old-school systems that rely on outdated cryptographic protocols embedded in internal software systems and storage communication networks. 

This explains the need for a closer look at how companies can migrate their networks to post-quantum cryptography without disrupting their business processes. 

Some of the first measures recommended by industry specialists include: 

  • Listing all the current cryptographic dependencies 
  • Finding out sensitive long-term data 
  • Identifying critical infrastructure systems 
  • Using hybrid encryption systems 
  • Developing gradual migration plans 

This broader strategy directly addresses the growing enterprise concern surrounding how does IBM quantum-safe lattice-based cryptographic standard protect enterprise cloud communication channels from harvest now decrypt later attacks without overhauling local network architecture.  

Conclusion 

In conclusion, the increasing capabilities of IBM quantum-safe cryptography represent a critical step towards the adoption of enterprise cybersecurity strategies to address quantum threats in the future. By adopting more powerful lattice-based cryptography techniques, enterprise storage network hardening processes, and ensuring compliance with sovereignty cloud laws, IBM is positioning itself right at the center of the post-quantum security era. 

However, the issue at hand should not be viewed solely from a theoretical perspective. The increasing adoption of IBM quantum-safe storage network hardening finance gov initiatives further demonstrates how governments and enterprises are prioritizing long-term cryptographic resilience.  

In light of these circumstances, migrating corporate networks to post-quantum security should prove a very lucrative investment for any business looking to future-proof its cybersecurity strategies.

Source- Make the world quantum safe 

San Diego, California 

By launching its own Snapdragon X Elite Gen 2 platform, Qualcomm is raising the stakes in the competition against AI-enabled laptops, creating a processor lineup that will directly go head-to-head with x86 devices.The arrival of the Qualcomm Snapdragon X Elite Gen 2 enterprise laptop platform signals a major industry transition toward devices optimized for AI acceleration, long battery life, and localized inference instead of relying entirely on cloud infrastructure.  

Unlike previous ARM chipsets that failed to meet enterprise-level performance requirements, Qualcomm’s new architecture specifically targets AI workloads to deliver significantly improved energy efficiency and high-throughput capabilities for generative AI software, coding development, and automation tools. 

The growing demand for Snapdragon X Elite Gen 2 battery developer workloads optimization reflects how developers and enterprise users now prioritize sustained AI execution without constant charging requirements.  

New Strategy for AI-Based Laptops from Qualcomm 

The launch of Snapdragon X Elite Gen 2 showcases Qualcomm’s most promising attempt to revolutionize the Windows laptop space by leveraging ARM technology. 

Some key highlights include: 

  • Increased speed in AI inferencing 
  • Decrease in thermal emissions 
  • Enhanced multitasking capabilities 
  • Sustained workloads 
  • Reduced power draw in the background 

Key to this new design is the Qualcomm Orion CPU core architecture, which delivers faster token processing for AI tasks without generating excessive heat. 

This is important considering how today’s AI systems demand sustained computing rather than bursts. 

Typical enterprise work includes: 

  • AI companions 
  • Summarization 
  • Automated workflows 
  • Local language models 
  • Automated productivity 

The growing importance of Oryon CPU ARM multi-agent workflow enterprise efficiency demonstrates how businesses are increasingly relying on local AI orchestration systems to improve operational productivity.  

Resolving the Windows Power Efficiency Issue 

Enterprise laptops have had difficulty achieving a balance between computing capacity and reasonable power consumption for many years. 

Powerful computers tended to produce excess heat, consume excessive amounts of electricity, and require powerful cooling systems under load. 

Qualcomm’s design is aimed at resolving exactly this problem. 

The innovative Snapdragon X Elite Gen 2 computing platform emphasizes low power consumption while delivering enterprise-level results in AI-native computations. 

There are multiple ways of achieving higher efficiency of the system: 

  • Workload orchestration improvement 
  • Improved AI instructions pipelines 
  • Thermal management adjustment 
  • Background activity optimization 
  • Enhanced ARM-based power saving techniques 

All of these techniques prove to be exceptionally important as businesses adopt AI co-pilots on a continuous basis. 

Local multi-agent execution improvements are especially relevant given the growing need for autonomous operation of AI algorithms in multiple productivity tools, collaboration software, and analysis systems. 

These operations require effective workload orchestration techniques due to otherwise rapid power consumption by such devices. 

Moving AI Workloads To the EdgeMoving AI Workloads To the Edge 

The growing use of AI-equipped PCs has prompted enterprises to rethink their infrastructure deployments. 

Before this trend began, there was a preference for using AI through cloud data centers. The cost increase, privacy issues, and latency have driven a greater need for localized inference. 

It is quite evident with the trend of enterprise copilot computing performance procurement. 

Contemporary firms want to purchase laptops that can: 

  • Be able to run offline AI assistants. 
  • Perform local processing of private information. 
  • Lower the cost of cloud computing resources. 
  • Be able to perform inferences in real time. 
  • Work while traveling to maintain productivity. 

These goals are becoming easier to achieve through the Qualcomm Snapdragon X Elite Gen 2 enterprise laptop platform, which enables substantial AI processing directly on endpoint devices.  

Qualcomm officials state that with improved local multi-agent execution efficiency, several AI processes can run without causing battery overheating. 

Integrated Connectivity – Competitive Differentiator 

Another competitive differentiator for Qualcomm’s platform is the company’s expertise in communications. 

While many classic PC chips have limited networking functionality, the Qualcomm Snapdragon lineup comes equipped with built-in cellular hardware edge system capabilities, enabling constant communication in a distributed work environment for enterprise laptops. 

The rise of Snapdragon integrated cellular ARM enterprise Copilot functionality could become especially important for organizations operating highly distributed workforces.  

Specifically, this characteristic will be important for: 

  • Remote workers 
  • Field technicians 
  • Global business units 
  • Systems of AI collaboration 
  • Developers of mobile applications 

The development of an integrated cellular hardware edge solution demonstrates the growing trend towards continuous connectivity among enterprise devices, enabling seamless AI synchronization across both cloud and local infrastructure. 

Continuous connectivity can improve coordination among AI agents by enabling faster synchronization across local and cloud enterprise environments. 

The AI Laptop Race Is Heating Up 

AI laptops are turning into one of the semiconductor industry’s hottest areas of competition. 

Qualcomm has emerged as a fierce competitor among Intel, AMD, Apple, and numerous custom silicon players seeking to control future enterprise computing. 

The growing importance of performance in enterprise copilot computing has intensified the race, as businesses assess laptop performance through the lens of AI acceleration capabilities. 

The considerations of enterprises when equipping thousands of their employees with laptops are: 

  • Battery endurance 
  • Speed of AI inference 
  • Efficiency at managing heat 
  • Integration of security features 
  • Autonomy of the workflow 

That’s why several analysts regard Snapdragon X Elite Gen 2 as a formidable strategic threat to the existing x86 laptop ecosystems. 

As enterprises seek the most battery-friendly laptops available, ARM laptops powered by AI technology will soon emerge as mainstream corporate options. 

Conclusion 

The introduction of the Snapdragon X Elite Gen 2 by Qualcomm marks the start of an entirely new era in enterprise laptop development. The new technology will leverage a more advanced oryon CPU core architecture, improved local multi-agent execution efficiency, and increased cellular hardware edge capabilities, putting ARM laptops on par with enterprise PCs. 

This transition also raises an important industry question: how does Qualcomm Snapdragon X Elite Gen 2 Oryon CPU architecture deliver high-throughput token production for multi-agent business automation without spiking thermal limits on enterprise laptops.  

Those looking for the longest-lasting laptop for developers might find that Qualcomm’s new architecture represents a revolutionary change in the AI laptop market over the coming years.

Source- Qualcomm Newsroom 

Santa Clara, California 

The new Intel Processor release is rapidly transforming the outlook for enterprise laptops through incraeased adoption of AI-friendly computers by corporate entities. With the arrival of Intel 18A Panther Lake AI laptop commercial shipment plans, Intel has introduced a major architectural transition that combines fabrication independence with advanced local AI processing capabilities.  

While earlier Intel laptop models relied on foundry partnerships, the Intel 18A processors are fabricated in-house, giving it greater manufacturing freedom and enabling better control over production schedules and optimization cycles. 

The new processor is thus launching at a time when enterprises prefer local AI execution rather than relying on cloud inference engines. 

The rise of Intel 18A internal foundry enterprise device refresh 2026 strategies further highlights how enterprises are preparing for a new generation of AI-capable notebooks.  

Why the Panther Lake Platform Is a Turning Point 

The development of the Intel 18a Panther Lake platform is not just another step in the processor refresh cycles. This is about Intel’s bid to reassert dominance in high-performance computing, now in the realm of mobile computing, amid the growing need to incorporate AI acceleration functionality in corporate devices. 

The new platform comes packed with many important improvements, such as: 

  • Higher transistor density 
  • Better AI inferencing capabilities 
  • Power savings 
  • Graphics acceleration 
  • Better thermals 

According to Intel’s management, the platform provides nearly 4x faster local AI inference than previous laptop generations, especially for generative AI apps, language models, and Copilot AI software. 

This leap in performance is central to the emergence of Intel Panther Lake Xe2 NPU 4x local AI inference speed advantages within the AI PC segment.  

These NPUs enable laptops to do the following: 

  • Language translation 
  • Image creation 
  • Speech transcription 
  • Copilot AI software support 
  • Multiagent AI workflow 

Such developments illustrate a shift within the industry towards edge AI, where sensitive data need not leave a laptop for processing. 

Changes in Internal Manufacturing Transform the Scenario 

One of the most strategically critical aspects concerning Intel 18a Panther Lake has been Intel’s internal manufacturing control efforts. 

The past few years have seen increased volatility within the semiconductor market. Slow shipments, fabrication difficulties, and political instability have led many firms to rethink their sourcing strategies. 

Intel’s Panther Lake aims to mitigate those issues as much as possible. 

The effectiveness of the rollout will largely depend on Intel Foundry’s Revenue Growth in Q1 2026, as Intel seeks to increase commercial adoption of its ecosystem through direct competition with Asian fabrication powerhouses. 

According to industry experts, there are multiple benefits for enterprises with Intel’s approach: 

  • Predictable supply chain 
  • Decreased reliance on external sources 
  • Shorter product development cycle 
  • Easier inventory management 
  • Increased geopolitical stability 

The transition toward Intel Panther Lake external foundry dependency elimination could become especially important as enterprise demand for AI-enabled laptops continues accelerating.  

It is critical because demand for AI laptop devices is expected to grow rapidly as enterprises implement local AI co-pilots and edge inference models across their infrastructures. 

The growth of the commercial client portfolio 18a project represents yet another step towards Intel’s goal of combining advanced manufacturing processes and the enterprise device ecosystem into a single infrastructure system. 

Xe2 Graphics and AI Loads 

Yet another significant factor behind Panther Lake’s success in capturing industry attention lies in its improved graphics solution. 

This platform features a powerful Xe2 processing core technology that enables substantial advances in parallel and visual processing performance. 

The need for such processing cores is increasing, as today’s enterprise workloads blend graphics and artificial intelligence operations. 

For instance: 

  • Enhanced real-time video editing 
  • AI-aided design processes 
  • 3D modeling 
  • Generative design locally 
  • Machine learning processes 

In addition to enhancing gaming, rendering, and creative software, the xe2 processing cores also deliver lower thermal emissions than other advanced mobile processors. 

This combination of efficiency and AI acceleration further strengthens the appeal of Intel Panther Lake Xe2 NPU 4x local AI inference speed capabilities for organizations adopting local generative AI tools . 

Enterprise Focus on AI-Laptops is Increasing Rapidly 

The quick adoption of generative AI solutions has accelerated the evolution of enterprise laptop purchasing decisions. 

In the past, companies considered factors such as battery life, CPU performance, and security when selecting products. These days, however, the ability to accelerate AI operations has become just as essential. 

Companies seek laptops that can enable them to: 

  • Operate AI assistants on-device 
  • Perform inferencing without an internet connection. 
  • Lower cloud-based cost dependencies 
  • Secure corporate sensitive information 
  • Boost the productivity of staff members. 

This trend accounts for the recent rise in the popularity of researching which CPUs are best to run local AI models. 

The market momentum surrounding Intel 18A corporate laptop IT fast-track refresh schedule initiatives reflects this broader transition toward AI-first enterprise hardware planning.  

Intense Competition in the AI PC Segment Emerges 

The AI notebook sector seems poised to be another of the semiconductor sector’s most intensely contested spaces. 

For example, as competition from ARM, custom chips, and even hyperscaler AI hardware architectures rises, Intel finds itself under growing pressure to respond to threats in the future computing space. 

This evolving landscape raises an important industry question: how does Intel 18A Panther Lake commercial shipments with Xe2 graphics and advanced NPUs deliver 4x local AI inferencing speed to trigger enterprise laptop refresh schedules.  

Industry experts expect the next generation of enterprise computing to involve hybrid approaches, with workloads switching between local devices and cloud-based systems based on factors such as performance or data privacy concerns. 

In this context, products like Intel 18a Panther Lake are vital assets, as they enable significant AI computation on the device without sacrificing portability or battery efficiency. 

Conclusion 

The deployment of Intel 18a Panther Lake processor marks a crucial moment in AI-driven mobile computing systems. The incorporation of self-reliant manufacturing processes, cutting-edge Xeon architecture, and robust integrated neural processing units will allow Intel to compete aggressively in the fast-growing AI PC category. 

Besides the technical implications, the platform is the result of a much more significant change in corporate IT, where efficient AI computing, robust infrastructure, and energy consumption have become key criteria in acquisitions. 

As organizations continue searching for devices capable of running AI workloads locally, the expansion of Intel 18A Panther Lake AI laptop commercial shipment deployments could make Panther Lake one of the defining enterprise notebook platforms of the next AI computing cycle. 

Source- Intel Core Ultra Series 3: The New Standard for Edge AI Robotics