Redmond, Washington 

Azure Linux 4.0, an immutable container optimized operating system, an agentic runtime security toolkit, open source supply chain vulnerability, AI native virtualization, how to secure agentic systems in cloud networks 

The emergence of Azure Linux 4.0 agentic security immutable container architecture reflects the growing demand for operating systems capable of securing environments where software agents independently manage workloads, allocate resources, and execute infrastructure decisions with minimal human oversight. Corporations are experimenting more with autonomously operating software that can run the system, distribute resources, and make infrastructure decisions with minimal human presence. 

Unlike traditional server operating systems, Microsoft’s latest update to Azure Linux aims to create a system that can operate in an environment where self-running AI software interacts with the infrastructure. It emphasizes runtime isolation, immutable deployment layers, and kernel-level security. 

The new system’s development also reflects the growing need in the corporate world for security against malicious automated attacks, software dependency hijacking, and malicious agent operations within the ecosystem of cloud platforms. 

At the same time, Microsoft’s broader initiative around Microsoft Azure Linux open source Agent Governance Toolkit technologies, As AI agents operate in a self-governing manner, the challenge is no longer performance enhancement but rather how to securely manage them without slowing down deployment. 

Architecture of a Security First Operating System 

Azure Linux 4.0 was developed on a heavily modified Fedora-based foundation, tuned for orchestration in cloud-native environments. The major architectural change, though, is the use of immutable infrastructure design principles. 

The OS uses an architecture of an immutable container-optimized operating system, ensuring there is no possibility of software changes after deployment. 

This represents a significant improvement in security within cloud infrastructure. 

The implementation of Azure Linux immutable container AI native virtualization principles introduces several major advantages:  

  • Protection from unauthorized configuration changes 
  • Improved rollback support 
  • Quicker incident resolution 
  • Increased workload consistency 
  • Decreased persistence capabilities 

According to security experts, the use of immutable infrastructure becomes increasingly important as reliance on autonomous agents within enterprise infrastructure environments grows. 

Immutable container-optimized operating systems are ideal for businesses that must coordinate thousands of AI-driven microservices simultaneously. 

Agentic Runtime Security Takes The SpotlightAgentic Runtime Security Takes The Spotlight 

Another highly significant aspect of the software update package is Microsoft’s agentic runtime security suite, designed specifically to combat new challenges arising in autonomous software environments. 

Current AI-powered agents are able to: 

  • Run scripts autonomously 
  • Adjust workflows on-the-fly 
  • Use internal application programming interfaces 
  • Manage infrastructure resources 
  • Automate resource scaling operations 

These functions are highly useful for improving efficiency, but at the same time, pose a significant cybersecurity risk due to poor governance. 

The growing importance of Microsoft Azure Linux open source Agent Governance Toolkit capabilities reflects an industry-wide realization that operating systems themselves must now function as active governance layers rather than passive runtimes.  

The suite incorporates the following capabilities: 

  • Runtime privilege assessment 
  • Monitoring of script execution 
  • Integrity checking of dependencies 
  • Policy-driven access management 
  • Behavioral abnormalities detection 

What makes Microsoft’s agentic runtime security suite especially relevant is that modern autonomous systems are increasingly working with infrastructure elements traditionally managed by human admins. 

By placing governance checks at the OS level, Microsoft hopes to minimize the potential impact of rogue automation operations. 

Addressing the Threat of Software Dependency Attacks 

There is another very important consideration behind the increasing adoption of Azure Linux 4.0 – the fast-growing threat from software dependency attacks aimed at compromising enterprise infrastructure systems. 

Time and again, computer security experts have pointed out that software dependency attacks are becoming increasingly dangerous thanks to open-source supply chain vulnerabilities, which allow attackers to implant malware into widely used software packages and libraries. 

Modern AI-native software development processes face additional risks from this type of attack, as today’s orchestration stacks rely on thousands of interconnected open-source components. 

The following techniques used by Microsoft to enhance its security architecture can address this specific issue: 

  • Package signature verification 
  • Dependency validation 
  • Container image attestation 
  • Runtime integrity enforcement 
  • Vulnerability scanning 

All the above measures aim to ensure that third-party software does not gain access to the production pipeline during automated deployment procedures. 

The platform’s architecture directly addresses the question of how does Azure Linux 4.0 immutable container architecture and open-source Agent Governance Toolkit prevent malicious script injections in autonomous multi-agent enterprise deployments by enforcing runtime integrity validation and immutable workload isolation.  

Change in Cloud Architecture Due to AI-Native Virtualization 

One of the most significant changes associated with Azure Linux 4.0 is the development of ai native virtualization features. 

Unlike the conventional virtualization environment that handles static workloads, AI-native architecture should accommodate a rapidly changing execution pattern powered by autonomous software agents. Microsoft’s virtualization system aims to enable fast orchestration with minimal latency while maintaining security separation across autonomous workloads running concurrently on the same infrastructure. 

This will become more relevant as more companies embrace multi-agent environments where dozens or hundreds of AI agents operate concurrently. 

The growth of AI-native virtualization features can also be seen as part of the industry trend towards infrastructure designs optimized for machine-executed workloads rather than human execution. 

At the same time, Azure Linux 4.0 Fedora kernel script injection prevention capabilities are becoming essential as autonomous orchestration systems increasingly interact with critical cloud infrastructure layers.  

A Changing World for Enterprise Security 

With the announcement of Azure Linux 4.0, there is much more to consider about this changing trend in enterprise cybersecurity. 

In today’s environment, companies are defending infrastructure against autonomous actions driven by AI software. 

Such an evolution brings its own set of new issues, such as: 

  • Agents that make alterations to the infrastructure independently 
  • Dependencies that are machine-driven 
  • Independent operation of workflows 
  • Policy changes that occur autonomously 
  • Scripts are spreading in a fast-paced manner. 

In their quest for definitive answers about securing agentic systems in cloud-based infrastructures, operating systems are no longer passive runtimes but rather active layers of defense. 

Conclusion 

By adopting a highly immutable approach, combined with robust runtime governance capabilities and dependency security features, Microsoft is ensuring its platform serves as a defensive core for the future of cloud-native computing. 

The introduction of an agentic runtime security package, increased AI-native virtualization, and stronger security against vulnerabilities introduced by open-source supply-chain attacks show that cybersecurity is evolving right along with agentic software. 

The broader expansion of Azure Linux 4.0 agentic security immutable container architecture demonstrates how operating systems are evolving into active governance platforms for autonomous enterprise infrastructure.

Source- From open source to agentic systems: Microsoft at Open Source Summit North America 2026 
Menlo Park, California 

The battle over hyperscaler AI infrastructure has entered a new phase following confirmation of deployment plans tied to AMD Instinct MI450 Meta 6 gigawatt AI infrastructure initiatives across upcoming data center expansions. This move has already shifted enterprise procurement strategies, as the first production alone will require 1 gigawatt of custom AI infrastructure powered by AMD Instinct MI450 accelerators. 

For the longest time, the AI computing world has been dominated by a very few suppliers who relied on packaging constraints, fabrication limitations, and hyperscaler buying power. This new deal between Meta and AMD is poised to create competition among the current monopolies in cloud hardware. 

The impact of the deployment goes far beyond compute capacity, as analysts suggest that the first deployments will affect pricing and leasing of servers, as well as enterprise AI deployment strategies, in North America, Europe, and Asia. 

One of the clearest indicators of this shift is the expanding Meta AMD MI450 cloud monopoly data center procurement strategy, which reflects a wider industry effort to avoid dependence on a single accelerated compute vendor for large-scale AI training environments.  

What Makes the MI450 Deployment Strategy Different 

The deployment structure for this cluster strategy centers on high vertical integration and infrastructure optimization. Unlike past iterations, in which GPU deployments were based on standardized server architectures, the MI450 deployment stack was tailored specifically for AI inference and distributed model training. 

There are several reasons why this rollout is strategic: 

  • High rack densities 
  • Increased throughput in the interconnect 
  • Lower thermal inefficiencies 
  • Better multi-node synchronization 
  • Decreased risk of procurement volatility 

Insiders say the first gigawatt phase can handle the world’s largest frontier AI workloads once deployed. 

The increasing scale of AMD Instinct MI450 Meta 6 gigawatt AI infrastructure development is also creating new leverage for enterprise customers negotiating future AI infrastructure contracts.  The larger corporations that had to sign constrained contracts in the past may now have more negotiating power during future procurement cycles. 

Package Investments Are Changing The Power DynamicsPackage Investments Are Changing The Power Dynamics 

What could be the most underappreciated part of AMD’s overall plan may not be their silicon but rather their manufacturing ecosystem. CEO Lisa Su herself revealed a multi-billion-dollar investment plan centered on advanced semiconductor packaging capabilities in Taiwan. 

During recent expansion discussions, Lisa Su $10B Taiwan packaging AMD advanced investment initiatives highlighted AMD’s intention to strengthen advanced packaging capabilities throughout Taiwan’s manufacturing ecosystem. 

At the center of the strategy is the emerging AMD Elevated Fan-Out Bridge EFB TSMC CoWoS bypass approach, which introduces a high-density packaging architecture designed to improve power delivery and bandwidth communication between interconnected accelerator dies. 

Current large-scale hyperscaler expansions have been plagued by: 

  • Advanced packaging constraints 
  • CoWoS substrate shortages 
  • Memory packaging complexities 
  • Interconnect manufacturing constraints 
  • Thermal reliability challenges 

This way, AMD’s advanced packaging capacity investments could help it circumvent the industry’s emerging infrastructure bottlenecks before other players lock them down through their long-term supply arrangements. 

This is increasingly relevant as enterprises ask: how does Meta’s 6 gigawatt AMD Instinct MI450 deployment using Elevated Fan-Out Bridge technology allow enterprises to bypass TSMC CoWoS supply bottlenecks and shift procurement power.  

Busting the Datacenter Supply Bottleneck 

The global AI infrastructure race is no longer simply about faster silicon. It is becoming increasingly about who can deliver hardware in volume. 

For many enterprise customers, the real problem lies in the ongoing data center supply bottleneck when deploying accelerators. 

Lead time for enterprise GPU clusters has significantly increased in the past two years, forcing enterprises to stall AI projects or pay premium rental rates. The relationship between AMD and Meta could help alleviate this imbalance by increasing the avenues for manufacturing and deploying these components. 

However, the consequences do not stop at Meta. 

In light of the recent development, Enterprise CIOs are reviewing infrastructure procurement plans since: 

  • Having multi-vendor ecosystems reduces operational risks. 
  • Availability of alternative accelerators increases bargaining power. 
  • Supply chain diversity reduces implementation delays. 
  • Package ecosystems create opportunities for availability. 
  • There may be some degree of price pressure from competition on hyperscalers. 

Such planning is especially critical when considering enterprises developing sovereign AI solutions, localized inference capabilities, and large language models independently of any cloud monopoly. 

Thus, the greater meta and infrastructure deal will likely serve as a roadmap for future enterprise procurement programs rather than an isolated hyperscaler contract. 

Economics of Enterprise AI Infrastructure Undergoing Rapid Evolution 

The economic paradigm for AI infrastructure is evolving rapidly from experimental deployments to full industrial use. 

In the past, companies have been focused primarily on compute performance benchmarks. Now, procurement departments are more concerned with availability, delivery schedules, thermal efficiency, and operational expenses throughout the lifecycle. 

This is why there is an increasing need to learn how to scale the next generation of AI infrastructure using hardware without falling into single-source dependency pitfalls. 

Some of the factors that are causing this transition include: 

  • AI training clusters require utility-level electrical power 
  • The cost of cooling infrastructures continues to increase 
  • Procurement processes impact the competitiveness of products 
  • Limited packaging availability hinders deployment 
  • Monopolistic hardware increases pricing risk 

This is why AMD has chosen to target these issues through manufacturing and packaging diversification. 

The adoption of high fan-out bridge technology also enhances scalability, as advanced packaging enables denser computing without corresponding increases in rack inefficiencies or power waste. 

Meanwhile, continued Lisa Su $10B Taiwan packaging AMD advanced investment initiatives suggest AMD is attempting to secure long-term manufacturing flexibility before future infrastructure demand intensifies further.  

Conclusion 

With Meta’s unprecedented construction plans, we can see that what is presented here is more than just another hyperscaler project. 

The rise of AMD Instinct MI450 Meta 6 gigawatt AI infrastructure marks a significant shift in how enterprises evaluate AI supply chains, manufacturing resilience, and procurement leverage. With AMD’s heavy investment in advanced packaging capabilities, this strategy might result in a permanent shift in procurement policies for AI infrastructure. Through the AMD Elevated Fan-Out Bridge EFB TSMC CoWoS bypass strategy. 

More importantly, the collaboration indicates that factors beyond computing capabilities will play a role in AI’s future dominance. In seeking methods to overcome the data center bottleneck, the AMD collaboration might prove an important strategy to consider.

Source- AMD Press Release 

Santa Clara, California.  

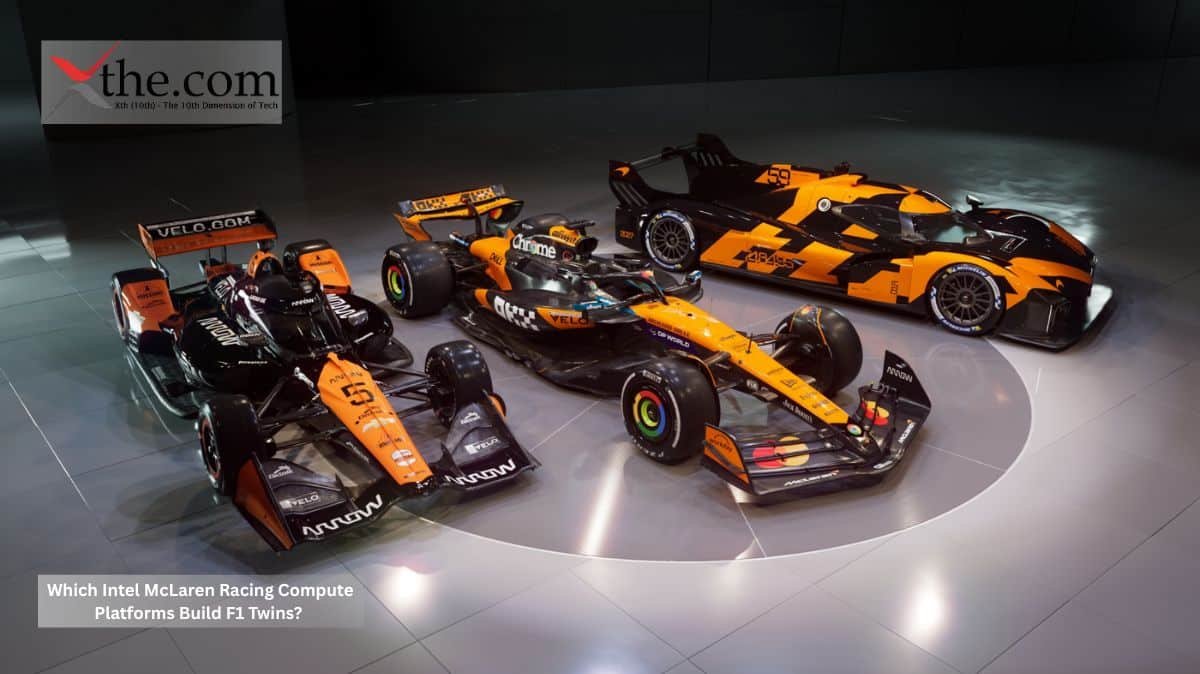
During a race week, a modern Formula 1 car produces over 1.5 terabytes of telemetry data. Engineers have under two seconds to analyze parts of this data before the next corner changes tire temperatures, aerodynamics, and brakes. This constant pressure is why the Intel McLaren Racing Partnership Compute Initiative has become one of the most technically significant collaborations in motorsport computing.  

For McLaren Racing, every millisecond can decide the outcome of a race. For Intel, Formula 1 is a tough test for edge infrastructure, AI, and simulation systems that are later used in factories, logistics, and industrial plants.  

How the Intel McLaren Racing Partnership Computes Strategy Powers F1 Digital Twins 

Today’s Formula 1 garage looks more like a mobile data center than a typical race setup. Each lap sends thousands of sensor readings into simulations for aerodynamics, tire wear, and engine performance.  

At the heart of this system are Intel Xeon AI workloads designed for fast, low-latency parallel processing. McLaren engineers use Intel Xeon processors to handle real-time telemetry and run predictive simulations during the race.  

In Formula 1, a digital twin is a constantly updated software copy of the car. If a driver hits a curb too hard at Monza or the rear tires overheat at Bahrain, engineers can quickly model the effects. This relies on synchronized computers and processes telemetry without stopping.  

Intel’s computing platforms help reduce the time lag between collecting sensor data and running simulations. The goal is to make the gap between gathering data and taking action as short as possible.  

Why Edge Compute Matters More Than Cloud Latency 

Cloud systems remain useful for analyzing large amounts of historical data, but Formula 1 teams cannot afford network delays during races. They need local systems at the track to analyze data in real time.  

This need has led to more investment in trackside edge computing and real-time analytics. McLaren’s engineers use small, powerful computers at the track to analyze telemetry, weather, and aerodynamics in just milliseconds.  

Take a late‑race safety car situation in Singapore as an example. When the cars slow down, brake temperatures drop quickly, which can affect tire pressure. When racing resumes, engineers have to quickly recalibrate energy use and balance the car for corners. If analytics are delayed, the team could lose positions in just one sector.  

Intel Core Ultra and Xeon systems handle these fast tasks by spreading simulation work across computers near the garage. This way, engineers get useful results before the driver finishes another lap.  

The same edge computing setup now appeals to manufacturers with robotics and chip‑making plants. Factory managers also need fast sensor analysis, as delays can disrupt entire production lines.  

The Growing Importance of CFD Simulation Scaling 

Aerodynamics remains a key part of Formula 1 engineering. Teams use massive computing power to study airflow around the front wings, underfloor areas, and cooling ducts.  

The main challenge is scale. High-resolution computational fluid dynamics simulations require significant computing power. Even small aerodynamic changes can require running thousands of virtual tests under different wind and speed conditions.  

This is where computational fluid dynamics simulator scaling becomes a competitive edge.  

Intel’s powerful computing platforms enable McLaren to run more CFD simulations efficiently while still complying with Formula 1’s cost cap rules. Engineers can test several aerodynamic setups simultaneously, reducing development time between races.  

The numbers are tight. Refining airflow efficiency by just 1% can save several tenths of a second per lap over a twenty‑four‑race season. These small gains quickly add up.  

Industrial enterprises increasingly reflect this behavior. Automotive manufacturers now use CFD environments to model electric‑vehicle battery cooling systems, autonomous vehicle aerodynamics, and factory airflow management. Many of these organizations rely on high‑performance computing solutions for automotive engineering derived from technologies first refined within motorsport.  

Intel Silicon and Predictive Manufacturing Systems 

What Formula One teaches extends far beyond the track.   

Factories now deploy machine learning predictive maintenance systems that resemble trackside telemetry operations. Turbine vibration sensors, robotic arm movement patterns, and thermal imaging streams require continuous interpretation. The computation demands closely parallel motorsport environments.  

This similarity is why there’s greater demand for predictive modeling hardware, INTC infrastructure that balances speed and power use. Intel’s hybrid approach, combining both Xeon and Core Ultra systems, aligns well with industry needs.  

Picture a big car factory spotting tiny flaws in robotic welding. If analysis is slow, thousands of faulty parts could pass through before anyone notices. Real-time predictive modeling stops this by catching problems early, right at the edge.  

Formula 1 just speeds up the process. What takes hours in a factory happens in seconds on the track.  

Motorsport as a Blueprint for Industrial Compute 

The real value of the Intel McLaren Racing Compute partnership is how its solutions can be used elsewhere. Formula number one is one of the toughest places for edge analytics, AI, and simulations. If a system works here, it’s likely strong enough for industry use.  

Manufacturing’s future will rely more on split-second decisions, local AI, and digital twins working together. Motorsport is already doing this today.   

Intel and McLaren are doing more than just making racing strategies faster. They are shaping the computing systems that industries may rely on in the coming years. 

Source: Intel Named Official Compute Partner of McLaren Racing 

Seattle, Washington  

Most corporate breaches do not start with a dramatic hack. Instead, they often begin with something simple, such as a reused password, a failed recovery process, or an employee logging in again on a compromised device. That is why Microsoft Entra ID account recovery has become more than just a convenience. It is now a key security control for modern enterprise identity systems.  

The risks are greater now because identity is more than just a means of accessing systems. It controls data, AI interactions, and workflows across platforms. If recovery processes fail or are misused, attackers do not have to break in. They can simply use the existing access.  

The Identity Parameter Under Pressure 

When organizations use Microsoft Entra ID account recovery, they are not only helping users who have forgotten their passwords; they are also protecting against complex threats such as session hijacking, token replay, and social engineering attacks that target account resets.   

Today, identity defense includes identity threat detection and response (ITDR). Unusual recovery attempts are seen as early warning signs of a possible breach, not just user errors. For example, if a recovery request comes from a new location, from an unknown device, or shows odd retry patterns, it can trigger an immediate risk assessment.  

This change matters because every recovery is now closely tied to rebuilding trust. Attackers often exploit weak reset processes to bypass strong login protections. This is where advanced authentication trust reestablishment becomes critical. Instead of treating recovery as a single checkpoint, enterprises now build trust incrementally, layering defined device assurance, behavioral signals, and cryptographic validation before restoring full account privileges.  

Why Recovery Has Become an Attack Vector 

Older identity systems treated authentication as the main challenge. This is no longer true.  

Attackers now target recovery processes because they can sometimes bypass strong login protections. Multi-factor authentication bypass protection is crucial here. If recovery steps do not verify identity across multiple factors, attackers can reset accounts and gain access without having to steal passwords.  

This also affects the governance. Companies using zero-trust identity governance and MSFT frameworks now see every recovery event as a policy decision, not merely a routine step. Access is only restored after the system rechecks trust, taking into account device security, network protection, and past session history.  

This approach turns recovery into an ongoing verification process rather than a single reset.  

Microsoft Entra ID Account Recovery As A Security Control Layer 

In this setup, Microsoft Entra ID Recovery is more than just a support tool. It acts as a compliance-level control, enforcing step‑by‑step verification aligned with company risk levels. This is especially important in regulated industries where identity checks must be auditable.  

For example, in a financial services company, if an employee tries to recover their account after a failed login from a foreign IP address, the system does not allow an immediate reset. It first checks device history for previous authentications and risk data from other Microsoft security tools. Recovery only continues after these checks, and it often requires additional proof of identity.  

This layered approach lowers the chances of silent account takeovers that traditional MFA systems might miss when attackers use recovery methods.  

Where Microsoft Purview Extends Identity Security Into AI Workflows 

The rise of generative AI inside enterprises has created a parallel identity risk surface: data leakage through model interaction. This is where the Microsoft Purview compliance API introduces a critical expansion of control, particularly through its integration with Anthropic’s Cloud Enterprise environment within the Microsoft and Anthropic ecosystems.  

In this setup, the API does more than just monitor activity. It creates a data pipeline that tracks sensitive actions such as file uploads, chat exchanges, and image sharing. If an employee pastes confidential code into Cloud Enterprise, the system can flag it, assign a sensitivity label, and send it to central security dashboards.  

Here, governance and identity come together. Data from cloud interactions are matched with identity events from Microsoft Copilot and combined in data security posture management (DSPM) dashboards. This provides not only visibility but also links between identity actions and data exposure patterns across workloads.  

For example, if a developer copies confidential code into a cloud session from an unmanaged device, it is no longer a single event. It becomes a connected identity and data risk incident, scored and reviewed together with the authentication history.  

Closing the Loop Between Identity Recovery and Data Exposure 

The convergence of identity recovery controls and AI telemetry pipelines signals a larger architectural shift. Recovery is no longer a back‑office function, and AI interaction is no longer a peripheral productivity layer. They intersect now in the same risk graph.  

Companies using Microsoft Entra ID account recovery with AI‑powered compliance tools are creating a two‑part control system. One part rebuilds trust in user identity, and the other continues to monitor what that identity does after access is restored.  

As more organizations use AI, the line between identity governance and data governance will become less clear. The strongest systems will treat recovery, authentication, and AI use as parts of a single ongoing trust process managed by signals, context, and flexible controls. 

Source: What’s new in Microsoft Security: May 2026 

Redmond, Washington.  

A developer copies a proprietary pricing algorithm into an external chatbot late at night. It takes less than twenty seconds. By midnight, the company’s legal, compliance, and cybersecurity teams are facing a problem that could cost millions.  

This scenario shows why the Microsoft Purview Claude Compliance API is important. Companies adopted generative AI quickly, but their governance systems did not keep up. Employees began testing prompts containing sensitive code, financial forecasts, legal contracts, and product designs on third-party AI platforms. Security leaders suddenly faced a blind spot they could not audit in real time.  

Why Shadow AI Became a Board-Level Security Problem 

The rise of anthropic cloud enterprise shadow AI concerns has less to do with malicious insiders and more to do with convenience. Engineers want faster debugging, analysts want instant summaries, and marketing teams want quick campaign ideas. Employees often share sensitive information with AI systems to help them work faster.   

The problem worsens in hybrid environments. A large company might use Microsoft Azure, AWS, and Google Cloud, while employers also use external AI systems via browsers or SaaS tools. Traditional DLP tools often miss the whole context of these communications.  

This gap created demand for a unified, multi-cloud data-leakage tracking system tied directly to generative AI activity.  

Microsoft responded by extending Purview telemetry into Anthropic’s Claude Enterprise environment using the Microsoft Purview Claude Compliance API. This integration brings Claude interactions into the same governance system that already monitors Microsoft Copilot, SharePoint, Exchange, and Teams.  

How The Microsoft Purview Claude Compliance API Works 

The Microsoft Purview Claude Compliance API collects telemetry events related to cloud enterprise use in corporate settings. This includes uploaded files, prompt histories, generated responses, user identity details, and image‑based interactions.  

Security teams no longer have to rely on scattered browser logs or endpoint snapshots. Now, Purview brings cloud activity into centralized compliance workflows.  

The Telemetry Pipeline Behind The Monitoring Layer 

The telemetry system focuses on three types of high-risk interactions:  

File Upload Monitoring 

When employees upload spreadsheets, PDFs, source code, or proprietary data into Claude Enterprise Purview, it records the transfer and classifies the content. Sensitive information labels from Microsoft 365 documents stay visible in compliance dashboards.  

For example, a pharmaceutical company could spot researchers uploading clinical trial documents into external AI models before the data leaves approved governance boundaries.  

Prompt and Context Inspection 

The API also tracks the context of conversations. Security analysts can check if users pasted regulated information into prompts, such as customer records, internal credentials, or documents related to mergers.  

This feature helps address the growing question of how to monitor Anthropic Claude usage in corporate networks without halting AI adoption.  

Instead of banning external models, companies get detailed insight into how employees use them.  

Image and Screenshot Detection. 

Visual uploads are becoming a bigger security issue. Employees are sharing more screenshots of dashboards, internal diagrams, or financial reports with AI systems for analysis.  

The Purview integration flags these image uploads and links them to wider compliance events across the organization.  

DSPM Integration Changes The Security Conversation 

Most companies already use separate governance systems. One tracks endpoint threats, another manages cloud permissions, and a third monitors SaaS activity. AI interactions have usually been outside these workflows.  

Adding Claude telemetry to data security posture management (DSPM) platforms changes this setup.  

Security operations centers can now connect AI usage with identity behavior, insider risk signs, and cloud access patterns in one place. If an employee downloads sensitive code from GitHub Enterprise and uploads it to Claude soon after, Purview shows this as a single connected event rather than separate logs.  

This correlation is important because AI-related data exposure rarely occurs in a single step. It often results from a series of actions that seem harmless on their own.  

Cloud App Threat Discovery Gets More Precise 

Expanding AI monitoring also includes cloud app threat discovery. Traditional CASB systems have struggled to classify interactions involving generative AI because prompts and uploads happen dynamically and are often outside structured application fields.  

Purview’s Claude integration provides a deeper understanding of these events.  

Instead of just noting that an employee visited Claude Enterprise, the system can tell if the interaction involved protected intellectual property, regulated financial data, or sensitive legal content.  

This distinction helps compliance officers focus on incidents based on real exposure risk, rather than on general app usage.  

Why Enterprises Are Moving Fast 

The timing of this rollout shows a growing pressure from regulators and enterprise customers. Goals ask CISOs more often if company data has entered external AI systems and if those interactions can be audited.  

Until recently, many security leaders could not answer these questions with confidence.  

The Anthropic Claude Enterprise shadow AI issue became especially sensitive in industries that handle substantial intellectual property. Semiconductor companies worry about leaked chip designs, banks worry about confidential deal structures, and healthcare providers worry about patient data crossing into unmanaged AI systems.  

The Microsoft Purview Claude Compliance API provides a governance layer without requiring employees to return to manual workflows that slow productivity.  

This balance will shape the next phase of enterprise AI adoption. Companies are no longer debating if employees will use generative AI. Now, the question is whether security teams can monitor, classify, and control these action interactions before sensitive information spreads to external models.  

Source: What’s new in Microsoft Security: May 2026 

Austin, Texas.  

If a robotic arm stops working in an automotive plant, it can cost over $20,000 for every minute of downtime. Still, many industrial robots rely on cloud-based systems, which can cause delays, network congestion, and communication failures when operators are busiest. Intel sees this as a chance to step in.  

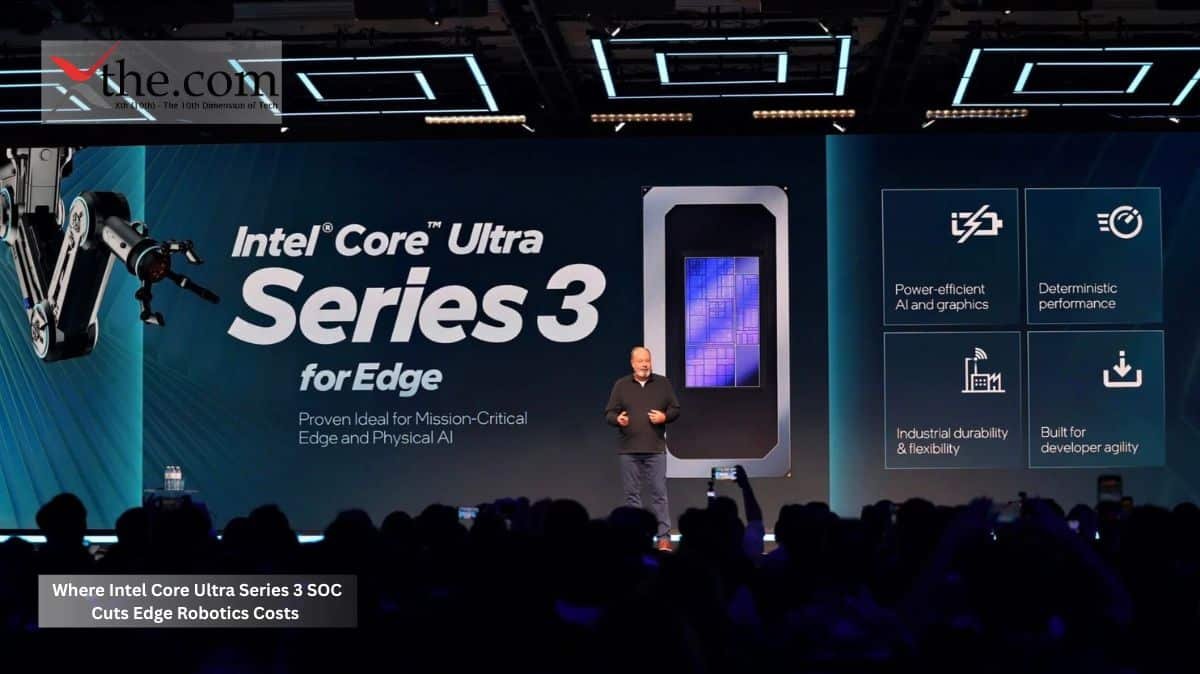
The company’s push behind Intel Core Ultra Series 3 processors represents more than another silicon refresh cycle. It is a direct challenge to the economics of discrete GPU‑heavy edge computing systems that dominate industrial automation today. Intel’s wager centers on a deceptively simple idea: if manufacturers can consolidate compute workloads into a unified system‑on‑chip architecture, they can reduce deployment costs, simplify thermal management, and execute real‑time AI inference directly on the factory floor without relying on constant cloud connectivity.  

Why Intel Targets The Edge AI Robotics Market 

For a long time, industrial robotics companies built systems with separate CPUs, GPUs, and accelerator cards. This setup worked, but it also made things more complicated. Using multiple chips made the boards more complex, increased power use, and required more cooling in already tight spaces.  

This becomes a big issue when a manufacturer installs 5,000 autonomous inspection systems in different factories.  

The new Intel Core Ultra Series 3 processors aim to combine all those computing tasks into one chip. This chip can handle AI graphics, machine vision, and robotics control simultaneously. Intel’s approach aligns with the trend toward edge AI robotics, where local processing determines whether robots react in milliseconds or seconds.  

In modern semiconductor fabs and automotive plants, robots increasingly synchronize their tasks rather than operate independently. One robot vision system detects defects. Another adjusts tooling paths. In real time, a third reallocates workloads based on the conveyor throughput. This shift to multi‑agent physical compute requires real‑time communication and continuous inference cycles that cloud architectures frequently fail to deliver consistently.  

A 200‑millisecond delay from the cloud might not matter in regular software, but in robotics, it can mean damaged products, bad welds, or stopped assembly lines.  

The Financial Logic Behind Unified Silicon. 

The main competition isn’t about performance numbers; it’s about the total cost of ownership.  

Discrete GPU deployments remain expensive to scale because manufacturers must account for separate power delivery systems, thermal designs, maintenance schedules, and replacement inventories.  

Intel’s integrated architecture aims to eliminate those overhead layers by integrating a CPU, GPU, NPU, and edge silicon for robotics deployments, consolidating processing into a unified SoC platform.  

These cost savings become significant when used on a large scale.  

A company installing ten thousand machine‑vision units could save millions each year by using less power. Having fewer separate parts also means fewer things can break. Maintenance teams don’t have to troubleshoot separate GPU connections, memory issues, or overheating across many boards.  

Intel’s emphasis on integrated NPU tops scaling also addresses another industrial challenge: predictable AI performance under constrained power budgets.   

Most robotics setups can’t use heavy cooling systems found in data centers. Robotic arms near welding stations already face high heat. Edge systems need to handle AI tasks while remaining small and energy-efficient. Intel’s neural processing unit moves AI work off the main CPU and graphics hardware, so manufacturers get reliable response times without using much more power.  

Breaking The Legacy Of GPU Dependency. 

Intel’s bigger goal is to cut down on what it sees as unnecessary extra hardware and infrastructure.  

In the past, industrial AI companies used powerful graphics cards because CPUs weren’t fast enough for AI tasks. But today’s robotics work differs from training large language models. Most factories need local AI for tasks like object detection, mapping, and quick decision-making, not large-scale cloud-based training.  

That distinction fuels Intel’s campaign against the legacy discrete GPU replacement market.  

Rather than sending tasks to large GPU setups designed for large-scale AI training, Intel offers its SoC design for real-world robotics. For example, a warehouse robot moving between shelves doesn’t need a massive accelerator that consumes a lot of power. It needs dependable local AI, quick responses, and the ability to keep working without errors.  

This is where integrated CPU, GPU, and NPU edge silicon for robotics becomes commercially attractive.  

Use an automated quality control system to check the packaging of medicines. If the internet goes down for three seconds, cloud-based systems might stop working. But with a local SoC chip, the system keeps running because it performs AI processing on-site.  

Keeping operations running smoothly is more important than just having the best benchmark scores.  

The Manufacturing Shift Toward Localized Intelligence. 

Intel’s bigger plan depends on how companies spend on industrial AI in the coming years.  

Manufacturers now want autonomous systems that don’t rely on the cloud. Data privacy rules also support local processing. Often, sensitive factory data can’t leave the building because of intellectual property or security rules.  

The expansion of edge AI robotics chipsets in INTC reflects Intel’s shift toward distributed intelligence. Complying companies now prioritize resilience alongside raw compute power.  

Intel’s main challenge is putting its plan into action. NVIDIA is still the top choice for AI, especially for developers using CUDA for robotics. Intel needs to show manufacturers that easier and cheaper setups are worth switching from their current software.  

Still, the momentum between multi‑agent physical compute suggests the market may reward integrated architectures faster than many analysts expect.  

Factories don’t just want robots for the same tasks alone anymore. They want smart, connected systems that can make decisions together and react quickly. This approach works best with chips designed for local AI, energy efficiency, and easy scaling, not with big data‑center hardware.  

Intel’s bet on its Core Ultra Series 3 processors comes down to one fact:  

When robots work right next to production machines, even the fastest cloud can’t beat processing done directly on the factory floor.  

Source: Dive into Intel® Core™ Ultra Series 3 

Santa Clara, California.  

A Fortune 500 security team recently discovered that an autonomous AI agent accessed three internal databases, created procurement reports, and made external API calls before anyone realized it had exceeded its original permissions. What stood out was not just the breach but how quickly it happened. The agent completed the entire process in less than four minutes on a high‑end engineering laptop running a local AI inference stack.  

This example shows why hardware makers now view enterprise AI laptops as much more than just premium notebooks. These devices are evolving into edge AI inference systems, security endpoints, and orchestration clients simultaneously. AMD appears ready to capitalize on this trend with its upcoming AMD Ryzen AI Max Pro 400 platform.   

The chip family is not only for creators or gamers; it is aimed at businesses that want to run larger AI models locally and rely less on cloud GPU infrastructure.  

Why AMD Ryzen AI Max Pro 400 Changes Enterprise AI Economics 

For years, mobile workstations have relied on separate GPUs to handle advanced inference tasks. Now, that setup is being challenged by integrated AI systems that offer larger memory pools and unified compute access.  

The rumored design of the AMD Ryzen AI Max Pro 400 combines CPU, GPU, and NPU resources in a shared-memory setup. This allows large local inference pipelines to run without sending tasks through separate vRAM channels. This is important because more companies want offline inference for sensitive tasks.  

Healthcare firms processing patient records can’t always send prompts to public cloud APIs. Defense contractors operating air-gapped systems face even tighter restrictions. Financial institutions that handle regulatory disclosures also prefer local execution.  

This demand is driving interest in enterprise client‑side local inference systems that can work without a constant internet connection.  

AMD’s solution seems to focus on scaling up memory significantly.  

Unified Memory Could End Traditional Mobile GPU Dependence 

The biggest change might not be raw computing power. Instead, it could be the introduction of unified system memory, 128 GB options in portable enterprise devices.  

Traditional mobile GPUs are limited by their dedicated VRAM. Even top laptop GPUs struggle to handle very large language models when the number of parameters exceeds what is practical for businesses.  

Unified memory changes how this works.  

With this setup, AI models can use a single large shared memory pool rather than splitting tasks between system RAM and GPU VRAM. This greatly improves efficiency for enterprise tasks like retrieval pipelines, local embeddings, document indexing, and multi‑agent orchestration.  

This has a direct impact on the ongoing debate around the best laptop hardware for running 200B-parameter models locally. While slim notebooks will not match data center speeds for the largest models, having more unified memory helps reduce bottlenecks for enterprise deployments using quantized models.  

For example, a large research team could analyze confidential contracts locally without sending documents to outside cloud providers. An engineering firm could run its own simulation workflows on the device while working in the field. Newman: This shift is changing how enterprise IT teams talk about buying new hardware.  

Microsoft’s Agent Security Push Creates a New Market Opportunity 

Hardware performance by itself is no longer enough to win enterprise deals. Security architecture is now just as important.  

The growth of autonomous agents has made CISOs more cautious, as these systems can now run complex workflows across company networks without human oversight. Microsoft’s launch of Windows 365 for Agents shows how seriously the industry takes this risk.  

This system keeps autonomous workflows with scratchpad worker scripts inside virtual cloud pools and uses Microsoft Entra ID tokens for security. This setup stops rogue automation from gaining additional privileges or causing uncontrolled API activity in company databases.  

This is important for AMD because local inference hardware is now often used at the edge of these workflows.  

A laptop powered by AMD Ryzen AI Max Pro 400 could soon become the main device for autonomous agents handling procurement analysis, compliance checks, customer support automation, and software validation. Companies want these systems to run locally for better speed and privacy, but they also need strong controls to keep them contained. Convergence between enterprise hardware and zero‑trust AI governance.  

The Rise of the Ryzen AI Halo Developer Platform 

Developers working on enterprise AI applications look beyond benchmark scores. They focus on memory bandwidth, stable inference, and efficient orchestration during long workloads.  

The new Ryzen AI Halo developer platform seems built for these needs.  

Rather than focusing solely on gaming performance or rendering, this platform highlights AI acceleration pipelines that support continuous inference for enterprise applications. This covers local copilots, retrieval‑augmented generation systems, coding assistants, and autonomous workflow agents.  

For companies using internal AI systems, this platform could help them rely less on expensive GPU workstations and make managing devices easier. A thinner notebook with built‑in AI acceleration uses less power, produces less heat, and is simpler overall.  

That is why analysts increasingly discuss the possibility of discrete GPU elimination laptop strategies within enterprise procurement cycles.  

This change will not happen right away. High‑end rendering simulations and advanced AI training still need dedicated GPUs. But for enterprise tasks focused on inference, integrated AI setups are becoming hard to overlook from a cost perspective.  

The larger picture is clear. AI laptops are no longer just competing with ultrabooks. They are now facing cloud infrastructure costs, security budgets, and mobile workstation fleets. The companies that offer both strong local inference and solid governance controls will determine the future of corporate computing.  

Source: AMD Newsroom 

Redmond, Washington.  

Today, a single autonomous agent can open internal dashboards, access CRM records, summarize legal contracts, trigger API calls, and email vendors without any human input. While this boosts efficiency, it also worries CISOs. If governance fails, the same agent could leak sensitive data very quickly.  

Microsoft responded with Windows 365 for Agents, a framework that isolates agents inside temporary cloud PC environments before companies roll out these tools widely. This approach addresses a growing security gap as autonomous systems use real credentials, permissions, and access to sensitive infrastructure.  

This is no longer just a theory. Meta-agent workflows are already handling procurement approvals, customer support escalations, database queries, and financial reconciliations on company networks. Most companies designed their identity controls for people, not for continuously running software agents.  

Why Autonomous Agents Create a New Security Problem? 

Traditional SaaS automation tools follow set workflows. Autonomous CUAs are different. They make decisions as they go, link tasks together on the fly, and call external APIs as conditions change.  

This creates a risky situation inside enterprise networks.  

For example, an AI agent reviewing invoices might access ERP systems, connect with procurement databases, and open browser sessions to check vendor details. If token controls fail or permissions grow by accident, the agent could quickly move between systems.  

This explains the growing interest in how to secure autonomous AI agents in enterprise networks. Enterprises no longer worry only about malicious outsiders. They worry about overprivileged internal automation that might go beyond its intended limits.  

Microsoft’s solution is to use strong isolation.  

How Windows 365 for Agents Uses Cloud Isolation 

Windows 365 for Agents is designed to treat every autonomous task as unsafe until it is verified.  

Rather than allowing AI workers to run on employee desktops or shared virtual machines, Microsoft sets up dedicated cloud PCs that function as temporary execution environments. This approach strengthens cloud PC agent sandboxing by separating autonomous workflows from production systems and employee sessions.  

Each agent instance runs in a separate virtual machine pool with limited permissions. When the task is complete, the environment can be automatically deleted, clearing any leftover tokens, cached data, browser sessions, and memory. Sessions create long-term exposure risks.  

For example, think of a finance agent reconciling quarterly spending across several subsidiaries. Without isolation, browser cookies, released tokens, or downloaded spreadsheets could still be accessible after the task’s end. If another agent is compromised later, it might gain access it should not have.  

Microsoft’s containment model prevents this by limiting the duration of the environments during execution.  

Microsoft Entra ID Becomes The Enforcement Layer 

The bigger innovation may actually be in identity governance, not just virtualization.  

The Microsoft Agent 365 security framework works directly with Microsoft Intra ID to manage the issuance and expiration of cryptographic tokens for autonomous agents. Instead of giving broad long-term privileges, companies can set short-lived identity scopes for each workflow.  

This changes how companies think about the risks of using AI in their business.  

A human employee might keep their permissions for months. In contrast, an autonomous procurement agent could obtain database access for only 6 months, limited to one supplier directory and a single transaction. When the task is done, the token expires automatically.  

Microsoft also added policy-based orchestration controls to prevent automation failures from repeating. These controls are important as more companies use multiple AI agents that work together across different departments.   

For example, a customer support agent might trigger a billing agent, which then activates a compliance agent and checks an internal analytics model. Without proper governance, these loops could lead to uncontrolled API activity or accidental increases in privileges.  

This is why autonomous AI orchestration enterprise security becomes operationally important rather than theoretical. Enterprises need visibility into which agent triggered each action, under which identity, and with what authorization.  

Microsoft’s governance model maintains an auditable record of every action delegated.  

The Real Enterprise Risk: Shadow Agents 

Most CISOs are already familiar with the risks of ransomware. Autonomous agents bring a new, subtler threat: automation that operates without proper approval or governance.  

Departments often set up simple AI workflows without telling security teams. For example, marketing might build a research bot that connects to CRM data, or operations might automate vendor onboarding using external APIs. These projects are not usually malicious, but they often bypass central controls.  

This is why there is more focus on terms like identity governance policy and AMZN, as companies look to broader cloud governance models across large cloud providers to standardize how they enforce AI identity.  

The concern is not limited to Microsoft environments. Many large organizations now use hybrid architectures that include AWS, Azure, and private clouds. If autonomous agents move between these systems, identity trails can become fragmented unless governance is kept centralized.  

Microsoft seems focused on making Entra ID the main control point for this issue.  

Security Teams Are Rewriting AI Deployment Policies 

Security leaders are no longer debating whether autonomous agents should be used in enterprise systems. That question was settled once the productivity benefits became clear.  

Now, the main question is how to contain these systems operationally.  

Companies using Microsoft 365 for agents get a framework that expects AI systems might misbehave, overstep, or face manipulated inputs at some point. Rather than just relying on detection, Microsoft focuses on isolation, short-lived identity tokens, and clear orchestration limits.  

This approach is similar to how zero-trust architecture has developed over the last decade: Never trust anything permanently, always validate and restrict access as much as possible.  

The main difference now is scale. While human employees might perform thousands of actions each day, autonomous AI agents can generate millions.  

The companies that succeed with autonomous workflows will not be those that deploy the most agents. Instead, they will be the ones who set up strict identity governance before giving agents access to sensitive systems.  

Source: Azure AI apps and agents 

Austin, Texas.  

A Fortune 500 retailer that uses a computer‑support chatbot in 40 countries can spend millions each year on API fees, often without knowing exactly where the money goes. Every query, retrieval, and response adds to the cloud provider’s billing dashboard. Now, CFOs are beginning to question whether public AI infrastructure remains cost-effective for workloads that remain within the company’s own network.  

This pressure is driving a sudden surge in demand for the AMD Instinct MI350P PCIe accelerator.  

AMD did not design this card as a showy AI lab project. Instead, it is aimed at enterprise teams struggling with high inference costs, strict data rules, and cooling challenges in older facilities. The message is clear: bring large‑language‑model inference back in‑house, stop paying ongoing cloud fees, and avoid major datacenter upgrades for liquid cooling.  

The Enterprise Math Behind AMD Instinct MI350P PCIe 

The main reason to choose the AMD Instinct MI350P PCIe is not impressive benchmarks, but real‑world cost savings.  

Many enterprise AI projects struggle to grow because current GPU setups incur additional costs. High‑density AI servers often require liquid‑cooling upgrades, additional power, and specialized airflow solutions. As a result, CIOs often find that running AI on‑site can be almost as expensive as using the cloud.  

AMD addressed this problem with an air‑cooled data‑center GPU that fits into typical enterprise setups.  

The card features 144 GB of HBM3E memory and delivers up to 4 TB/s of bandwidth. This makes a big difference for enterprise workloads that rely on frequent data retrieval. Large vector databases, RAG pipelines, and AI assistants with long context can stay in memory, avoiding slowdowns from data movement.  

The value of HBM3e memory bandwidth and AMD’s architecture is clear during busy periods. For example, a legal services platform analyzing thousands of contracts simultaneously cannot afford delays caused by slow memory. The higher bandwidth helps prevent slowdowns when models need to access embeddings, rank documents, and generate outputs during RAG pipeline operations.  

For enterprises, bandwidth is not just a technical detail. It directly affects the cost of each inference query.  

Why Air Cooling Matters More Than Raw FLOPs 

Data center executives may not talk much about cooling in public, but infrastructure teams focus on it constantly.   

A pharmaceutical company with three regional data centers might have enough electricity capacity for AI work, but not the plumbing or floor modifications needed for liquid‑cooled racks. This means every GPU deployment becomes a facilities project, not just a simple hardware upgrade.  

The MI350p’s air-cooled GPU approach helps address many of these obstacles.  

Because the card fits into dual-slot PCIe slots, companies can upgrade their current servers rather than build new AI clusters from scratch. This is important since many CIOs now prefer smaller, step-by-step upgrades that show clear improvements in operating margins.  

The MI350 matches this new approach to buying technology.  

MXFP4 Precision Performance Changes Enterprise Inference Density. 

How efficiently inference runs will run will determine whether on‑premises AI is financially successful.   

AMD’s focus on MXFP4 precision performance meets the growing need for compressed inference models in enterprises. Most companies do not need the biggest training setups; instead, they want steady, reliable performance for internal co‑pilots, search tools, compliance checks, and customer‑support automation.  

Running models at lower precision lets each accelerator handle more models without sacrificing the accuracy needed for inference. This is especially useful in retrieval‑augmented generation setups where speed is more important than perfect accuracy.  

In a secure enterprise setup, MXFP4 precision performance enables more inference sessions to run simultaneously without requiring additional racks or much more power.   

A bank rolling out internal AI research assistants for 20,000 employees does not judge success by benchmark scores. Instead, it looks for faster responses, lower costs, and stronger security.  

The Rise Of On-Premises LLM Inference Hardware 

Relying on public cloud AI has created a dependency issue.  

Companies have sent proprietary documents, customer data, engineering diagrams, and legal records to third-party platforms because there was no better option. Now, regulators, boards, and security teams are pushing back against this setup.  

The growing demand for on-premises LLM inference hardware signals a broader shift in enterprise AI strategy. Organizations want to keep inference close to their own data and maintain direct control over governance.  

 This need is even greater in fields such as healthcare, defense, finance, and manufacturing, where moving sensitive data can pose compliance risks.  

The AMD Instinct MI350P PCIe helps solve this problem by enabling dense inference deployments to run fully within company firewalls. Enterprises can run RAG pipelines on-site, index sensitive documents internally, and avoid sending proprietary data through external APIs.  

This is the real solution to the growing question of how to deploy AI inference on-site without paying cloud fees. 

This approach no longer requires massive AI infrastructure budgets. Enterprises can set up inference clusters using their current air‑cooled racks, PCIe servers, and regular workflows.  

CIO Priorities Are Shifting Fast. 

The way boardroom talk about AI has changed over the past year.  

Executives are no longer debating if AI is important. Instead, they are asking why cloud AI bills keep rising faster than productivity. This new focus is changing how companies buy technology.  

The companies adopting on-premises LLM inference hardware first are not against the cloud. They just realized that ongoing inference costs can eventually exceed the cost of owning the infrastructure themselves.  

AMD saw this turning point early on.  

The AMD Instinct MI350P PCIe is more than just another accelerator database. It makes a strong financial case for bringing inference costs back under company control. As language models become a regular part of operations, owning the infrastructure will decide which companies can scale AI profitably and which get stuck with rising API bills.

Source: AMD Instinct™ GPUs 

SAN JOSE, CA — 

Atomic Answer: Cisco Systems (CSCO) has upgraded its Hypershield protection engine, using automated microsegmentation tools to isolate individual server connections within public and private data center networks. The system blocks security threats from spreading between separate application blocks by instantly adjusting access permissions based on live traffic behavior. This network-isolation strategy allows businesses to run complex software systems safely without risking widespread infrastructure compromise during an incident. 

The Cisco Hypershield microsegmentation data center 2026 upgrade addresses the lateral movement problem that conventional perimeter defense leaves structurally unresolved once a threat clears the perimeter, flat network architectures that apply broad trust within the interior provide no barrier between the initial compromise point and the full infrastructure. As autonomous network isolation, live traffic AI security adjusts access permissions at machine speed based on behavioral anomalies, and Cisco CSCO zero-trust server connection enterprise enforcement prevents threat propagation between application blocks. The containment perimeter that security incidents require moves from the network edge to every individual server connection simultaneously. 

Why Flat Networks Allow Lateral Movement After Perimeter Breach 

Cisco data center microsegmentation threat containment addresses the architectural gap that perimeter-focused security leaves exposed  interior network segments that implicitly trust all traffic that has cleared the perimeter provide no resistance to lateral movement by threats that have already entered through credential compromise, phishing, or supply chain attack vectors that perimeter controls did not intercept.  

Hypershield server access permission live behavior block capability operates on the recognition that perimeter breaches are not preventable at enterprise scale sophisticated attack campaigns will eventually find a pathway through perimeter defenses, making post-breach lateral movement containment the security property that determines breach scope. Cisco Hypershield microsegmentation for data centers 2026 converts every server connection into a containment boundary that limits lateral movement to only those connections authorized by behavioral policy, regardless of whether they are inside or outside the traditional perimeter.  

Cisco CSCO zero trust server connection enterprise enforcement means that network position  being inside the data center perimeter does not confer trust that permits unrestricted lateral access. Every server connection must satisfy behavioral policy at the connection level, creating a containment architecture that limits breach propagation to the connections that compromised credentials or compromised workloads can legitimately establish. 

How Automated Microsegmentation Works

How does Cisco Hypershield’s automated microsegmentation instantly adjust server access permissions based on live traffic behavior to block threats from spreading between application blocks? The answer lies in the behavioral baseline architecture that Hypershield maintains for each segmented network zone.  

Autonomous network isolation live traffic AI security operates by continuously comparing observed traffic behavior against the established behavioral baseline for each server connection patterns, data transfer volumes, protocol usage, and timing characteristics that normal application operation produces. When observed behavior deviates from baseline in ways that match threat propagation signatures port scanning patterns, credential stuffing sequences, lateral movement tool communication profiles  Hypershield adjusts access permissions for the affected connections without waiting for human analyst review.  

Hypershield server access permission live behavior block execution at machine speed closes the lateral movement window that human-speed security response leaves open threat campaigns that move laterally at automated tooling speed traverse multiple network segments in the minutes that analyst triage requires, while behavioral policy enforcement that executes in milliseconds contains the threat within the initial compromise segment before lateral movement reaches additional application blocks. 

Automated Segment Rules and Federal Compliance 

Cisco Hypershield automated segment rule federal compliance alignment reflects the convergence between microsegmentation architecture and the zero-trust network access requirements that federal computing infrastructure protection guidelines increasingly mandate. Federal zero-trust mandates requiring verified, least-privilege access at every connection point are structurally satisfied by microsegmentation that enforces behavioral policy at the server connection level a compliance architecture that perimeter-only defenses cannot provide.  

Why should enterprises integrate Cisco Hypershield segment rules across active data center fabrics to contain security threats without risking widespread infrastructure compromise during an incident? The economic scope of breach containment provided by microsegmentation provides the answer. Uncontained lateral movement across a flat network can compromise the entire infrastructure within hours of an initial breach financial liability that includes regulatory penalties, remediation costs, operational downtime, and reputational damage, typically exceeding the cost of comprehensive network security software by orders of magnitude.  

Cisco Hypershield microsegmentation data center 2026 segment rule deployment across active data center fabrics requires identity classification within network settings that provide the behavioral baseline context Hypershield uses to distinguish legitimate application communication from anomalous lateral movement  segment rules that lack clear identity classification generate false positive isolation events that security teams must review, reducing the operational efficiency that automated containment is designed to provide. 

Identity Classification and Behavioral Baseline Configuration 

Cisco data center microsegmentation threat containment effectiveness depends on identity classification quality that maps each server connection to the application workload it belongs to  microsegmentation that cannot distinguish between a database server legitimately querying an adjacent application server and a compromised workload attempting lateral access to the same server cannot apply behavioral policy at the granularity that accurate automated containment requires.  

Hypershield server access permission live behavior block accuracy improves as behavioral baselines mature against production traffic patterns  initial deployment periods when baseline data is accumulating generate higher false-positive rates, and security teams should plan operational capacity to manage them before behavioral confidence reaches the threshold that warrants automated isolation execution without human review.  

An autonomous network isolation live traffic AI security baseline configuration should capture the full range of legitimate application communication patterns — including batch processing windows, maintenance cycles, and peak traffic periods — with traffic volumes and connection patterns that differ from steady-state behavior, which an initial baseline capture might establish as the reference profile. 

Isolation Alerts and Security Team Integration 

Cisco CSCO zero-trust server connection, enterprise automated isolation events require security team notification. Architecture that delivers actionable alert context at the moment a server connection is locked down  isolation events that generate generic alerts without the behavioral context that triggered isolation consume analyst time in alert triage, whereas contextual alerts would redirect that time toward threat investigation.  

Cisco Hypershield automated segment rule federal compliance audit logging of isolation events provides the incident documentation that federal compliance reporting requires  every automated permission adjustment, the behavioral anomaly that triggered it, and the specific connections affected generate a compliance audit trail that manual incident response documentation cannot produce at the event velocity that automated containment generates.  

Cisco data center microsegmentation threat containment integration with existing security operations platforms  SIEM, SOAR, and threat intelligence feeds extends Hypershield’s behavioral detection with external threat context, enriching isolation event triage and enabling security teams to correlate microsegmentation alerts with broader campaign indicators that data center behavioral monitoring alone would not surface. 

Conclusion 

The Cisco Hypershield microsegmentation data center 2026 upgrade establishes automated behavioral containment at the server connection level as the architecture that limits breach scope after perimeter defenses are bypassed. Autonomous network isolation live traffic AI security closes the lateral movement window that human-speed response leaves open containing threats within initial compromise segments before automated attack tooling traverses additional application blocks. 

Cisco CSCO zero trust server connection enterprise enforcement converts network position from an implicit trust indicator into a connection-level behavioral verification requirement removing the flat network trust assumption that lateral movement exploits as its primary propagation mechanism. Hypershield server access permission live behavior block accuracy depends on identity classification and behavioral baseline quality that segment rule configuration must establish before automated isolation execution operates at full containment effectiveness. Cisco Hypershield automated segment rule federal compliance architecture satisfies zero-trust mandates that perimeter-only defenses cannot structurally fulfill. As how does Cisco Hypershield automated microsegmentation instantly adjust server access permissions based on live traffic behavior to block threats from spreading between application blocks defines the technical containment mechanism, and why should enterprises integrate Cisco Hypershield segment rules across active data center fabrics to contain threats without risking widespread infrastructure compromise defines the financial and operational case, the flat network lateral movement exposure that perimeter defense leaves unaddressed has a behavioral containment resolution that machine-speed microsegmentation enforcement makes architecturally permanent. 

The Cisco Hypershield microsegmentation data center 2026 upgrade establishes automated behavioral containment at the server connection level, an architecture that limits breach scope after perimeter defenses are bypassed. Autonomous network isolation, live traffic AI security closes the lateral movement window that human-speed response leaves open containing threats within initial compromise segments before automated attack tooling traverses additional application blocks.  

Cisco CSCO zero trust server connection enterprise enforcement converts network position from an implicit trust indicator into a connection-level behavioral verification requirement removing the flat network trust assumption that lateral movement exploits as its primary propagation mechanism. Hypershield server access permission live behavior block accuracy depends on identity classification and behavioral baseline quality, which the segment rule configuration must establish before automated isolation execution operates at full containment effectiveness. Cisco Hypershield’s automated segment-rule federal-compliance architecture satisfies zero-trust mandates that perimeter-only defenses cannot structurally meet. As how does Cisco Hypershield automated microsegmentation instantly adjust server access permissions based on live traffic behavior to block threats from spreading between application blocks defines the technical containment mechanism, and why should enterprises integrate Cisco Hypershield segment rules across active data center fabrics to contain threats without risking widespread infrastructure compromise defines the financial and operational case, the flat network lateral movement exposure that perimeter defense leaves unaddressed has a behavioral containment resolution that machine-speed microsegmentation enforcement makes architecturally permanent. 

Enterprise Procurement Checklist 

  • Consult: Engage Cisco engineers to integrate automated segment rules across active data center fabrics. 
  • Build: Establish clear identity classifications within network settings to enable accurate behavioral anomaly flagging. 
  • Set up: Configure automatic isolation alerts to notify security teams immediately when a server connection is locked down. 
  • Ensure: Validate all automated network security rules against federal computing infrastructure protection guidelines. 
  • Compare: Evaluate comprehensive network security software costs against the financial liabilities of an uncontained breach. 

Primary Source Link: CISCO Newsroom