Santa Clara, California 

AI development is now evolving past smartphone and cloud server applications. The next leap in technology will involve machines capable of interacting with their environment. With robots in manufacturing, warehouse automation, smart home gadgets, and other intelligent devices, the future is here.The emergence of the Intel Core Ultra Series 3 edge AI robotics chip 2026 platform is expected to significantly accelerate the development of intelligent edge devices worldwide.  

This month, Intel unveiled significant improvements to its Intel Core Ultra processor line, intended to handle complex Edge AI tasks without cloud support. According to industry watchers, this breakthrough may lead to a fundamental revolution in how robotics systems work in households, hospitals, manufacturing plants, and transport systems. 

Many analysts also view the launch as a major step toward integrated CPU GPU NPU zero-latency physical AI edge computing systems.  

Conventional cloud AI requires data to constantly move between devices and cloud computing centers in order to complete calculations. Although the delay would usually only take seconds, it can pose significant difficulties when applied to robotics and automated devices. 

This is where Intel’s new architecture seeks to improve performance. 

Why Edge Computing Has Become Increasingly Important 

For a very long time, most artificial intelligence processes relied on large data centers. Devices collected information and sent it to cloud platforms for processing. 

It worked well for things such as video streaming or search engines. But it became difficult to operate robotics processes in the real world, which required timely responses. 

Intel Core Ultra processors have started becoming increasingly important here. 

These processors consist of a combination of various types of processors in a single unit: 

  1. Central Processing Unit (CPU) 
  1. Graphics Processing Unit (GPU) 
  1. Neural Processing Unit (NPU) 

As a result, they achieve a new hybrid AI PC architecture that can process conventional computer data and complex artificial intelligence algorithms simultaneously. 

Industry experts believe this architecture represents the future of Intel Series 3 edge robotics zero cloud round-trip AI systems operating independently from cloud infrastructure  

Advantages of Intelligent Machines 

The most significant benefit of on-device AI is decreased latency. 

Consider an automated industrial vehicle that is required to transport goods. It should be able to operate instantly in busy, crowded environments without delay. Similarly, when a home appliance uses AI to recognize objects via computer vision, it should immediately execute user commands. 

AI-based intelligent machines with integrated processors do not need an internet connection to execute such applications. 

The benefits are numerous: 

  • Reduced latency 
  • Decreased cloud operational expenses 
  • Less traffic on networks 
  • Enhanced data security 
  • Reliability even in the event of an internet outage 

 The company’s approach toward Intel NPU home appliance industrial robot brain compute is helping create smarter robotics systems for both homes and industrial facilities. 

Industry experts believe that the adoption of these chips will accelerate global smart robotics adoption. The Intel Core Ultra Series 3 edge AI robotics chip 2026 ecosystem may become central to future autonomous robotics infrastructure. 

Why Should Businesses Care? 

Firms have been showing growing interest in Edge AI solutions amid rising cloud costs as AI technology gains popularity worldwide. 

Transmitting enormous volumes of information from sensors per second to cloud infrastructure will be highly costly. By processing information locally, one will use fewer resources and operate faster. 

It is particularly beneficial for sectors such as: 

  • Manufacturing 
  • Logistics 
  • Healthcare 
  • Agriculture 
  • Automated retail industry 
  • Transportation systems 

When using robotics, the main consideration for firms is speed and reliability over processing power. The industrial robot would not operate if the internet connection fails. 

Analysts increasingly ask how does Intel Core Ultra Series 3 integrating CPU GPU and NPU onto a single chip enable zero-latency physical AI in factory robots and edge machinery without cloud dependency as enterprises move toward fully autonomous industrial operations.  

Implications for Consumers May Be Far-Reaching 

While many consumers may overlook just how quickly Edge AI is infiltrating their lives, many future gadgets will be secretly powered by AI processing systems operating off-site. 

In contrast to smart gadgets that regularly exchange data with cloud servers, future gadgets may be able to do many things on their own. 

That change may mean greater: 

  • Privacy for users 
  • Responsiveness for devices 
  • Efficiency of the battery 
  • Offline functionality 
  • Personalization in real time 

Ultimately, an Edge AI robotics processor could become as ubiquitous as any modern mobile phone chip. 

The change may also raise new standards for computing performance. Today’s consumers increasingly desire gadgets that are instantaneous, intelligent, and responsive without needing an internet connection at all times. 

Competition Is Heating Up in the Market 

The AI hardware industry has become one of the most competitive sectors of the tech industry. 

Among others, companies compete for dominance in areas such as: 

  • AI-based PCs 
  • Industrial robots 
  • Smart mobility solutions 
  • Edge computing hardware 
  • Autonomous machinery 

Intel’s strategy centers on integrating AI acceleration directly into mainstream processors rather than relying solely on external hardware. 

That provides more design flexibility for next-generation robotics products. 

Experts believe Intel Core Ultra hybrid AI PC factory automation silicon solutions could help manufacturers reduce long-term operational costs.  

The fight will not be limited to merely fast chips anymore. It will extend to creating fully integrated intelligent environments. 

Conclusion 

It would be an oversimplification to say that Intel’s latest processor developments constitute yet another hardware update. The reality is that Intel positions itself as an enabler of a future in which intelligent machines become independent and capable of making autonomous, real-time decisions. 

Thanks to the development of systems powered by Intel Core Ultra technology, various industries are undergoing change, from manufacturing and logistics to consumer electronics and health care. Moreover, the broader Intel Core Ultra Series 3 edge AI robotics chip 2026 roadmap highlights Intel’s ambitions to dominate the future of edge-based robotics intelligence.

Source- Intel Newsroom 
San Jose, California 

Today, the battle between competing AI systems is not about the largest number of chatbots. Instead, it is about owning the future basis of digital intelligence. For example, this explains why NVIDIA recently unveiled its Nemotron Coalition, an initiative aimed at uniting researchers and developers from various centers across major technological hubs worldwide. 

It is easy to assume that the announcement will not be perceived as particularly remarkable within the tech community. On the contrary, however, some experts argue that it is far more important than it appears at first glance and reflects one of the new trends in the tech world – an effort to develop open-source artificial intelligence systems. Many analysts now describe the coalition as a NVIDIA AI lab coalition open-source LLM alternative designed to reduce dependence on closed AI ecosystems.  

Increasingly, technology companies realize that they need to adapt to the changing realities. Thus, while NVIDIA once specialized in creating hardware, it is now moving in a new direction – developing an ecosystem based on collaboration and innovation. NVIDIA Nemotron is the beginning of a new era in the development of artificial intelligence. 

Why this is an important initiative, among other reasons, is that many current highly sophisticated AI applications have become closed “black boxes.” They can be utilized, but their operations cannot be fully comprehended. The growing debate around NVIDIA Nemotron vs OpenAI closed AI model competition is also pushing developers toward more transparent AI systems.  

Such an approach would lead to rapid advancement of future open frontier AI models across industries such as healthcare, finance, robotics, and education. 

Reasons why NVIDIA needs an AI Coalition 

The strategic initiative of forming a coalition aims to tackle two significant problems in the industry, which are as follows: 

  1. Scalability in AI computing 
  1. Monopolization of AI ecosystems 

NVIDIA currently holds a commanding position in the global market, providing GPU-based computing power for training deep AI neural networks. However, being the sole leader is increasingly challenging in an environment with growing competition. 

An alliance will help NVIDIA create conditions that allow developers to continue developing software for NVIDIA hardware. Experts believe the NVIDIA Nemotron GTC 2026 chip sales dominance strategy is closely connected to this long-term ecosystem expansion plan.  

The coalition will help NVIDIA gain influence across universities, research centers, and startup ecosystems in key technology hubs worldwide. It is much better than trying to compete with all AI companies one by one. 

The Importance of Open AI Development 

Most common users do not know just how much control corporations have over current AI technology systems. Closed AI systems might impose restrictions on transparency, personalization, and independent innovation. 

Here are a number of potential benefits of open development initiatives: 

  • Faster scientific collaboration 
  • Lower startup barriers 
  • Greater transparency in training algorithms 
  • Easier access for scientists 
  • Less vendor dependence 

Such an initiative is important in that AI is playing a greater role in everyone’s lives today. Recommendation engines, search tools, productivity programs, and even customer service use large neural networks.NVIDIA’s coalition is being positioned as an open frontier model collaborative AI software layer capable of encouraging wider innovation among developers and enterprises.  

Without proper competition, innovation would be hindered, and prices could go up. One such initiative would be NVIDIA’s Nemotron project. 

Interest Among Investors Is Growing Quickly 

Analysts on Wall Street have been following the development of the coalition because it significantly expands the scope of NVIDIA’s operations beyond its semiconductor production. 

NVIDIA was traditionally considered a chip provider. Now, it is viewed as an AI infrastructure provider that can potentially impact both hardware and software environments simultaneously. 

It is very important to note this difference. 

As open ecosystems continue to grow, there will be an increased need for additional computing capacity. All developers who build powerful AI models will need access to GPUs, servers, networking equipment, and cloud acceleration capabilities. 

These factors create additional sources of revenue for NVIDIA over time: 

  • AI data center expansion 
  • Software licensing 
  • Growth of the developer ecosystem 
  • Cloud infrastructure cooperation 
  • Research computing services 

The coalition approach reduces risk for NVIDIA by driving broader adoption rather than relying on a few technology giants. 

Many investors are also analyzing how does NVIDIA Nemotron coalition with global AI labs build open frontier models that challenge closed systems like OpenAI and secure NVIDIA’s AI chip market dominance as a major long-term business question  

The Real Battle in AI Infrastructure 

In an increasingly technological world, artificial intelligence has become a geopolitical issue, with many countries making major investments in sovereign AI infrastructure. 

AI infrastructure becomes very important in this context. 

Building AI technology requires large computational power, energy infrastructure, cooling infrastructure, and custom-made processors. Very few companies can provide these kinds of resources on a global scale. 

This makes NVIDIA’s business model quite unique. 

With its focus on collaboration and innovation, NVIDIA can influence the work of various governmental institutions, private enterprises, universities, and research institutions. In effect, NVIDIA creates a platform for the entire global economy powered by artificial intelligence. While developers using open front models would still be able to develop customized AI for specific needs. 

Customized AI may become a defining feature of the next generation of artificial intelligence technologies. 

Why the General Audience Must Pay Attention 

While the practical implications of this for average users might seem remote right now, they may very well dictate every user’s future online experience within a few years. 

In the future, artificial intelligence could potentially affect the following areas: 

  • Education solutions on the internet 
  • Healthcare diagnostics and monitoring tools 
  • Software solutions for businesses 
  • Translation services for real time communications 
  • Robotics technology 
  • Entertainment platforms 

How open, innovative, and competitive AI solutions of tomorrow will be determined by how the industry develops. 

The establishment of the NVIDIA Nemotron partnership clearly indicates that the industry’s future will require greater cooperation rather than competition. 

Conclusion 

With their new step, the creators of AI aren’t just forming yet another research laboratory. Instead, they are setting the agenda for the further development of artificial intelligence. By building connections among laboratories, developers,, and business organizations in the AI community, NVIDIA is strengthening its dominant position in the sector. 

The NVIDIA Nemotron open frontier AI model 2026 initiative, along with the broader NVIDIA AI collective neural network global tech hub vision, positions the company strongly for the next phase of global AI expansion. The company’s broader NVIDIA Nemotron GTC 2026 chip sales dominance strategy also demonstrates how tightly AI software ecosystems and semiconductor demand are becoming interconnected.

Source- GTC 2026 News 

Round Rock, Texas  

Millions of people hit refresh without realizing how easily internet traffic can break down, bank apps can freeze during payday deposits, ticketing sites can stall just before concert sales start, and retailers can crash during holiday rushes, losing millions in abandoned parts before engineers find the problem.  

This pressure affects enterprise infrastructure, such as Dell PowerEdge XE9680 devices, top AI, and high‑performance computing servers. Dell recently improved the systems’ internal design to fix a problem that frustrates both customers and IT teams: data congestion within servers.  

The problem was not a lack of computing power; modern enterprise servers already have plenty of processing capacity. The real challenge was how quickly graphics processors, memory, and networking components could share information under heavy workloads.  

Why Internal Bottlenecks Break Consumer Apps 

Most people blame their internet provider when apps are slow. In fact, many slowdowns start deep inside enterprise data centers.  

A bank handling millions of mobile banking requests at once cannot afford delays between its internal GPUs and CPUs. Even small interruptions inside the server add up quickly during busy times.  

Dell engineers focused on improving the high-speed computer data pipeline in the Dell PowerEdge XE9680 by redesigning circuit layouts and shortening communication paths between graphics accelerators. This change reduces delays when large AI models or busy applications move information between parts.  

For consumers, the result is simple. Pages load faster. Apps stop freezing. Login systems stay stable even when traffic spikes.  

Behind the scenes, the engineering challenge is like rebuilding a busy highway interchange while keeping the city running.  

How The Dell PowerEdge XE9680 Handles Massive Demand 

The Dell PowerEdge XE9680 already plays a key role in enterprise AI, as it can support up to 8 high-performance GPUs in a single system. Large banks, healthcare providers, and cloud companies use these servers to run AI, detect fraud, make recommendations, and analyze customer data simultaneously.  

The problem emerged when massive AI workloads collided with real-time consumer applications.  

AI training clusters move huge amounts of data between GPUs. If the internal communication paths get crowded, the system slows down, a problem called AI app training cluster slowdowns. These delays do not just stay in research labs. They eventually affect customer services that use the same infrastructure.  

Dell’s updated architecture addresses that issue by improving signal routing and optimizing internal bandwidth management. Engineers refined board-level layouts and implemented more efficient upgrades to internal network traffic cable upgrades to reduce transmission delays between components.  

Think of a crowded airport where baggage carts and passenger shuttles use the same paths. Everyone, everything slows down. Dell made the server’s internal pathways wider, so information can move smoothly without running into other data.  

Why Financial Platforms Depend on Faster Internal Communication 

Banking is one of the fastest industries to reveal infrastructure problems.  

During busy payroll times, digital banking platforms handle millions of balance checks, transfers, and fraud checks in just minutes. Even delays of a few milliseconds matter because modern fraud detection depends on nonstop AI analysis working with transaction databases.  

If servers slow down during these times, payments can fail, account updates may be delayed, or customers could get locked out.  

This explains why many enterprises continue to invest heavily in on-premises corporate server updates rather than relying exclusively on public cloud providers. Large institutions often want direct control over latency-sensitive infrastructure, especially when regulatory requirements and customer trust remain central concerns.  

The Dell PowerEdge XE9680 fits this strategy because it offers strong AI processing and local control. Organizations can run advanced AI in their own data centers and reduce the communication slowdowns that often happen during traffic spikes.  

The answer to why the Dell XE9680 server is popular comes down to one factor: consolidation.  

Companies no longer want separate systems for AI analytics and customer apps. They want fewer machines that can handle all three reliably, even under pressure.  

Dell designed the server as a central platform that can handle demanding GPU tasks without losing stability. The new internal pathways make it even more attractive since IT teams now care more about steady performance than just benchmark scores.  

A retailer getting ready for Black Friday shows this, this value well. Recommendation engines, payment systems, inventory databases, and customer analytics all run simultaneously. If the server’s internal communication slows down, the entire customer experience can quickly degrade.  

The improved high-speed data pipeline in the Dell PowerEdge XE9680 reduces this risk by ensuring GPUs and processors share information almost instantly, even under heavy workloads. It marks a new performance era.  

Customer expectations have changed faster than enterprise infrastructure can keep pace. Now, people expect banking apps, streaming services, and online stores to work smoothly at all times, even when millions are online at once.  

This expectation is pushing server makers to focus on better hardware design rather than just adding more processors.  

Dell’s updates to the Dell PowerEdge XE9680 show where enterprise computing is going. Future performance may depend more on how well internal systems communicate under pressure than on just having more chips. As AI grows in finance, healthcare, and retail, the companies that fix hidden infrastructure slowdowns first will likely set the standard for online reliability in the next decade.

Source:  Dell Blog 

Seattle, Washington 

If only one cloud account is compromised, a company can waste money for months before anyone realizes. Attackers hide crypto miners on servers, steal developer credentials, and run fake workloads that rapidly increase electricity and cloud bills. Cybersecurity researchers say global cybercrime damages could reach 10.5 trillion dollars each year, and cloud systems are now among the easiest targets for quiet digital theft.  

Amazon Web Services has recently improved Amazon GuardDuty’s runtime monitoring to address this issue directly. The new feature watches live server activity in cloud workloads rather than just examining logs after something goes wrong. This is important because many attacks leave little sign until stolen data shows up for sale or accounting teams notice strange cloud charges.  

How Amazon GuardDuty Runtime Monitoring Works 

Traditional cloud security tools usually check network traffic or access logs. AWS has gone further by looking inside the operating system. The updated Amazon Guard Duty Runtime Monitoring Service now analyzes running processes, system calls, container activity, and workload behavior in real time across Amazon, EC2, instances, containers, and Kubernetes environments.  

This approach helps security teams spot unusual software actions before attackers can gain a lasting foothold.  

For example, if a finance application is compromised, it might suddenly start an unknown command-line process that tries to contact a foreign server. AWS can quickly flag this activity with its cloud server security threat alerts system. Security teams can then isolate the affected workload before attackers steal payroll or customer data.  

The platform also helps defend against insider attacks that use stolen credentials. Criminal groups are buying leaked employee passwords from underground markets and quietly accessing company cloud accounts without setting off alarms. AWS has added enhanced stolen corporate credential tracking features to identify suspicious runtime behavior even when attackers use real login details.  

The Rising Cost of Hidden Cloud Abuse 

Many executives think of cyberattacks as ransomware or public data breaches. However, the most costly threats can often go unnoticed in the background.   

Hidden cryptocurrency mining is especially expensive for companies with large cloud setups. Attackers can break into a server, install mining malware, and use up huge amounts of computing power while the company pays the bills. Some businesses only find out about these attacks after seeing cloud charges in the hundreds of thousands of dollars weeks later.  

AWS built the updated service with a stronger defense against hidden crypto-mining software defense, a model that identifies abnormal CPU spikes, unauthorized mining programs, and suspicious pro-process chains linked to cryptojacking.  

This update comes at the right time. High cryptocurrency prices continue to attract criminals, as cloud systems offer ample processing power without the need to buy hardware. When attackers take over a company’s servers, they get free mining equipment.  

Why Runtime Monitoring Changes Cloud Security 

Security teams used to rely on perimeter defenses, but this approach is less effective in cloud environments where workloads are always changing.  

Runtime monitoring now looks at how software behaves, not just fixed rules. It checks whether programs behave as they should in real-world situations. For example, if a customer service app suddenly attempts to gain additional privileges or starts an unknown process, AWS considers this a potential threat.  

The built-in malicious app process behavior blocker is especially useful for containerized apps that run thousands of microservices at once. Security analysts cannot manually check every process in today’s large environments. Automated runtime analysis cuts detection time from weeks to just minutes.  

A healthcare provider using AWS for patient databases shows this advantage well. If attackers break into a weak web app and install malware to steal credentials, runtime monitoring can detect anomalous file access and network activity before sensitive records are compromised.  

How to Turn on GuardDuty EC2 Monitoring. 

Many businesses do not turn on advanced monitoring tools because cloud security settings appear overly technical. Fortunately, turning on GuardDuty EC2 monitoring involves a relatively straightforward setup process in the AWS Management Console.  

Administrators start by turning on Amazon GuardDuty in their AWS account. Next, they enable runtime monitoring in the GuardDuty Protection Plans section. AWS then adds lightweight security agents that begin checking EC2 activity in real time.  

Companies running containerized workloads with Amazon EKS can use the same monitoring features for their Kubernetes clusters. This unified view helps security teams track threats across all their cloud environments.  

The main challenge is staying disciplined in operations, not simply setting things up. Many companies turn on basic monitoring but skip alert tuning, escalation steps, or automated replies. Good cloud security relies on quick investigation when something suspicious happens.  

AWS Pushes Further Into Proactive Defense 

Amazon’s new monitoring approach is part of a bigger change in enterprise cybersecurity. Companies now assume attackers will get in at some point, so they focus on limiting damage as fast as possible.  

This thinking is why behavioral analysis is now central to cloud defense strategies. Runtime visibility can reveal attacks that firewalls and antivirus tools often miss.  

For American businesses facing mounting regulations and higher cyber insurance costs, they may soon view core two detection tools as standard operating procedure, not just as extra protection. AWS seems to make Amazon GuardDuty runtime monitoring a core part of cloud security before the next wave of costly attacks hits.

Source: Work with trusted Partners to find the right solutions 

Houston, Texas  

On a hot July afternoon, a modern data center can use more electricity than a small town. In places like Texas, Virginia, and Arizona, utilities keep a close eye on large server campuses just as they do with factories. If an AI cluster is poorly managed, it can quickly increase cooling demand and put extra strain on substations during a heat wave.  

This pressure is why HPE ProLiant Gen12 servers are important for more than just the IT industry.  

On Tuesday morning, Hewlett Packard Enterprise launched its first servers focusing on liquid cooling, power savings, and efficient AI infrastructure. While the technology may seem complex, the impact is clear. Every watt saved in a data center helps reduce the load on the electric grid that supports homes, schools, stores, and hospitals.  

Why Data Centers Have Become a Utility Problem 

The rapid growth of AI has quickly changed how computing works. Training big models and running AI tasks need tightly packed processors that get very hot, making it hard for traditional air cooling to keep up.  

This leads to a risky cycle.  

Fans have to work harder, chillers run longer, and buildings use more electricity from the grid just to keep processors cool. In some cities, cooling systems now use almost 40% of a data center’s power during the hottest months.  

Rather than blowing cold air through server aisles, HPE’s system uses direct-to-chip fluid cooling manifolds that circulate liquid across high-temperature components. Liquid absorbs heat far more efficiently than air. This means fewer chillers, fewer fast-spinning fans, and much less electricity used during heavy computing.  

For utility operators, that translates into something tangible: local electrical grid strain reduction.  

The Physics Behind Lower Bridge Stress 

Most people only notice problems with the grid when lights flicker or blackouts start. Utilities, however, see the warning signs much sooner. If cooling demand suddenly rises, they may have to turn on costly backup generators, especially during extreme weather.  

Liquid cooling changes this by removing heat using less energy.  

The difference becomes obvious at rack scale. A conventional AI rack cooled primarily by air can require massive airflow volumes to maintain safe operating temperatures. By contrast, liquid-cooled infrastructure can achieve a measurable reduction in high-density computing heat drop while consuming substantially less supporting power infrastructure.  

This directly improves data center energy use efficiency level, a metric that large operators monitor obsessively because cooling costs add up across thousands of servers.   

Many businesses now ask a simple question: how do liquid-cooled servers save energy? 

The answer is about thermodynamics and efficiency. Liquid moves heat around 1,000 times better than air. Thanks to this, facilities rely less on energy-hungry cooling systems that use a lot of electricity during summer.  

In practice, a large facility with thousands of HPE ProLiant Gen12 servers might cut cooling costs enough to put off upgrades from your local utilities. This is important in fast-growing areas where power demand is already outpacing grid expansion.  

Why Neighborhoods Care About Enterprise Servers 

Northern Virginia is a good example. It has the world’s largest group of data centers, and local utilities have often warned about growing pressure on the grid from more AI infrastructure.  

People do not worry about the type of hardware in a server rack. They care when their electricity bills go up or when backup generators start during times of high demand.  

This is where technologies like direct-to-chip fluid cooling become important for public safety, not just engineering.  

Efficient cooling allows operators to fit more computing power into the same electrical system. Instead of building new substations, some facilities can increase AI processing capacity while maintaining tighter power envelopes. That results in measurable local reductions in electrical grid strain, especially during hot months when air conditioning already strains utilities to the limit.  

The bigger economic impact could be huge. Industry forecasts say US electricity demand from AI data centers might double by the end of the decade. Without better efficiency, utilities would have to expand their infrastructure quickly just to keep up.  

The Competitive Pressure on Enterprise Infrastructure. 

HPE is not the only company working on liquid-cooled computing. Other server makers now see advanced cooling as a must-have, not just an experiment.  

Still, the launch of HPE ProLiant Gen12 servers shows how fast the market has changed. Five years ago, liquid cooling was mostly used in supercomputing labs. Now, company CIOs discuss cooling systems in regular meetings because energy use is a major financial concern.  

This shift also mirrors investor pressure. Large corporations increasingly disclose sustainability metrics tied to IT operations, including data center energy-efficiency targets and carbon-reduction commitments.  

Using less energy for cooling helps with both energy efficiency and sustainability.  

The next stage of AI infrastructure growth will rely less on just faster processors and more on how well companies handle heat, electricity, and space limits. The companies that solve these challenges could shape the future of computing and strengthen local power grids in America’s fastest-growing digital areas.

Source: The self-driving network 

Austin, Texas  

A distracted driver traveling at 70 mph can cross a football field in under 4 seconds. At that brief moment, a family’s safety can change in an instant. Safety today does not begin with airbags or steel frames, but with a quiet computer under the dashboard. Here, the Tesla custom AI chip analyzes millions of data points before the driver even hits the brakes.  

Tesla’s new hardware approach shows just how intense the competition has become. Industry sources say Tesla is securing advanced semiconductor manufacturing for its next autopilot processors, including sub-2nm factory wafer orders for future full self-driving systems. This matters because real autonomous safety depends on fast computing, not just marketing claims.  

Why The Tesla Custom AI Chip Matters More Than Horsepower 

For years, carmakers focused on engine power. Electric vehicles changed that. Now, a car’s intelligence decides how well it handles traffic, sudden lane changes, construction, and people crossing at night.  

Today’s full self-driving computer hardware can already handle trillions of operations every second. Cameras around the car send video to processors trained to spot lane lines, brake lights, cyclists, animals, and unpredictable drivers. It’s similar to how a pilot checks instruments during rough weather.  

The next Tesla custom AI chip is designed to further reduce processing delays. Engineers measure these gains in nanometers. Using sub-two-nm silicon means more transistors fit on each chip, greatly increasing efficiency and computing power.   

The engineering progress has a direct impact on preventing accidents.  

When a child suddenly runs into the street, the vehicle’s computer must identify the object, predict motion, calculate braking distance, evaluate surrounding traffic, and initiate action almost instantly. Tesla’s future advanced vehicle neural network processing systems could reportedly execute these calculations up to 4 times faster than previous generations of hardware.   

At highway speeds, every millisecond counts.  

How Sub-2 nm Silicon Changes Highway Safety 

Smaller transistors use less energy and can handle more tasks at once. In electric cars, this is especially important because processing power and battery life are closely linked.  

A sub-2 NM chip design lets cars use more advanced real-time driving models without straining the electrical system. Engineers can run bigger neural networks that spot subtle dangers older systems might miss.  

Imagine heavy rain on Interstate 95 at night. Water reflections distort lane markings. A pickup truck suddenly hydroplanes into the lane over. Older systems may hesitate while inspecting the scene. New edge-silicon autonomous safety upgrades reduce recognition latency, enabling the onboard computer to model vehicle trajectories faster and issue corrective steering inputs earlier.  

This faster response could help prevent chain reaction crashes involving many cars.  

The Tesla custom AI chip also enables higher-resolution sensor fusion. Rather than looking at each camera to feed separately, future systems will combine all visual data into a single model, similar to how our brains process what we see. Tesla engineers use these methods more and more because they help predict what will happen in heavy traffic.  

What does the Tesla FSD Computer Use Today? 

Many people wonder: what chip does the Tesla FSD computer use?  

Today’s Tesla vehicles with full self-driving mainly use Tesla’s own Hardware #3 and the newer Hardware #4 platforms. These chips replaced older third-party systems, giving Tesla more control over software, neural network training, and safety timing.  

This approach explains why Tesla keeps investing heavily in its own chip design instead of outsourcing. The company sees AI processing as a core part of its vehicles, not just another component.  

The next generation of full self-driving computer hardware, reportedly under development, will likely push that philosophy further by integrating denser transistor layouts, more memory bandwidth, and more AI acceleration cores built for self-driving tasks.  

The Semiconductor Is Behind Autonomous Driving 

Tesla is not the only company seeking advanced chip manufacturing. All major automakers now realize that self-driving systems need top-notch semiconductors. Still, Tesla’s push for sub-2 nm wafer orders shows it expects future cars to need much more computing power.  

Training advanced neural networks is like running a digital nervous system that keeps learning. Cars gather unusual driving situations from millions of miles on the road. Engineers keep improving the models and send updates back to the fleet.  

This process only works if the cars’ processors are fast enough to keep up.  

The industry now sees advanced neural network processing as the key to safer transportation. Faster chips mean quicker object recognition, leading to shorter reflection times and fewer crashes.  

Most people notice self-driving cars because of flashy demos. Engineers, though, care more about cutting down hesitation by fractions of a second, which can save lives.  

That is where the future of highway safety will likely be decided, not in the showroom, not in the battery pack, inside microscopic transistor structures powering the next wave of edge silicon autonomous safety upgrades that increasingly act as co-pilots for millions of drivers worldwide.

Source: Tesla Blog 

Cupertino, California  

A commuter in Chicago glances at her phone, which displays a photo from a friend. In Texas, a student follows a lecture with real‑time spoken captions. These situations are no longer rare; they are becoming the norm, thanks to Apple’s intelligent accessibility features, now central to the company’s software strategy.  

Apple’s Intelligence Accessibility Features Are Changing How People Use Their Devices Every Day 

In its latest announcement, Apple put the spotlight on usefulness instead of flashy hardware. The company expanded Apple Intelligence accessibility features to more iPhone models with its newest AI technology, showing a clear move toward more inclusive computing.  

The heart of this is a simple idea: a phone should do more than show information. It should help make sense of it.  

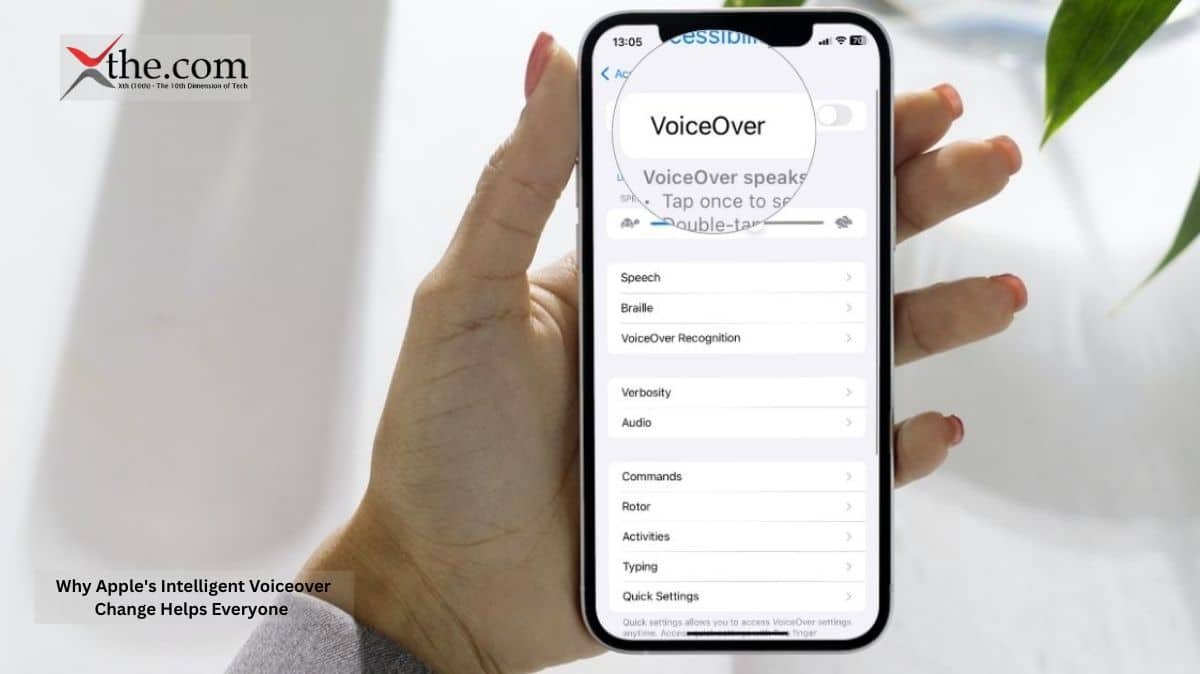
Now, this interpretation includes voiceover, screen reader, and image descriptions. The system no longer relies solely on static labels or preloaded data; it analyzes the screen in real time and describes even complex visuals in detail. For example, a chart in an earnings report is explained out loud, and a busy social media photo is described clearly. The aim is to make it easier for everyone to understand what they see.  

On-Device Intelligence Changes the Privacy Equation 

A big part of this equation is the new on-device neural processing, which moves heavy computing from remote servers to the phone itself. This change is important for both speed and privacy.  

For example, someone in a hospital waiting room can point their phone at a medical form and hear spoken applications, all without sending private data to the cloud. The phone handles everything on its own, which means less delay and better privacy.  

This setup also makes voiceover screen reader image descriptions work quickly for many people. The phone analyzes visual content right away, so users looking at a transit map or a restaurant menu get faster, more natural feedback.  

Real-time Speech Becomes a Second Layer of Vision 

One of the biggest changes is real-time audio subtitle generation. Apple’s system now listens to live audio from calls, videos, and even in-person conversations and quickly converts it to spoken or displayed text.  

For people who are hard of hearing, this changes how they receive information in groups. They can immediately delay classroom discussions, understand customer service calls more easily, and even keep up with conversations in noisy places.  

Earlier captioning systems often struggled with timing and punctuation. The new model uses an on-device neural processing upgrade, enabling it to retain context in the middle of a sentence rather than waiting until the end.  

The Role Of The Consumer Software Update Rollout 

Apple is delivering these changes through a staged consumer software update rollout rather than a single global switch. That decision reduces server strain and enables incremental tuning across device generations.  

In real life, this means two people in the same city might get new features at different times. One might already have real-time audio subtractive generation, while another is still waiting. This staggered release also helps Apple improve the system, especially in places where different languages, accents, or fast speech can be tricky for AI.  

How to Use Apple Intelligence Voiceover Updates in Daily Life 

Many people want to know how to use Apple Intelligence VoiceOver updates without having to change their daily routines.  

Someone who is visually impaired can turn on enhanced VoiceOver screen reader image descriptions in accessibility settings and start getting better descriptions of apps, emails, and images right away. A student can use real-time captions during lectures, and a traveler can get spoken navigation with helpful explanations about their surroundings.  

The system does not require new apps or workflows. It integrates directly into the operating system, which is why the consumer software update rollout matters as much as the features themselves. The value gradually becomes embedded in the tasks people already perform.  

Risk, Opportunity, and Impact 

The main opportunity is clear. Cool technology that used to need special assistive devices is now built into regular smartphones. This shift makes these tools available to many more people, thanks to widely used software instead of rare hardware.  

The risk lies in over-reliance and accuracy. Misinterpreted image descriptions or delayed subtitles can create confusion in critical situations. Apple’s emphasis on local processing through its on-device neural processing upgrade reduces some of that risk, but not all of it.  

Even so, the trend is clear. Accessibility is no longer just an extra feature. It is becoming a basic part of how devices work.  

The result is a phone that feels more conversational. It can speak, listen, and understand with increasing skill. As Apple’s accessibility features improve, the line between device and assistant will keep fading, not through flashy changes but through small, useful updates that quietly make daily life easier.

Source: Apple TV to broadcast first major professional live sporting event shot entirely on iPhone 17 Pro 

Mountain View, California  

A ransomware group in another country can shut down a hospital within minutes. State-backed hackers can attack energy networks, defense contractors, and election systems without leaving their own borders. This threat is why Google Distributed Cloud Air-Gapped systems are now among the most closely watched security projects in government technology.  

Google’s latest approach addresses a simple but harsh truth: if attackers cannot physically access a network, they cannot compromise it remotely.  

Why Government Swarm An Air-Gapped Cloud 

Most cloud platforms require an internet connection at all times. This setup works well for streaming video, online shopping, and business collaboration, but it becomes much riskier when intelligence agencies, military databases, or nuclear research systems are involved.  

An air-gapped system avoids this risk by physically separating sensitive infrastructure from public networks. There is no open internet path and no outside connection to classified workloads. This separation happens at the hardware level, not just through software settings.  

This defense is important.  

Firewalls can fail. Software patches can have bugs. People can set permissions incorrectly. Physical isolation creates a stronger barrier. Google’s distributed, air-gapped cloud design embeds this barrier directly into the infrastructure.  

Google’s Distributed Cloud Air-Gapped Architecture Explained 

Google created this platform for defense agencies, intelligence operations, and organizations that handle highly sensitive national data. Rather than sending workloads to Google’s public cloud, the company sets up dedicated infrastructure in secure facilities.  

This is the system that uses what security engineers call an isolated software infrastructure build. Servers, networking equipment, storage, and admin tools all run in a sealed environment, cut off from the wider internet.  

This means administrators cannot just log in from home or another country. They must be physically present and follow strict authentication steps to get access.  

For most people, the easiest way to picture this is to think of a bank vault.  

A regular cloud system is like online banking, where you access services remotely via a secure internet connection. An air‑gapped cloud is more like a vault deep inside a secure building, guarded and with no doors leading outside.  

Google also built the system to support sovereign data privacy network defense requirements. Governments increasingly demand that confidential data remain within national borders and under local operational control. Countries worry that international surveillance laws or overseas breaches may reveal important information.   

By keeping infrastructure local and disconnected, agencies can better control where information is stored and who can access it.  

How Physical Security Keys Block Overseas Intrusions 

One of the most important elements in the system involves physical cryptographic key storage.  

Encryption keeps sensitive information safe by turning it into unreadable code. To access the data, you need cryptographic keys. In many regular cloud setups, attackers try to steal these keys remotely using phishing, stolen credentials, or hacked admin accounts.  

Google’s air-gapped model changes this by keeping keys on local hardware rather than on systems connected to the internet.  

Picture a defense contractor storing s-satellite intelligence data. Even if hackers from another country steal employee passwords through phishing, they still cannot access the protected systems without the physical security key kept inside the secure facility.  

This physical requirement makes things harder for attackers. Remote hackers rely on scale and automation. They send millions of malicious emails, attack exposed servers, and constantly look for weaknesses in public applications. Physical isolation stops these tactics because there is no remote way in.  

The strategy directly addresses rising concerns in the highly regulated sector about security clouds. Industries such as defense, healthcare, finance, and energy are under increasing pressure to prevent catastrophic breaches. Regulators no longer accept vague cybersecurity promises. They want verifiable controls, documented isolation, and auditable protections.  

How Does an Air-Gapped Cloud Work for Safety? 

The question many executives ask is straightforward: how does an air‑gapped cloud work for safety when modern organizations still need speed and scalability?  

The answer is controlled connectivity.  

Air-gapped systems do not prevent all data movement. Instead, they carefully control every transfer. Organizations usually move approved data through secure review processes, specialized transfer stations, and fully monitored validation systems.  

For example, a military intelligence analyst updating classified mapping software might receive the update on encrypted physical media only after it has been inspected and approved, rather than downloading it automatically from the internet.  

This slower process can be frustrating for tech firms that value convenience. However, it greatly reduces the risk of automated malware, ransomware, and remote attacks.  

Google’s design signals a broader shift in cybersecurity thinking. For years, companies expected attackers to break through defenses, so they focused on detecting and responding to threats. Air-gapped infrastructure shifts the focus back to strong prevention.  

Not every organization needs this much isolation. For example, a retail chain or streaming service would probably find these restrictions too much. National security teams have different needs. A single breach could reveal classified information, disrupt defense operations, or damage critical infrastructure.  

With the increase in global cyber warfare, physical separation is becoming popular again. Cloud computing once promised that you could connect from anywhere. Google’s air‑gap approach suggests that for the most sensitive system, the safest option might be no connection at all. 

Source: News, tips, and inspiration to accelerate your digital transformation 

Austin, Texas.  

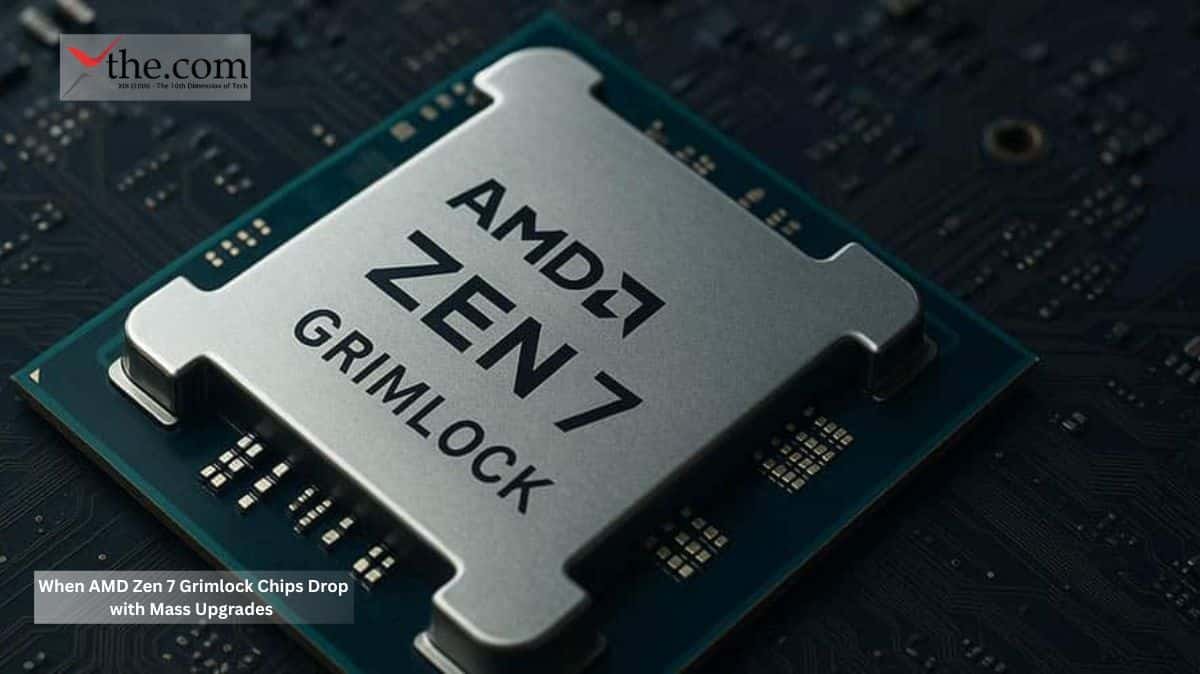
For years, PC gamers have focused on squeezing out small frame‑rate improvements, but a new report from Taiwan’s supply chain hints that AMD could be preparing something much bigger. The latest AMD Zen 7 Grimlock leak suggests a major leap in processor design that might transform high‑end gaming PCs and local AI tasks sooner than anyone expected.  

People connected to motherboard makers and packaging partners say AMD plans to use the advanced TSMC 1.4 nm process‑node silicon strategy for Zen 7 “Grimlock” CPUs. This is important because making transistors smaller is not just about adding more cores. It also affects latency, power use, heat management, and how much cache memory can sit next to the processor cores.  

If you play games like Cyberpunk 2077 on ultra settings or work with local AI models, this rumored architecture could deliver a significant performance boost for gaming processors.  

The AMD Zen Grimlock Leak Signals a Major Manufacturing Shift 

AMD’s current Zen lineup already competes strongly with Intel for gaming and workstation power. Zen 7 looks set to go even further. Reports from Taiwan suggest AMD might skip small upgrades and move straight to TSMC’s 1.4 nm process node silicon technology sooner than many thought.  

The main reason this change is important is density.  

A smaller manufacturing process lets AMD fit more transistors into the same space and reduce power loss. Engineers can use the extra room for more cache, AI features, or even better scheduling hardware.  

The most eye‑catching rumor involves cache capacity. Multiple reports suggest AMD could place an enormous 224 MB cache structure on a single compute die. If accurate, that would dramatically expand AMD’s desktop core complex die’s memory capabilities compared with today’s enthusiast processors.  

This could have effects that go far beyond just better benchmark scores.  

Modern games constantly move textures, geometry, and physics data between different types of memory. A bigger on-chip cache means less need to use slower system RAM. This lowers latency and helps keep frame rates smooth during demanding scenes where today’s CPUs can struggle.  

If you play esports on a 360Hz monitor, you might see fewer frame time spikes. Content creators who render AI-generated videos on their own PCs would get faster results without relying on cloud servers.  

How Next Gen 3D V-Cache Tech Could Redefine Gaming CPUs 

AMD has already shown how useful vertically stacked cache can be with its X3D chips. Processors like the Ryzen 7 7800X3D became popular because games perform much better with bigger cache sizes.  

Zen 7 reportedly pushes that concept much further with next‑gen 3D V‑cache tech.  

Rather than just making small improvements, AMD might change how the cache connects to the processor cores. People familiar with the design say there will be closer vertical integration and better heat management, which has been a problem for stacked cache in the past.  

This could let AMD hit higher clock speeds without running into heat problems.  

Imagine a future open‑world game that streams huge environments in real time. Today’s systems often struggle when Big Maths, AI, and physics calculations collide simultaneously. An expanded desktop core complex per memory channel would allow the processor to keep more game data closer, reducing slowdowns and maintaining steady performance.  

This benefit also helps with running AI tasks directly on your PC.  

More and more people are running AI tools right on their desktops. Voice models, image generators, and coding helpers all work better with faster memory. More cache means less waiting for data. For anyone trying out local AI engines, Zen 7 could feel much quicker if the rumors are true.  

Why the Gaming Processor Performance Jump Could Extend Beyond Gaming 

Calling these chips “gaming CPUs” doesn’t really cover everything they can do anymore.  

Modern processors handle streaming, AI acceleration, multitasking, and creator workloads simultaneously. The rumored gaming processor performance jump attached to Zen 7 could spill over into several adjacent markets.  

Small developers making AI apps on their own PCs could get workstation-level power without paying for expensive hardware. Streamers might be able to encode video and run AI moderation simultaneously. Engineers using simulation software could also see better performance with larger cache sizes.  

The timing is also consistent with the rising demand for edge AI computing. Firms increasingly want local processing rather than sending sensitive data to public cloud systems.  

AMD appears positioned to capitalize on this shift if the AMD Zen 7 Grimlock leak proves accurate.  

When Will the AMD Zen 7 Processors Be Released? 

AMD has not confirmed the launch timing publicly, but supply chain estimates suggest late 2027 remains the most realistic target. That estimate matches the expected availability for advanced TSMC 1.4 mm process node silicon production capacity.  

Questions about when AMD Zen 7 processors will be released continue to circulate as motherboard manufacturers reportedly began early compatibility planning sooner than expected. That usually signals confidence in architectural stability even as final specifications remain fluid.  

Even so, it’s wise to be cautious with leaks.  

Plans in the chip industry change frequently. Issues with packaging, heat, or costs can mean last‑minute redesigns. Still, the amount of talk about Zen 7 suggests AMD is working on something much bigger than a typical update.  

If even some of these rumors are true, the next generation of desktop processors could do much more than just add cores or boost speeds. They might completely change how PCs handle gaming, AI, and memory‑heavy tasks for years to come.

Source: Investor Relations The Industry’s High Performance and Adaptive Computing Leader 

Santa Clara, California.  

PC gamers and desktop builders are too familiar with this situation. You buy a $300 motherboard, upgrade your CPU after a couple of years, and your still‑working board ends up as electronic waste. There is a new socket, a new chipset, and more money spent.   

That cycle might finally be coming to an end.  

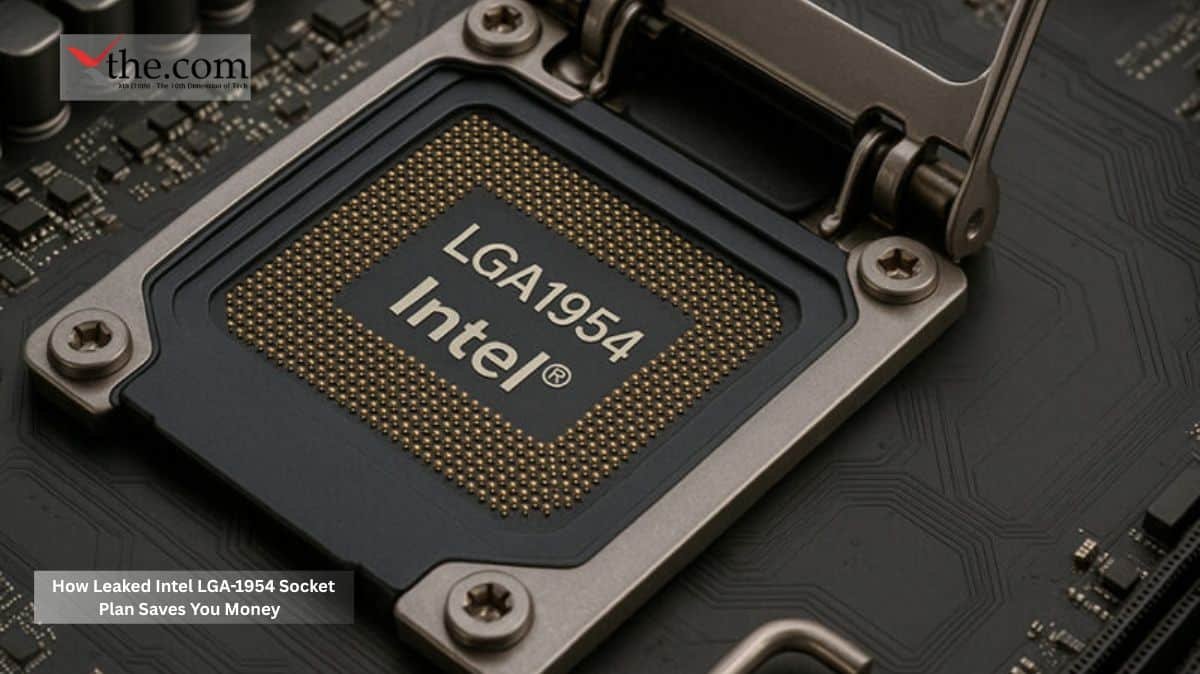
A newly leaked roadmap suggests Intel’s LGA 1964 socket plans could deliver something desktop buyers have long demanded: long‑term upgrade support across three processor generations. If the leak is accurate, Intel’s upcoming LGA 1964 platform will work with Nova Lake, Razor Lake, and Hammer Lake chips on the same motherboard. For everyday builders, this could make a big difference.  

AMD earned significant goodwill with AM4 by supporting multiple CPU generations on a single socket. Intel, on the other hand, became known for frequently changing socket designs, leading to costly motherboard upgrades. This leak suggests Intel might be changing its approach.  

Why Intel’s LGA 1954 Strategy Matters 

When upgrading a modern PC, the highest cost is often not the processor; it is the platform’s hidden cost.  

If you upgrade from a Core i7 to a next‑generation Intel chip, you often need a new motherboard, updated BIOS, and sometimes even new memory. These extra costs can add up to hundreds of dollars before you even turn on your system.  

The leaked Intel LGA 1954 socket plans suggest that Intel may finally focus on making platforms last longer instead of changing sockets quickly. The document says the socket could stay in use for at least three CPU families: the Nova Lake, the Razor Lake, and the Hammer Lake.  

This kind of consistency directly affects how much consumers spend.  

Someone who buys a premium Z series motherboard in 2026 could theoretically keep it through multiple processor upgrades until the end of the decade. That creates substantial PC builders’ hardware budget savings, especially for those who upgrade CPUs more often than GPUs.  

The Real Value of a Longer Upgrade Path 

Intel users have usually dealt with shorter platform cycles than AMD customers. LGA 1200 lasted for two generations. LGA 1700 lasted a bit longer, but still required careful chip choices and BIOS updates.   

Now Intel seems ready to make motherboards last longer, similar to AMD’s successful strategy.  

Nova Lake Processor Upgrade Path for Release: Total Build Costs 

Picture someone building a $1,800 gaming PC with a Nova Lake processor in 2026. In the past, upgrading the CPU in 2028 would probably mean buying a new motherboard for another $250 or $400.  

But if the same board works with Razor Lake Hammer Lake support, you avoid the extra cost.  

The Nova Lake processor upgrade path basically gives customers more options. Buyers can spend more on a better motherboard upfront, knowing it will remain useful for years rather than become outdated after just one upgrade.   

This is even more important for content creators and workstation users who prefer upgrading parts gradually rather than rebuilding their entire system.  

How Many CPU Generations Will LGA 1954 Support? 

According to the leaked roadmap, the answer seems to be at least three generations.  

This would start with Nova Lake, then Razor Lake, and finally Hammer Lake.  

While Intel has not officially confirmed this roadmap, the leak points to a serious strategy to extend the lifespan of motherboard compatibility.  

For consumers, supporting three generations is a big step up from what Intel has done in the past.  

AMD won a lot of loyal customers because AM4 worked from the first Ryzen chips through Ryzen 5000. People could upgrade CPUs several times without having to replace the entire system. Now Intel looks ready to compete with that approach.  

Intel May Finally Understand Enthusiast Frustration 

Socket longevity might sound technical, but it has a big financial impact on everyday consumers.  

Serious motherboards are no longer ninety-dollar entry-level parts. A good DDR5 board with strong VRM cooling, PCIe Gen 5, Wi-Fi 7, and advanced storage can easily cost more than $350.   

Having to replace that hardware every two years is frustrating even for high-end enthusiasts.  

The leaked Razor Lake and Hammer Lake indicate that Intel recognizes that frustration. If one socket works across several architectures, buyers can feel better about spending more on premium boards since their investment will last longer.  

This also helps smaller system integrators and boutique PC builders. Stable platforms may mean less inventory risk and easier compatibility testing.  

A Quiet Shift In Intel’s Competitive Strategy 

This leak comes at an interesting time for the desktop GPU market.  

AMD built its reputation with enthusiasts by keeping its sockets stable.  

Intel led in raw performance in many areas, but often lost goodwill because it changed platforms so often.  

The reported motherboard-compatibility lifespan extension tied to LGA 1954 suggests that Intel may now care as much about building trust as it does about performance.  

This could change how people decide what to buy.  

More and more consumers are looking at long-term ownership costs rather than just benchmark scores.  

A CPU platform that lasts for three generations gives real value that benchmarks alone cannot show.  

The best part of Intel’s supportive rumored strategy might not be the socket itself, but the message it sends.  

Buyers want the freedom to upgrade, predictable costs, and hardware that lasts longer than just one product cycle.  

If Intel goes ahead with these leaked plans for the LGA 1954 socket, the company might finally give PC builders what they have wanted for over a decade a platform that values their budget as much as their need for performance.

Source: Intel Newsroom