San Jose, California  

A single AI training server now uses more electricity than a typical suburban home, but in many data centers, the main bottleneck is not the graphics chip. Instead, it is the processor that manages memory, storage, networking, and workloads across thousands of accelerators. This challenge is why the Nvidia Vera CPU market is important well beyond Silicon Valley.   

During a recent keynote, Jensen Huang introduced Nvidia’s Vera CPU as part of a broader computing strategy. This move directly challenges processor leaders like Intel and AMD. More importantly, it shows that AI infrastructure is shifting not just from training chatbots, but to running autonomous software agents throughout the workplace.  

Why The NVIDIA Versus CPU Market Suddenly Matters 

For years, NVIDIA led the AI field with its graphics processors. These chips excel at handling the large-scale parallel computations required for machine learning. CPUs mostly played a backup role.  

But now that balance is changing.  

Modern AI systems do more than just train models. Now, businesses want AI agents that can schedule meetings, analyze spreadsheets, write reports, approve invoices, and monitor cybersecurity threats without human intervention. This surge in agentic AI autonomous system demand changes the economics of computing infrastructure.  

Picture a global retailer running 50,000 AI agents at once during the holidays. One agent predicts inventory shortages, another manages shipping schedules, and a third monitors fraud. These systems require continuous communication among memory, networking hardware, and accelerators. Graphics chips perform the calculations, while CPUs manage the entire process.  

This management layer is now extremely valuable.  

Analysts expect the global central processing unit market value to achieve hundreds of billions of dollars over the next decade as AI spreads across business, robotics, and cloud computing. NVIDIA wants a bigger piece of that market, not just relying on GPU sales.  

The Bigger Bet Behind Vera 

The Vera processor is not meant for consumer desktops or gaming PCs you find at electronics stores. NVIDIA designed it for AI factories and large cloud providers.   

NVIDIA paired Vera with its next‑generation Rubin AI architecture in the upcoming  Vera Rubin chip platform rollout. That integration matters because Nvidia controls both the CPU and GPU communication. Traditional servers often mix processors from one company with accelerators from another, which can cause delays, software issues, and wasted energy.   

NVIDIA wants to remove these problems.   

NVIDIA’s approach is similar to Apple’s integration of hardware and software in the iPhone. By closely connecting Vera processors with Rubin GPUs, Nvidia can boost performance across the whole AI workload, not just in separate parts.   

This could make enterprise AI systems respond much faster. For example, a legal AI assistant reviewing 20 million documents needs quick coordination between processors and graphics chips. Moving data faster means quicker answers and lower costs.  

What Is the New NVIDIA Vera Processor Used For? 

In short, it is about managing large-scale coordination.  

The long answer is that NVIDIA thinks the next big wave of AI will focus on autonomous decision‑making, not just chatbots.  

“What is the new NVIDIA data processor used for?” becomes easier to understand when viewed through a workplace example. Consider a bank deploying AI agents for loan processing, compliance checks, customer service, and fraud detection. Thousands of small decisions happen every second. The CPU handles task scheduling, memory access, security, and communication between accelerators.  

Without a strong processor, GPUs waste time waiting for instructions.  

This is where NVIDIA sees a chance with graphics card cluster integration. Large AI setups now look more like coordinated computing grids than single servers. Vera serves as the command center that connects these grids efficiently.  

This setup also supports future robotics. Autonomous warehouse machines, factory automation, and AI-powered logistics all need fast coordination between sensors, processors, and inference engines. NVIDIA wants its hardware to be at the center of this system.  

What This Means For Computer Speed 

You might not buy a laptop with Vera next year, but you will notice its effects.  

Cloud apps could get faster. AI assistants could reply more quickly. Business software may automate more tasks without slowing down under heavy use. Companies that use a lot of AI could cut costs and handle larger datasets.  

There is also a ripple effect in the industry. NVIDIA’s move to CPUs pushes competitors to redesign their products for AI workloads. This kind of competition often accelerates innovation in the semiconductor industry.  

The deeper shift involves how society uses computers. For decades, people operated software directly. The next phase centers on AI agents operating software on behalf of people. That transition explains the rise in agentic AI, the demand for autonomous systems, and NVIDIA’s urgency to control more of the computing stack.  

Vera is more than just another processor. It is NVIDIA’s effort to set the standard for the technology behind autonomous digital work. If this plan works, NVIDIA will influence not only how AI models are trained, but also how machines that work around the clock make daily business decisions.

Source: Nvidia Newsroom 
Redmond, Washington  

This spring, Microsoft faced an unusual problem. Its engineers preferred a competitor’s AI coding assistant over its own.  

Developers working on Windows, Office, and Internet systems started using Anthropic’s Claude Code more often to debug scripts, review code, and quickly create production-ready snippets. This growing popularity raised concerns among Microsoft’s security and leadership teams. By late May, managers in the Experiences and Devices group began warning employees about a June 30 deadline to stop using Claude Code and switch back to GitHub Copilot CLI.  

It was ironic: Microsoft, the company behind GitHub Copilot, saw its own developers favor a competitor’s tool.  

For Microsoft’s leaders, the problem shifted from convenience to governance.  

Microsoft Cancels Claude Code Licenses After Internal Adoption Surges 

Many engineers were surprised by the strict enforcement of the policy since Claude’s code was known for handling large‑scale debugging and expanding complex architectures. Developers working with legacy Windows components found it especially helpful for navigating large, complex codebases.  

This efficiency created a difficult situation for Microsoft.  

Microsoft provides AI infrastructure, enterprise security, and developer tools to major companies. Allowing internal teams to send sensitive code to an external AI system raised tough questions about data location, monitoring, and intellectual property protection. These concerns grew as more employees used Claude Code in their daily work.  

The internal order behind Microsoft cancels Claude’s code licenses, reportedly focused on two areas: column data control and platform loyalty.  

Executives were concerned that engineers were putting copyrighted code into systems Microsoft did not fully control. Even with Anthropic’s security measures, Microsoft leaders could not see exactly how prompts, contexts, or outputs interacted with sensitive code.  

Meanwhile, GitHub Copilot remained a key component of Microsoft’s overall AI strategy.  

A senior engineering manager met a computing tool for testing, but could not support thousands of employees who openly chose it over Microsoft’s primary AI coding platform.  

The Rise Of Claude Code Inside Microsoft 

The use of Claude code grew quietly within Microsoft.  

At first, engineers used Claude Code for smaller tasks such as shell scripting, migration assistance, API documentation, and resolving tricky dependency issues. Over time, its use grew. Teams found that it handled complex reasoning well and could follow logic across many files without losing track, which helped with enterprise workflows.  

This became a direct challenge to the company’s planned GitHub Copilot CLI transition strategy.  

Microsoft invested heavily in making Copilot work with Visual Studio, Azure, GitHub, and command-line tools. Internal use was important because enterprise customers often follow Microsoft’s own policies. If employees preferred Anthropic’s tools, customers would see that.  

Even the mere appearance of this situation posed a risk for Microsoft. Newland, a Fortune 500 CIO looking at AI development platforms, expects Microsoft engineers to use Microsoft’s own tools. If not, it makes sales discussions harder, gives competitors an advantage, and raises questions about product quality.  

That pressure explains why the Experiences and Devices division tool policy was escalated quickly rather than remaining an isolated security recommendation.  

Why Did Microsoft Stop Using Claude Code Internally? 

The central question behind this shift why Microsoft stopped using Claude Code internally comes down to corporate control more than model quality.  

Microsoft already has strict compliance rules for its internal code, customer environments, and regulated workloads. Using external AI systems makes things more complicated, since every prompt could become a governance issue.  

For example, if a Windows engineer is fixing authentication logic for enterprise identity systems, even cleaned-up prompts might reveal patterns, design choices, or internal details. Security teams want clear boundaries, especially since AI systems learn from user data.  

Microsoft also wants its engineers’ actions to better align with its product strategy.  

This is important because GitHub Copilot is now more than just a coding assistant. It is central to Microsoft’s enterprise AI offerings. Azure runs many of the core workloads. GitHub earns revenue from developer subscriptions, and Microsoft sales teams promote Copilot integrations to companies seeking AI-powered software development.  

Relying on Claude’s code inside Microsoft made this story less convincing.  

The new policy made developers part of Microsoft’s push to standardize its own tools.  

The Push Toward GitHub Copilot CLI 

The broader GitHub Copilot CLI transition effort now serves two goals simultaneously: including security oversight and reinforcing Microsoft’s internal AI ecosystem.  

Developers have reportedly received updated internal software developer guidelines detailing approved AI workflows, acceptable repository interactions, and restrictions around internal reference tools. Those policies mirror changes across large enterprises as they attempt to contain AI sprawl.  

This issue isn’t just Microsoft; it affects the whole tech industry.  

Now every major tech company faces the same question: Should employees use the best AI model or the one the company can fully control?  

This choice becomes more important as coding assistants get deeper access to company systems, customer infrastructure, and deployment pipelines.  

Ironically, the controversy may strengthen Anthropic’s reputation. If Microsoft engineers aggressively adopted Claude Code before restrictions arrived, enterprises may interpret that behavior as validation of the product’s technical strengths. This creates new momentum for the broader Anthropic enterprise coding alternative market, especially among companies seeking options outside the Microsoft system.  

Microsoft’s strict response shows this is more than just internal tools. AI coding assistants are no longer just productivity experiments. They now influence platform control, enterprise trust, and competition in the software industry.

Source: Microsoft Source 

Mountain View, California 

However, governments and highly regulated industries are urgently revamping their strategies for developing AI infrastructure amid escalating geopolitical challenges, cybersecurity issues, and data sovereignty concerns worldwide. Sectors that handle sensitive information, such as national security, finance, healthcare, and defense, seek more sophisticated AI systems without compromising their internal systems through exposure to the public internet. 

This shift has accelerated demand for Google Distributed Cloud air-gapped sovereign AI 2026 infrastructure models designed to operate independently from globally connected cloud ecosystems.  This technology helps organizations run sophisticated AI applications within fully isolated computer infrastructures, disconnected from the outside world. 

It shows how vital sovereign AI infrastructure becomes as organizations seek solutions to create air-gapped clouds for their governments. 

As governments and regulated industries seek a way to construct an air-gapped cloud environment, isolated AI infrastructure is one of the fastest-growing categories in enterprise cloud computing. 

Why Air-Gapped Infrastructure Is Coming Back 

For a long time, cloud technology use was focused on centralizing connections and providing access to infrastructure located around the world. Today, however, the increasing threat of cyberattacks, as well as growing geopolitical uncertainty, is driving organizations to return to isolated computing infrastructure. 

Air-gap technology provides physical separation of systems from internet access, significantly reducing the risk of cyberattacks in high-stakes environments. 

With Google’s new Distributed Cloud Air-Gapped Technology, users can run AI services, cloud orchestration, and analytics in disconnected environments. 

These industries are projected to adopt this technology extensively: 

  • Defense organizations 
  • Intelligence agencies 
  • Financial organizations 
  • Energy infrastructure 
  • Healthcare systems of nations 

The rise of Google Distributed Cloud public internet detached defense strategies reflects a broader realization that some sensitive operations cannot safely operate within traditional globally connected public cloud ecosystems.  

Strategic Sovereign AI Investments on the Rise 

National governments all around the world are now worried about the geographic location of their AI models, their data storage capabilities, and any potential external provider of infrastructure access. 

It is resulting in increased investments in sovereign AI infrastructures aimed at ensuring complete control over the sensitive environments. 

The strategies are currently based on the following aspects: 

  • Data residency 
  • Infrastructure governance 
  • Limited external network access 
  • AI model execution locally 
  • National cyber resilience 

The expansion of sovereign AI geopolitical compliance air-gap deployment systems reflects growing concerns over international data governance, cyberwarfare risks, and regulatory pressure surrounding critical infrastructure.  

Security Based on Physical Infrastructure Control 

The most critical aspect within Google’s air-gapped cloud system concerns the use of hardware cryptographic security keys. 

Unlike regular cloud systems that rely heavily on remote management technologies, air-gapped environments require an independent, trusted physical infrastructure component. 

These features include: 

  • Physical cryptographic keys 
  • Key management locally 
  • Workload isolation verification 
  • Offline infrastructure authorization 
  • Trust infrastructure validation 

The increasing reliance on hardware cryptographic security keys is just another example of industry trends aimed at enhancing physical infrastructure security capabilities. 

AI Models Need to be Run Locally 

A critical challenge in implementing sovereign AI models is handling sophisticated models without the aid of cloud-based inference infrastructure. 

To solve the problem mentioned above, Google offers the ability to configure local model deployment. 

This approach supports running the following models locally: 

  • Large language models 
  • Autonomous AI models 
  • Analytical systems 
  • Computer vision algorithms 
  • Sensitivity inference models 

within a secure infrastructure environment. 

Local model deployment configuration is critical because most governments and regulated companies are not permitted by law to send any operational data to the outside world using cloud connections. 

Moreover, local inference enables greater resilience, as the AI model can still function even in the event of disruptions to external communication. 

Isolation Compliance Pressures Are Shaping Cloud Infrastructure 

Compliance pressures are fast becoming a key reason isolated clouds will become popular. 

With increasing amounts of sensitive data and infrastructure, there is a greater need for compliance standards that regulate how such data can be managed. 

In addition, industries that handle sensitive and regulated information need compliance structures that ensure data protection in a cloud environment. 

These industries include: 

  • Financial institutions and banks 
  • Health care facilities 
  • Defensive corporations 
  • Utilities 
  • Government entities 

Increased regulation in these industries has led to a greater need for isolated clouds with compliance and data protection structures that allow flexibility to meet regulatory requirements. 

The rise of Google air-gapped cloud defense regulated industry AI systems aligns directly with these increasingly strict regulatory frameworks.  

Air-Gapped AI Infrastructure Becoming Increasingly Common 

The rise of sophisticated AI technologies has led to a significant increase in demand for secure isolated infrastructure. 

Historically, most instances of air gaps were primarily concerned with isolation in storage and communications. However, there is renewed interest in creating fully functional AI systems that do not rely on any external connections. 

As such, questions about creating an air-gapped cloud infrastructure suitable for government use have become more common and pressing. 

Some of the core elements needed today include: 

  • AI isolation 
  • Secure workload portability 
  • Localized inferencing 
  • Access control 
  • Operational resiliency 

The broader question of how does Google Distributed Cloud fully air-gapped hardware deployment allow defense agencies and regulated industries to run advanced AI models completely detached from the public internet is becoming central to enterprise AI infrastructure planning.  

Google’s newest cloud platform appears to be aiming to achieve all those goals through a sovereign approach. 

Conclusion 

Google’s distributed cloud and air-gapped infrastructure development represent one of the key changes in enterprise and governmental computing strategy now underway. The use of disconnected cloud services with advanced hardware-based cryptographic security keys, superior local model deployment configurations, and support for sovereign AI localization infrastructure enables By combining Google Distributed Cloud cryptographic key local model deployment capabilities with advanced physical trust systems and sovereign governance controls, Google is positioning itself aggressively within the rapidly growing sovereign AI infrastructure market. 

The increasing importance of sovereign AI geopolitical compliance air-gap deployment strategies also reflects how cybersecurity, regulation, and geopolitics are now directly influencing cloud architecture decisions. 

With the rise of geopolitical and cybersecurity threats worldwide, air-gapped AI systems might soon become a critical element in the infrastructure plans of governments and enterprises. 

When considering ways to create an air-gapped cloud infrastructure for government, organizations should be aware that air-gapped clouds are becoming an increasingly important component of strategic infrastructure initiatives.

Source- Infrastructure Modernization 

ROUND ROCK, TX — 

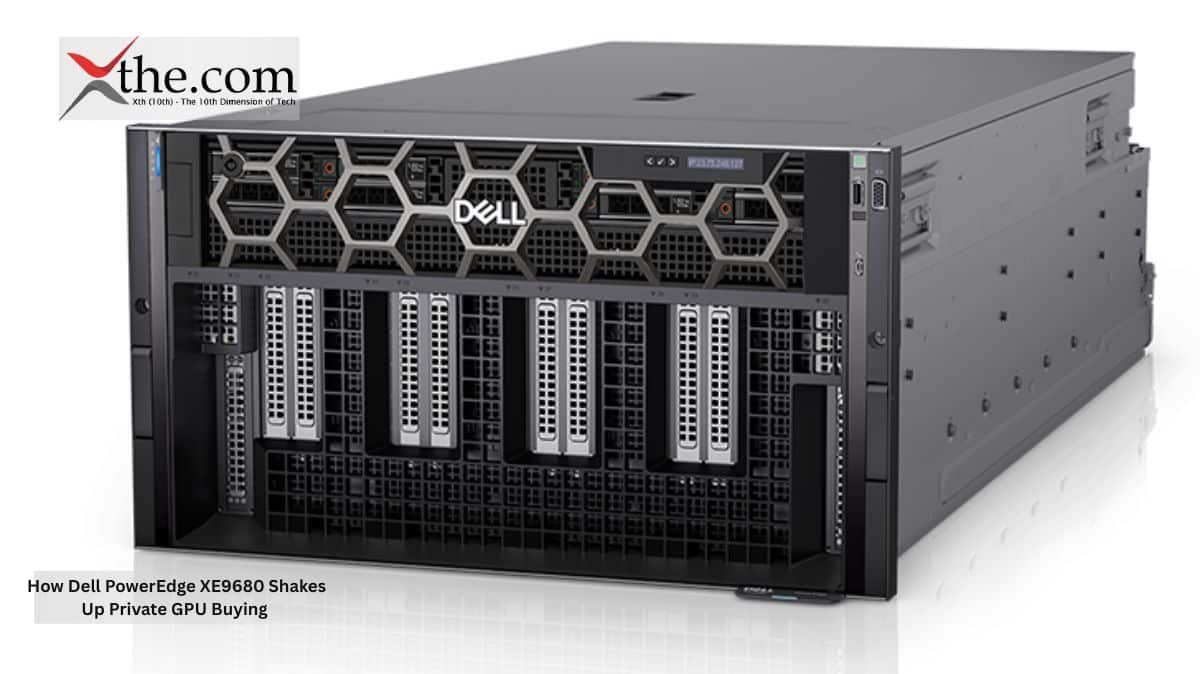
The Dell PowerEdge xe9680 configuration update addresses the infrastructure bottleneck that has been quietly limiting enterprise private AI deployment performance  not GPU compute capability, not memory capacity, but the PCIe switch fabric bandwidth throughput congestion that occurs when eight high-performance accelerators compete for interconnect bandwidth that the switch fabric cannot serve simultaneously without queuing delays that compound into training throughput degradation. As enterprise deep learning cluster scaling on private infrastructure becomes a board-level AI strategy commitment, the best server hardware for private enterprise deep learning should eliminate interconnect bottlenecks rather than simply maximize per-GPU specifications. 

The PCIe Congestion Problem Limiting Eight-Way GPU Performance 

High-density accelerator server architecture with eight GPUs creates interconnect bandwidth requirements that PCIe bus topology must simultaneously satisfy across all accelerator pairs during collective communication operations  AllReduce gradient synchronization, tensor parallel weight distribution, and pipeline parallel activation transfer all generate traffic patterns that require every GPU to communicate with every other GPU at near-simultaneous intervals, as switch fabric contention degrades.  

PCIe switch fabric bandwidth throughput congestion in previous XE9680 configurations occurred when multiple accelerator pairs attempted simultaneous communication through shared switch fabric segments  creating queuing delays that collective communication operations cannot tolerate because stalled gradient synchronization stalls the full training step across all eight GPUs, regardless of which specific GPU pair is experiencing the congestion. Eight GPUs operating at 90% individual utilization but experiencing 15% collective communication delays deliver effective training throughput below that of four fully utilized GPUs.  

Enterprise deep learning cluster scaling economics make this bottleneck particularly damaging  enterprises that invest in eight-GPU server hardware to achieve training throughput that justifies the capital premium over four-GPU configurations receive training performance closer to the four-GPU baseline when switch fabric congestion degrades collective communication efficiency that eight-way training depends on. 

Updated Switch Fabric Architecture 

Dell PowerEdge xe9680 switch fabric upgrade provides dedicated bandwidth paths between accelerator pairs, eliminating the shared-segment contention that previous configurations experienced under simultaneous multi-GPU communication loads. The updated topology ensures that any GPU-to-GPU communication pair can achieve full bandwidth simultaneously with any other GPU-to-GPU pair removing the traffic serialization imposed by shared switch segments when collective operations require all-pairs communication within the same synchronization window.  

PCIe switch fabric bandwidth throughput improves with the topology update, delivering sustained bandwidth during the collective communication phases generated by training workloads not peak bandwidth achieved by sequential communication without contention, but sustained bandwidth under the simultaneous multi-directional traffic that AllReduce operations require from all eight accelerators at once.  

The redesign of the high-density accelerator server architecture’s switch fabric also improves NVMe storage access consistency during training  reducing latency spikes for storage read operations that compete with GPU-to-GPU communication for shared switch fabric bandwidth during intensive training phases. Dedicated bandwidth allocation that the updated fabric provides eliminates storage access latency variability that interrupts data pipeline feeding efficiency during training runs. 

On-Premises Capital Deployment Economics 

On-premises hardware capital deployment for eight-GPU server configurations requires justification against cloud GPU rental alternatives that enterprise finance teams apply increasingly rigorous scrutiny to  the capital investment in XE9680 hardware must demonstrate total cost of ownership advantages over equivalent cloud GPU hours that become visible only when hardware utilization efficiency reaches the levels that switch fabric congestion previously prevented.  

Best server hardware for private enterprise deep learning: TCO analysis improves materially when switch fabric updates recover the training throughput degradation caused by congestion — enterprises whose XE9680 utilization metrics showed hardware operating below theoretical throughput capacity receive performance improvements from configuration updates that close the utilization gap without additional hardware investment.  

Enterprise deep learning cluster scaling through XE9680 private deployment also provides data sovereignty advantages that cloud GPU rental cannot match  training on proprietary model architectures, sensitive customer data, and competitive IP that enterprises cannot route through cloud provider infrastructure gains the eight-GPU training throughput that private hardware delivers without the data handling exposure that cloud training creates. 

Hardware Utilization and Training Throughput Recovery 

High-density accelerator server architecture utilization improvement from switch fabric congestion elimination compounds across the training job portfolio that enterprise AI teams run faster individual training jobs that complete in less wall-clock time, free hardware capacity for subsequent jobs sooner, increasing the effective training throughput of the full hardware investment beyond the per-job improvement that congestion elimination delivers.  

PCIe switch fabric bandwidth throughput consistency, which the updated XE9680 configuration also provides, also improves training job completion time predictability  congestion-induced variability that caused identical training configurations to complete in different wall-clock times depending on traffic conditions made scheduling optimization difficult. Consistent throughput provided by a congestion-free switch fabric enables training-pipeline scheduling that maximizes hardware utilization across the full job queue, rather than padding schedules with variability buffers.  

Dell PowerEdge xe9680 configuration update deployment for existing hardware installations applies through Dell’s standard firmware update pathway enterprises that have already deployed XE9680 hardware capture the switch fabric improvement through update deployment rather than hardware replacement, protecting capital investments that previous configurations failed to deliver against their specifications. 

Conclusion 

The updates to the switch fabric configuration on the Dell PowerEdge xe9680 switch will resolve the PCIe bus congestion bottleneck that had prevented eight GPU private AI server deployments from achieving the training throughput specified by the hardware. This improves PCIe switch fabric bandwidth by using a dedicated bandwidth path topology that eliminates collective communication contention, thereby improving multi-GPU training efficiency to the point that private hardware capital investment must now be justified over cloud rental alternatives. 

Recovering access to high-density accelerator server architecture by eliminating congestion also reduces the time required to complete training jobs, increases the availability of hardware capacity for future jobs, and ensures consistent throughput required for optimizing training pipeline scheduling. Scaling enterprise deep learning clusters on private XE9680 infrastructure provides data sovereignty protection while delivering surpassed cloud rental training throughput economics for sensitive workloads. Total cost of ownership (TCO) for private on-premises hardware capital deployments reflects the cost advantage of private infrastructure over congestion-degraded performance, with switch fabric efficiency improvements included in TCO. Given that the best private enterprise deep learning evaluation frameworks include interconnect efficiency alongside GPU specifications, the XE9680 switch fabric update demonstrates that the configuration architecture is just as important as the accelerator specifications for the training performance that will actually be realized through procurement comparisons.

Source: Dell Blog 

SAN JOSE, CA — 

The Supermicro liquid–cooled racks modular turnkey release targets the operational constraint that has become the binding limit on AI infrastructure expansion not GPU availability or capital budget, but the electrical grid capacity ceiling that cooling infrastructure overhead consumes before compute hardware receives its share. As a coolant distribution unit, energy savings compress the cooling fraction of the total facility power draw, and the plug-and-play modular architecture eliminates the deployment complexity that previous liquid-cooling installations required. Reducing power usage effectively in data centers has a hardware answer that operators can deploy within weeks rather than quarters. 

The Grid Constraint Liquid Cooling Solves 

High-density computing thermal layout at AI accelerator density generates thermal output that forces a power allocation decision that air-cooled data centers resolve unfavorably dedicating increasing percentages of available facility power to cooling infrastructure that serves thermal management rather than compute throughput. A facility operating at 1.5 PUE allocates 33% of total power draw to cooling overhead; reducing PUE to 1.1 through liquid cooling reclaims that cooling overhead as available compute capacity without requiring utility service upgrades.  

How to reduce power usage effectiveness in data centers running AI workloads requires thermal management that scales with compute density rather than with facility floor space  air cooling that distributes thermal management burden across the full data center volume becomes less efficient as AI rack density concentrates thermal output in specific floor areas that localized cooling infrastructure must manage at intensities that room-level HVAC cannot address without overcooling the surrounding floor space that wastes cooling capacity on under-utilized areas.  

Coolant distribution unit energy savings from Supermicro’s redesigned CDU architecture stem from the thermodynamic efficiency difference between liquid and air heat transfer at equivalent thermal loads  liquid coolant that extracts heat conductively from chip-level interfaces operates at a fraction of the energy cost of moving equivalent air volumes through high-static-pressure server chassis. The fan power reduction alone from eliminating high-speed server fans, which air cooling requires, generates measurable energy savings that CDU pump power consumption does not fully offset. 

Plug-and-Play Modular Architecture and Deployment Speed 

The use of plug-and-play modular architecture in Supermicro’s turnkey liquid-cooled rack systems eliminates the deployment barriers that previously made liquid cooling a specialized installation rather than a standard configuration in data centers. To date, liquid cooling systems require customized plumbing, specialized installation contractors, lengthy commissioning times, and downtime during installation that cannot be readily accommodated by operating data centers. 

The turnkey delivery of hardware infrastructure using Supermicro’s modular approach results in complete rack delivery, including integrated chiller distribution unit (CDU) manifolds, pre-piped coolant distribution infrastructure, and quick-connect fittings, enabling integrated installation with no custom pipe fabrication for operators. Operators will receive a system that connects to the facility’s supply and return lines via standard connections, reducing installation timelines from a multi-week facility remodel to a few days for equipment deployment and eliminating facility downtime except for the time required to install the rack. 

Supermicro liquid-cooled racks‘ modular CDU design also enables incremental deployment scaling that an all-or-nothing facility liquid-cooling infrastructure cannot accommodate  operators can deploy liquid-cooled rack capacity in increments that workload growth requires, rather than investing in facility-wide liquid-cooling infrastructure before the workload volume that justifies full deployment has materialized. 

CDU Energy Savings and PUE Impact 

SuperMicro’s CDU design saves energy by reducing the cooling power “overhead” load by 40% compared with the existing solution. This result is achieved with three benefits brought on by this new CDU architecture: 
1. Higher coolant return temperature facilitates increased chiller energy efficiency; 
2. The elimination of high-speed fan-cooled servers reduces fan power consumption; and 
3. Using a lower total volume of air to distribute high heat absorption loads via a water-cooled distribution system versus a traditional HVAC system saves energy for the entire building cooling system, including the HVAC mechanical equipment and associated distribution piping systems. 

High-density computing thermal layout optimization that Supermicro’s rack architecture enables allows operators to position high-density AI accelerator racks without the spacing requirements that air cooling hot-aisle-cold-aisle containment imposes liquid-cooled racks that extract heat through coolant loops rather than exhaust airflow can be positioned in configurations that optimize network topology and storage proximity rather than thermal airflow management, improving infrastructure utilization efficiency alongside energy efficiency.  

How to reduce power usage effectiveness in data centers from the 1.4-1.6 PUE range that air-cooled AI workload facilities commonly operate at toward the 1.05-1.1 range that liquid cooling enables generates annual energy cost savings that accelerate hardware investment recovery — the cooling energy cost reduction at scale represents millions of dollars annually for hyperscale deployments and hundreds of thousands for enterprise data centers that justify liquid cooling investment through operational savings rather than only through compute density gains. 

Regional Grid Limitation Navigation 

Turnkey hardware infrastructure deployment with Supermicro’s modular system enables AI infrastructure expansion within regional electrical grid constraints, where utility capacity limits prevent expansion through additional power service. Operators whose facilities have reached utility service capacity limits can increase compute throughput within existing power budgets by reclaiming the cooling overhead that PUE improvement delivers deploying Supermicro liquid-cooled racks that operate at 1.1 PUE within a facility power budget previously supporting 1.5 PUE air cooling provides 36% more compute capacity from the same utility service connection.  

Plug-and-play modular architecture deployment timelines that compress liquid-cooling installation from months to weeks; also address the grid-constraint navigation timeline utility service upgrades that require regulatory approval, infrastructure construction, and interconnection agreements operate on 12-24 month timelines that AI workload demand growth cannot wait for. Liquid-cooling efficiency improvements that expand effective compute capacity within existing grid connections provide the near-term capacity-expansion path that utility upgrade timelines cannot deliver. 

Conclusion 

Supermicro’s liquid-cooled racks and modular turnkey architecture deliver the cooling efficiency transformation that AI workload density requires without the facility reconstruction timeline that custom liquid-cooling installations historically imposed. Plug-and-play modular architecture compresses liquid-cooling deployment from a multi-month facility project into a weeks-long equipment installation that operational data centers can execute without downtime.  

Coolant distribution unit energy savings of up to 40%, cooling power overhead reduction, reclaim grid capacity that air cooling overhead consumes enabling compute density expansion within regional electrical grid constraints that utility service upgrades cannot resolve on AI infrastructure demand timelines. The thermal layout flexibility enabled by liquid cooling improves rack positioning optimization and energy efficiency. Turnkey hardware infrastructure deployment scaling in increments that workload growth justifies, protects capital investment against over-provisioning, and requires a full facility of liquid cooling infrastructure upfront. As reducing power usage effectively in data centers becomes the operational priority that grid-constrained AI infrastructure expansion demands, Supermicro’s modular CDU architecture provides the deployment-ready efficiency improvements that power budget limitations make immediately actionable.

Source: Superior Cooling Reduces Power, Water, Noise, and Space 

ARMONK, NY — 

The IBM Granite models Apache 2.0 release reframes enterprise AI procurement from a subscription obligation into a capital infrastructure decision and the financial math behind that reframing is compelling enough to demand immediate CIO attention. As open-source enterprise parameter weights under the Apache License model, commercial use eliminates the per-token billing that cloud model providers have normalized as an unavoidable AI infrastructure cost. How to run open source frontier models on local servers becomes the procurement question that separates enterprises building durable AI cost structures from those accumulating subscription dependencies that compound with every additional use case they activate. 

The Vendor Lock-In Economics Apache 2.0 Breaks 

The Apache licensing model provides significant freedom for commercial use. This is important because it removes the three lock-in mechanisms that arise from cloud providers’ subscription-based models. These are: 

1. The method of billing for usage (per-token) varies based on total usage volume rather than being a fixed amount based on the amount of infrastructure cost incurred. 
2. The fact that all enterprise data is routed through the cloud provider’s infrastructure, regardless of whether the enterprise has any say in the security or sovereignty of how they store their data. 
3. The cloud provider’s decision regarding the cost of AI capabilities will dictate what the business can produce in the future. 

With the improved Granite 3.0 platform and local compute budgets for cloud providers, businesses migrating from cloud-based service providers to Granite can realize significant savings. Businesses are currently spending an estimated $9.2 billion annually on API services from cloud providers for businesses that process over 100 million tokens per month, while a private environment allows them to purchase hardware to support multiple model deployments over a five-year infrastructure lifecycle. 

Open source enterprise parameter weights under Apache 2.0 also eliminate the audit opacity that proprietary model subscriptions impose on regulated enterprises compliance frameworks that require explainability, bias documentation, and training data provenance for AI systems used in consequential decisions receive Granite 3.0’s full model documentation, training methodology disclosure, and parameter transparency that closed model providers do not provide, regardless of contractual commitments. 

The Price-Per-Token Math CIOs Need to Run 

How to run open source frontier models on local servers cost comparison requires modeling three variables that cloud provider pricing obscures: the fully loaded cost per token on owned infrastructure, including hardware amortization, energy, and operations; the fully loaded cost per token on cloud provider APIs, including base pricing, egress costs, and volume-tier penalties; and the breakeven token volume where infrastructure investment recovers against subscription avoidance.  

Local server compute budget savings modeling for Granite 3.0 on-premises deployment should use current GPU server hardware costs amortized over 5 years, compared with the inference throughput that Granite 3.0’s optimized architecture delivers on that hardware. IBM’s optimization of Granite 3.0 for efficient inference on standard enterprise GPU hardware rather than requiring specialized accelerator configurations that frontier model scale typically demands compresses the hardware investment required to achieve the production inference throughput that enterprise workload volumes demand.  

Private cluster infrastructure deployment economics improve further when existing GPU infrastructure that enterprises already operate for other workloads provides spare capacity for Granite 3.0 inference  the marginal cost of adding inference workloads to infrastructure whose fixed costs are already absorbed approaches the energy cost of the inference compute alone, making the per-token economics of existing infrastructure utilization dramatically favorable against cloud API billing for equivalent workloads. 

Apache 2.0 Compliance Framework for Regulated Enterprises 

The Apache License model’s commercial use terms provide the legal clarity that enterprise legal and compliance teams require before deploying open-source AI models in commercial applications  permitting commercial use, modification, and redistribution without a royalty obligation, while requiring attribution and license notice preservation, which standard enterprise software deployment practices already satisfy.  

Open source enterprise parameter weights transparency enables the compliance documentation that regulated industries require for AI systems involved in consequential decisions  financial services firms subject to model risk management guidelines, healthcare organizations subject to AI clinical decision support regulations, and federal contractors subject to AI transparency requirements can satisfy documentation obligations with Granite 3.0’s accessible training methodology and parameter disclosure that proprietary model providers cannot match.  

Private cluster infrastructure deployment under Apache 2.0 also satisfies the data sovereignty requirements that prevent cloud model API deployment for regulated data categories — patient health information, financial transaction data, and classified operational information that cannot leave enterprise-controlled infrastructure routes through Granite 3.0 inference on private clusters without the cloud transmission that API-based model access requires. 

Private Cluster Deployment Architecture 

How to run open source frontier models on local servers using Granite 3.0 requires infrastructure configuration that IBM’s deployment documentation covers for standard enterprise GPU server environments model weight loading, inference server configuration, and API endpoint deployment that makes Granite 3.0 callable by enterprise applications through the same interface patterns that cloud model APIs use, enabling drop-in substitution for cloud model calls without application code modification.  

Private cluster infrastructure deployment at enterprise scale requires attention to inference serving architecture that maximizes throughput efficiency on available GPU hardware — batching strategies, quantization configuration, and memory management that IBM’s Granite 3.0 optimization documentation specifies for different hardware configurations affect the tokens-per-second throughput that determines whether private cluster capacity satisfies enterprise workload volume requirements before additional hardware investment is needed.  

Local server compute budget savings from Granite 3.0 deployment compound when inference serving infrastructure serves multiple enterprise applications through a shared private cluster rather than requiring dedicated hardware per application the infrastructure investment that a single high-priority application justifies provides capacity that additional applications consume at near-zero marginal infrastructure cost. 

Conclusion 

IBM Granite models’ Apache 2.0 release provides the financial and architectural freedom that vendor lock-in economics have withheld from enterprise AI procurement open-source enterprise parameter weights that deploy on owned infrastructure under the Apache license model’s commercial use terms eliminate the subscription dependencies that cloud model providers have normalized as unavoidable AI cost structure.  

Local server compute budget savings from private cluster deployment replace variable per-token cloud billing with fixed infrastructure amortization, improving per-unit economics as usage scales. Private cluster infrastructure deployment satisfies data sovereignty and compliance documentation requirements that cloud API deployment cannot address for regulated data categories. The Apache License model for commercial use transparency provides the documentation that regulated enterprise compliance frameworks require for AI systems involved in consequential decisions. As how to run open source frontier models on local servers becomes the infrastructure strategy that CIOs with genuine cost discipline pursue, the subscription model cartel that cloud AI providers have built faces its most credible architectural challenge from IBM’s decision to release Granite 3.0 as genuinely free enterprise infrastructure.

Source: IBM Newsroom 

HOUSTON, TX — 

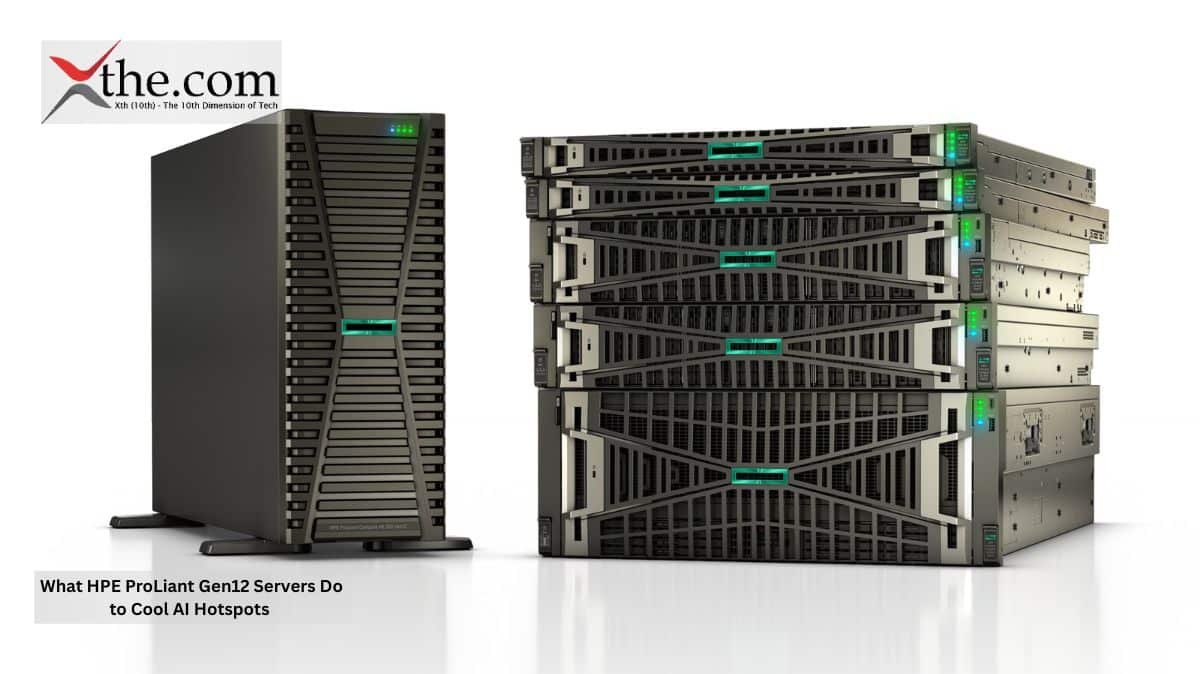
The HPE Proliant Gen12 servers release addresses the thermal wall that data center operators running AI accelerator workloads have been hitting with increasing frequency  not a theoretical capacity limit but an active operational constraint where high-density accelerator thermal efficiency failures are forcing throttling decisions that undermine the compute investment justification. As datacenter energy draw limits at the facility level prevent simple horizontal scaling, and rack-scale computing power density continues to increase with each GPU generation, liquid-cooling direct-to-chip architecture transitions from a premium option to an operational prerequisite that AI workload economics require. 

The Thermal Wall AI Density Creates 

High-density accelerator thermal efficiency failure in data centers running current-generation AI training configurations manifests as localized energy density spikes that facility HVAC systems cannot dissipate at the rack level. Conventional raised-floor air cooling that manages thermal output at the room level distributes cooling capacity across the full data center floor  a distribution model that worked when thermal output was relatively uniform across rack populations but breaks down when AI accelerator racks generate 40-80 kW of thermal output in a physical footprint that standard cooling capacity was sized to manage at 10-15 kW.  

Datacenter energy draw limits at the facility level compound the thermal problem utility service capacity, transformer ratings, and electrical distribution infrastructure that existing facilities were built around create power ceilings that prevent operators from simply adding more cooling infrastructure to compensate for air cooling’s thermal density limitations. The thermal wall and the power wall arrive simultaneously for AI workload density, making architectural solutions that address both constraints at the rack level the only path forward that does not require facility reconstruction.  

Best enterprise rack servers for intensive model training must therefore solve thermal management at the chip level rather than delegating it to facility infrastructure  HPE Proliant Gen12 servers integrated closed-loop manifold architecture is the engineering response to a thermal physics problem that ambient air cooling cannot solve at AI accelerator density, regardless of facility HVAC investment. 

Direct-to-Chip Cooling Mechanics 

With liquid cooling in the ProLiant Gen12 servers, direct-to-chip cooling delivers a supply of cooled liquid directly to each thermal interface (i.e., CPU, GPU, memory subsystem) via integrated manifolds that extract heat before it dissipates into the airspace of the rack (the air-cooled rack would have to pull the heat from air). The closed-loop design allows the continued circulation of the liquid between the chip/cold plate and the facility’s heat exchange (not in contact with the rack environment), and it eliminates the risk of leaks associated with open-loop or exposed liquid-cooling systems located near high-voltage server hardware. 

High-density accelerator thermal efficiency improvement from direct-to-chip cooling derives from the thermal resistance difference between conductive liquid heat transfer and convective air heat transfer liquid coolant that contacts the chip package surface extracts heat at rates that airflow across the same surface cannot approach, maintaining junction temperatures within operating specifications at power densities that air cooling would require dramatically increased airflow volumes to manage. The reduced airflow requirement enabled by liquid cooling allows ProLiant Gen12 configurations to reduce fan power consumption while maintaining thermal compliance compounding the energy efficiency gain beyond the direct cooling efficiency improvement.  

Rack scale computing power density that ProLiant Gen12 liquid cooling enables allows operators to double the accelerator count per rack footprint that thermal constraints previously imposed  a 40-GPU rack configuration that previously required two racks and the associated floor space, power distribution, and network cabling fits within a single ProLiant Gen12 rack that direct-to-chip cooling keeps within thermal and power limits. 

Facility Impact and HVAC Retrofit Avoidance 

Datacenter energy draw limits at existing facilities become manageable under ProLiant Gen12 direct-to-chip cooling architecture because heat extraction moves from the facility HVAC domain into the rack-level coolant loop domain reducing the thermal burden that facility air conditioning systems must manage while increasing compute density that power distribution infrastructure serves. Facilities that cannot expand HVAC capacity gain compute density headroom through liquid cooling, which air-cooling expansion would require, and would require facility construction to deliver.  

Best enterprise rack servers for intensive model training deployment in existing facilities benefit from ProLiant Gen12’s coolant distribution unit compatibility with standard data center coolant infrastructure facilities that have invested in coolant distribution infrastructure for other liquid-cooled hardware can integrate ProLiant Gen12 manifolds without dedicated CDU deployment that new liquid cooling infrastructure would otherwise require.  

Liquid-cooling direct-to-chip manifold installation within ProLiant Gen12 servers ships as an integrated factory configuration rather than a field retrofit  eliminating the installation complexity that aftermarket liquid-cooling additions to standard server hardware introduce and providing the thermal interface quality that factory-integrated cold plate mounting delivers compared to field-installed alternatives. 

Best Enterprise Rack Servers for AI Training Workloads 

The thermal management of HPE Proliant Gen12 servers enables continuous, high-performance AI training throughput that higher-performance air-cooled alternatives cannot deliver due to thermal throttling. The GPU clusters with direct-to-chip cooling will run at full clock rates for long-duration AI training jobs because the cooling keeps junction temperatures below the thermal throttling threshold, enabling much faster completion without thermal throttling, even with the same hardware specifications. 

Rack-scale computing power consistency across extended training runs provides the predictable compute throughput that training job scheduling requires air-cooled configurations that throttle under sustained load generate variable throughput, making training completion time estimates unreliable and wasting GPU hours during thermal recovery periods consumed between sustained workload phases.  

High-density accelerator thermal efficiency at ProLiant Gen12 density levels enables the GPU-to-storage-to-network ratio optimization that AI training cluster design requires fitting more GPU compute within the rack footprint that storage and network infrastructure already serve improves the infrastructure utilization ratio that training cluster economics depend on. 

Conclusion 

HPE Proliant Gen12 servers‘ direct-to-chip liquid-cooling architecture resolves the thermal wall that AI accelerator density has created for data center operators whose facility HVAC systems cannot scale in proportion to GPU compute investment. Liquid cooling, direct-to-chip, closed-loop manifold integration extracts heat conductively at silicon-level interfaces that air cooling cannot match at equivalent power density enabling compute doubling per rack footprint that rack-scale computing power economics require without facility reconstruction.  

High-density accelerator thermal efficiency, enabled by sustained full-clock-rate GPU operation, delivers training throughput consistency that throttled air-cooled configurations cannot match over extended job durations. Datacenter energy draw limits that prevent HVAC expansion become manageable when the thermal burden shifts from facility air conditioning to rack-level coolant loops served by the existing CDU infrastructure. As the best enterprise rack servers for intensive model training evaluation frameworks incorporate thermal sustained performance alongside peak specification comparison, HPE Proliant Gen12 servers’ direct-to-chip cooling architecture provides the thermal management foundation that AI training cluster economics require at the density that next-generation GPU generations will demand.

Source: Compute servers HPE ProLiant Compute 

AUSTIN, TX — 

The Oracle sovereign cloud cluster architecture arrives as geopolitical risk has become a board-level infrastructure variable rather than a legal department footnote. As localized government infrastructure compliance requirements tighten across the EU, Middle East, Asia-Pacific, and emerging digital sovereignty legislation in Latin America, multinational corporations that built their cloud strategies around centralized hyperscaler hubs face a decoupling mandate that how to build an air gapped cloud network for public sector deployments operationalizes  and that Oracle’s isolated regional installation model delivers as a production-ready architecture rather than a compliance roadmap aspiration. 

The Legislative Pressure Driving Hyperscaler Decoupling 

As a result of hard legislative requirements in many different areas that include regulatory preference and require all levels of government, the resulting increased number of local or regional laws requiring compliance with local or regional government authorities or local regulation most recently includes those in the jurisdiction of the European Union with respect to digital sovereignty, those from data localization activity under the Gulfo Cooperation Council, and regulations under India: as well as, the growing number of regulations for national governance for Artificial Intelligence, all of which have the same data residency requirements and activity-based control requirements on data, that the centralised hyper-scale computing architecture cannot meet. 

The compliance gap is not contractual major cloud providers offer data residency region selection and contractual sovereignty commitments. The gap is architectural. Centralized hyperscaler operations require support access, telemetry routing, and operational management functions that traverse the provider’s global infrastructure regardless of where customer data is stored. Inter-hyperscaler data barrier requirements imposed by emerging legislation prohibit exactly this operational dependency  data that cannot be accessed, managed, or processed by personnel or systems outside the host jurisdiction, regardless of purpose.  

Oracle sovereign cloud isolated regional installations address this legislative requirement at the operational layer, where centralized hyperscalers remain exposed  restricting administrative network access to localized networks, limiting operational personnel to in-jurisdiction employees, and eliminating the cross-border operational dependencies that contractual commitments acknowledge but cannot architecturally prevent. 

Air-Gapped Architecture and Network Path Restriction 

Air-gapped datacenter identity protection within Oracle’s sovereign cloud installations provides the network isolation that distinguishes genuine sovereignty from data residency region selection. Air-gapped architecture means the sovereign cloud cluster has no network path to Oracle’s global cloud infrastructure  administrative traffic, monitoring telemetry, and operational management functions that standard cloud operations route through the provider’s global network are contained within the localized administrative network that the sovereign installation exclusively serves.  

Building an air-gapped cloud network for public sector deployments requires resolving the operational tension that air-gapping creates isolated infrastructure that cannot receive updates, patches, and operational support through standard cloud provider channels requires localized operational capability that most cloud providers cannot sustain in every jurisdiction their customers require. Oracle’s sovereign cloud model addresses this through dedicated in-jurisdiction operations teams with the full Oracle Cloud operations capability required to maintain isolated installations without cross-border operational dependency.  

The use of an air-gapped network architecture provides the categorical assurance that audit frameworks will accept as stronger evidence for inter-hyperscaler barriers enforcement versus monitoring-based isolation detection there cannot be a path to extenor (external) infrastructure, therefore no data can transmitt between the two using this path, regardless of degree of software misconfiguration, degree of compromise of credentialed users, and span and inducement that an isolated or independent software layer would not withstand. 

Cryptographic Key Isolation and Endpoint Protection 

Isolated network cryptographic key management is the security property that air-gapped sovereign cloud architecture delivers for regulated sector deployments where key exposure represents the definitive security failure  financial institutions whose encryption keys protect transaction records, healthcare organizations whose keys protect patient data, and government agencies whose keys protect classified operational information all require key management that physically cannot be accessed from outside the sovereign boundary.  

Air-gapped datacenter identity protection is achieved by deploying a hardware security module within the air-gapped installation, ensuring that cryptographic keys never leave the physical security boundary of the sovereign cluster key generation, storage, rotation, and access authorization execute within HSM hardware protected by the sovereign installation’s physical security controls. External access to key management endpoints is architecturally impossible rather than policy-prohibited, providing the absolute protection that regulated sectors require.  

In Oracle’s sovereign cloud cryptographic architecture, cryptographic keys are stored in a secure location, or “air gap,” away from the compute resources (applications) that will process the data. Therefore, no applications that use encryption keys are ever allowed to acquire those keys directly; instead, they must use an HSM interface to perform all cryptographic data protection operations, so that the key material never resides in application memory, where it could be compromised through software vulnerabilities. By separating the two (key management and compute operations), Oracle ensures cryptographic integrity is maintained at all times, regardless of whether application-layer security is compromised. 

Regulated Sector Deployment Scenarios 

Localized government infrastructure compliance requirements for public sector deployments represent the most demanding sovereign cloud validation environment government agencies subject to national security classification requirements, public health systems processing citizen health records, and critical infrastructure operators managing power, water, and transportation systems each require cloud infrastructure that satisfies sovereignty requirements that commercial data residency commitments do not address.  

How to build an air-gapped cloud network for public-sector deployments using Oracle’s sovereign cloud model provides government agencies with the full Oracle Cloud service catalog database, analytics, AI inference, and application platforms within an isolated installation that meets national security classification requirements. Government workloads that previously required on-premise hardware because no cloud architecture satisfied sovereignty requirements gain cloud operational advantages within a sovereign boundary that classification frameworks accept.  

Inter-hyperscaler data barrier protection for multinational corporations operating across multiple sovereign jurisdictions requires sovereign cloud installations in each jurisdiction  data generated in EU sovereign installations cannot transit to Gulf or APAC sovereign installations via Oracle’s global infrastructure, because air-gapped architecture lacks cross-installation network paths. Data that requires cross-jurisdictional sharing must traverse approved government-controlled network paths rather than provider infrastructure, thereby satisfying the inter-jurisdictional data barrier requirements imposed by the strictest sovereignty frameworks. 

Conclusion 

Oracle sovereign cloud cluster architecture delivers the air-gapped, cryptographically isolated, locally administered infrastructure that geopolitical risk and legislative sovereignty requirements demand from enterprises that cannot afford to treat data sovereignty as a contractual negotiation. Localized government infrastructure compliance enforcement through physical network isolation removes the cross-border operational dependency that centralized hyperscaler architecture cannot eliminate without dedicated sovereign installations.  

Air gapped datacenter identity protection and isolated network cryptographic key management provide the absolute security guarantees that regulated sectors require  categorical protection that architecture enforces rather than policy prohibits. Inter-hyperscaler data barrier compliance through an air-gapped network topology satisfies the legislative requirements that contractual data residency commitments were always insufficient to address. As how to build an air gapped cloud network for public sector deployments becomes a standard infrastructure planning requirement rather than a specialized government procurement consideration, Oracle’s sovereign cloud cluster model provides the production-ready architecture that geopolitical risk has made essential for any multinational enterprise operating in jurisdictions where data sovereignty is legislatively mandated rather than commercially negotiated.

Source: Sovereign Cloud 

CUPERTINO, CA — 

The Apple intelligence accessibility features suite Apple revealed represents the most significant assistive technology advancement the company has delivered in a single release cycle not because individual features are unprecedented, but because local neural processing integration makes capabilities that previously required specialized standalone hardware available through software updates to devices enterprises already own. As voice-over natural-language descriptions eliminate the terse metadata labels that previous VoiceOver implementations generated, and on-device-generated subtitles remove the network dependency that real-time captioning previously required, the question of how to use Apple intelligence for hardware accessibility becomes a fleet management and compliance budget decision rather than a specialized procurement project. 

Why Local Neural Processing Changes Accessibility Architecture 

Apple’s intelligence accessibility features delivered through on-device Neural Engine processing eliminate the architectural compromise that cloud-dependent accessibility tools impose on enterprise deployments network latency that makes real-time captioning stutter during bandwidth-constrained use, privacy exposure that transmitting accessibility telemetry to cloud processing creates for users with sensitive communication needs, and connectivity dependency that fails users in the offline environments that enterprise field operations frequently involve.  

Voiceover natural language descriptions generated locally through Apple’s generative vision models produce spatial scene descriptions that communicate environmental context at a qualitative depth that metadata-label VoiceOver implementations cannot approach  describing not just that an image contains a person and a document but that a colleague is reviewing a contract at a conference table, with the contextual specificity that blind and low-vision users require to participate fully in visual workplace environments.  

How to use Apple intelligence for hardware accessibility through local neural processing requires no additional infrastructure the Neural Engine silicon in current iPhone, iPad, and Mac hardware executes the generative vision models that produce natural language descriptions without API calls, without cloud subscription costs, and without the data transmission that enterprise security policies restrict for sensitive workplace communications that accessibility users generate alongside all other employees. 

VoiceOver Natural Language Descriptions and Workplace Integration 

Voiceover natural language descriptions through Apple Intelligence generative vision models address the workplace document and interface accessibility gap that previous VoiceOver implementations left open enterprise applications that display complex visual information through charts, dashboards, annotated documents, and multi-panel interfaces generated VoiceOver descriptions that identified UI element types without communicating the informational content that visual users extracted from those elements.  

Apple’s intelligence accessibility features, VoiceOver enhancement, generate descriptions that communicate the informational content of visual elements rather than their structural metadata a sales performance dashboard that previous VoiceOver described as “image, chart, multiple elements” receives a natural language description that communicates the performance trend, the metric values, and the comparative context that the chart was designed to convey. Enterprise employees using VoiceOver gain informational parity with visual colleagues rather than structural awareness without informational content.  

Commercial device fleet refresh procurement planning for enterprise accessibility compliance should account for the VoiceOver enhancement’s Neural Engine silicon requirement devices with Neural Engine generations that support Apple Intelligence generative vision model execution deliver the full natural language description capability, while older devices receive partial accessibility enhancement that does not include generative vision model integration. Fleet refresh cycles that prioritize accessibility-designated devices for Neural Engine-capable hardware upgrades capture the full compliance value that Apple Intelligence accessibility features deliver. 

On-Device Generated Subtitles and Enterprise Communication Accessibility 

On-device-generated subtitles from Apple Intelligence eliminate the network dependency that real-time captioning previously imposed on deaf and hard-of-hearing enterprise employees — cloud-processed captioning that stutters under network congestion during high-stakes meetings, fails entirely during connectivity interruptions, and transmits speech content to external processing infrastructure that enterprise security policies may restrict.  

How to use Apple intelligence for hardware-assisted subtitle generation requires only Neural Engine silicon and local audio processing in enterprise meeting environments where network reliability is variable, where security policies restrict cloud audio transmission, or where international employees need real-time caption translation that cloud latency makes practically unusable. Receive on-device subtitle generation that performs consistently regardless of network conditions.  

On-device-generated subtitle accuracy for enterprise technical vocabulary domain-specific terminology, product names, acronyms, and industry jargon benefits from Apple Intelligence’s on-device language model, which adapts to usage patterns without requiring specialized vocabulary training, unlike enterprise cloud captioning solutions, which charge for it as a configuration service. Technical meeting content that cloud captioning misidentifies due to vocabulary limitations generates accurate captions on-device as the language model adapts to the specific terminology patterns in each user’s enterprise context. 

Vision Pro Eye Tracking and Wheelchair Navigation 

Vision Pro eye tracking wheelchair navigation integration extends Apple Intelligence accessibility enhancement into the physical mobility domain providing wheelchair users with eye-gaze interface control that Vision Pro’s spatial computing environment enables for both digital workplace interaction and, through smart home and mobility device integration, physical environment navigation that transforms Vision Pro from a productivity device into a comprehensive assistive technology platform.  

Apple’s intelligence accessibility features, eye tracking precision that Vision Pro’s sensor array enables, provide the gaze accuracy that wheelchair navigation control requires distinguishing intentional navigation commands from ambient eye movement that less precise eye tracking systems cannot differentiate reliably enough for mobility control applications, where misinterpretation creates physical safety consequences rather than UI interaction errors.  

Commercial device fleet refresh procurement consideration for Vision Pro eye tracking wheelchair accessibility requires enterprise IT teams to evaluate Vision Pro not only as a spatial computing productivity device but as a qualifying assistive technology that accessibility compliance budgets fund through different procurement channels than standard commercial device refresh cycles a procurement categorization that changes both the budget source and the procurement timeline that Vision Pro accessibility deployment follows. 

Enterprise Accessibility Compliance Budget Implications 

Commercial device fleet refresh economics for enterprise accessibility compliance change materially when Apple Intelligence accessibility features deliver assistive technology capability through software updates to standard commercial hardware eliminating the specialized hardware premium that enterprise accessibility procurement previously paid for standalone screen readers, dedicated captioning devices, and separate eye tracking systems that each required individual procurement, configuration, and support overhead.  

How to use Apple Intelligence for hardware accessibility compliance deployment requires enterprise accessibility coordinators to reassess the specialized hardware stack that current accessibility compliance programs maintain identifying where Apple Intelligence features on standard commercial devices provide equivalent or superior capability to specialized hardware that accessibility compliance budgets currently fund as separate line items.  

Voiceover natural language descriptions and on-device generated subtitles delivered through standard iPhone and iPad hardware create a compliance deployment model where accessibility capability scales with standard commercial fleet refresh rather than requiring separate accessibility-specific procurement cycles reducing the administrative overhead that managing parallel commercial and accessibility-specialized device fleets imposes on enterprise IT operations. 

Conclusion 

Apple’s suite of intelligence accessibility features, integrated with local Neural Engine processing, establishes on-device assistive technology capability that enterprise accessibility compliance programs can deploy through standard commercial fleet management rather than specialized hardware procurement. Voiceover natural language descriptions deliver informational parity for blind and low-vision enterprise employees through generative vision model processing, providing terse metadata labels that VoiceOver could not at a comparable depth.  

Device-generated subtitles eliminate the network dependency and security exposure that cloud captioning imposes on deaf and hard-of-hearing employees in security-sensitive enterprise environments. Vision Pro eye-tracking wheelchair navigation extends Apple Intelligence accessibility into physical mobility assistance, positioning Vision Pro as a qualifying assistive technology for accessibility compliance budget funding. Commercial device fleet refresh planning that prioritizes Neural Engine-capable hardware for accessibility-designated devices captures the full Apple Intelligence accessibility feature set that older silicon cannot execute. As Apple’s intelligence for hardware accessibility compliance deployment replaces specialized hardware procurement with standard commercial device management, the accessibility technology budget that enterprise compliance programs maintain can redirect specialized hardware spend toward accessibility program investments that software-delivered capability no longer requires hardware support.

Source: QUICK READ Apple TV to air first major live pro sports event shot on iPhone 17 Pro 

SEATTLE, WA — 

The question of how to manage non-human identities in cloud architecture has moved from a forward-looking governance concern into an active security incident category — and the collaboration that AWS and SailPoint secure agentic AI infrastructure addresses has arrived at the moment when the identity explosion from autonomous agent deployment has outpaced every governance framework that enterprises built for human identity management. As autonomous machine identity tracking becomes the defining security requirement for agentic enterprise environments, the architectural blind spots created by unmanaged service accounts and untracked M2M entitlements are no longer theoretical exposures — they are the attack vectors that adversaries are actively mapping. 

The Non-Human Identity Explosion Behind the Governance Gap 

Organizations are facing the emergence of a new type of governance framework for their non-human identities. This new identity governance layer is being driven by an exponential increase in the number of autonomous software agents performing background system updates, coupled with a vast number of API integrations that produce numerous child processes that inherit the permissions of the parent process, and orchestrated platforms generating services dynamically and creating non-human identities at a rate that far exceeds that of human identity provisioning  all without having any lifecycle governance applied by the organization. 

Enterprise access model defense frameworks built around human identity assumptions  provisioning workflows tied to HR onboarding, access reviews triggered by role changes, deprovisioning initiated by offboarding  have no equivalent trigger for non-human identities that are created programmatically, accumulate permissions through inheritance and scope creep, and persist indefinitely because no offboarding event ever triggers their review.  

Autonomous machine identity tracking addresses the visibility problem that precedes governance enterprises cannot govern non-human identities they cannot see. The service accounts, API tokens, OAuth credentials, and IAM roles that autonomous agents generate during background system updates are often outside the security teams’ identity inventory. How to manage non-human identities in cloud architecture begins with discovery that surfaces the full non-human identity population before governance policy can be applied. 

What the AWS-SailPoint Collaboration Actually Builds 

AWS and SailPoint secure agentic AI infrastructure through a governance architecture that integrates SailPoint’s identity security platform with AWS IAM, AWS Organizations, and AWS Security Hub creating a unified visibility and policy enforcement layer that spans the full non-human identity lifecycle from automated provisioning through continuous access certification to automated deprovisioning when agent workloads terminate.  

Non-human identity governance layer technical implementation within the collaboration provides M2M entitlement tracing that maps the permission relationships between autonomous agents, the downstream services they access, and the data environments those services expose  building the entitlement graph that security teams need to understand what each non-human identity can reach before assessing whether it should reach it.  

Autonomous machine identity tracking through AWS CloudTrail integration with SailPoint’s identity graph ensures that every API call, service account access event, and cross-service permission exercise that autonomous agents generate is attributed to a specific tracked non-human identity  eliminating the attribution gap that untracked service accounts create when incident investigation requires reconstructing the access sequence that preceded a security event. 

Machine-to-Machine Entitlement Tracing and Script Loop Prevention 

Enterprise access model defense against script loop attacks requires entitlement tracing that identifies the permission chains that automated execution can traverse recursively  an autonomous agent with permission to modify its own execution environment, invoke other agents, and write to shared data stores creates the entitlement graph conditions that script loop attacks exploit through legitimate permission exercise rather than permission bypass.  

How to manage non human identities in cloud architecture for script loop prevention requires entitlement analysis that evaluates not just what each non-human identity can access directly but what it can access transitively through the service accounts and downstream agents it can invoke a non-human identity that cannot directly access a sensitive database may be able to invoke an agent that can, creating an indirect access path that direct permission analysis misses.  

Non-human identity governance layer policy enforcement that applies least-privilege constraints to M2M entitlement chains prevents the permission accumulation that script loop conditions require autonomous agents that can only invoke downstream agents with permissions equal to or less than their own cannot escalate access through agent chaining that exceeds the governance boundary established by provisioning policy.  

Data sovereignty cloud compliance protection through M2M entitlement tracing identifies the cross-region data access paths that autonomous agents create through background system update execution  an agent provisioned in an EU-sovereign cloud zone that can invoke a service account with access to US-region data creates a data transfer pathway that sovereignty compliance frameworks treat as a violation, regardless of whether the agent was designed to execute cross-region data access. 

Data Sovereignty Compliance and Regional Isolation Enforcement 

Data sovereignty cloud compliance enforcement for agentic AI workloads requires a governance architecture that operates at the identity layer rather than only at the network layer  network controls that enforce regional data isolation can be bypassed by non-human identities with legitimate cross-region permissions that were provisioned without sovereignty compliance review.  

AWS and SailPoint secure agentic AI sovereignty enforcement through IAM policy integration with SailPoint’s access certification workflow, ensuring that non-human identities provisioned for agentic workloads undergo sovereignty compliance review before activation confirming that the regional permission scope that each non-human identity carries does not create cross-region data access pathways that violate the sovereignty boundaries that enterprise data governance and regulatory compliance require.  

Enterprise access model defense for sovereignty compliance requires continuous certification rather than point-in-time review  autonomous agents that accumulate permissions through background system updates may develop cross-region access pathways after initial provisioning that a sovereignty-compliant provisioning review would have prevented. Continuous access certification that SailPoint’s platform applies to non-human identities, on the same review cadence as human identity certification, provides the ongoing sovereignty compliance assurance that point-in-time provisioning reviews cannot sustain.  

Autonomous machine identity tracking for sovereignty compliance generates the data flow attribution data that regulatory audits require  every cross-region data access event is attributed to a specific non-human identity, along with the provisioning history and access certification records that demonstrate governance oversight of the permission that enabled the access. 

Eliminating Architectural Blind Spots in Agentic Environments 

The deployment of a governance structure at the non-human identity level eliminates the three architecture holes consistently identified by managed service account conditions. The unmanaged service account condition has service accounts that have permissions in excess of operationally acceptable limits; entitlements for machine-to-machine (M2M) communications are not tracked and therefore create a communication channel that does not have to be evaluated for access rights; and the lifecycle of non-human identities is ungoverned and thus allows for the continued usage of purposefully assigned credentials even after the non-human workload no longer exists. 

How to manage non-human identities in cloud architecture for each blind spot requires distinct governance mechanisms that the AWS-SailPoint collaboration integrates into a unified platform automated discovery that surfaces unmanaged service accounts that exist outside the identity inventory, entitlement graph analysis that maps indirect M2M access paths, and lifecycle automation that triggers non-human identity deprovisioning when the agent workloads they support terminate.  

Autonomous machine identity tracking completeness determines governance effectiveness — a non-human identity governance layer that covers 90% of the non-human identity population provides zero governance protection for the 10% that adversaries discover through the same enumeration techniques that security teams should apply to their own environments before attackers do. 

Conclusion 

AWS and SailPoint secure agentic AI infrastructure, establishing the non-human identity governance layer that enterprise cloud environments require to close the identity security gap opened by autonomous agent proliferation, faster than traditional governance frameworks could respond. Autonomous machine identity tracking through integrated AWS and SailPoint telemetry provides the discovery completeness and attribution accuracy that M2M entitlement governance requires to be operationally effective rather than selectively applied.  

An enterprise access model defense through least-privilege M2M entitlement enforcement and continuous access certification prevents the permission accumulation and script loops that ungoverned non-human identity expansion creates. Data sovereignty cloud compliance enforcement at the identity layer closes the sovereignty bypass pathway that legitimate cross-region permissions create for autonomous agents, a gap that network controls alone cannot prevent. As how to manage non-human identities in cloud architecture becomes the foundational cloud security question that agentic AI deployment makes unavoidable, the governance architecture that AWS and SailPoint have built together provides the identity visibility, entitlement tracing, and lifecycle automation that enterprise security teams need to govern the non-human identity population that autonomous agents are creating faster than human governance processes can track.

Source: AWS Partner Network (APN) Blog