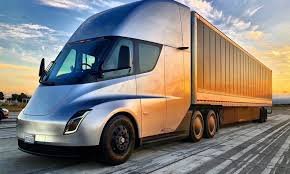
Las Vegas, Nev. More than 65% of commercial freight operators in long-haul logistics are holding off on fleet-on-fleet electrification because they are unsure if the grid can handle the extra demand. This uncertainty is a major obstacle to updating transport operations and keeps older diesel fleets running even with strict regulations in place. The impact of megawatt-class charging on US industrial power procurement outlines the fundamental shifts required to support the adoption of heavy-duty electric vehicles. The recent order for Tesla semis is a key moment for the industry, prompting utilities and logistics companies to reconsider their power infrastructure from the ground up.  

The Electrification Milestone for The Tesla Semi 

Rolling out a Class 8 electric vehicle fleet changes the financial picture for long-haul logistics. In the past, companies were reluctant to shift from diesel due to concerns about range and slow charging. WattEv’s recent order of the Tesla Semi shows that the industry is now ready to make this shift on a large scale. The order includes 370 trucks, with over 300 set to operate near the Port of Oakland.  

With megawatt charging, operators can cut downtime by a large margin. A Tesla Semi can recharge up to 60% of its battery in just 30 minutes. This fast charging helps logistics companies meet tight schedules and avoid the long waits associated with slower charging methods.  

The Infrastructure Bottleneck and the Grid 

To scale up this technology, local electrical grids need major upgrades. Industrial sites can’t run multiple heavy-duty chargers without investing in dedicated substations. Utilities also have to adjust to the sudden increases in demand as more fleets switch to Class 8 electric trucks.  

Installing MCS chargers at freight depots sets out a new standard for high-power commercial transport. When companies use multiple chargers simultaneously, the total power demand quickly reaches megawatt levels. Upgrading these sites requires close teamwork among transport operators and local utility companies. The Port of Oakland is now a real-world test site for meeting these high-power needs without straining the local grid.  

Rethinking Energy Procurement Strategies 

Now, logistics companies need to invest directly in energy generation and storage. Buying trucks is no longer separate from managing their power supply. WattEV uses a model that combines vehicle leasing with the construction of megawatt-scale charging infrastructure.  

This approach lowers capital risk for fleet operators. It moves the responsibility of building infrastructure from individual carriers to dedicated service providers. Using MCS chargers also means trucks spend more time driving and less time charging.  

But as zero-emission fleets grow quickly, the utility chain comes under pressure. Local power companies now have to plan a new transformer upgrades and more distribution lines. Industrial electricity buyers need to secure long-term contracts for stable prices and avoid peak-hour surcharges that could offset the savings from switching to electric vehicles.  

Long-Term Financial Consequences 

Modern freight transport depends on predictable energy costs. Moving from diesel to electric power lowers operating costs over a vehicle’s life. However, the initial cost of installing a high-power electric grid remains high.   

One megawatt charging cabinet can cost several hundred thousand dollars. This means businesses have to rethink their capital spending. The shift to electric trucks also means logistics companies need to act as energy managers, keeping a close eye on electricity use and charging schedules for batteries.   

Regulators are also changing to help with this transition. Alliances between public and private groups are accelerating the installation of high-power infrastructure at major freight hubs. California’s success offers a clear example for the rest of the country, showing how to grow sustainable freight operations without closing economic efficiencies.  

The Future Of Freight Corridors 

Switching to zero-emission freight is a lasting change in how industrial operations use electricity. In the future, networks will depend on connected heavy-duty vehicles with high-power delivery systems. Companies that update their energy strategies now will save money in the next decade. Soon, freight corridors will be entirely changed by clean energy and advanced charging systems. 

Source: Tesla Blog 
CUPERTINO, Calif. — Apple has introduced a major architectural change to its AI ecosystem with the rollout of the iOS 27 Extensions framework, a system that allows users and enterprises to integrate and switch between multiple artificial intelligence models directly within iOS.   

The implementation enables Apple devices to access AI services from multiple model providers and allows users to create custom AI workflows.   

The introduction of AI Model Selection capabilities marks one of the most important strategic shifts in Apple’s AI platform strategy.  

Why iOS 27 Extensions Matter  

The iOS 27 Extensions framework enables developers to create modular AI systems that run directly on the operating system core.   

Apple permits third-party artificial intelligence systems to operate as independent service components that work with all supported programs and processes.   

The system allows users and organizations to choose from a range of models that meet their privacy, performance, and operational needs.   

The change establishes new boundaries for future AI services, which will use mobile operating systems.  

AI Model Selection Expands User Control  

The emergence of AI Model Selection gives users and enterprises greater authority over which models handle specific tasks. Different AI systems exhibit significant differences in their security controls, latency performance, inference styles, and data retention methods.   

Apple has developed a system-level model selection framework to enable users to customize AI capabilities rather than rely on shared system features.   

The new approach marks a complete shift from the previous system of closed-assistant environments.  

Apple Intelligence Evolves Into a Platform Layer  

The Apple Intelligence initiative has evolved into an operational framework that handles multiple tasks rather than functioning as a single independent assistant system.   

Instead of designing a single dominant AI model, Apple developed an AI system that enables multiple other AIs to communicate and share information securely. 

With this approach, Apple retains complete control of its platform while allowing broader participation in the world’s artificial intelligence ecosystem. 

The development of Apple Intelligence shows consumer operating systems moving toward artificial intelligence systems that can work together.  

On-Device LLMs Gain Strategic Importance  

The new framework includes expanded support for On-Device LLM processing as its main component.   

Running large language models directly on-device improves privacy, reduces latency, and minimizes reliance on external cloud systems.   

This matter is particularly significant for enterprise organizations and regulated environments that need to protect sensitive data.   

On-Device LLM systems have emerged as the primary trend shaping mobile AI architecture.  

Private Cloud Compute Balances Security and Scale  

The company employs Private Cloud Compute systems that provide stronger privacy protection than standard cloud AI systems to handle workloads that exceed their local processing capabilities.   

The hybrid system enables iOS devices to use local processing and secure cloud-based inference when needed.   

Private Cloud Compute integration enables performance scalability while maintaining Apple’s privacy requirements.  

Siri 3.0 Becomes an AI Routing Layer  

The new AI framework’s most important advancement is evident in the development of Siri 3.0.  

Siri now operates as a voice assistant and, in its new role as a routing and orchestration interface, directs tasks to various AI models based on user needs and contextual information.   

As a result of this development, Siri serves as the primary artificial intelligence coordination system across the entire Apple system.   

The transition indicates broader developments shaping the evolution of virtual assistants.  

Model Swap Changes Enterprise AI Strategy  

The ability to perform a Model Swap directly within iOS environments has major implications for enterprise technology strategy.  

Organizations will use approved AI systems as their chosen systems, configuring them for device operation in accordance with their compliance requirements, internal governance policies, and data security standards.  

The system provides organizations with operational flexibility by reducing their reliance on a single vendor AI system while enabling them to operate their business functions.  

Enterprise mobile AI deployment will undergo substantial changes because of the introduction of Model Swap functionality.  

OpenAI Dependency Weakens on iOS  

The iOS 27 Extensions framework is of greater importance because it affects competition among various artificial intelligence ecosystems.   

The large artificial intelligence ecosystems of the past relied on a few dominant model providers for their entire functionality.   

Apple has developed a system that enables different AI providers to collaborate. This system enables all AI providers to compete on equal terms on the iOS platform.   

The system will establish an AI services market that supports multiple providers and increases competition among them.  

Enterprise Security Gains More Flexibility  

The long-term importance of how to swap default AI models in iOS 27 for enterprise security lies in aligning AI deployment with organizational governance requirements.  

Organizations operating in finance, healthcare, defense, and regulated industries need detailed control over their AI systems and data transmission.   

The dynamic selection and replacement of AI models enables organizations to enhance their security governance while gaining operational flexibility.  

AI Platforms Move Toward Interoperability  

The introduction of model-selection frameworks indicates that AI ecosystems will prioritize interoperability over maintaining vendor-specific restrictions.   

Users will increasingly demand the ability to switch AI providers just like they currently switch between applications and cloud services.   

This development has the potential to transform how companies compete in the AI platform market.  

Conclusion: Apple Reframes the Mobile AI Ecosystem  

The launch of iOS 27 Extensions by Apple establishes new guidelines that define distinct approaches to managing mobile artificial intelligence systems.   

Apple develops its AI platform through four main changes: AI Model Selection progress, On-Device LLM extension, Private Cloud Compute integration, and Siri 3.0 development as a model orchestration system.   

The increasing value of Model Swap functionality indicates that both businesses and individual users will require more authority to choose which artificial intelligence systems will function on their devices and in their work activities.  

As organizations explore how to swap default AI models in iOS 27 for enterprise security, the future of mobile AI may become significantly more open, customizable, and interoperable than earlier, closed assistant ecosystems allowed.

Source: UPDATE Apple Manufacturing Academy accelerates AI use in U.S. supply chains 

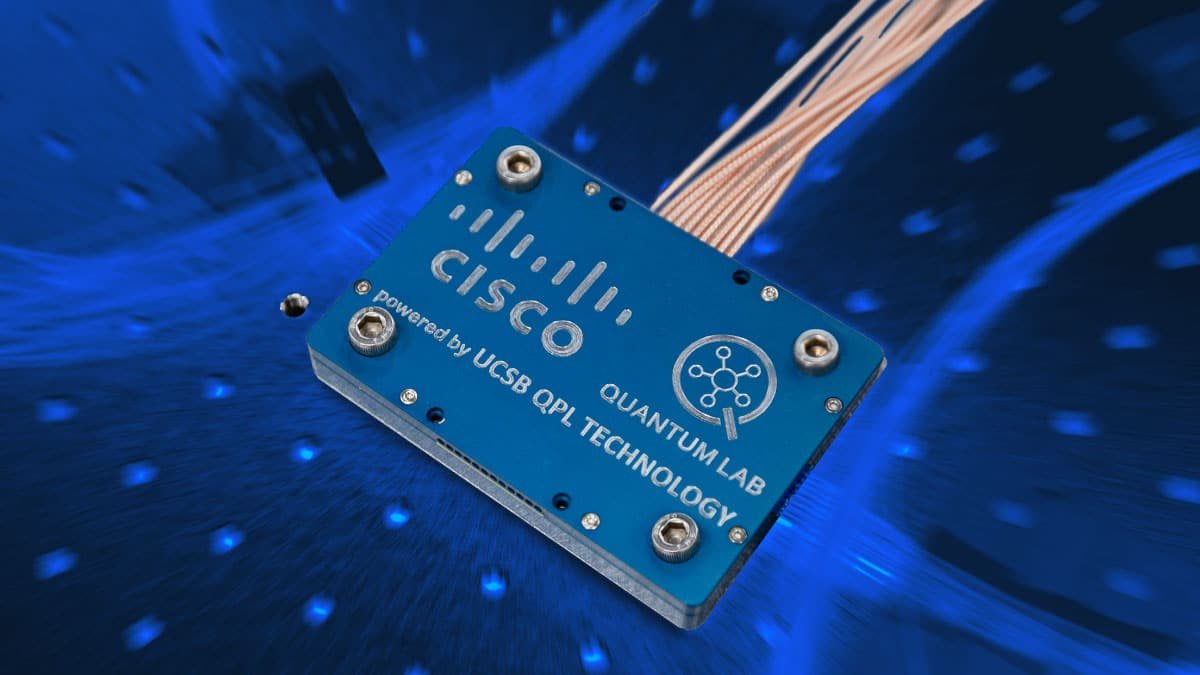
SAN JOSE, Calif. — The organization has developed a networking innovation that uses its Cisco Quantum Switch to enable quantum data transmission through existing telecommunications systems.   

This announcement represents a significant milestone within the evolution of Secure Communications; the initial use of a Room-Temperature Quantum system signifies that this will not be limited in terms of access to room-temperature-based operations only, but rather, it will completely eliminate the need for the complex and expensive Cryogenic environments that most existing Quantum Technologies require. 

The shift will accelerate enterprise adoption of quantum-secure networking technologies, leading to new encryption standards used across worldwide fiber networks.  

Why the Cisco Quantum Switch Matters  

The Cisco Quantum Switch represents an attempt to bridge classical networking systems with future quantum communication environments.   

Scientists needed to work in remote laboratory spaces because traditional quantum networking experiments required specialized equipment that could not connect to the real world. 

Cisco developed its system to work with existing telephone networks, enabling quantum communications to operate over standard internet transmission methods.   

The technology is gaining significant importance because it applies to both enterprise- and carrier-scale deployments.  

Room-Temperature Quantum Changes Deployment Economics  

An announcement cites Room-Temperature Quantum operation (RTQ) as being its most valuable component. 

To function properly, quantum systems require ultra-low-temperature environments to support their quantum states, resulting in high operational costs and complex installation challenges. 

Cisco improves access to quantum technology infrastructure by developing quantum switching that operates at standard temperatures.   

The technology has the potential to make quantum networking systems commercially viable.  

Qubit Routing Enables Dynamic Quantum Networking  

In addition to the sophisticated routing of qubits, dynamic quantum communication across various network types will also be possible with this advance in technology. Quantum communications employ qubit states to transmit data; as a result, they use alternative forms of information transmission compared to classical binary data transmission. 

A scalable quantum networking architecture requires efficient routing of quantum states to function properly.   

The development of Qubit Routing technology is the main factor that will determine how quantum internet infrastructure evolves in the future.  

Telecom Fiber Gains Extended Relevance  

Cisco’s strategic advantage lies in its ability to work with existing Telecom Fiber systems.   

The quantum switching system enables operation within existing fiber-based transmission networks, eliminating the need for a completely new communication system.   

The system’s compatibility with enterprise and carrier networks enables cost savings during deployment by simplifying integration.   

Telecom Fiber usage enables organizations to maintain their current infrastructure investments.  

Modal Conversion Supports Hybrid Networks  

The technology depends on Modal Conversion technology because it enables networks to transform and use multiple signal states.   

The technology needs this capability to enable its two communication systems to operate simultaneously on a common network infrastructure.   

Modal conversion helps maintain signal integrity while improving interoperability across hybrid communication architectures.   

The growing field of quantum networking will drive the development of Modal Conversion systems to achieve their full potential.  

Post-Quantum TLS Gains Strategic Importance  

The development of quantum-capable communication systems leads to increased awareness of Post-Quantum TLS protocols, which safeguard future internet traffic against quantum-fueled attacks. 

Quantum computing power will eventually render traditional encryption systems ineffective, according to current security predictions.   

The goal of post-quantum security systems is to maintain the security of encrypted communication as quantum computing advances.   

The development of quantum networking at Cisco directly supports their efforts to update encryption systems throughout the organization.  

NIST FIPS Compliance Remains Central  

The integration of quantum-secure communication technologies will also depend heavily on alignment with NIST FIPS standards and federal cybersecurity certification frameworks.   

Standardized validation processes for encryption and security compliance must be in place before government and enterprise organizations can begin using quantum networking systems.   

NIST-related standards will determine the commercial deployment of quantum infrastructure technologies as they continue to develop.   

The future governance of quantum networking will establish NIST FIPS standards as its primary governing framework.  

Encryption Becomes Infrastructure Agnostic  

The Cisco Quantum Switch supports the development of encryption systems that can operate independently of their chosen transmission media.   

Future encryption systems will use dynamic adaptability to operate across classical and quantum transmission systems, rather than relying on specific hardware requirements.   

The system provides enhanced resilience and improved compatibility for operating across different types of infrastructure systems.   

The outcome leads to a communication security framework that possesses greater capacity for adaptation.  

Existing Fiber Networks Gain Quantum Potential  

The broader significance of implementing room-temperature quantum switching in existing fiber networks lies in the ability to modernize current infrastructure without complete replacement.  

Future organizations will incorporate quantum-secure communication systems into their existing telecom infrastructure.   

The solution will enhance adoption rates by reducing implementation challenges while keeping business operations running smoothly.  

Quantum Networking Moves Toward Commercialization  

The transition to room-temperature quantum networking signifies that this area is now entering another stage of development: practical use. 

Enterprise interest will rise as operational costs decrease, and compatibility with current infrastructure improves.   

The investment rate across telecom, defense, finance, and cloud infrastructure sectors will experience acceleration from this development.  

Conclusion: Cisco Pushes Quantum Networking Toward Mainstream Infrastructure  

Cisco has developed the Cisco Quantum Switch, which creates the first real-world implementation of quantum-compatible networking technology.   

Cisco is transforming future encryption systems through its Room-Temperature Quantum operation capability, which includes advanced Qubit Routing and Modal Conversion, as well as Telecom Fiber infrastructure compatibility.   

The growing significance of Post-Quantum TLS and the NIST FIPS frameworks indicates that secure communication standards have entered a new era, requiring quantum resilience and infrastructure flexibility.  

As enterprises explore implementing room-temperature quantum switching in existing fiber networks, the future of encryption may increasingly depend on adaptable architectures that operate seamlessly across both classical and quantum communication layers.

Source: Talking Agentic Ops and the evolution of artificial intelligence, with Akshay Bhargava 

SANTA CLARA, Calif. — AMD has released new information about the Ryzen AI Max+ platform, highlighting its capabilities as a computing system that unites workstation-level artificial intelligence processing with ultra-thin laptop design.   

This announcement marks a drastic shift for both companies from their existing strategies for personal computing. As such, users can now build AI software applications on their mobile devices, rather than being limited to accessing cloud computing services for higher-end graphics workloads or neural inference.  

The development of AMD Ryzen AI Max+ will set new standards for lightweight workstation performance and artificial intelligence in laptop computers.  

Why Ryzen AI Max+ Matters  

The AMD Ryzen AI Max+ platform combines CPU, GPU, and AI acceleration into an energy-efficient system that operates effectively in lightweight devices.   

Ultra-thin laptops used to suffer from significant thermal and processing power limitations, preventing them from achieving the performance of full desktop workstations.   

AMD works to solve specific design challenges by adding high-speed memory technology and AI acceleration capabilities to its small-form-factor solutions.   

The AMD Ryzen AI Max+ platform supports all essential AI functions for Mobile work.  

Unified Memory Changes AI Workflow Efficiency  

The new platform features its most essential element through its expanded Unified Memory architecture.   

With Unified Memory, instead of having to keep a constant duplicate and incur transfer overhead between two different memory pools (CPU & GPU), one access location is ever-so-importantly accessible by many processors at once.  

The system enables better performance through its AI workloads, which process large datasets and perform multimodal inference.   

The expansion of Unified Memory provides important benefits to local AI model development and edge inference systems.  

Zen 5 Architecture Powers AI-Centric Computing  

The Zen 5 architecture delivers significant improvements in processing efficiency, workload management, and support for artificial intelligence functions across devices.   

The Zen 5 design enables systems to achieve optimal performance through parallel processing and instant task execution, which are essential for workflows that depend on artificial intelligence.   

The new capabilities of ultra-thin systems enable them to perform advanced local inference and development tasks that exceed those of earlier laptop models.   

The development of Zen 5 architecture demonstrates how AI-native computing design has become an essential design element.  

Radeon 800M Expands Integrated Graphics Performance  

The ultra-thin workstation category receives better multimedia and AI visualization capabilities through the integration of Radeon 800M graphics.   

Professionals needed to use dedicated graphics cards because integrated graphics lacked the power to deliver professional rendering and AI visual processing.   

The new Radeon architecture enables more demanding graphics operations yet achieves power efficiency.   

The development of creative projects and AI workflows now benefits from the availability of the Radeon 800M, which has established itself as a suitable tool for these tasks.  

NPU 2.0 Accelerates Local AI Processing  

The introduction of NPU 2.0 demonstrates AMD’s ongoing commitment to developing specialized neural processing units for use in consumer computers.   

Neural Processing Units are specialized hardware designed to perform artificial intelligence inference operations, including speech recognition, computer vision, and generative AI tasks.   

The enhanced NPU design enables greater use of AI functions, allowing them to operate directly on devices without relying on cloud services.   

The expanded capabilities of NPU 2.0 enable more portable devices to run local artificial intelligence operations, thereby increasing their adoption.  

ROCm 7.2 Targets Developer Ecosystems  

The integration of ROCm 7.2 is particularly important for developers building machine learning and artificial intelligence systems.   

ROCm provides AMD’s open software ecosystem for GPU computing, enabling AI developers to optimize their workloads across all AMD hardware platforms.   

ROCm 7.2 provides better support for AI frameworks and accelerated computing, helping AMD establish its presence in the local AI development market.   

The demand for adaptable AI software systems that operate outside of proprietary cloud platforms has increased, according to this trend.  

Ultra-Thin Workstations Enter a New Category  

Artificial intelligence tools that assist workers in their tasks redefine ultra-lightweight workstations.   

Previous designs for thin laptops focused on creating portable devices that could run on battery power for extended periods.   

Modern systems need to handle local AI processing, creative rendering, and development tasks, which were previously limited to more powerful equipment.   

The AMD Ryzen AI Max+ platform directly serves this new category of products, which has emerged in the market.  

Unified Memory Supports Local AI Development  

The combination of Unified Memory and GPU acceleration, along with NPU integration, delivers significant advantages for local AI development environments.   

Developers increasingly want the ability to run and test AI models directly on portable devices without depending entirely on cloud compute resources.   

This trend is driving demand for laptops that can efficiently process multimodal AI workloads through local computing Power.   

AMD has designed its architecture to meet this changing operational demand.  

AMD vs Apple Competition Intensifies  

The broader discussion surrounding AMD Ryzen AI Max+ performance vs. Apple M5 for local AI development highlights intensifying competition in AI-first laptop architectures.  

The two companies choose their main focus area, which involves developing memory systems that work together with neural acceleration and local inference processing capabilities.   

The competitive environment among companies drives faster technological advancements in portable AI workstations, benefiting the entire semiconductor sector.   

Research now emphasizes comprehensive AI workflow performance testing rather than measuring CPU performance through traditional benchmarks.  

AI Workstations Become Mainstream  

Dedicated AI acceleration unit integration into consumer laptops indicates that AI-powered workstations will soon be a standard in the professional computer market. 

Professionals provide evidence of demand for AI-capable systems to create, develop, conduct research, and use AI in enterprise computing. 

Portable computing devices now face new requirements because of this technological advancement.  

Conclusion: AMD Pushes AI Workstations Into the Ultra-Thin Era  

The introduction of AMD Ryzen AI Max+ marks a significant advancement for ultra-thin computing architecture, according to AMD.   

AMD uses its Unified Memory system, Zen 5 architecture, Radeon 800M, NPU 2.0, and ROCm 7.2 to create lightweight laptops that support advanced local AI development and workstation-level productivity.   

The growing rivalry between AMD Ryzen AI Max+ and Apple M5 for local AI development underscores the industry’s shift toward AI-based computing systems that support diverse workloads and perform edge processing.   

The growing demand for portable AI processing capabilities has turned ultra-thin workstations into essential technological platforms that enable advanced AI productivity for future generations.

Source: Your Trusted Partner for Advancing AI 

SEATTLE, Wash. — Amazon Web Services has introduced a major shift in its enterprise automation strategy with the rollout of Amazon Quick, a desktop integration framework that enables AI agents to work with legacy desktop software systems.   

The update positions AI systems not merely as chatbot assistants but as operational software actors who can use computer vision, workflow interpretation, and authenticated task execution to operate traditional enterprise applications.   

The launch will create a major impact on future Amazon Quick deployments while driving the development of Agentic Workspaces throughout enterprise IT environments.  

Why Amazon Quick Matters  

The introduction of Amazon Quick addresses one of the largest limitations facing enterprise AI adoption: legacy software compatibility.   

Enterprise organizations continue to rely on desktop applications that do not support modern application programming interfaces or cloud-based system integrations.   

Amazon Quick enables AI agents to interact with existing systems through visual and operational controls that mimic human user behavior in desktop environments.   

The system allows organizations to automate all processes and run their operations. Agentic  

Workspaces Transform Enterprise Automation  

The rise of Agentic Workspaces represents a major evolution in enterprise productivity systems.  

Agentic systems differ from traditional automation tools because they can process interface information to make context-based decisions and adapt their operational procedures to new data.  

The system enables AI to work across multiple applications simultaneously without interrupting its operational processes.   

Agentic Workspaces will cause a fundamental transformation in the management practices of enterprise software environments.  

AWS Bedrock Powers the AI Layer  

The architecture behind Amazon Quick Connects directly to AWS Bedrock, which serves as the basic AI model infrastructure for enterprise deployments.   

Through AWS Bedrock, organizations can combine large language models with multimodal AI systems into their business operations while preserving corporate security measures and governance protocols.   

Amazon extends AI capabilities to traditional business systems by integrating Bedrock functions into desktop environments.   

The integration expands the range of enterprise use cases that AI agents can support.  

Managed Agents Reduce Operational Complexity  

Organizations now use Managed Agents to implement their internal AI systems, which fundamentally transforms their deployment methods.   

Enterprises now have the option to use centralized AI agents that operate workflows independently, rather than developing their own automation systems from the ground up.   

The agents can perform routine business operations, extract information, and operate applications across different software systems.   

The demand for scalable enterprise AI orchestration has driven the expansion of Managed Agents.  

GPT-5.5 and Multimodal Interaction  

The integration framework supports Amazon Quick Connects with modern multimodal AI systems, including GPT-5.5-class architectures. The systems can handle multiple types of input, including text and visual interfaces, workflow logic, and operational data that contains contextual information.   

The AI agents use this tool to better understand desktop environments, enabling them to analyze them with greater precision and advanced operational capabilities.   

The development of GPT-5.5 multimodal processing systems functions as the core technology that enables software agents to interact with enterprise applications.  

Computer Vision Enables Legacy Software Control  

The primary technology powering the Amazon Quick solution is its advanced Computer Vision system. The design of many legacy enterprise applications requires AI agents to handle visual data from screen interfaces because these systems do not provide structured APIs.   

Computer vision technology enables agents to detect buttons, menus, forms, and the states of interface elements in real time. The system enables organizations to create automated processes in previously closed-off spaces that modern artificial intelligence systems could not access.  

IAM Authentication Strengthens Security Controls  

The architecture requires IAM Authentication because enterprise deployments require strong identity and access management.   

Organizations achieve better control over permissions and operational limits by implementing identity-aware access management into their AI workflows.   

The system helps reduce the risks posed by unauthorized automated operations. The importance of IAM Authentication grows as AI agents gain access to more system resources.  

Legacy Enterprise Software Gains Extended Lifespan  

The main effect of Amazon Quick is a major advantage for businesses, as they can now use artificial intelligence automation without updating their desktop software.   

Organizations can keep their current systems running for extended periods while implementing artificial intelligence technologies.   

The solution will help decrease migration expenses while maintaining established business processes.   

The outcome creates a slow-paced process that businesses can afford to use as their modernization strategy.  

Agentic Workspaces Shift SaaS Economics  

The emergence of Agentic Workspaces will disrupt the financial model that enterprise SaaS platforms currently use.   

SaaS vendors, through their historical development, have used integration and cloud-native accessibility as competitive advantages over rivals. The development of AI agents that can control traditional desktop systems through a visual interface will reduce the need for organizations to switch their entire operations to SaaS solutions.   

This creates a new competitive dynamic in enterprise software strategy.  The competitive environment now operates through different fundamental principles that organizations must follow.  

How Amazon Quick Enables Legacy Software Automation  

The broader significance of How Amazon Quick enables AI agents to operate legacy desktop software lies in its potential to bridge decades of fragmented enterprise infrastructure.  

AI agents use multimodal reasoning and interface interaction to operate in current software environments without needing expensive redevelopment projects.   

The solution has the potential to accelerate enterprise AI implementation across sectors that rely on outdated legacy systems, including finance, healthcare, manufacturing, and government operations.  

Conclusion: Enterprise SaaS Enters an Agentic Era  

The launch of Amazon Quick by Amazon Web Services marks a pivotal transformation in enterprise software systems, enabling AI technologies to interact with their operational environments.   

The development of Agentic Workspaces through its integration components, including AWS Bedrock, Managed Agents, Computer Vision, and IAM Authentication systems, establishes new operational frameworks that merge human-operated software with AI-driven tasks. Enterprise AI systems are currently developing their capabilities through multimodal systems, such as GPT-5.5, which enable organizations to build software agents that interact directly with their existing systems.   

The transition enables organizations to use AI-based automation in their operations, transforming their enterprise SaaS strategies by eliminating the need to replace all their existing systems.

Source: AWS News Blog 

ARMONK, N.Y. — IBM has released IBM zSecure Secret Manager, a breakthrough software product that aims to automate the Certificate Lifecycle within the IBM z/OS environment. The release marks an innovative departure from existing enterprise cryptography management practices, especially as companies gear up for the quantum age. Unlike existing certificate management solutions, which use a variety of different tools to manually issue, renew, and revoke certificates, the new IBM offering combines certificate management functionality with Quantum-Safe Cryptography capabilities built right into the mainframe. 

The Automation of Certificate Lifecycle Management 

Until recently, certificate management involved complex interactions across multiple tools and personnel, resulting in lengthy processes riddled with errors and other issues. Businesses running on IBM z/OS systems had a tough time keeping track of all their certificates and addressing related issues. 

However, with the advent of IBM zSecure Secret Manager, enterprises can forget about all that because the process will be automated and include such features as: 

  • Real-time certificate validity monitoring 
  • Automatic renewals upon expiry 
  • Immediate revocation when necessary 

Fulfilling the Post-Quantum Obligation 

With the rise of quantum computing, classical forms of encryption are getting compromised. Hence, governments and organizations need to embrace Quantum-Safe Cryptography to secure their data. In line with this post-quantum obligation, IBM has introduced IBM zSecure Secret Manager. It incorporates quantum-ready cryptography in Certificate Lifecycle Management. It also ensures compliance with standards like NIST Compliance, as it provides cryptographic support. 

Architecture Advantages: Integrated within z/OS 

IBM zSecure Secret Manager stands out for its integrated architecture, built into IBM z/OS rather than as an add-on solution. 

Here are some major advantages of its architecture: 

  • Integrated with IBM z/OS security mechanisms 
  • Instant policy application 
  • Compatibility with automated PKI systems 

It removes the dependency on any third-party middleware software. 

Long-Tail Innovation 

One of the key strengths of IBM zSecure Secret Manager is the ability to automate certificate lifecycle management in post-quantum z/OS. 

Effects on the PKI Ecosystem 

The introduction of the IBM zSecure Secret Manager is expected to disrupt the PKI ecosystem. 

For example, companies like DigiCert and Entrust, which previously offered certificate management services, could see demand drop due to automated PKI functionality. 

Effectiveness in Compliance and Cost Savings 

Another major selling point for IBM zSecure Secret Manager is its effectiveness in ensuring compliance and reducing costs. 

Some of the notable benefits of this technology include: 

  • Manual compliance minimization 
  • Rapid NIST Compliance alignment 
  • Minimal chances of security breaches 

Enterprises operating in the Federal Cloud environment can especially benefit from automation. 

Cost-Benefit Analysis for Businesses 

Automating the certificate of lifecycle offers significant financial savings for businesses. 

Some of the expected benefits include: 

  • Labor savings of up to 30% 
  • Minimal downtime attributed to expiring certificates 
  • Easier auditing processes 

Strategic Outlook 

The development of IBM zSecure Secret Manager reflects some major industry trends, such as: 

  • The shift towards quantum-proof security architecture 
  • The increasing prevalence of automation in infrastructure 
  • The need for compliance in cloud-based environments 

With the advent of quantum computers, tools that ensure security efficiently through core-level integration will play a crucial role. 

Conclusion 

IBM zSecure Secret Manager can serve as a landmark for future developments in enterprise security. With zSecure Secret Manager, IBM can help organizations adapt to changing cryptographic conditions by automating Certificate Lifecycle Management under IBM z/OS. This move signals much more than technological progress; it symbolizes a change in the approach to cryptographic security management altogether.

Source- Introducing IBM zSecure Secret Manager 

MOUNTAIN VIEW, Calif. — 

Now, Google has officially moved to disrupt the cloud computing industry by releasing its newly designed and built processor for cloud-based operations, called Google Axion. The new release is set to be a game-changer in cost, performance, and scalability assessments of SaaS providers. Unlike conventional x86 processors, the new chip has been designed to maximize performance when running today’s complex software systems. With claims of having up to 2x better price-performance ratios, the new technology could soon revolutionize cloud computing economics. 

Disrupting the x86 Dominance 

For many years, cloud computing systems have largely relied on CPUs from vendors such as Intel and AMD. Although these processors have provided computing power for most enterprises, they have become increasingly inadequate for efficient processing. 

With the release of Google Axion, we are likely to see an increase in the adoption of CPU processors based on Arm architectures, including: 

  • Greater efficiency 
  • Specific optimizations 
  • Reduced costs 

Real Gains In PerformanceReal Gains In Performance 

In essence, Google Axion can provide users with better Price-Performance than traditional Virtual Machines. With its focus on scalability, the technology performs exceptionally well for Java Optimization and microservice-oriented applications. 

Its benefits include: 

  • Improved speed for native cloud computing 
  • Decreased lag during times of high traffic 
  • Increased efficiency of resource utilization 

Google Axion now offers developers the ability to try out C4A Instances, which provide a highly efficient compute environment for their needs. 

What makes this product launch revolutionary is its ability to enable Achieving 2x better price-performance with Google Axion custom Arm CPUs. Such an ability affects how SaaS providers approach investments into cloud infrastructure, as they will need fewer resources than before.  

One more great thing about Google Axion is that it enables running workloads in Bare-Metal mode. In other words, this allows developers to avoid the overhead associated with virtualization, gaining such benefits as: 

  • Higher levels of performance consistency 
  • Ability to run any workload as they see fit 
  • Eliminating unnecessary overhead 

With Google’s full ecosystem, from TPU 8i to everything else, developers will receive a complete platform for any kind of application. 

Industry-wide Ripple Effects 

The emergence of Google Axion will likely bring profound changes within the technology industry as well. For instance, major SaaS players such as Salesforce and Adobe will have greater bargaining power to negotiate lower infrastructure costs. 

However, established semiconductor manufacturers are under intense pressure due to: 

  • Decreased market demand for x86 processors 
  • Increased competition in customized silicon solutions 
  • Innovation in performance per watt ratios 

This move represents an ongoing trend towards vertical integration, in which cloud service providers develop customized hardware to maximize performance and reduce costs. 

Strategic Advantages for SaaS Companies 

For SaaS providers, the potential impact of Google Axion cannot be overstated. 

These advantages include: 

  • Cost savings on infrastructure by optimizing the Price-Performance ratio 
  • Scalability to cater to expanding customer bases 
  • Improved performance for critical applications 

The use of ARM-based CPU technology enables SaaS organizations to plan long-term infrastructure and develop competitive pricing strategies. 

Procurement and Cost Optimization 

Among the most vital lessons learned from this development is the importance of CTOs and other decision-makers reassessing infrastructure strategies. 

Legacy x86 hardware has become a burden for many enterprises, particularly given Google Axion’s effectiveness. 

It is imperative to analyze: 

  • Compute the cost relative to the dollar 
  • Scalability of the infrastructure in question 
  • Ability to support cloud-native applications 

Custom silicon has turned out to be more than just an engineering choice; it is also an economical one. 

Future OutlookFuture Outlook 

Some of the trends that have been witnessed within the industry recently include: 

  • Increased adoption of Arm-based technologies 
  • Higher interest in affordable cloud computing options 
  • Advancement of artificial intelligence and large data workloads 

With more innovations emerging from major cloud providers, future developments will increasingly hinge on offering the optimum blend of cost and performance. 

Conclusion 

Through superior Price-Performance enabled by a customized Arm-based processor, Google has set a new benchmark for the underlying infrastructure of SaaS products. It is a game-changing development that sets a new standard for how computer resources should be engineered, deployed, and priced. SaaS providers need to prepare for a significant shift in how they operate to remain competitive.

Source: Unlock 2x better price-performance with Axion-based N4A VMs, now generally available 

AUSTIN, Texas — However, Tesla has now moved to the next level by launching a new generation of its AI supercomputing infrastructure, Tesla Cortex 2.0. Unlike its predecessor, this new system is more than a powerful supercomputer. It is a breakthrough in terms of training, optimizing, and deploying robots in the real world. Currently, the first stage of Tesla Cortex 2.0 has been launched, enabling the company to train its robots using AI models for Optimus Gen 3 with exceptional computational capacity. 

Transition to Production-Level Robot Training 

In previous decades, most humanoid robots have remained at the prototype stage due to limitations in computing power and inefficient pipeline training. 

Thanks to Tesla Cortex 2.0, however, the company will be able to move to a new phase of robot development by combining efficient compute power with vertical AI solutions. 

Benefits of Tesla Cortex 2.0 for Optimus Gen 3 

  • Faster training processes 
  • Simulation capability in real time 
  • Elimination of dependency on external infrastructure 

Powering Optimus Gen 3 

At the core of the transition lies Optimus Gen 3, Tesla’s latest humanoid robot. The machine is designed for real-world applications and features several breakthroughs in locomotion, manipulation, and cognition. 

Key features: 

  • 22 Degrees of Freedom Hand capable of fine motor skills 
  • Enhanced perception provided by the AI5 Chip 
  • Mass deployment following the principles of Humanoid Scale production 

Tesla Cortex 2.0 guarantees that all of the above capabilities will continually evolve through intensive training and real-world feedback. 

Compute at Massive Scale 

Massiveness is one of the most distinctive traits of Tesla Cortex 2.0. Tailored to handle extremely large AI workloads, the architecture is built to ensure a gradual transition to a capacity of 500 MW. In the initial phase, the technology already provides enough computing resources to train Tesla’s “General World Model,” which helps robots operate in complex environments. 

This is essential for ensuring: 

  • Autonomous behavior 
  • Adaptability to varying conditions 
  • Easy integration into production workflows 

The Long Tail Breakthrough 

The most crucial aspect of this innovation lies in its potential to ensure how Tesla’s Cortex 2.0 supercomputer drives Optimus Gen 3 production. It closes the gap between AI training and physical implementation, enabling Tesla to shift from isolated experiments to full-scale production runs. 

Tesla’s decision is already creating waves in the robotics sector. Competing companies such as Boston Dynamics and Figure AI face a significant weakness: a lack of an integrated computing architecture. Unlike Tesla, which has its own computing architecture, these companies would be forced to work with third-party entities, such as NVIDIA and Microsoft, for training. 

It means they will: 

  • Have higher training latency rates 
  • Experience higher operational costs 
  • Lack of control over data optimization and management 

Tesla has an advantage due to its tightly integrated system, where hardware and software go hand in hand. 

Compute-to-Action Latency Edge 

In robotics engineering, compute-to-action latency—the time it takes AI models to convert computations into physical actions—is one of the key performance indicators. 

Thanks to Tesla Cortex 2.0, the latency will be shortened because of: 

  • Integration with Tesla’s proprietary AI architecture 
  • Fast data-processing pipelines 
  • Real-world environmental feedback 

Compared to competing humanoid robotics systems that use separate compute devices, Tesla gains a significant advantage—a 3X edge in compute-to-action latency. 

Implications for Manufacturing 

The rollout of Tesla Cortex 2.0 suggests the company’s plans to mass-produce its humanoid robots. Plants like Giga Texas will become the backbone of Optimus Gen 3‘s manufacturing and delivery. 

The shift implies: 

  • Simplification and optimization of the manufacturing process 
  • Automation of robotics assembly lines 
  • Coordination with industrial production flows 

The transition from prototypes to mass production heralds a crucial turning point in the robotics industry. 

Strategic Implications 

Tesla’s release of the Tesla Cortex 2.0 represents several emerging industry trends in robotics and artificial intelligence: 

  • Growth in the demand for humanoid robots as labor substitutes 
  • Proliferation of advanced infrastructure for AI model training 
  • Verticalization of technology production and distribution networks 

Conclusion 

The launch of Tesla Cortex 2.0 marks a watershed moment in the development of humanoid robots. By deploying Optimus Gen 3 on a wide scale, Tesla is basically starting a new race altogether. It’s no longer about who comes up with more prototype designs; it’s about who has the capability to produce at scale. Tesla has placed itself perfectly for this new era of robotics with its unique combination of software and hardware. One thing is certain amid all the developments in this field: the firms that control both AI training and robotics will shape the future.

Source- Tesla Optimus Gen 3: Everything We Know (2026) 

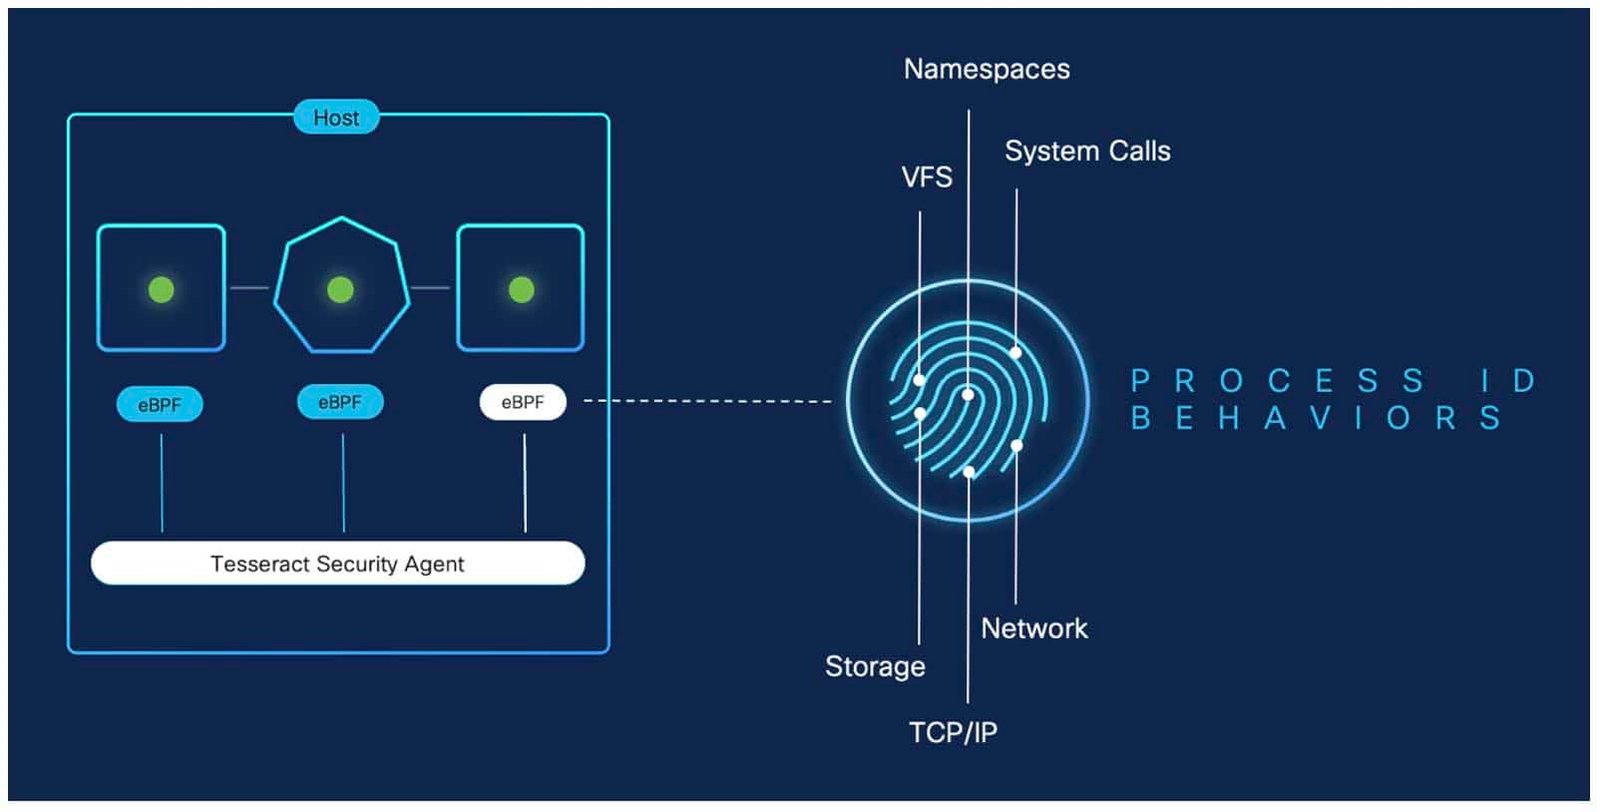
SAN JOSE, Calif. — One such revolutionary innovation from Cisco in the domain of Cloud security is Cisco Hypershield, which is based on eBPF security at the kernel level for AI applications. Not just a step-up from existing solutions, this is a new way of approaching security. Unlike typical security solutions that focus solely on detecting malicious traffic entering the network at the periphery, Cisco Hypershield operates within the AI application itself. By integrating eBPF Security into the kernel, it enables real-time protection without an external firewall, thereby eliminating the possibility of side-channel leakage. 

Going Beyond the Perimeter 

Traditional enterprise security relied on firewalls and centrally deployed security monitoring systems for networks and applications. However, the evolution towards cloud environments makes such an approach less viable. Attack surfaces have grown significantly, and threats are active within the workloads themselves. 

The inclusion of Cisco Hypershield alters this scenario by deploying eBPF Security to protect workloads at their point of execution. 

Specifically, the key benefits include: 

  • Immediate Policy Enforcement: Security enforcement happens directly within the workloads 
  • Shrunk Attack Surface: No need for additional firewall layers 
  • Improved Visibility: Deeper application-level telemetry 

Overall, such a deployment strategy adheres to the principles of Zero Trust, which assume no implicit trust in entities based on their location. 

Kernel-Level Security Intelligence: The Power of eBPF 

This capability enables Cisco Hypershield to monitor network activity, system calls, and application execution in real time. 

Some of the benefits are: 

  • Low Latency Filtering: Security analysis done without any context switching overhead 
  • High Flexibility: Ability to update security rules in real time 
  • Scalability: Can be used in distributed cloud infrastructures 

As seen, Cisco Hypershield creates a Distributed Fabric of security policy enforcement via kernel intelligence. 

Microsegmentation and Zero Trust Progression 

Among the many benefits offered by Cisco Hypershield, perhaps one of the best is Microsegmentation. Rather than securing whole network environments, this solution allows for securing workloads or even specific processes. 

This can be used for: 

  • Protecting sensitive workloads 
  • Stopping lateral movements inside the system 
  • Controlling policy execution 

When combined with a Zero Trust security architecture, eBPF Security ensures that all interactions are controlled, monitored, and verified. This makes it much harder for breaches to occur from within the organization. 

Closing the Door on Side-Channel Attacks 

Side-channel attacks exploit indirect data leakage, such as timing, memory access, or system behavior. This type of threat poses challenges for conventional detection methods. 

Using Cisco Hypershield to secure systems and applications means taking advantage of the following possibilities: 

  • Monitoring system-level side channel signals 
  • Recognizing abnormal activity immediately 
  • Stopping side channel attacks automatically 

Such a solution is especially necessary to secure AI workloads, as training models and data may be targeted through side channels. 

Impact on Industry Ecosystem 

Cisco Hypershield is likely to trigger further disruption across the broader cybersecurity landscape, where firms like Check Point, which rely on the conventional firewall approach, may become less relevant as cloud-native approaches emerge. 

On the other hand, cloud vendors such as Amazon Web Services and Google Cloud may have no other choice but to: 

  • Facilitate greater integration with the kernel. 
  • Enable third-party eBPF Security capabilities. 
  • Increase the transparency of workload protection. 

This change represents a shift from perimeter defense to embedded, intrinsic security within the infrastructure. 

Operational Efficiencies and Cost Savings 

In addition to improved security features, Cisco Hypershield offers operational efficiencies that reduce the total cost of ownership. 

Main efficiencies provided by Cisco Hypershield include: 

  • Minimal involvement in manual policy rule creation 
  • Increased speed in deploying security policies 
  • Ease of complying with regulatory frameworks 

The use of telemetry enables timely decisions based on performance metrics and threat data collected. 

Moreover, Workload Protection eliminates the need to implement security controls at an additional layer. 

Future Strategic Outlook for Enterprises 

As enterprises expand and develop their capabilities through AI and cloud-based services, the need for flexible, real-time security solutions will become inevitable. Hypershield by Cisco represents a foundation for developing next-generation infrastructure. The synergies between Distributed Fabric, Telemetry, and Workload Protection result in a coherent system with security embedded in its architecture rather than bolted on. 

In the context of the current industry trends, we may highlight the following ones as most relevant to the new solution: 

  • Growing popularity of cloud-native infrastructures; 
  • Complexity of AI workload; 
  • Need for automation of cybersecurity processes. 

Early adopters of the new solution may expect an advantage in terms of security and efficiency. 

Conclusion 

Introducing eBPF Security to Cisco Hypershield can be considered the key step towards a change in the cybersecurity paradigm. The shift in focus to kernel-level security and protection against side-channel attacks has enabled overcoming all constraints associated with traditional perimeters. In addition to higher-level protection, Cisco Hypershield provides organizations with smarter and more efficient security. Now enterprises can feel confident about their workloads because of the protection’s internal nature. Zero Trust architecture and a distributed environment represent the future of infrastructure, but first, one must ensure security and scalability.

Source-Cisco Hypershield: Reimagining security at AI-scale 

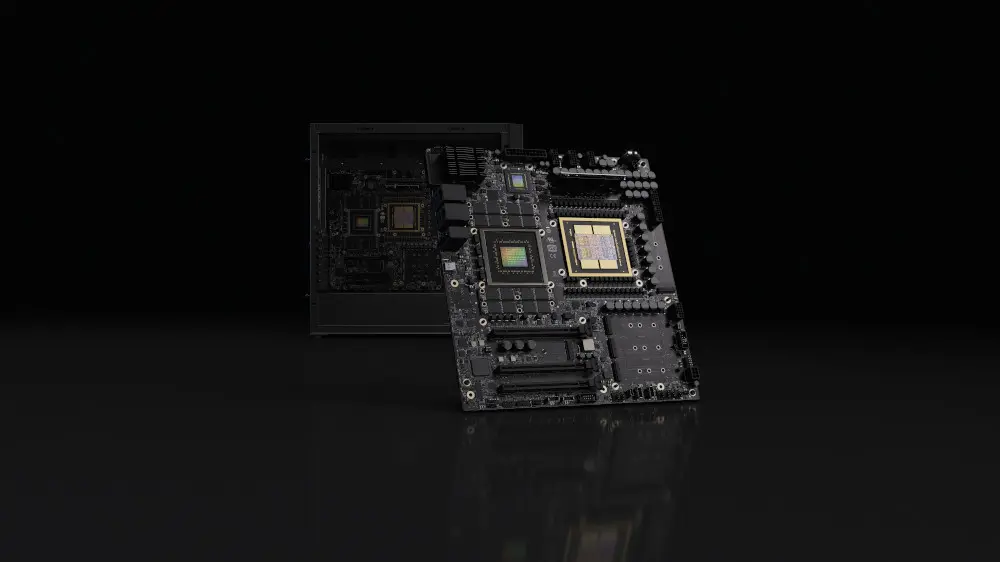
SANTA CLARA, Calif. — NVIDIA’s new product is not simply another hardware upgrade; it represents a revolution in the development and training of artificial intelligence models and ownership. Launching the NVIDIA Blackwell Ultra-powered DGX Station marks a major milestone, making possible a desktop machine that provides unparalleled compute density and brings the same level of hyperscale AI training capabilities to businesses and labs. DGX Station, based on the GB300 Superchip architecture, is the key to this revolution. The impressive amount of memory (up to 748GB), made possible by HBM3e technology, in addition to very fast NVLink-C2C interconnectivity, allows achieving outstanding AI performance of up to 20 Petaflops. It effectively breaks the dependence on distributed cloud clusters for training purposes. 

The End of Cloud Dependence 

AI research has always been dependent on cloud services from companies such as Microsoft Azure. For model training, there was a need for powerful GPU clusters, expensive bandwidth, and high operating costs. The arrival of NVIDIA Blackwell Ultra has disrupted this scenario. 

There are three key benefits associated with this new paradigm: 

  1. Decrease in Latency: Training and inference will occur in-house with no latency. 
  1. Cost Management: There will be no recurring cloud egress or compute charges 
  1. Data Security: Confidential data can stay within corporate premises 

This is especially important for start-ups and research facilities that wish to maintain proprietary information. Instead of using third-party services, these facilities can now utilize DGX Stations as their local AI supercomputers. 

Architectural Leap: Its Unique Features 

As far as the technical leap, this NVIDIA product has one more crucial feature – it is designed for system coherence, combining the HBM3e memory’s high bandwidth and low latency with an NVLink-C2C connection that eliminates the need to synchronize different compute parts. 

Some highlights include: 

  • Memory pool: unified and 748GB large 
  • Interconnects: scalable and NVLink-C2C powered 
  • Software stack: deeply integrated and Ubuntu-based 

This architecture provides all the necessary prerequisites for scaling 1-trillion-parameter models on NVIDIA Blackwell Ultra desktop supercomputers, a task previously considered a hyperscale data center task. 

Impact on the Hardware Ecosystem 

The introduction of the NVIDIA Blackwell Ultra immediately puts pressure on hardware providers like Supermicro, as they have traditionally offered enterprise-class AI systems. The first-party solution from NVIDIA, in turn, shrinks the time to innovation in cooling, density, and performance. 

Possible outcomes are: 

  • Faster introduction of liquid-cooled enterprise towers 
  • More competition regarding high-density packaging 
  • Focus on vertically integrated AI hardware solutions. 

The game is no longer about putting together various hardware components – it is about creating ready-for-use AI computing systems. 

Financial Implication: Transition to CapExFinancial Implication: Transition to CapEx 

Another important implication is the shift towards financial optimization. The AI stack is moving from being an operational expenditure in the cloud to a capital expenditure system based on ownership. 

What will change for business? 

  • High Initial Costs: Systems over $100,000 become a long-term investment 
  • Asset Depreciation: Allow hardware accounting in installments 
  • Fixed Cost: Removes unpredictable costs from cloud bills 

The capital expenditure model is suitable for high-growth AI companies that seek stable finances and data privacy. Thus, the DGX Station is not only a product but a key asset in the AI development pipeline. 

Competition for Cloud Service Providers 

The emergence of such technology puts cloud service providers under stress. The “inference moat,” which refers to their capacity to bind clients to proprietary hardware, is becoming weaker. If enterprises can achieve the same level of efficiency in-house using NVIDIA Blackwell Ultra, their solutions lose their competitive advantage. 

Therefore, companies like Amazon Web Services and Google must now consider: 

  • Decreasing GPU computing prices 
  • Hybrid cloud deployment options 
  • Enhancing security guarantees 

Benefits for Developers and Researchers 

For developers, the DGX Station opens up the following opportunities: 

  • Increased Iteration Cycle Speed: Instant access to computing capabilities 
  • Model Prototyping: The ability to experiment with larger architectures 
  • Confidentiality Guarantee: No need to expose proprietary models externally 

With such a solution integrated with an Ubuntu AI environment, developers have access to premium AI training solutions without the need for complex infrastructure management. 

Strategic Vision 

In light of the new NVIDIA Blackwell Ultra solution, the approach to building AI infrastructures undergoes fundamental changes. Scaling outward, into large cloud networks, is no longer required; one can build their own systems instead. 

This trend is part of a wider pattern: 

  • Growing awareness of privacy issues 
  • Increasing prices for cloud computing services 
  • Real-time AI requirements 

It is within this context that the DGX Station is placed. 

Conclusion 

The introduction of NVIDIA Blackwell Ultra via the DGX Station is no ordinary product; it is an AI infrastructure gamechanger. This technology is breaking free from reliance on cloud providers by enabling on-site training of trillion-parameter models. Enterprises, start-ups, and academic research institutes now have a fundamental choice to make: do you continue renting your computing power or own it? The potential for performance up to 20 PetaFLOPS, and technological developments such as HBM3e and NVLink-C2C, could change the game in favor of owning AI. This shift is not only about building great models; it is about who owns the infrastructure behind them.

Source– NVIDIA DGX Station