Redmond, Wash. A massive 80% of corporate data breaches now originate from compromised credentials rather than traditional software vulnerabilities. As hostile strategies shift toward sophisticated social engineering and automated session hijacking, static defense measures are proving insufficient for modern enterprise protection. To solve this, organizations are moving beyond a reactive posture management and adopting identity security systems powered by autonomous AI agents. This shift creates a dynamic defensive layer in which every access request is analyzed in real time. The Microsoft Entra AI agent identity security impact 2026 signals a fundamental move away from human-led administration toward a machine-speed response model that can counter threats before they move laterally across a network.  

The Evolution of the Identity Infrastructure 

Older security models used a castle-and-moat approach, trusting anything within the network. With remote work and cloud services, this boundary no longer exists, so identity has become the main control point. To address this, Microsoft is introducing an intelligent access fabric in the Microsoft Entra ecosystem. This fabric links different identities, from employees to machine accounts, into one connected and visible system.  

With AI agents in place, behavior is monitored continuously, not just at login. While a human administrator may miss small changes in a user’s login, location, or device, an autonomous agent can spot these differences in milliseconds. These agents in Microsoft Entra enforce complex policies that would be hard to manage manually. By analyzing trillions of signals worldwide, the system can quickly spot and respond to patterns of cyber attack mitigation. This automation is important, especially since non-human identities now outnumber human individuals by a factor of 10.  

Redefining Zero Trust For The Autonomous Era 

Zero-trust architecture is based on the idea of “Never trust, consistently verify.” In the past, verification occurred only at certain times, such as during a multi-factor authentication challenge. Now, this is not enough. The new approach requires ongoing access checks during system monitoring sessions, even after the password is entered. Identity security must be a continuous process that adjusts to the user’s risk level and the data they access.  

Advanced conditional access policies updated by machine learning make this possible. If a user’s risk score goes up, for example, because malware is found on their device, the system can immediately block access or ask for stronger authentication. This detailed control is key to modern zero trust. It means that even if someone steals a credential, they cannot access important assets without triggering an automated response.  

Adding AI agents to this process enables a new kind of “intent analysis.” The system can tell the difference between a real employee doing their job and an attacker trying to steal data by analyzing signals across the company, such as email use and file access. These agents offer strong protection against cyberattacks and help keep sensitive information safe.  

The Fiscal And Operational Impact Of Self-Governing Defense 

Apart from the technical security benefits, there is a clear financial incentive for adopting autonomous identity management. The Microsoft Entra AI Agent Identity Security Impact 2026 includes a significant reduction in the operational burden of managing a global workforce. Large organizations currently spend millions of dollars on help desk support for password resets and access requests. By automating these routine tasks, the IT department can focus on major initiatives such as digital transformation and cloud optimization.  

The cost of a data breach is rising, now averaging over $4.4 million worldwide. By stopping credential-based attacks, organizations can avoid huge financial and reputational losses. Using an intelligent access fabric also keeps security from slowing down work. Users only need extra verification when there is a real risk, which makes their experience more seamless and boosts employee satisfaction.  

Small business owners benefit, too, since they can get the same high-level protection through flexible cloud subscriptions. This helps smaller companies defend against the same advanced threats that target large corporations. Making identity security widely available is key to building a strong global economy.  

Managing the Future of Digital Identity 

By the end of the decade, digital identity will continue to evolve. We are heading toward decentralized identity, where users control their own data and decide how it is shared. Still, strong verification and ongoing monitoring will be needed. As computer-based interactions increase, AI agents will play an even bigger role.  

Organizations that thrive in this new environment will be those that use automation and treat identity as a key asset, not just a background tool. By using strong conditional access and automated monitoring, businesses can build trust and grow with confidence. Moving to fast automated defense is now essential for surviving in a world full of automated threats.

Source: Four priorities for AI-powered identity and network access security in 2026 
Santa Clara, Calif. In localized data processing, even a few milliseconds can mean the difference between a quick response and a major system delay. Until recently, many believed high-quality intelligence required a connection to central data centers. However, new AI benchmarks show a clear move toward edge computing. Now, hardware that used to handle only simple office tasks can run large 100-billion-parameter language models right on-site. This isn’t simply a technical upgrade. It is a major change in how businesses operate. As companies focus on keeping their data secure and reducing delays, having powerful AI in a small workstation is quickly becoming essential to remain ahead. In 2026.  

The Architectural Foundation of Intel Xeon 6 

MLPerf v6.0 is the first industry-standard test for the latest silicon designed for today’s hybrid AI needs. The new Intel Xeon six processors move away from the old one-size-fits-all model. With specialized performance cores and better memory bandwidth, these CPUs can efficiently run complex AI tasks, something that used to require large server racks.   

Standardizing on the Intel Xeon six performance in MLPerf Inference 2026 data uncovers a critical insight: the CPU is no longer a passive host. In these benchmarks, the processor orchestrates multi-GPU scaling and PCIe peer-to-peer data transfers, making sure data flows through the system without the choke points that traditionally cripple edge systems. This host-side intelligence enables a workstation to handle a high volume of concurrent requests while maintaining the stability required for 24/7 industrial operations.  

Cooperation Between CPU and Arc Pro GPUs 

The CPU handles the main logic, but the latest Arc Pro GPUs do the demanding work of matrix multiplication. The v6.0 results show that using four GPUs with a total of 128 GB of VRAM is key for 2026. This much memory lets a diverse set of expert (MoE) models run locally, so there’s no need to send data to the cloud.  

The new Battlemage Arc Pro GPUs are up to 1.8 times faster than the last generation of workstation hardware. For engineers in labs or doctors working with high-resolution images, this means they get results almost instantly. The hardware halves the wait time for insights, making users much more productive.  

Achieving Low Latency Inference In The Field. 

Real-world performance matters more than test results, especially in changing environments and power-limited systems. MLPerf v6.0 now tests server and offline scenarios to better reflect real conditions. Getting low-latency inference in these situations takes more than just fast hardware. It needs software that can quickly adjust weight loading and decoding as needed.  

Intel uses an open containerized software stack that works well with Linux. This shows how better software can get more out of the same hardware. For example, the same cards performed 18% better after software updates compared to the v5.1 cycle. This pliability helps small businesses use their hardware longer and delay costly upgrades while still taking advantage of new model improvements.  

The Function Of Advanced Silicon Manufacturing 

The improvements seen in 2026 also come from advances in silicon manufacturing. Using denser process nodes means more AI-accelerated instructions, such as AMX, can be built right into the chip. These hardware features help convert to lower-precision formats like FP8 and/or INT8 without loss of accuracy.   

By building these features into the chips, manufacturers have made high-end AI much more accessible. What used to require $100,000 servers five years ago can now run on a workstation that fits under a desk. This shift lets local governments and research groups use advanced models without paying ongoing subscription fees or facing privacy issues.  

A New Economic Reality for Industrial AI 

The economic effect of these benchmarks is just as important as the technical gains. With Intel Xeon 6‘s performance in MLPerf Inference 2026, companies can move away from expensive cloud services and invest in their own local systems. The cost of an AI workstation is often recovered in less than 18 months, especially given rising API and data transfer fees.  

Adding features like ECC memory and remote firmware updates to workstations makes them not only fast but also reliable. In factories where robots rely on vision models to spot defects on fast assembly lines, reliability is critical. These machines are built to withstand the harsh conditions of industrial environments, offering dependable performance that consumer-grade hardware can’t match.  

Managing the Post-Cloud Transition 

The computing industry is moving toward a future where local intelligence is everywhere, much like electricity. Soon, data centers will serve mainly as backups, while most work happens right where the data is created. Companies that adopt this new approach to local high-performance computing will be less affected by the changes in the global cloud market. The latest benchmarks show that hardware is no longer the main barrier. The real challenge is how quickly firms can update their procedures to use this new local power.

Source: Intel Newsroom 

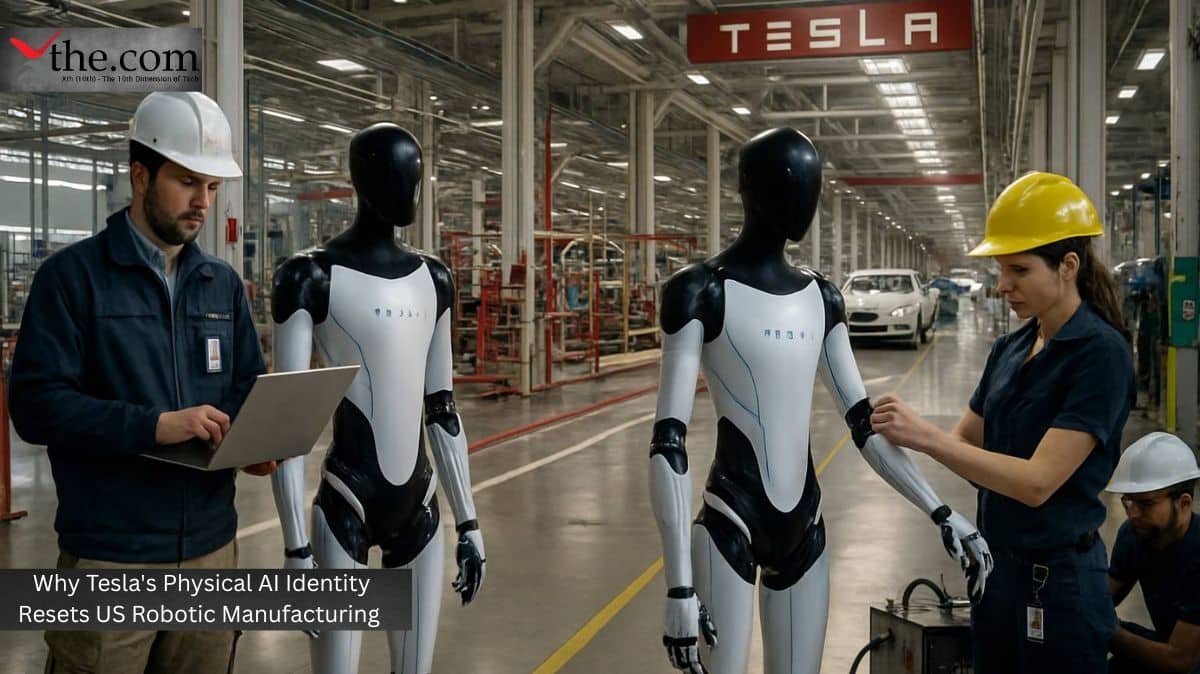
Austin, Texas. On average, an American car assembly line incurs about $22,000 in losses per minute of unforeseen downtime. When a line stops because of tired workers or equipment problems, profits take a big hit. To address this, the industry is turning to physical AI as the main intelligence on the factory floor. By moving past fixed automation and into robotic labor, manufacturers hope to separate production from human physical limits. Tesla is leading this change. The company’s move into robotics represents a larger shift, in which intelligence now interacts directly with the physical world rather than remaining behind a screen.  

The Convergence of Intelligence and Hardware 

Conventional industrial robots cannot see. They follow strict preset paths and stop working if a part is even a little out of place. Physical AI changes this by permitting machines to sense, think, and act in changing environments. This is not simply a small improvement to factory automation. It is a complete overhaul of how manufacturing works.  

Tesla Optimus is the main example of this new intelligence. It is a humanoid robot made to work in spaces designed for people. Unlike the specialized robotic arms in older factories, Tesla Optimus can perform many different tasks, such as moving battery cells or sorting parts. By using these robots in its own Giga factories, Tesla creates a feedback loop that helps the robots learn from real-world situations.  

This training depends on neural networks that handle large amounts of image data. These networks are the same ones used in Tesla’s vehicles, but now they control the robot’s joints, motors, and sensors. If a robot fails to grab something, that mistake is recorded, studied, and fixed on all robots. This shared learning means a solution from Texas can be used right away in Nevada.  

Redefining the Assembly Line: The Unboxed Process 

The factory’s layout needs to change as its technology evolves. Tesla’s unboxed process differs from the traditional assembly line pioneered by Henry Ford. Instead of moving the car down a single long line, it is built in separate sections or boxes simultaneously.   

The Unboxed Process requires robots that can move freely and work together in tight spaces. Older robots do not have the same level of awareness required for this kind of teamwork. But with vision-based intelligence, these robots can work on different parts of the car simultaneously, such as the interior, underbody, and drive unit, before everything is put together. This approach reduces the factory by 40% and cuts costs for new production lines.  

Scaling through real-world fleet data 

In robotics, the main advantage is now data, not just hardware. Tesla uses huge amounts of free data from its vehicles to improve its models of the world. Every mile driven gives information about how things move, how light works, and how physics affects motion. This data helps a robot grow. Musk says that a robot knows that a cardboard box is light and a brake rotor is heavy before it even picks them up.  

The same intelligence is used to develop the Robotaxi. A Robotaxi is a robot that carries people, while a humanoid robot carries tools. Both use the same computer vision systems to move through the world. By sharing these systems, Tesla can spread the cost of AI research across several products, something smaller robotics companies cannot do.  

The Fiscal Reality: Impact On Labor Costs 

The economic effects on the domestic industrial sector are considerable. Tesla’s physical AI impact on US manufacturing labor costs will likely define the next decade of American competitiveness. By switching to a model in which robotic labor handles the full set of dirty and dangerous tasks, manufacturers can reduce the rising costs of human wages and overtime.   

Take a top supplier with high turnover in its stamping department. By swapping five human jobs for two robots, the company keeps production steady and avoids the cost of constantly training new workers. While buying a robot costs a lot upfront, over time, it is expected to cost less than paying a worker in a high-wage country like the US.   

Physical AI also enables lights-off manufacturing. Factories can run at full speed all night with little need for heating, lighting, or ventilation, further lowering costs. This kind of efficiency is the only way for countries with high wages to compete with cheaper manufacturing centers around the world.  

The Future of General Purpose Robotics 

We are entering a time when the line between a car company and a technology company is fading. The aim is not just to make better machines, but to create machines that can build other machines. This needs a level of independence beyond simple tasks like picking and placing parts.  

Tesla Optimus and similar robots will succeed if they can handle rare, unpredictable events in busy factories. As these machines get better at handling surprises, people will only need to supervise rather than step in to fix problems.  

Adding vision-based neural networks to factories is the last key step. This brings a level of flexibility that was not possible before. Now, a factory can switch to making a new product in just days by updating the robot’s software, rather than taking months.  

American manufacturing is facing a big decision. Companies that stick with old, specialized automation will struggle to compete. Those that adopt physical AI and new robotic labor will be able to produce more at lower costs in ways that formerly seemed impossible. The change has already begun, and now it is a race to see who can keep up.

Source: Tesla Blog 

Cupertino, Calif. Exporting a 12-minute 8K view can bring a production workflow to a halt when AI rendering tools compete for memory. Editors are familiar with this frustrating problem. Motion graphics freeze, audio transcription slows, and local language models consume resources that creative software needs to function.   

This bottleneck shows why the next generation of Apple silicon is more important for more than just hardware upgrades. The M5 Pro in the MacBook Pro marks a significant shift in how AI-powered creative work is handled, processed, and shared in the professional world.  

The focus is no longer only on fast CPUs. New features such as dedicated neural accelerators, larger unified memory, and more efficient on-device LLM processing could change how creators, studios, and freelancers use AI in their work. The current debate about Apple M5 neural accelerator vs M4 AI performance benchmarks shows that local AI is becoming a real advantage.  

Apple Silicon Is Pushing AI Workloads Back To The Edge 

Over the past two years, the AI industry has relied heavily on the cloud. Video generation, image creation, and language models all depended on remote servers, but this approach had its downsides.  

Cloud-based creative AI tools can cause delays, add subscription costs, and raise security issues. For example, a documentary editor with unreleased footage may not want to upload sensitive material to outside servers. Music producers with unreleased tracks face the same risks.  

This is where Apple Silicon makes a difference.  

Apple combines CPU, GPU, and neural accelerator functions into a single integrated system, reducing reliance on the cloud. These efficiency gains matter most in AI-powered creative apps, where many tasks run concurrently.  

Now, editors using AI video editing tools for tasks such as scene segmentation, transcription, color matching, and background cleanup can handle much of the work on their own machines rather than relying on external computing platforms.  

This change also affects the finances of the wider creative industry.  

Why the M5 Pro Matters Beyond Raw Speed 

The M5 Pro is far more than a faster chip. It shows that Apple is placing greater emphasis on running AI tasks locally as its main goal.  

Most laptops split memory between graphics and computing tasks, but Apple’s unified memory model removes much of this separation. As a result, large AI models can use shared memory more productively without moving data back and forth between different parts.  

This efficiency matters enormously for on-device LLM deployment.  

For example, a filmmaker using a local AI assistant for script analysis while rendering high-definition footage simultaneously puts significant pressure on memory. On systems with split memory, this often leads to overheating or slowdowns.  

The MacBook Pro with the M5 Pro seems designed for these mixed AI and creative tasks.  

The debate about Apple M5 Pro neural accelerator versus M4 AI performance shows that professionals now judge laptops more by their AI abilities than by traditional productivity measures.  

Neural Accelerator Design Changes Creative Economics 

The dedicated neural accelerator in today’s Apple silicon chips changes the cost and capability of creative work in important ways.  

Cloud AI services change based on how much computing you use, which can get expensive for creators who run many AI tasks every day. Small studios that process thousands of AI-generated frames or perform extensive local transcription can see these costs add up quickly.  

Running AI tasks locally helps reduce this need on cloud services.  

Take a small post-production studio working on 30 projects a month. If each editor pays $400 a month for cloud-based rendering and AI tools, a five-person team could spend almost twenty-four thousand dollars a year just on these subscriptions.  

A powerful MacBook Pro capable of running advanced on-device LLM tasks locally can significantly reduce these costs.  

This is why more creative professionals are paying attention to the Apple M5 Pro neural accelerator rather than the M4 AI performance. They are looking beyond hardware specs and thinking about long-term efficiency and costs.  

AI Video Editing is Becoming Hardware Dependent 

For years, video editing software has advanced faster than most computer hardware could keep up. AI is now making that gap even wider.  

Today’s AI video editing tools can perform facial tracking, object masking, automatic subtitle generation, noise removal, scene extension, and smart timeline assembly simultaneously. Each of these features places greater demands on memory and processing power.   

This is where unified memory becomes strategically important.  

Unlike systems that require moving data between separate memory areas, Apple silicon lets creative apps and AI tools use shared resources with less delay. This makes editing sessions easier and more responsive.  

Picture a sports editor creating video highlights in multiple languages for live publishing. Even short delays can hurt audience engagement and ad revenue. Faster local AI processing helps speed up production.  

The M5 Pro is built for exactly these kinds of demanding tasks.  

On-Device LLM Adoption Is Accelerating Inside Creative Workflows 

The growth of on-device LLM systems could be one of the biggest changes to time-to-compute in the next few years.  

Writers now use local language models to improve drafts. Designers create layout ideas offline. Editors summarize transcripts without the cloud. Musicians try out local generative audio tools during production.  

Part of this shift concerns privacy. The other part is about getting uniform performance.  

AI workflows that depend on the cloud can become unreliable if internet speeds change, or API costs increase. Running AI tasks locally improves process stability.  

The MacBook Pro benefits because Apple manages both the hardware and the software. This close integration lets neuron accelerators work better with creative apps than what’s usually possible on Windows systems.  

The result is not just faster processing, but smoother, more reliable workflows.  

Apple Silicon and the Future of Independent Creative Production 

Big studios will keep investing in cloud systems, but independent creators face different challenges.  

Freelance editors, YouTubers, filmmakers, and digital agencies now need powerful AI tools without the big budgets of large companies. This shift favors systems that run efficient AI tasks locally.  

With Apple Silicon state-of-the-art neural accelerators and a more unified memory architecture, the M5 Pro is more than just a high-end chip. It functions as the backbone for decentralized creative work.  

The real importance of comparing Apple M5 Pro neural accelerator and M4 AI performance lies in what it reveals about the market. Buyers now look beyond speed or battery life and focus on how well laptops handle ongoing AI-assisted work.  

This acceleration may change how software is priced, how creators run their business, and even the economics of digital content.  

The AI Creative Economy Is Moving Closer to the Device 

Over the last decade, creative technology has increasingly moved to the cloud. AI could start to reverse that trend.  

As on-device LLM capabilities mature and AI video editing workloads grow more sophisticated, local compute efficiency becomes increasingly valuable. Systems that decrease latency, preserve privacy, and minimize recurring infrastructure costs will likely dominate the next phase of professional creative production.  

The latest iteration of Apple Silicon suggests Apple understands that transition clearly. The M5 Pro is not only about speed benchmarks or thinner hardware. It expresses a broader belief that the future of creative AI belongs closer to the device itself, where processing power, memory architecture, and intelligent acceleration operate together rather than across different servers.

Source: Apple introduces MacBook Pro with all‑new M5 Pro and M5 Max 

Bethesda, MD. A Navy aircraft flying beyond normal communication range cannot risk even a 2-second delay in command-and-control missions. Any lag is more than an inconvenience; it’s a real risk. This urgency is why the Pentagon is rethinking how military networks send data under difficult conditions.   

Lockheed Martin and Nokia Federal are teaming up just as defense agencies need faster and more flexible communication systems. Their focus on Open 5G and distributed tactical cloud shows how military operations are changing. Fixed networks no longer fit today’s battlefields. Mobility, interoperability, and strong edge connections are now key to mission success.  

The Lockheed Martin Nokia 5G solution for the US Navy TACAMO mission could have effects far beyond a single contract. This project might change how the government buys communications technology, uses cloud systems, and designs future military operations.  

Why Open 5G Matters Inside Tactical Cloud Environments 

Older defense communications systems relied on centralized setups. This approach worked when military operations used fixed command-and-control centers and stable communications. Today’s conflicts are not the same.  

Now, military operations use distributed assets and autonomous systems and face electronic warfare threats. Data moves constantly between air, sea, space, and ground. In these situations, rigid infrastructure can create weak points.  

This is where Open5G makes a difference.  

Open architectures, unlike closed wireless systems, let agencies combine software, radios, apps, and network features from different vendors. Such flexibility is important because defense agencies want to avoid being locked into a single vendor, which may slow upgrades and raise costs over time.  

In a distributed tactical cloud, being able to work among different systems is as important as having enough bandwidth. For example, a surveillance aircraft sending intelligence to naval units cannot rely on closed systems that struggle to share data between platforms.  

Lockheed Martin and Nokia Federal are working together to solve this problem.  

The Pentagon’s Shift Toward Modular Architecture 

In the past, defense agencies often signed large, long-term contracts for closed systems. Over time, this led to more sluggish upgrades, higher integration costs, and older systems that were hard to update.  

Now, federal agencies are seeking more flexible solutions.  

This is why there is more focus on modular architecture in military communications. Instead of replacing all systems every 10 years, agencies want networks that can update incrementally.  

The Lockheed Martin Nokia 4G solution for the US Navy Tacomo mission is a good example of this new approach.  

With a modular approach, software and networking components can be updated without requiring hardware updates. Security can be updated when needed, and new applications can be added at the edge without rebuilding the whole system. Such flexibility helps military planners avoid interruptions and make long-term purchasing more efficient.  

It changes how defense procurement works financially.  

Defense Procurement Is Moving Away From Closed Ecosystems 

For years, big defense contractors used integrated systems that made agencies depend on them for the long term. Now, this approach to buying technology does not align with the Pentagon’s push to modernize.  

Officials now emphasize speed, interoperability, and rapid software deployment.  

With an open network approach, agencies can adopt new technologies more quickly without having to rebuild their entire communications setup. This change benefits companies like Lockheed Martin and Nokia Federal since they know how to meet the needs of secure federal networks and support open standards.  

This has a big impact on how defense procurement will work in the future.  

Programs using Open 5G could accelerate deployment and reduce maintenance costs over time. Instead of waiting years for hardware updates, agencies can modernize incrementally, as commercial tech companies do.  

Being able to adapt quickly is important because adversaries are continually improving their cyber and electronic warfare capabilities.  

Zero Trust Is Becoming A Battlefield Requirement 

Military communications now assume that breaches will happen. This way of thinking changes how networks are designed.  

Old security models that protect only the network’s edge do not work well in modern military settings where devices, people, and systems move between safe and risky areas.  

That’s why zero-trust frameworks are now central to federal networking plans.  

In a modern tactical cloud, every device and user must continuously verify their identity to access data or network resources. Checking identity is now ongoing, not just occasionally.  

Using zero trust in Open 5G enables defense teams to quickly isolate compromised devices while keeping the overall mission running smoothly.  

This is especially important for airborne communication systems in sensitive operations such as TACAMO, where continuous connectivity is required for strategic nuclear command.  

With so much at risk, there is no room for weak network designs.  

Open 5G and Tactical Cloud Deployment at the Edge 

A key benefit of Open 5G is that it can support edge computing with very low delays.  

Conventional centralized clouds can struggle to handle real-time battlefield data when network capacity is limited. A distributed tactical cloud solves this by moving computing power closer to where it is needed.  

For example, if a patrol aircraft spots a new threat in contested waters, older networks would send the data to faraway centers before leaders could act. With edge-enabled systems, analysis happens close to the source, cutting response times.  

This faster response time is a real competitive advantage.  

The Lockheed Martin Nokia 5G solution for the US Navy TACAMO mission demonstrates how edge networking and modular communications are converging in military upgrades.  

The aim is not just to connect, but to keep connections working even under tough conditions.  

Nokia Services’ Strategic Position in Military Networking 

Lockheed Martin offers strong defense integration capabilities, while Nokia Federal brings years of telecom engineering experience that aligns with today’s military needs.   

Federal agencies want commercial-level innovation that works in mission-critical settings. This creates opportunities for telecom companies to provide secure, reliable networks at scale.   

By combining modular architecture, distributed cloud, and zero trust, Nokia Federal becomes more than just a vendor. It becomes part of the core operational infrastructure.   

This matters because future military strength might depend more on how well data moves across connected systems than on having the best hardware alone.  

Tactical Cloud Infrastructure Will Shape the Next Defense Era 

Military strength now depends more on strong, resilient networks than just on the size of ships or planes. These platforms are part of a bigger data system.  

This makes open 5G and distributed tactical cloud systems even more important for strategic operations. The Lockheed Martin and Nokia partnership shows a bigger shift in defense modernization. Agencies no longer want fixed communication systems with slow update cycles. They want flexible networks that can adapt as threats change.  

With rising worldwide tensions and better electronic warfare tools, having secure, modular, and fast communication systems may matter more than just having lots of hardware. The new infrastructure in Lockheed Martin’s Nokia 5G solution for the US Navy TACAMO mission suggests that future military strength could depend as much on network design as on traditional weapons.

Source: Lockheedmartin  

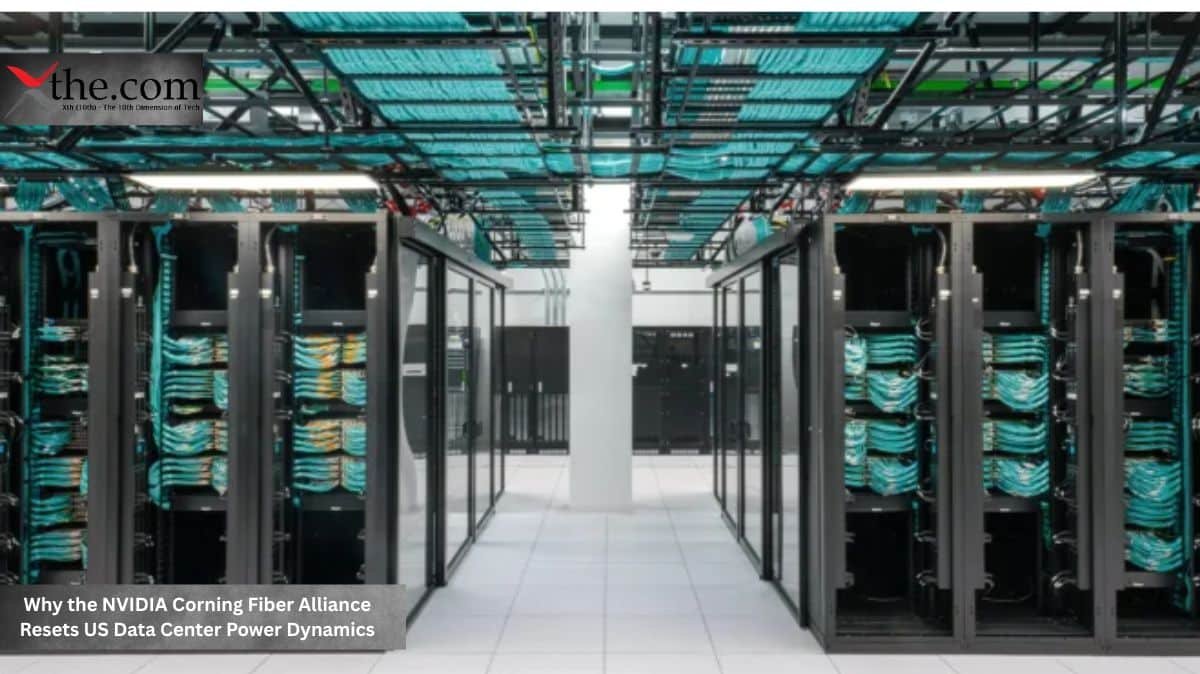
New York, NY. A single AI query uses almost 10 times more network traffic than a typical cloud search. Many executives may not realize how important this is. As GPU arrays grow across the US, the main challenge is shifting from computing power to physical infrastructure that connects these systems. The partnership between Corning and Nvidia is a direct response to this issue and could change how AI infrastructure is built in the US.   

The main issue is not only about making cables faster, but it is also about energy efficiency, control over manufacturing, and the costs of scaling up new AI systems. The impact of the Nvidia and Corning fiber optic partnership on US AI infrastructure goes well beyond buying hardware. It affects national competitiveness, energy use, and the future of American leadership in cloud technology.  

The Hidden Bottleneck Inside AI Infrastructure 

For years, large-scale operators focused on adding more computing power, GPUs, racks, and cooling. But data traffic congestion has quietly become the weak point in big AI training setups.  

Modern language models need thousands of GPUs to share huge datasets. At the same time, even tiny delays can lower training efficiency across these distributed systems. This is when networking latency becomes a financial issue, not only a technical one.  

If synchronization is delayed in a 100,000-GPU cluster, it can waste millions of dollars in computing each year. This is why fiber optic manufacturing is now a key topic in infrastructure planning.  

Optical fiber, unlike traditional copper connections, offers higher bandwidth and requires less power per bit. For those running dense AI clusters, this difference directly affects operating costs.  

The NVIDIA and Corning partnership is designed to tackle this exact challenge.  

Why Corning Matters More Than Most Investors Assume 

Most people know Corning for making smartphone glass, but in the tech industry, Corning has spent decades developing expertise in optical networking components and sophisticated cables.  

This manufacturing background has suddenly become strategically very important.  

The US is under increasing pressure to strengthen its domestic semiconductor and networking supply chains. Recent global political tensions have shown how much American tech companies still rely on overseas factories.  

Optical networking equipment is a key part of this vulnerability.  

By expanding US-based fiber optic manufacturing, Corning gives cloud providers and AI operators a stronger sourcing strategy. This matters to companies building multi-billion-dollar campuses, where supply disruptions might delay deployment schedules by months.  

The financial effect is substantial. A large AI facility might need hundreds of thousands of fiber connections. If transceivers or cables are delayed, the entire project can be put on hold.  

This is one reason why the NVIDIA and Corning fiber optic partnership has effects that go far beyond a typical vendor deal for US AI infrastructure.  

AI Infrastructure Is Becoming a Power Management Problem 

Most public conversations about AI focus on chips, but energy use is another important part of the story.  

Large AI clusters now use as much electricity as small cities. Moving data between GPUs significantly increases power consumption. Operators now have two main challenges: speeding up communication and cutting energy costs.  

Optical networking helps address both of these problems.  

Compared to copper-based systems, advanced fiber-optic systems reduce heat and improve data transmission over long distances. This effectiveness is especially important in large data centers, where rack density continues to increase.  

Microsoft, Amazon, and Meta are already under greater scrutiny from utilities and regulators over how much power they consume. Every watt saved in networking adds up across millions of tasks running at once.  

This is why AI infrastructure and fiber optic manufacturing are now closely linked to energy strategies.  

The Competitive Race Behind Domestic Supply Chain Expansion 

The US is not the only country investing in AI networking. China is expanding its state-backed optical manufacturing, and Saudi Middle Eastern countries are heavily funding their own AI infrastructure projects.  

This competition is a strategic concern for both Washington and Silicon Valley.   

A stronger domestic supply chain helps protect against geopolitical interruptions and allows American companies to deploy faster. It also gives the US more leverage in future trade talks about semiconductors and telecom infrastructure.  

For Nvidia, working with Corning brings benefits beyond just logistics. It lets them better connect GPU systems with optical networking technologies designed for AI workloads.  

This merging could reduce network latency in distributed AI clusters, especially as models continue to grow to trillions of parameters and beyond.  

The advantages are evident. Faster connections can cut model training times by days or even weeks for companies competing in generative AI. This time savings can directly lead to more revenue.  

Hyperscale Data Centers Confront a New Infrastructure Hierarchy 

For the past 20 years, expanding data centers followed a set pattern: get land, secure power, install servers, and then grow outward.  

AI changes that hierarchy.  

Now, network design is a key factor in whether a facility can efficiently handle advanced AI workloads. Operators can no longer see connectivity as a minor purchase.  

Inside modern hyperscale data centers, optical interconnect density now rivals power delivery as a design priority. The shift elevates companies involved in fiber-optic manufacturing from component suppliers to strategic infrastructure partners.  

This shift explains why the Nvidia and Corning partnership is getting so much focus from investors and tech companies.  

The partnership addresses three main challenges simultaneously. They are the rising demand for AI bandwidth, growing concerns about domestic supply chain resilience, and rising energy costs for AI infrastructure. Very few infrastructure deals affect all three of these areas simultaneously.  

NVIDIA’s Expanding Infrastructure Strategy 

For NVIDIA, this cooperation is part of a bigger strategic change.  

NVIDIA is not simply a GPU vendor. The company is now presenting itself as a full AI infrastructure provider, covering computing, networking, cooling, and systems integration.  

This change is important because future enterprise AI spending will likely focus on comprehensive infrastructure solutions rather than buying separate hardware components.  

By partnering with Corning, NVIDIA gains more control over a key part of AI deployment. This move also puts pressure on networking suppliers who still rely on scattered international supply chains.  

The wider impact of the NVIDIA and Corning fiber-optic partnership could change how the cloud industry sets its purchasing priorities. Companies planning future AI projects may start to value US-made networking systems that are closely linked to GPU performance.  

This would be a major shift in how tech companies evaluate infrastructure investments.  

The Next Phase of AI Infrastructure Will Be Physical 

Software has gotten most of the attention, and hardware has gotten the profits, but physical connectivity might end up deciding which companies come out on top.  

As AI systems continue to grow, companies that reduce network latency, manage energy use, and maintain a stable supply chain will have an edge. These abilities now depend more on advances in fiber-optic manufacturing than on computing power alone.  

The Corning and Nvidia partnership shows this new reality. It suggests that the future of American AI leadership could rely as much on glass, cables, and optical engineering as on silicon chips. 

Source: NVIDIA and Corning Announce Long-Term Partnership to Strengthen US Manufacturing for AI Infrastructure 

REDMOND, Wash. — Microsoft has developed the Microsoft AVA-100 benchmark framework, a comprehensive testing platform that evaluates how modern AI systems comprehend and process extended video footage from open-world settings.   

The benchmark test is a part of the NSDI 2026 research project, which involves technical discussions between the two research areas. The benchmark test introduces a new method for assessing video intelligence systems used in enterprise environments, security operations, and multimodal artificial intelligence applications.   

The launch will drive a major transformation, changing people’s expectations for Video Analytics, long-context AI processing, and real-time multimodal reasoning systems.  

Why Microsoft AVA-100 Matters  

The introduction of Microsoft AVA-100 signals a transition away from short-form AI video testing toward persistent, real-world contextual analysis. Traditional video AI benchmarks did not measure complete movies but instead tested short clips using specific recognition abilities, such as object detection and scene classification.   

AVA-100 tests AI systems on their ability to sustain contextual awareness over extended periods, including continuously changing video content. The evaluation process for enterprise-level AI systems has reached a significant transformation through this development.  

Video Analytics Enters the Long-Context Era  

The advanced Video Analytics capabilities have grown as enterprises now require systems that provide continuous video interpretation.   

The security, logistics, healthcare, manufacturing, and autonomous systems industries now depend on AI-based monitoring systems that can analyze large visual data streams over extended time frames.   

Traditional models often struggled to maintain continuity across long-duration footage.   

The AVA-100 framework tests the ability of systems to maintain contextual understanding throughout time.  

Vision Language Models Become Central Infrastructure  

AI systems now use Vision-Language Models (VLMs) to interpret visual information in a new way.   

VLM systems process video content by leveraging visual comprehension, their ability to understand spoken language, and knowledge of the surrounding context.   

The system enables AI to create better video content analysis by improving observation, summary generation, and the development of operational insights.   

Multimodal AI infrastructure development depends on the progress of Vision-Language Model (VLM) technology.  

NSDI 2026 Research Signals Infrastructure Shift  

The research link between AVA-100 and NSDI 2026 establishes that scalable AI systems are essential for processing long-duration data.   

The system requires new AI infrastructure design solutions that must function at both cloud and edge computing locations.   

The research findings from NSDI 2026 demonstrate that video AI systems now require greater computational resources than before.  

Ultra-Long Context Changes AI Expectations  

The primary characteristic that defines AVA-100 exists because it requires users to perform Ultra-Long Context reasoning tasks.   

AI systems need to develop memory capabilities that enable them to understand contextual information over extended time periods, rather than processing each input as a separate entity.   

This requirement is particularly significant for applications that involve surveillance and enterprise monitoring, as well as autonomous operations and media intelligence.   

Ultra-Long Context processing development will create new design requirements that will shape the future of multimodal artificial intelligence systems.   

Research from NSDI 2026 indicates that video artificial intelligence is now a critical requirement for modern computer systems.  

Open-World AI Expands Beyond Controlled Datasets  

The Open-World AI research field has developed new benchmarks to evaluate its ability to operate in unpredictable environments without predefined scripts.   

Open-world systems need to interpret real-world conditions, which are constantly changing, unlike closed testing environments that use fixed categories and labels.   

The system requires multiple AI reasoning evaluation methods, which pose greater challenges than standard testing procedures.   

The AVA-100 framework has been created to assess this wider range of contextual adaptability.  

Heuristic Analysis Enhances AI Reasoning  

The adoption of Heuristic Analysis for long-form video assessment marks a shift toward evaluation methods that better resemble human thinking.   

The heuristic approach enables AI systems to detect patterns and select important information while their understanding evolves through flexible interpretation.   

The advancement of video AI systems through operational environments.   

Heuristic Analysis has become a universal trend driving the development of contextual intelligence systems.  

Enterprise Video AI Demands Are Increasing  

The rapid expansion of video data across industries is creating strong demand for more capable AI interpretation systems.   

Organizations now need AI tools that can summarize content, detect anomalies, monitor behavior patterns, and produce operational insights from ongoing video streams.   

The development of long-context multimodal AI systems has become essential for organizations as they establish their infrastructure requirements.  

AVA-100 Reshapes AI Benchmark Standards  

The broader significance of why Microsoft AVA-100 is the new standard for 10-hour video AI analysis lies in its attempt to redefine how AI capability itself is measured.  

The benchmark system assesses contextual persistence, reasoning continuity, and adaptive interpretation over extended periods.   

The evaluation system for artificial intelligence now uses a different approach according to this evidence.  

Video AI Becomes Core Infrastructure Layer  

Business operations already use AI-powered monitoring and automation systems, which help us establish video intelligence as our primary operational foundation rather than treating it as an analytical tool for specific situations.   

The growth of this industry impacts multiple sectors, which include defense, transportation, and retail and industrial automation.   

The market requires scalable video reasoning systems that can operate for extended periods.  

Conclusion: Microsoft Pushes Video AI Into Persistent Intelligence  

Microsoft’s AVA-100 system launch marks a significant advancement in evaluating AI systems that assess real video content.   

Microsoft develops multimodal AI systems through Video Analytics and Vision Language Models, Ultra-Long Context, and Open-World AI and Heuristic Analysis to create permanent contextual understanding systems that operate across intricate operational domains.   

NSDI 2026 research demonstrates that scalable, long-context reasoning has become a fundamental obstacle that next-generation AI infrastructure must overcome.  

As enterprises explore why Microsoft AVA-100 is the new standard for 10-hour video AI analysis, the future of video intelligence appears increasingly focused on continuity, adaptability, and operational-scale reasoning rather than isolated recognition tasks alone.

Source: Microsoft Research Blog 

SANTA CLARA, Calif. — NVIDIA has published additional technical information about the NVIDIA Space-1 platform, which operates on the new Vera Rubin Architecture. This launch marks a significant extension of AI acceleration capabilities, which now reach beyond Earth-based systems to support military operations in space.   

The announcement highlights a growing convergence between space systems, autonomous AI infrastructure, and defense computing strategy.   

The United States has identified AI-native hardware systems as critical components for satellite and defense platform operations, as orbital systems are becoming increasingly data-intensive and independent.  

Why NVIDIA Space-1 Matters  

The NVIDIA Space-1 initiative seeks to develop advanced AI computing systems that can operate in orbital environments with high latency, limited bandwidth, and the need for autonomous operation.   

Traditional satellites relied on ground systems to perform their most computationally intensive tasks.   

The current defense and intelligence systems demand that their operational functions have real-time decision-making capabilities enabled by space-based systems.   

The military needs onboard AI acceleration because it is now more critical than in earlier space systems.  

Vera Rubin Architecture Expands Beyond Data Centers  

The Vera Rubin Architecture serves as the architectural framework NVIDIA uses to build its AI infrastructure that operates at scale across different environments, including the cloud, edge, and orbital space.   

The architecture, developed to enable enormous AI computations and fast computer systems, is now used to create systems that operate autonomously.   

The development of AI hardware design will create new applications that extend beyond traditional data center usage.   

Defense-oriented systems that adopt the Vera Rubin Architecture will drive a major transformation in how military computing systems operate.  

BlueField-4 STX Supports Autonomous Processing  

The orbital platform strategy relies on BlueField-4 STX, which manages secure data movement and networking acceleration, as well as AI workload orchestration across distributed systems.   

Centralized processing models face difficulties because the orbital systems experience communication delays and their connections break intermittently.   

BlueField-4 STX enables more localized compute management and autonomous system coordination directly at the edge of the network.   

This technology holds significant importance for upcoming space-based AI operations.  

Orbital Computing Becomes Strategic Infrastructure  

The emergence of Orbital Computing technology is driving a fundamental transformation in defense and communications system design.   

Future systems will begin processing intelligence, navigation, and operational data through space infrastructure rather than relying solely on Earth-based processing centers.   

The system achieves improved response times by operating independently of fragile ground networks while enabling self-sufficient operations in areas under enemy control.   

The expansion of Orbital Computing has become an essential element of contemporary defense planning.  

Agentic Space Systems Gain Importance  

The concept of Agentic Space describes cosmic orbital systems that operate through their own intelligence to choose their actions and coordinate their movements while performing their tasks with minimal human assistance.   

The development of artificial intelligence will enable satellites and space assets to operate as intelligent, autonomous entities rather than remain mere communication devices.   

The system includes three main functions: automated system surveillance, security evaluation, data ranking, and system network management.   

The development of Agentic Space infrastructure systems has brought about a major change that affects all aspects of space mission operations.  

Edge AI Extends Beyond Earth-Based Systems  

The orbital infrastructure requires Edge AI because remote areas need distributed intelligence to function effectively.   

Edge AI enables systems to handle processing tasks at local sites without needing complete access to centralized cloud systems.   

The system enables defense and satellite missions to achieve faster communication while maintaining operational stability under challenging network conditions.   

Space systems now use Edge AI because AI systems have evolved to operate through multiple decentralized components.  

Defense Procurement Priorities Are Shifting  

The United States defense procurement process is now undergoing changes due to newly developed orbital AI systems.   

Defence Procurement decisions will increasingly require defense organizations to adopt AI-native hardware, autonomous coordination systems, and resilient distributed computing systems.  

Defense contractors and technology providers need to adjust their marketing strategies because of new infrastructure platform developments.   

Organizations now consider AI acceleration an essential strategic capability rather than treating it as an additional technological resource.  

Orbital Systems Require Autonomous Coordination  

The growing complexity of orbital environments demands the development of systems that can operate without continuous ground control supervision.   

The system needs to handle four primary tasks: traffic management, threat detection, communication optimization, and resource allocation.   

The operational requirements of AI-driven orbital systems exceed the efficiency of conventional systems that rely on human operators.   

The growing investment in autonomous orbital infrastructure systems stems from this particular aspect.  

Vera Rubin Architecture and US Defense Integration  

The broader significance of integrating NVIDIA Vera Rubin architecture into US orbital defense systems lies in the convergence of AI infrastructure with national security operations.  

The military systems now require real-time intelligence processing and autonomous operational capabilities, which make AI acceleration platforms essential for developing future defense systems.   

The new rules will affect procurement standards, strategic partnerships, and future military infrastructure planning.  

Orbital AI Competition Intensifies  

The introduction of AI-based orbital systems will increase competition between defense contractors, semiconductor companies, and aerospace manufacturers.   

Countries that develop autonomous satellite systems will gain an advantage because their systems will improve monitoring capabilities, communication systems, and emergency response.  

This creates a new frontier where AI computing and aerospace systems increasingly overlap.  

Conclusion: AI Infrastructure Expands Into Orbital Defense  

The release of NVIDIA’s Space-1 specifications based on the Vera Rubin Architecture marks a major evolution in the relationship between AI infrastructure and defense systems.   

NVIDIA achieves its goal of extending AI acceleration to autonomous orbital environments through its combination of BlueField-4 STX with Orbital Computing and Agentic Space and Edge AI capabilities.   

The current shift in Defense Procurement priorities indicates that upcoming military and intelligence systems will increasingly rely on space-based, distributed AI-native computing infrastructure.  

As organizations explore integrating NVIDIA Vera Rubin architecture into US orbital defense systems, orbital AI platforms are rapidly emerging as a new strategic layer in national defense and infrastructure modernization.

Source: NVIDIA GTC 2026: Live Updates on What’s Next in AI 

REDMOND, Wash. — Windows Autopatch and Hotpatching advanced features have now completed their deployment across enterprise Windows systems to support Microsoft’s goal of permanent system maintenance.   

The initiative represents a fundamental transformation of enterprise IT operations because companies now choose to implement security updates that protect against threats while maintaining their normal operational processes.   

The need for uninterrupted operations while cyber threats develop has led enterprises to adopt reboot-free patch deployment as their new standard for system infrastructure.  

Why Windows Autopatch Matters  

The Windows Autopatch expansion project aims to reduce the operational workload companies experience when using standard methods to manage system updates.   

The complete system update process required organizations to manually schedule updates, manage device restarts, and plan system unavailability periods for their entire network of devices.   

The platform automates most operations through its system, which manages update distribution, system testing, and policy enforcement from a single cloud-based control center.   

The solution helps businesses achieve consistent operations by simplifying maintenance requirements.  

Hotpatching Eliminates Traditional Restart Cycles  

The main breakthrough of Hotpatching technology enables users to install security patches on active systems without restarting them.   

Patching methods from the past disrupted work activities because essential system elements required restarts for implementation.   

Hotpatching enables real-time system updates by changing the contents of active system memory.   

This capability fundamentally transforms the methods that businesses use to manage software updates and plan for system availability.  

Zero-Downtime IT Becomes a Priority  

The main reason organizations adopt hotpatch technology comes from their need to maintain operations with zero downtime.  

Worldwide business operations require modern organizations to maintain their systems because their customers need access to their services at all times.   

Short system reboots cause operational interruptions that affect financial systems, logistics networks, healthcare environments, and manufacturing operations.   

Organizations achieve their goal of maintaining operational systems without interruption through hotpatching technology.  

VBS Security Strengthens Enterprise Protection  

The expansion of VBS Security integration is another important element of Microsoft’s enterprise update plan.   

Virtualization-Based Security protects critical system functions and security processes by creating secure virtualized environments.   

The system reduces vulnerability to kernel attacks while boosting protection systems that guard against endpoint threats.   

Enterprises can achieve better system availability and stronger security protection by using hotpatch deployment together with VBS Security.  

Azure Arc Extends Centralized Control  

Organizations use Azure Arc to maintain consistent management of Windows infrastructure across their cloud environments, on-premises systems, and hybrid deployments.   

Azure Arc enables IT teams to implement governance, monitoring, and update procedures across their entire distributed device network from a single central control system.   

Enterprises that have adopted hybrid infrastructure systems need this solution to meet their operational requirements.   

The combination of Autopatch and Azure Arc creates a more unified operational framework for enterprise endpoint management.  

Patch Tuesday Evolves Beyond Monthly Maintenance  

The standard schedule for Microsoft security updates used to follow Patch Tuesday for several years. The rising complexity of cyber threats, along with the need for rapid threat resolution, has compelled organizations to adopt permanent security update systems.   

Hotpatching enables organizations to reduce the need for complete system shutdowns, which were previously required during Patch Tuesday operations. The organization has begun moving away from its standard maintenance schedule and adopting a system that provides ongoing security updates.  

Endpoint Manager Supports Automation at Scale  

As organizations automate update orchestration for their device fleets, the position of Endpoint Manager is gaining recognition. 

By definition, the endpoint manager allows IT teams to set up deployment policies, track deployment compliance, and manage the rollout sequences of enterprise systems. 

When combined with hotpatching, this creates a more adaptive and less disruptive maintenance environment.  

The growing reliance on Endpoint Manager reflects broader trends toward autonomous IT operations.  

Enterprise Downtime Costs Continue Rising  

The financial costs of downtime have become the primary driver of businesses’ decisions to implement hotpatch systems.   

Even short service interruptions will disrupt three main areas of business operations: productivity, operational continuity, and customer-facing services.   

Organizations gain both technical and economic benefits by reducing the time required for system restarts during maintenance activities.   

This requirement holds special significance for industries that operate continuously throughout the entire week.  

Windows 11 and 12 Move Toward Continuous Maintenance  

The broader significance of eliminating reboot-related downtime with Windows 11/12 Hotpatching lies in the evolution of operating systems into continuously maintained platforms.  

Future enterprise operating systems will use background updates to deliver most security and stability updates, rather than disruptive maintenance cycles.   

This development will create new user expectations about how devices should be maintained and how operations should continue.  

Hybrid Infrastructure Demands Flexible Updates  

As enterprises continue expanding their hybrid and remote work environments, traditional maintenance approaches become increasingly difficult to manage.   

Systems that operate across different geographical areas and network environments need flexible update systems to meet their needs.   

Hotpatching solves these issues by enabling continuous operations across the entire distributed infrastructure.  

Conclusion: Enterprise Maintenance Enters the Continuous Era  

Microsoft has developed Windows Autopatch and Hotpatching as advanced solutions for managing enterprise systems.   

Microsoft has developed new methods for operating system management and cybersecurity protection through its technology, which enables organizations to achieve Zero-Downtime operations while improving VBS Security and using Azure Arc and Endpoint Manager for system management.   

Patch Tuesday now serves a different purpose because organizations have shifted toward security delivery systems that focus on maintaining system availability while protecting against threats.  

As enterprises explore eliminating reboot-related downtime with Windows 11/12 Hotpatching, operating system maintenance is increasingly evolving from scheduled interruption into seamless background infrastructure management.

Source: Accenture is rolling out Copilot to a workforce the size of Denver. Here’s how they’re doing it. 

Armonk, N. Y. On average, developing a new pharmaceutical drug costs $2.3 billion and takes more than 10 years of lab work. Most clinical candidates, 9 out of 10, fail during development. This is awesome because conventional computers cannot precisely predict how molecules behave inside human proteins. A new computational method is changing this. A recent breakthrough with a 12635-atom protein complex demonstrates the real potential of quantum-centric supercomputing at a scale never before achieved. Pharmaceutical leaders now have a chance to rethink their R&D budgets. Moving from trial-and-error testing to predictive calculations can lower costs, reduce animal testing, and speed up the delivery of new treatments.  

The Technical Breakthrough of the 12635-Atom Model 

Researchers from the Cleveland Clinic, RIKEN, and IBM zSecure achieved a major breakthrough by simulating protein-ligand interactions at a scale far greater than ever before. They modeled the trypsin enzyme and T4-lysozyme in water. Earlier quantum analysis could handle only small molecules with ten to a few hundred atoms. This new model is forty times larger than previous ones and two hundred and ten times more accurate for certain calculations.  

This hybrid workflow uses a wave function-based embedding algorithm. Classical supercomputers break the large molecular structure into smaller, manageable clusters. IBM quantum Heron processors then calculate the quantum attributes of these pieces. Afterward, the classical systems reassemble the full molecule. Combining classical and quantum computing units is what makes quantum-centric supercomputing so valuable for scientific research.   

This method’s accuracy helps address a long-standing industry problem. Predicting how a drug binds to a target protein usually takes months of trial and error. With this level of biomolecular simulation, researchers can test binding affinities and chemical reactions before making physical compounds.  

Structural Reduction of Capital Expenditures 

The traditional drug discovery process relies heavily on brute force synthesis and high-throughput screening. Pharmaceutical companies build massive physical libraries of compounds, and they test each one against disease targets. This approach calls for substantial investments in laboratory space, chemical supplies, and personnel. The fiscal benefits of quantum-centric supercomputing in pharmaceutical R&D include significant reductions in material costs, reduced reliance on animal testing, and shorter regulatory approval timelines. Companies spend millions of synthesizing variants that fail in early-stage validation. By eliminating ineffective compounds before synthesis, firms preserve resources for candidates with higher probabilities of clinical success.   

Executives need to shift funding from physical labs to high-performance computing clusters and quantum access points. This change means understanding infrastructure costs in detail. Chief financial officers now have to see computing hardware as a core operational need, not just an experimental expense.  

Managing Data Governance and Cryptography 

Bringing quantum chips together with classical supercomputers creates new data governance challenges. Pharmaceutical intellectual property includes sensitive patient data and proprietary molecular structures. Organizations must protect this information while sharing work between on-site supercomputers and cloud-based quantum nodes. Keeping molecular data safe means following strict security procedures. Companies using these mixed systems need to update their certification of lifecycle management. Automatically rotating cryptographic keys helps keep data moving between the Cleveland Clinic and remote data centers secure against interception. The aim is to maintain end-to-end encryption for sensitive data.   

There is also a risk that attackers could intercept research data, so companies need to take a preemptive approach to post-quantum security. Data stolen today could be decrypted in the future by powerful quantum computers. Pharmaceutical firms should set up cryptographically agile systems right away. This upgrade will require a major investment in security architecture. Updating the certificate lifestyle across global research networks helps prevent unauthorized access to proprietary molecular models. These security improvements also help companies meet strict regulatory requirements.  

Preparing Enterprise Infrastructure for the Future 

Bringing together different types of computing systems requires strong infrastructure planning. The RIKEN and IBM partnership shows how conventional computers and quantum computing units can work together in real time. To match this scale, enterprise data centers need high-bandwidth, low-delay connections.  

Chief technology officers should review their current IT infrastructure before using these cutting-edge algorithms. They must make sure that graphical processing units, classical CPUs, and quantum computing units can communicate smoothly. The quantum-centric supercomputing model depends on this ongoing feedback loop.  

Investing in post-quantum security is important for protecting proprietary drug designs over this transition period. Using lattice-based cryptography helps safeguard intellectual property against future threats. This approach keeps data secure even as computing power continues to grow rapidly in the coming years.  

Transforming The Preclinical Pipeline 

Moving toward quantum-assisted discovery is changing the economics of the pharmaceutical industry. Being able to model large molecules such as trypsin and T4 lysozyme enables the replication of complex enzyme catalysts and biological receptors.  

The accuracy of biomolecular simulation depends on how well the system models physical forces. As quantum error correction gets better, these tests will become almost perfectly accurate. Pharmaceutical companies that use these methods will gain a clear market advantage and bring targeted therapies to market much faster than those using only classical modeling.

Source: IBM and Aramco Explore Collaboration to Accelerate AI