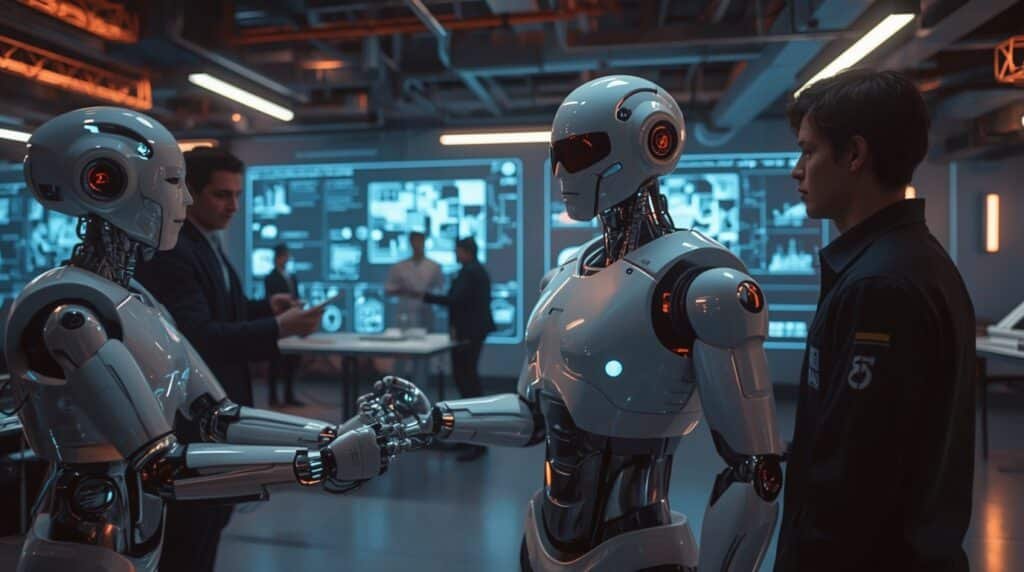
Humanoid robots have been around for decades, yet until recently, they have been more about creating a ‘cool’ visual experience than achieving tangible results. The advent of Tesla’s Optimus has changed that; it’s a working prototype of a humanoid robot and is no longer simply an idea for the future. 

Optimus has moved beyond being a prototype; it is now being tested in manufacturing to see whether humanoid robots can work in a real-world production environment. 

The transition from prototype to application is the pivotal point regarding physical Artificial Intelligence. 

Why is Optimus important now? 

Industrial Automation is not new. Many factories have been using industrial robots for years for repetitive, high-precision jobs such as welding, assembly, and packaging. But these industrial robots are generally fixed to a single location and designed for a single specific task. 

Optimus is fundamentally different in how it defines building a humanoid robot. Optimus represents a new type of plant-wide, general-purpose humanoid robot that can be programmed to do multiple jobs in the same environment. 

The versatility of Optimus means that, instead of building separate machines to do individual jobs, companies can potentially use one robotic machine or system that can learn to perform different jobs. This will completely change the way factories are constructed, staffed, and expanded. 

The Beginning of a Transition 

Assessing internal use is an essential quantifiable measure of actual progress. Tesla has begun testing Optimus within its own production processes, performing initial material handling and movement. 

These may appear to be straightforward tasks, but they have a significant effect on manufacturing operations, which rely heavily on repetitive physical labor involving moving parts, organizing components, and supporting assembly lines. These will be among the first tasks humanoid robots will help to fulfill. 

Therefore, even early trials of Optimus indicate that it has moved from demonstrations and testing into production environments in which efficiency, repeatability, and reliability are important. 

The Economic Model Is Evolving 

The greatest long-term impact of humanoid robot technology is on economic models. Traditional automation requires substantial capital investment in machines, customization, and integration into businesses’ existing workflows. Automation systems are built to perform a specific workflow, which creates challenges when modifying or scaling them out. 

While businesses may invest in multiple specialized machines, fewer adaptable robots could be deployed as the technology matures, resulting in lower capital and maintenance costs and increased operational flexibility. 

Labor costs factor into this equation as well. Robots are unlikely to fully replace human workers in the near term, but they can reduce reliance on significant amounts of repetitive manual labor. 

Industry Implications 

Tesla has developed Optimus using artificial intelligence. For example, it can perceive its surroundings and decide how to navigate its environment. 

All of these features allow Optimus to: 

  • Grasp and process information about its environment 
  • Adapt to constantly changing conditions 
  • Improve by performing the same task multiple times 
  • Become better at what it does 

Therefore, Optimus is not just doing what it is told to do- it is learning. This is where physical artificial intelligence takes on a new role. The combination of robotics and artificial intelligence enables the development of systems that are fully automated yet adaptable and scalable. 

Possible Impacts On Industry 

If Optimus continues to improve as it has so far, its impact could be felt across many other industries beyond Tesla. Many companies in the broader manufacturing industry are closely monitoring the performance of these early deployment projects, hoping to replicate similar results. 

If we see a successful implementation of Tesla’s Optimus, there will certainly be a ripple effect that will lead to: 

  • The use of humanoid robots in many industries 
  • Increased investments in physical AI systems 
  • Factory workflows are being redesigned based on flexible manufacturing processes 

In addition to affecting how companies operate, it will also affect the labor force, particularly those in repetitive, manual labor jobs. This raises concerns about job loss but also provides ample opportunity to create new positions related to managing and maintaining robots, as well as training AI. 

Conclusion 

Tesla’s Optimus is not just another robotics project—it represents a broader shift toward physical AI systems that operate in real-world environments. 

Early deployments, even at a small scale, signal that humanoid robots are moving beyond experimentation. If progress continues, they could reshape how factories operate, how costs are structured, and how automation is understood. The transition will not happen overnight. But for the first time, it feels less like a distant future and more like an emerging reality. 

Source: Tesla  
Traditionally, many Software-as-a-Service (SaaS) providers viewed compliance as an afterthought. Although they acknowledged its importance, it was rarely a priority. As a result, many SaaS providers are in jeopardy today due to the rapidly evolving nature of data and the increasing global compliance regulations. In addition to the rapid increase in compliance regulations, organizations are also required to properly implement them through their compliance processes. 

There have been few announcements or deadlines associated with the implementation of new data/compliance regulations. The previous “waves” of regulations have been well-publicized, and the regulations appear similar on the surface. However, there is a significant difference between the previous methods of enforcing compliance regulations and the current approaches. 

Enforcement Is No Longer Passive 

Historically, regulatory agencies have relied primarily on enforcement through voluntary compliance (self-reporting) and responding to incidents of non-compliance or received complaints. However, this approach to enforcement is quickly diminishing. Rather, regulatory agencies are now utilizing/proactively monitoring systems that allow them to monitor organizations’ data processing activities without requiring a violation to occur. 

Therefore, organizations are now being monitored on an ongoing basis for compliance—except during a crisis. Regulatory agencies are assessing organizations’ internal processes for obtaining consent from individuals, where data is stored, and how third parties are involved in data processing. Organizations that do not fully comply with expectations may receive serious warnings or face penalties. 

The current state of enforcement has shifted from “reactive” to “proactive,” making it an opportune time for organizations. Therefore, no organization should consider that there is no likelihood that something negative has occurred that would preclude it from being subject to an enforcement action. 

Proof of Compliance Is Now Required, Not Just A Claim 

One of the biggest changes in compliance is the demand for proof of compliance through demonstrable evidence. The days of simply saying, “I comply with regulations,” and moving on are over; it is no longer sufficient to “say” that you comply; now you must “prove” it by providing detailed records and systems. 

Some of the items that fall into this category are as follows: 

  • Clearly defined data flow maps 
  • Audit trails of user data 
  • Documented consent mechanisms 
  • Mechanisms for internal accountability 

Most SaaS companies, particularly start-ups, are experiencing a tremendous shift in their operations as they meet compliance requirements, because building systems to track and justify every data-related event will require a great deal of time, financial resources, and expertise. In summary, compliance is becoming part of the infrastructure rather than just part of policy. 

The Complexity of Cross-Border Data 

Lots of SaaS providers operate all over the world; however, this has become much more difficult with the recent development of local data regulations. Governments are tightening regulations governing where and how data can be stored and transferred between countries. 

Data localization laws will ultimately force businesses to re-evaluate how they architect their environments. Instead of using a single, centralized system for the entire world, companies will need to use multiple regional or cloud-hosted systems, thereby compounding existing layers of cost and complexity. 

The technical determination of where to host customer data is no longer just a technical decision; it is also a legal one. 

Costs Will Continue to Rise 

The various changes in regulations come at a price—and compliance has gone from being an overhead, fixed cost to being a growing area of investment for businesses. 

For businesses, including: 

  • Legal help (advisory and interpretation of policies) 
  • Internal compliance teams (legal) 
  • Third Party Audits and Certifications 

For small- to mid-sized SaaS businesses, this added compliance will directly affect their ability to grow and become profitable. For larger businesses, the challenge will be scaling compliance across multiple products and global locations without stifling their ability to innovate. 

Whether small or large, the growing cost pressure and compliance workloads are a reality. 

Preparedness Gap 

Despite clear warnings, many businesses remain unprepared for this new landscape. One major challenge in preparing businesses for compliance is a misperception that a large business will receive more scrutiny as compared to a small business — but, regulations are increasingly putting small businesses under the same level of scrutiny as large enterprises; e.g., businesses that deal with and house a high volume of users’ sensitive data. 

The second challenge is execution; just because you understand regulations does not make it easy to implement compliance within your business. Today’s successful businesses rely on all teams (legal, tech, product, and operations) to work together when complying with various regulations. If teams are not aligned, then businesses will have compliance gaps. 

The gap between awareness and compliance execution today is where all major risks lie. 

Technology: Solution and Risk 

The Use of Technology to Mitigate Risk and Comply; Protect Against Compliance and Risk: Technology is revolutionizing how businesses create systems to manage and comply with regulations. Automated systems, artificial intelligence, and compliance dashboards are enabling businesses to have greater visibility into how to maintain and ensure compliance. 

On the other hand, there is a downside to using these tools. 

As regulations increasingly focus on SaaS applications, regulators are beginning to challenge the operational aspects of automated systems. Issues related to algorithmic transparency, data security,, and the way compliance with regulations is determined are now being scrutinized by regulators. As a result, businesses are now required to ensure their automated systems comply with regulations. 

So while technology eliminates the need for manual processes, it also adds additional layers of scrutiny to automated systems. Hence, companies that rely on the latest technology are required to continually evaluate if their tools are compliant as they apply them to their operations. 

What Should Businesses Do? 

SaaS companies need to think of compliance differently. Instead of reacting to new regulations as they come out, businesses need to build the necessary infrastructure and operational processes to anticipate and adapt to how they will be in compliance with regulations going forward. 

To accomplish this: 

• Invest in building a scalable compliance infrastructure 

• Establishing clear policies that are regularly updated internally 

• Training staff members to ensure they understand compliance and associated issues/costs 

• Staying informed about changes in regulatory policies on a real-time basis. 

Conclusion 

Compliance needs to be thought of no longer as just a “legal” obligation, but rather as an integral part of your business strategy. 

In SaaS companies, it has gone from the question of whether compliance is important to how do we successfully comply with regulations? To succeed, companies that respond to and/or adapt to change sooner will build credibility with their customers. Ultimately, in a data-oriented economy, gaining credibility is the best overall advantage. 

Source: Data Governance Regulations and Compliance Essentials 

Many developers anticipated that cloud dependence would escalate as AI functionality expanded across operating systems. Instead, Apple’s latest macOS update discreetly shifts away from the cloud, transforming how intelligence is executed on personal devices. While the change is understated, it has significant effects on performance, privacy, and infrastructure costs. Apple is not eliminating cloud use, but it is decreasing users’ routine reliance on it.  

Apple’s new macOS features focus on processing data locally rather than in the cloud. These updates use local hardware, especially Apple silicon chips. Now tasks like text summarization, image enhancement, and voice transcription happen right on your computer.  

This approach means less dependence on external servers. It also reduces delays, so responses are faster without waiting on the network. Users can see the improvement right away during real-time tasks.  

On Device Intelligence Becomes The Default 

Apple’s strategy is to build AI directly into the operating system, handling tasks like predictive typing, smart search, and contextual suggestions on the device rather than sending them to remote servers.  

One major benefit is reliability. AI features remain functional even without internet access. For businesses, this dependability is crucial in secure or offline environments.  

Processing data locally also helps protect sensitive information. Files and user activity remain on the device instead of being sent elsewhere.  

Hardware Drives the Shift 

Apple’s move away from the cloud relies on specialized hardware. Apple Silicon integrates CPUs, GPUs, and neural engines into a single system. This setup lets AI tasks run efficiently without needing outside computing power.  

For example, the neural engine accelerates machine learning tasks such as image recognition. These tasks run faster and use less power than if they were done in the cloud.  

Because Apple controls both the software and hardware, it can optimize performance more effectively. This gives Apple an edge over competitors who use standard hardware.  

Privacy as a Strategic Advantage 

Apple has always made privacy a feature by keeping data on the device. Its new AI approach in macOS further reduces the need to send personal information to the cloud.  

This is important for both regular users and businesses. Sensitive documents, emails, and workflows stay on the device. It also gets easier to meet regulations when less data is moved around.  

This approach also helps build trust. People are more likely to use AI features when they know where their data is handled.  

Reduced Cloud Costs for Enterprises 

Cloud-based AI comes with ongoing costs for every API call, data transfer, and computing task. Apple’s shift away from the cloud changes this situation.  

Companies can move some AI tasks to employees’ devices, reducing the need for central servers. Over time, this can save a lot of money, especially for big teams.  

For example, if a company uses AI to summarize documents for thousands of employees, it can move some of that work to local devices. This reduces cloud usage without losing any features.  

Limitations of Local AI 

This shift doesn’t mean the cloud is no longer needed. Some tasks still require large models and extensive data processing. Complex reasoning, analyzing large data sets, and working together on AI projects often still rely on the cloud.  

Local AI also depends on the device’s hardware. Older computers might not support the newest features, which can create differences between users. This can make IT management harder for businesses.  

Apple solves this by using a hybrid approach. Simple tasks run on the device, but more complex jobs can still use the cloud when needed.  

Developer Implications 

Apple’s move away from the cloud changes how developers design apps. Instead of always depending on cloud access, developers now must plan for tasks to run locally, which alters application architecture. Developers need to optimize models for compact size and efficient on-device performance. It also requires balancing accuracy with available resources. Apple’s frameworks streamline this process, but they also introduce new design considerations. Developers must determine which tasks should be processed on the device and which should be in the cloud.  

Competitive Pressure Across The Industry 

Apple’s strategy is affecting the wider tech industry. Other companies are also looking for ways to rely less on the cloud. They’re adding AI accelerators to hardware and improving software performance on local devices.  

This shift is part of a bigger trend. As AI becomes more widespread, companies are increasingly focused on efficiency and cost control. Using only the cloud is no longer the standard approach.  

Companies that switch to this model can provide faster, more private, and more affordable solutions.  

Enterprise Strategy Adjustments 

For businesses, Apple’s move away from the cloud means IT strategies need to be reviewed. The abilities of each device now matter more when deciding how to use AI.  

Companies need to check if their employees’ devices are ready for AI. Buying devices that can handle AI is now part of planning their tech infrastructure.  

At the same time, IT teams must balance the use of local and cloud resources. A hybrid setup gives flexibility, keeps costs down, and maintains good performance.  

Apple’s macOS AI push signals a quiet shift away from the cloud over time. 

Apple’s move away from the cloud is happening slowly, not all at once. Cloud services are still important, but their role is changing.  

Local AI will handle routine tasks while the cloud supports more complex operations. This balance improves efficiency and reduces unnecessary data movement.  

Aligning infrastructure with Apple’s hybrid model offers clear benefits in cost, speed, and user trust. As local AI handles routine tasks and the cloud supports complex ones, businesses will gain efficiency and privacy. This gradual shift is shaping how AI works across devices. 

Source: Apple Newsroom 

Intel AI PCs with Core Ultra processors and vPro security are accelerating hardware upgrades in businesses. Now, 87% of companies are upgrading or planning to, driven by the need for higher productivity, advanced security, and the impending end of Windows 10 support in 2025. Upgrades now aim to equip organizations with AI-capable devices for a competitive edge.  

Key Drivers for Enterprise Upgrades: 

  • Performance and productivity: AI PCs with Intel Core processors offer on-device AI that is more than twice as fast as older systems for tasks like content creation. For 46% of companies, built-in AI is now the main reason for upgrading PCs.  
  • Windows 10 support is ending in 2025. So many companies are using this as an opportunity to move straight to AI-ready machines rather than a standard upgrade.  
  • Security and fewer on-site visits: Intel vPro platforms with AI features can cut on-site repairs by up to 90% and deliver a strong 213% return on investment in over three years  
  • On-device AI lets companies process data locally, improving privacy and reducing delays compared to cloud-based AI.  
  • Organizations are accelerating upgrades to future-proof operations and remain competitive, viewing AI pieces as a critical step for employee efficiency and ongoing innovation.  

Impact on Enterprise IT Strategy 

  • Nearly half of businesses now see on-device AI as the most important factor when choosing new PCs  
  • IT teams are now using Intel-powered AI to predict and prevent problems rather than just react, thanks to device insights.  
  • About 75% of IT leaders say that access to AI PCs will prompt them to upgrade their technology sooner.  

The AI PC market is growing quickly. Canalys reports that 19% of PCs shipped in 2024 had dedicated low-power chips (NPUs), and this is expected to jump to 60% by 2027, with businesses leading the way.  

To stay competitive in an AI-driven world, businesses are proactively upgrading to the right technology now, recognizing the urgency given that Windows 10 support ends soon.  

The Revolutionary Impact Of AI PCs 

AI PCs represent a transformative leap in enterprise computing, making them central to ongoing business innovation rather than just standard device upgrades.   

These PCs offer lower latency and faster response times because they process large amounts of data locally. They also use AI to adapt to each user, customizing workflows, apps, and experiences. By automating repetitive tasks and streamlining workflows, they can save companies significant money.  

Because of these features, more businesses see AI PCs as a game-changer for enterprise computing. This is a sea change, says Tom Pieser, large enterprise sales strategy specialist at Intel. AI PCs are poised to redefine how businesses operate, much as Windows and wireless technology did in their respective eras. They are not just tools. They are catalysts of a new era of productivity and innovation.  

Use Cases for AI PCs 

New use cases for AI PCs show their potential to boost teamwork, productivity, security, and content creation. These benefits help both IT teams and everyday users.  

For IT teams, a key use is fleet management. Intel-powered AI provides insights into device status and history, enabling informed maintenance and sustainable practices. This anticipates and prevents issues.  

For users, working on a PC becomes much better. AI can remove backgrounds, suppress noise, add live captions, and transcribe meetings, making virtual conferences smoother and helping document what happens. These features help organizations work more efficiently and accomplish more.  

Selecting the Right Technology 

As companies upgrade their PCs, picking the right technology is key. Choosing Intel-powered hardware offers several important advantages:  

  • Processing power: Intel Core Ultra delivers next-generation performance by combining powerful GPUs, energy-efficient NPUs, and fast CPUs. This means great performance without sacrificing battery life, as battery tests use real-world scenarios rather than unrealistic benchmarks.  
  • Intel’s integrated NPU and improved GPU now handle more AI tasks, letting different components work optimally. This boosts overall system efficiency and employee productivity.  
  • Fleet management. Intel vPro offers 18 years of trusted security, easy management, and productivity. This platform gives strong protection and stability for both IT teams and users.  
  • Software ecosystem: with over 45 years of innovation, the Intel software ecosystem works well with new AI operating system apps and developer tools. Intel partners with over 100 software vendors and on more than 400 features, aiming to help companies of all sizes innovate.  

With many new AI apps available and more on the way, using Intel technology enables businesses to modernize rapidly, maximize AI investments, and outpace competitors.  

Discover more about Intel’s leadership in AI PC technology by downloading our new interactive e-book. Get actionable insights and examples to guide your business’s next technology upgrades.

Source: The future of work: AI PCs with Intel at the core 

Many developers thought that as managed AI platforms like Amazon Bedrock matured, pricing would get easier to predict. Instead, costs have become harder to estimate. The Bedrock model expansion now offers more models, pricing tiers, and usage patterns, making financial planning even more complex for experienced cloud teams.  

With the bedrock model expansion, cloud costs are harder to predict because pricing is no longer based on just one usage pattern. Now, organizations pick from several foundation models, each with its own cost structure. Every model has different prices for input tokens, output tokens, and extra features. This shift marks a new challenge in financial planning.  

This flexibility lets teams choose the best model for each task, but it also makes cost tracking more fragmented. Finance teams can’t rely on a single baseline for monthly spending anymore.  

Model Diversity Introduces Pricing Variability 

The platform now offers models from several providers, each designed for different types of work. Some models are built for speed, while others focus on deeper reasoning or handling multiple types of data. These differences directly affect the cost of each request.  

Switching models on the fly can quickly change cost patterns, making forecasting at scale tough.  

Trying higher quality outputs can double inference costs in days without teams realizing it.  

Usage Patterns Are No Longer Linear 

Traditional cloud services usually scale in predictable ways, where increased usage results in higher costs in a straight line. The Bedrock model expansion changes this by adding pricing that doesn’t always follow a simple pattern. Some models charge extra for longer context windows or more complex reasoning. Others have different rates depending on how fast or how much data you process. This means two similar workloads can end up with very different bills.  

A chatbot that handles simple questions might stay cheap, but if you upgrade it to handle more advanced reasoning, the cost can increase significantly. Often, you don’t notice the change until you see the bill.  

Token Economics Become Harder to Track 

Token-based pricing remains, but each model applies it differently, which adds complexity. Tracking now involves not just counting total tokens. Engineering teams must break down the number of input tokens, output tokens, and context window size for each model. If prompt length or output depth shifts unnoticed, increases can lead to cost overruns, as token distributions vary by use case and model selection.  

For instance, a content generation tool that lengthens prompts to improve quality will use more tokens per request. Tracking must account for this, since millions of such requests can significantly impact overall cost, even if each change seems minor.  

Hidden Costs and Advanced Features 

The Bedrock model expansion also introduces advanced features such as tool use, retrieval augmentation, and multimodal processing. These add value, but they also entail additional costs.  

For example, retrieval-based workflows may require access to external data and additional processing, which can introduce delays and consume more computing power. In the same way, multimodal inputs need more resources than just text.  

These costs are often hidden. Teams might focus on model pricing but miss the additional infrastructure needed for these features. This can lead to a gap between what they expect to spend and what they actually pay.  

At an enterprise level, even minor inefficiencies can become serious concerns as high-volume applications magnify small cost changes.  

A recommendation engine that handles millions of requests each day can see its costs change significantly just by switching models. If different teams in the company use different models, things get even more complicated.  

This segmentation makes it hard to control costs without a central team watching over spending. Costs can rise without anyone noticing who is responsible.  

Operational Challenges for Finance and Engineering 

The bedrock model expansion means finance and engineering teams have to work more closely together. Managing costs isn’t just a financial job anymore. It also needs a technical understanding of how the models work.  

Finance teams need to see how models are being used. Engineering teams need to know how their choices affect costs. If these teams aren’t on the same page, the company could end up overspending on AI projects.  

Many companies are now setting up internal dashboards to track model usage in real time. These tools help stop what’s driving costs before small problems turn into bigger ones.  

Strategies to Regain Cost Predictability 

Organizations are using several methods to address the uncertainty arising from the expansion of the bedrock model. These strategies focus on making costs more visible, keeping control, and optimizing usage.  

First, teams strive to standardize which models they use. Using fewer models reduces cost variability and makes cost predictions easier. Second, they set usage limits to avoid unexpected spikes.  

Third, teams focus on making prompts shorter and more efficient, reducing token use without lowering quality. Finally, companies test models thoroughly before rolling them out widely.  

These steps don’t remove all unpredictability, but they help lessen its effects.  

The Role Of FinOps In AI Workloads. 

Financial operations, or FinOps, are now key to managing AI costs. It connects technical choices with financial results.  

FinOps teams analyze usage data, identify inefficiencies, and propose cost-saving measures. They also try to negotiate better pricing with cloud providers when they can.  

With the Mac Bedrock and model expansion, FinOps brings needed structure. It makes sure that cost is considered throughout development, not just at the end.  

Bedrock Model Experiment Makes Cloud Costs Harder to Predict Over Time 

As companies increase AI adoption, the expansion of the bedrock model will keep cloud costs unpredictable, with each new model bringing its own pricing challenges.  

Cost management cannot be a one-time effort. Companies need ongoing vigilance and adoption as pricing and models continue to shift.  

Success will favor companies that combine technical advances with disciplined cost insight. A sharp financial focus is now a competitive advantage as pricing continues to evolve. 

Source: Amazon Bedrock 

As technology rapidly evolves, two things stand out: organizations are seeing real results from AI, and the possibilities for innovation are endless. Our goal is to help you, whether you’re a developer, IT professional, AI engineer, business decision-maker, or data expert, use AI to move your business forward. With Microsoft’s experience, strong capabilities, and commitment to trustworthy technology, Azure brings everything together to support your AI goals and help you shape the future.  

This week, we are sharing updates and new features that highlight our commitment to your success in this fast-changing time. Let’s get started.  

Introducing Microsoft Azure AI Foundry: A Single Platform To Design, Customize, And Manage AI Solutions. 

Each new wave of applications brings new needs. Just as web, mobile, and cloud technologies led to new platforms, AI is now changing how we build, run, and manage applications. A Deloitte report found that nearly 70% of organizations have moved only 30% or fewer of their generative AI experiments into production. So there is still a lot of untapped potential. Business leaders want to bring AI solutions to market faster and more affordably while tracking their performance and return on investment.  

That’s why we are excited to introduce Azure AI Foundry, a unified platform for your whole organization in this new era of AI. Azure AI Foundry connects the latest AI technologies with real business needs, helping organizations use AI more efficiently and effectively.  

We’re bringing together the AI toolchain in the new Azure AI Foundry SDK, making Azure AI features available in familiar tools like GitHub, Visual Studio, and Copilot Studio. We’re also updating Azure AI Studio to serve as an enterprise-level management console and portal for Azure AI Foundry.  

Azure AI Foundry is built to help everyone in your organization, developers, AI engineers, and IT professionals customize, host, run, and manage AI solutions more easily and confidently. This unified approach simplifies development and management, allowing everyone to focus on innovation and achieving strategic goals.  

For developers, Azure AI Foundry offers a smoother way to use the latest AI advancements and focus on building valuable applications. Developers also get an improved experience with access to all current Azure AI services, tools, and the new features we’re announcing today.  

For IT professionals and business leaders, using AI brings up important questions about how to measure results, ROI, and ongoing improvements. There’s a real need for tools that give clear insights into AI projects and their business impact. Azure AI Center helps leaders track effectiveness, align projects with company goals, and invest in AI with more confidence.  

To help you grow AI adoption in your organization, they’re offering detailed guidance for AI adoption and architecture through Azure Essentials. This resource brings together Microsoft’s best practices, product experiences, reference architectures, training, and resources in one place. It’s a great way to learn from our experience and see how to get the most out of Azure AI Foundry.  

With so many different technologies and options available, we built Azure AI Foundry to meet a wide range of needs as organizations pursue AI transformation. It’s not just about offering advanced tools; we have those as well. It’s also about encouraging collaboration and alignment between technical teams and business strategy.  

Now, let’s look at more updates aimed at improving your experience and efficiency throughout the AI development process, whatever your role may be.  

Introducing Azure AI Agent Service: A Tool to Automate Business Processes and Help You Focus on Your Most Important Work 

AI agents can handle routine tasks independently, boosting productivity and efficiency while keeping you involved. With the Azure AI Agents service, developers can organize, deploy, and scale enterprise AI-powered apps to automate business processes. These smart agents handle tasks on their own, but bring in people for final review or action, so your team can focus on the most important projects.  

One key feature of Agent Service is its ease of connecting to enterprise data sources such as Microsoft SharePoint and Microsoft Fabric, as well as its integration with tools to automate actions. With options like bring-your-own storage (BYOS) and private networking, it keeps data private and compliant, helping organizations protect sensitive information. This lets your business leverage existing data and systems to build secure, powerful agent workflows.

Source:  Introducing Azure AI Agent Service to automate business processes and help you focus on your most strategic work  

As AI moved from experimental projects to large-scale production in 2026, Google Cloud’s costs have come under closer review. American companies are adding complex machine learning to their main operations, and the costs of using specialized platforms are changing. These changes often appear in areas such as API calls, storage, and hardware setup. As a result, technical leads are finding that the pricing models they used during pilot projects no longer match the costs of running AI at scale, putting new pressure on enterprise budgets.  

The Evolution of Token Economics in 2026 

The move to multimodal models has changed how Google sets prices for AI services. In the past, billing was mostly based on text token counts, but now video and audio processing have added new, less predictable costs. This shift makes it harder for procurement teams to estimate monthly spending as accurately as before. As a result, many companies are finding their costs are much higher than they expected.  

Google has also added new reasoning tiers, which make billing more complicated. Basic tasks are still affordable, but more advanced logic that needs data processing costs much more. This system means users pay for the level they choose, they use, but it also means developers have to choose models more carefully. For companies handling millions of automated tasks, picking the wrong tier, even for a small part of their workload, can quickly strain their budgets.  

Infrastructure Costs and the GPU Premium 

The hardware needed to run Vertex AI has also become more expensive. Google’s newest Tensor Processing Units are faster, but the fees to reserve these high-performance clusters have increased as demand rises. Companies that use on-demand capacity instead of long-term reservations are especially affected by these price jumps. This reliance on specific hardware is a key reason why Vertex AI pricing changes are putting extra pressure on tech budgets.  

  • Preemptible capacity: Though these lower-cost instances are less available, so many startups have had to switch to more expensive guaranteed options.  
  • High memory nodes: The need for larger context windows has driven demand for specialized RAM-heavy instances, which carry a 20% premium over standard nodes.  
  • Networking Overlays: Moving data between Vertex AI and external storage now incurs higher interzone transfer fees, which were previously subsidized.  
  • Provisioned throughput: to guarantee minimum performance for customer apps. Companies now pay a monthly fee even if they do not use the full capacity.  

The Impact of Data Management and Storage Fees 

Much of the recent financial strain stems from how data is collected and stored for ongoing model updates. Vertex AI’s managed datasets make training easier, but they add a storage fee that grows as your data grows. As companies gather more feedback to keep their models accurate, the cost of keeping this data available for retraining becomes a big expense. Many teams now find that storing training data can cost as much as the training process itself.  

Managing metadata also adds to the growing complexity of cloud costs. Each experiment, model version, and test creates a record in the Google Cloud metadata store, which is now billed in smaller units. These fees may seem minor, but they add up fast when hundreds of models are tested at once. This extra cost is often overlooked during planning, but surfaces as a major expense in quarterly reviews.  

Strategic Responses to Scaling Challenges 

To address the pressure from vortex AI pricing changes, organizations are shifting to a cost-first approach. They use automated budget guardrails that stop expensive training jobs when they exceed set limits. By limiting these controls in the DevOps process, teams can avoid unexpected costs that often arise during large-scale model tuning. This careful approach is now essential for any company aiming for a sustainable AI strategy.  

Many American companies are also turning to model distillation to save costs. They use a powerful, expensive model to train a smaller, cheaper student model for specific jobs, cutting insurance costs by more than 70%. This way, they keep high performance by using less expensive hardware. The most costly resources are then saved for only the toughest tasks.  

Implementing FinOps for Machine Learning 

MLOps now includes FinOps, a role focused on both cloud engineering and financial responsibility. FinOps specialists use dashboards to track the return on investment for each model, ensuring the business value exceeds the infrastructure costs. They also negotiated committed use discounts, which can cut TPU and GPU prices by up to 40%. Without this oversight, hidden scaling costs can quickly cancel out the expected efficiency gains.  

Preparing for the Future of Cloud Intelligence 

Looking ahead to 2027, the main focus in cloud computing is moving from raw power to economic efficiency. Google is likely to launch more automated tools that recommend cheaper model options in real time. Still, it is up to each company to build systems that consider costs from the start. Companies that do not adjust to these new billing models will fall behind more efficient competitors.  

The fact that Vertex AI’s pricing quietly increases enterprise costs is an important reminder that cloud intelligence is a paid service, not a free one. Succeeding in 2026 means balancing technical goals with financial discipline. By focusing on model optimization, long-term resource planning, and strong FinOps practices, US companies can keep using Vertex AI without risking their budgets. The time of growth at any cost is over, replaced by a new focus on smart, sustainable scaling that values both results and the bottom line.  

In summary, changes in Vertex AI pricing show that the machine learning industry is maturing. While it is getting cheaper to start, scaling up to enterprise-level performance is becoming more complicated and costly. Companies need to stay alert, regularly check their cloud usage, and adjust their systems to keep up with these changes. The most successful AI companies will be those that understand the total cost of ownership for every token they produce. By viewing infrastructure as a strategic tool rather than just a fixed cost, American businesses can remain competitive in the digital economy. 

Source: Google Cloud Blog 

GPU costs usually don’t jump all at once. Instead, they rise slowly, a few extra milliseconds here, a slightly bigger batch there, and before you know it, inference costs are doubled without any clear code changes.  

This is where the latest NVIDIA Tensor RT update becomes important. It doesn’t add a flashy new feature; instead, it reduces inefficiencies that most teams never notice.  

The Hidden Cost of GPU Idle Cycles. 

Modern inference pipelines often seem optimized on paper. Models are quantized, batches are adjusted, and latency targets are met. Still, GPUs often remain partly idle during execution.  

Why does this happen? Utilization is not just about the computing power. It also depends on how well workloads match the GPU’s execution patterns.  

The recent TensorRT update tackles this mismatch head-on. It improves kernel scheduling and execution overlap, enabling multiple operations to run more efficiently within the same inference cycle. While the improvement per request is usually 5-15%, these gains quickly add up at scale.  

Then there’s a real-world scenario:  

  • A recommendation engine serving 15 million daily entrances.  
  • Average latency: 40 ms.  
  • GPU utilization: 65%.  

A 10% boost in efficiency not only lowers latency but also increases throughput without needing more hardware. In a mid-size deployment, this is like getting several GPUs back.  

Smarter Memory Management, Less Waste 

Fragmentation has been a lame cost in GPU workloads for a long time. When models allocate buffers dynamically, they often leave unused gaps that still take up valuable VRAM.  

The updated TensorRT uses more aggressive memory reuse strategies. Buffers are backed up more tightly, and allocation patterns now adapt to runtime behavior rather than relying on fixed assumptions.  

This is especially important for teams running multiple models on shared infrastructure. Because of these limitations, each model consumes more memory than it actually uses, limiting the number of workloads that can run simultaneously.  

With improved memory handling, more modules fit into a single GPU. Context switching becomes cheaper, and out-of-memory errors drop significantly.  

Some companies are running multi-tenant inference systems. This change alone can put off the need for new hardware by several months.  

Precision Tuning Moves Beyond INT8 

Quantization is done earlier. INT8 has long been the standard for shrinking model size and speeding up inference. However, it comes with trade-offs, especially for models that are sensitive to precision loss.  

The TensorRT update includes support for mixed-precision execution. Rather than applying precision to all layers, it now applies it only where it provides the greatest benefit.  

In practice, this means critical layers retain higher precision, less important computations drop to lower precision, and accuracy remains stable while performance improves.  

For example, a computer vision pipeline can maintain its detection accuracy while reducing inference time by 20-25%. In the past, teams had to pick between speed and quality, but now that trade-off is less severe.  

Dynamic Shapes Without Performance Penalties 

Many production systems deal with variable input sizes, such as text sequences, image resolutions, or user-generated data. Supporting dynamic shapes often adds overhead because engines have to reconfigure execution paths as they run.  

The latest TensorRT update reduces that overhead. It pre-optimizes multiple execution paths and switches between them more efficiently during runtime.  

The impact shows up in cases:  

  • Chat applications process unpredictable input lengths.  
  • Video pipelines handling mixed resolutions.  
  • Search systems with variable query complexity.  

Latency becomes more consistent. Even more importantly, the worst-case performance gets better, which is what users tend to notice most.  

Why Most People Miss These Gains. 

These improvements are subtle. There is no simple switch labeled “reduce GPU waste.” Teams have to recompile engines, review configurations, and benchmark workloads to notice the benefits.  

That’s where the gap emerges.   

Engineering teams often see inference optimization as a one-time task. After they meet latency targets, their focus moves on, but the tools underneath keep improving, so new performance gains are often missed.  

A typical pattern looks like this:  

  • Initial deployment optimized for baseline performance.  
  • Minimum revisiting of inference configurations.  
  • Gradual cost increase as usage scales  

Teams that break this pattern will benefit from the TensorRT update.  

Operational Impact on AI-Driven Businesses 

For organizations running large-scale inference, such as recommendation systems, fraud detection, or generative AI APIs, the financial impact is clear.  

Lower GPU waste translates into reduced cloud spend, higher throughput, for instance, and improved margins on AI-driven products.  

For example, a SaaS company that charges per API call can either raise its profit margins or lower prices to win more market share. Both choices help the company compete better.  

There is also a strategic benefit. With more efficient infrastructure, teams can experiment faster. They can deploy more models, try more variations, and iterate without running into cost limits as quickly.  

What to Audit Right Now 

Executives and engineering leaders don’t need a full overhaul to benefit. Targeted audits can reveal immediate opportunities:  

  • Engine rebuilds: recompile models using the latest TensorRT version. Older engines won’t inherit new optimizations.  
  • Utilization metrics: chart track GPU utilization beyond averages. Look for idle gaps during inference cycles.  
  • Memory footprint: measure actual versus allocated VRAM usage across workloads.  
  • Precision settings: re-evaluate mixed-precision configurations for critical models.  

You don’t need new hardware for this. You just need to pay attention.  

A Quiet Shift with Measurable Consequences. 

Infrastructure efficiency rarely makes the news, but it affects the economics of AI more than model benchmarks ever could.  

The latest TensorRT update doesn’t change what models are capable of, but it does improve their efficiency.n. The difference is important.  

Teams that review their inference stack will discover extra capacity they didn’t realize was there. Others may keep adding hardware to fix problems that have already been solved.  

Over time, this difference will be reflected in profit margins, pricing power, and the speed at which teams can innovate. It doesn’t happen overnight. It builds up slowly, then suddenly becomes obvious. 

Source: From Rainforests to Recycling Plants: 5 Ways NVIDIA AI Is Protecting the Planet 

At first, developers didn’t notice anything had changed. The builds looked the same until their usage increased. Then their numbers started to shift in ways they didn’t expect.  

The Subtle Redesign of Pricing Logic 

In the past, API pricing was simple. You paid a fixed rate for input tokens and output tokens. It was predictable and easy to plan for. GPT-4 Turbo makes things more complex, helping some types of workloads while making others more expensive.  

The new model rewards context efficiency and shorter responses. Developers who make their prompts concise and avoid repeating information will see much lower costs. On the other hand, those who use long instructions or keep a lot of conversation history will pay more than before, even if the token rates seem lower at first glance.  

This change is intentional. It encourages developers to adjust their API usage.  

Why Context Is Now the Cost Driver 

With GPT-5 Turbo, the context window is much larger. That’s the main feature people notice. However, the real impact is how this affects costs.  

A larger context window doesn’t just mean more tokens. It also changes how the model processes and prioritizes information. GPT-5 Turbo gives more importance to recent tokens and less to earlier ones. If you repeat information, you still pay for those tokens, but they don’t help the output as much.  

Consider two hypothetical applications:  

  • A customer support chatbot that carries a full conversation history across 20 turns.  
  • A financial analysis tool that injects only the latest structured data per request.  

Both make use of the same number of tokens. The first gives extra context while the second keeps things simple. Over time, the cost difference grows, sometimes by 30-40%.  

That gap didn’t exist in earlier models at this scale.  

Output Efficiency Becomes a Competitive Edge 

There’s also a change in how output tokens are valued compared to input tokens.  

GPT-5 favors shorter outputs. The model now uses fewer trigger words and repeats itself less, which might result in fewer words and lower token counts. This shift also means developers need to rethink how they design their applications.  

Long-winded outputs, which used to be acceptable, now increase costs without providing extra value.   

Consider content generation platforms. In the past, longer outputs were often seen as a selling point. Now, being too wordy directly impacts profit margins. Companies that don’t adjust output length will see their profits shrink as usage increases.  

This adds a new area for optimization:  

  • Quantum engineering for precision.  
  • Output constraints for brevity.  
  • Structured responses instead of free-form text  

Now being disciplined, waking up is more cost-effective.  

Latency Tiers and Hidden Trade-offs 

GPT-5 Turbo also brings in different latency levels, even if they aren’t always clearly advertised. Getting faster responses usually means higher hidden costs because of how resources are managed.  

This is important for businesses running real-time applications like trading platforms, customer service portals, or live analytics.  

A CTO looking at API usage now has to juggle three factors: response speed, token efficiency, and cost per request.  

It’s no longer easy to optimize the ad ranks. Some products are now unavailable.  

For example, lowering latency might mean using shorter prompts and limiting outputs, which can affect quality. On the other hand, keeping responses detailed and high quality will increase both latency and cost.  

The new pricing model makes these increases unavoidable.  

Implications for SaaS Business Models 

These changes affect more than just engineering teams. SaaS companies relying on AI APIs now have to rethink their cost structures.  

In the past, many products assumed that costs would keep falling as models improved. GPT-4 Turbo changes this by linking cost efficiency to how the model is used, not just how good it is. This has several consequences:  

  • Freemium models become riskier. Unoptimized user behavior can drive disproportionate costs.  
  • Usage-based pricing is becoming more popular, while flat-rate subscriptions struggle to handle cost savings.  
  • Internal tools. Companies are investing more in internal tools because they now need systems to track and optimize tokens in real time. A business deploying AI for customer engagement may not notice the shift immediately. A platform serving millions of requests per day will  

The Rise Of Prompt Engineering as Cost Control. 

Content marketing is no longer just a creative task. It is now a financial discipline.  

Teams now review grants the same way they review cloud infrastructure. Extra instructions, too much polite language, and unnecessary context all add up to real cost inefficiencies.  

A simple example illustrates this point:  

Prompt A: Please analyze the following data and provide a detailed explanation of the results in a clear and concise manner.  

Prompt B: analyze data, return key findings  

Both prompts give similar results with GPT-5 Turbo, but prompt A always costs more.  

When you multiply that by millions of workers, the financial impact is significant.  

Organizations are starting to standardize fonts, build internal libraries, and set clear usage rules. This marks a move toward more disciplined operations.  

Strategic Positioning by OpenAI 

This change in pricing shows a clear intention. OpenAI is not just offering a more expensive model; it’s also shaping how people use it.  

By rewarding efficiency and discouraging waste, GPT-4 Turbo aligns how developers work with the real costs of running large AI systems. Leaner usage helps reduce strain and keeps performance steady.  

It also gives efficient companies a competitive edge. Those who master these efficiencies get cost advantages that are hard for others to match quickly.  

In short, pricing now shapes how the whole ecosystem behaves.  

What executives should watch 

For executives, these changes affect more than just technical methods. They are costs, market shape, product design, pricing strategies, and the customer experience.  

Key areas to monitor:  

  • Cost per user interaction. Track how it evolves with scale.  
  • Run efficiency methods: Measure performance for a successful outcome.  
  • Output length trends: Identify necessary, unnecessary verbosity.  
  • Revenue cost balance: Align with business priorities  

If you ignore these factors, your profit margins position the business, and your revenue is going.  

A Quiet Shift with Long-Term Impact 

GPT-4′s perverse impact isn’t immediately obvious. It does not bring chaos or a sudden increase. Instead, it quietly changes the rules behind the scenes.  

Developers who adjust will stand out and deliver faster, cleaner results. Those who don’t will see their costs rise and their breakup hard to stop.  

This is how infrastructure changes usually happen, not with a sudden shift, but through a slow reevaluation of one’s position over time. Companies that adapt will lead, while others rush to keep up. 

Source: OpenAi Blog 

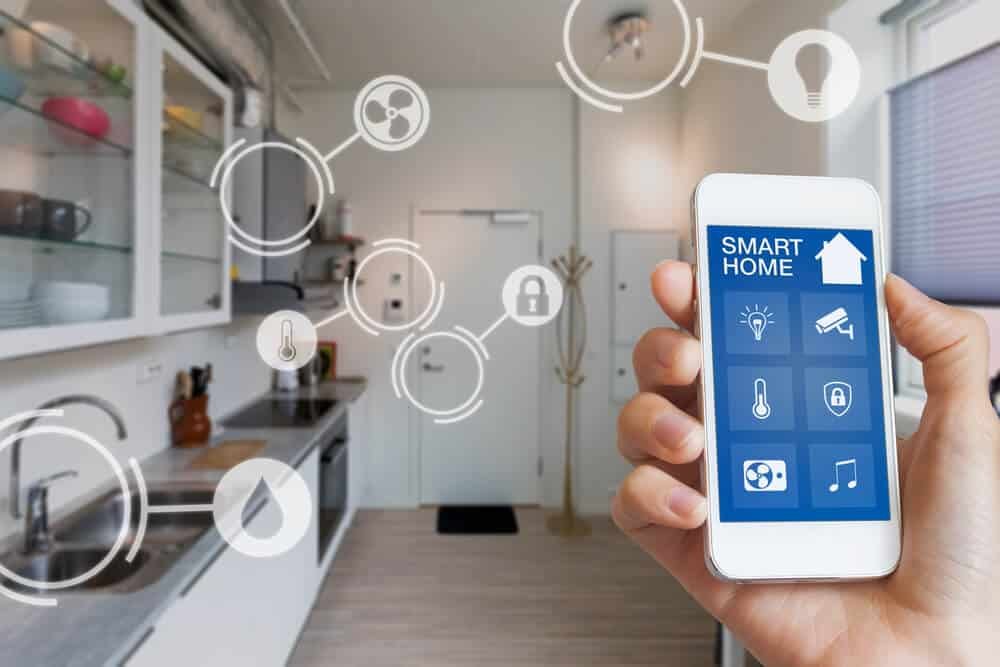
For many years, smart homes were thought to be the “next big thing” – homes that learn about how you live, can adapt to you, and are able to anticipate what you might need. From voice assistants to predictive thermostats, AI-enabled devices and self-scheduling routines promise a level of convenience unlike anything else. But as we move closer to 2026, we are seeing very different behaviour from users: they are actually turning off the AI features that were once considered the hallmark of a smart home! 

This is not to say users are abandoning the purchase of smart devices; it is to say there is greater concern about how users’ private data is collected, processed, and used by smart devices. What was originally considered “smart” has now been redefined as “intrusive!” 

Privacy Concerns Are Causing Users to Opt Out 

The issue at the heart of this is not functionality, but rather that users are losing visibility and control over their private data. Consumers are becoming aware that AI-enabled smart device products rely on continuous collection of user data (voice recordings, device usage patterns, and geolocation tracking), which is raising alarm about the scale of the data being collected. 

Below are some common issues that are contributing to this shift for users: 

  • Always-on listening: Smart speakers and smart assistants are perceived by users to always be “listening” to conversations, even when manufacturers say they are not. 
  • The ambiguity of data storage: Users often do not know where or for how long their data is stored, or who has access to it. 
  • The risk of third-party sharing of data: Smart device type products are, in most cases, integrated with many other third-party applications and/or services, which puts users at an increased risk of their data being shared without their knowledge or consent. 

The Rise of Feature Opt-Out Trends 

Trends are shifting toward consumers opting out of features. 

One difference between opting out as a trend and just being disappointed is that people opt out daily rather than passively accept their disappointment. 

Some examples of the features being opted out of by users are: 

  • Logging and storing voice recordings 
  • Personalized automation routines 
  • Recognizing a face with smart cameras 
  • Triggering with location-based triggers 
  • AI recommendations that are driven by automation 

Younger, tech-savvy users are the ones who primarily use this trend to opt out, as they tend to be more aware of digital privacy. Ironically, the people who propelled smart home adoption are now also driving pushback. 

The trend right now is that, instead of totally abandoning the devices, users are “downgrading” them to use them in manual mode or without all their capabilities. For example, a smart speaker may be used only as a Bluetooth speaker rather than as a smart speaker. A smart TV may be used only as a non-personalized TV, not as a smart TV with personalized suggestions. 

Trust vs. Convenience: The Core Conflict 

This fundamental shift in trends represents a basic trade-off between convenience (AI features) and control (of personal data). AI features (i.e., smarter products/feature use) are designed to reduce the friction between automation and routine. In addition, automation and routine provide users with greater convenience. The more data a user shares with AI and automation, the better the outcome will be; therefore, the more data the AI and automation have about the customer, the better the automated product and routine will perform. 

However, consumers are now beginning to question whether the convenience of the product is worth the cost (of sharing their personal data) 

Is it worth sharing your voice data for quicker command recognition? 

Is it worth revealing to the system what it means to automate an everyday task without personal data? 

Vendor Response on Rebuilding Trust for AI Ecosystems 

Both Amazon and Google recognize this shift toward greater privacy interest and have taken steps to address some concerns. 

Here are some key examples of their response: 

1. Increased Transparency – Companies are launching new dashboards that enable users to view and manage their data more clearly; for example, how to collect, what to use, and how to delete. 

2. On-Device Processing – As some AI functionalities are redesigned for on-device use rather than sending all the data to the cloud, this will lead to less data being exposed and thus increase privacy. 

3. Granular Controls – Users will now have greater flexibility to choose which privacy settings identify and deactivate certain features instead of simply accepting “all or nothing”. 

4. Shorter Data Retention Policies – Automatic deletion of voice audio recordings and activity logs will soon be commonplace. 

5. Privacy-Centric Marketing – Companies are shifting their marketing messages from “smart and seamless” to “secure and private”, indicating a shift in priorities. 

Although the above steps are an example of establishing trust within an AI ecosystem, the pace at which trust is being rebuilt has been much slower than that at which it was lost! 

Trust Resetting in AI: A Larger Picture 

Looking back at the opt-out activity indicates that there’s something much larger than just smart homes. There is a general recalibration of the user’s engagement with AI technology. 

Users are becoming active participants in the AI ecosystem; they are questioning, customizing, and indeed rejecting AI-based features that don’t align with their personal standards. 

This trend does not mean that AI is failing, but rather that it is changing perceptions. 

Going forward, the next major phase of the smart homes growth and innovation cycle will be defined not by the total amount AI can accomplish, but by how effectively it operates. 

Conclusion: Smart Homes Need Smarter Trust Models 

Smart home technology isn’t disappearing—but blind adoption is. Users are becoming more intentional, more cautious, and more selective. 

For companies, the message is clear: 

Trust is no longer a byproduct of innovation—it is a prerequisite. 

The brands that succeed will not be the ones with the most advanced AI, but the ones that make users feel safest using it. 

Source: Amazon Alexa, Google Home top privacy risks in smart home devices: Study