Last week, Apple released the first iOS 16.4 beta, which included a bunch of new features and changes to Apple’s mobile software. Included was the news that Apple had started testing encrypted RCS messaging, but only between iPhones. Now, with the release of iOS 16.4 beta 2, that’s changed.  

At the time, I hoped Apple would soon test encryption for RCS messages between iPhones and Androids. I did not expect this to happen quickly, but I am glad it has.  

iPhone beta testers must have the latest iOS 16.4 beta installed to participate in cross-platform testing. Android users will need to have the latest version of Google Messages.  

Apple has affirmed that this feature will be in testing for a while. It will not ship the final version of iOS 26.4 and is not available for all devices and carriers. You have to be one of the few beta testers to send encrypted messages to your Android-using friends.  

Apple has previously confirmed that RCS won’t change the green bubble situation, so Android users will remain green regardless of encryption status, while iMessages are displayed in blue. However, testers will see a lock icon on all encrypted messages, indicating the security of their conversations.  

That change applies to our CS and iMessage, so there is absolutely no confusion. No lock means your messages are about as secure as an open gate.  

The benefit of RCS messaging between iPhone and Android is that all cross-platform issues are gone. Larger file-sharing limits mean photos and videos are not heavily compressed, and users get modern features like real-time typing indicators and reaction emojis.  

Soon, everyone will benefit from end-to-end encryption, which secures messages from anyone trying to intercept them. We do not know when it will be available to all. Apple has only said it will arrive in future releases of iOS, iPadOS, macOS, and watchOS 26.  

Ultimately, we will have to wait until Apple confirms everything works as intended.

Source: iOS 26.4 beta 2 now lets iPhones send encrypted RCS messages to Android — here’s how it works 

Meta engineers have launched KernelAgent, a multi-agent system that automates the creation and tuning of GPU kernels for AI workloads. This open-source tool, available in the Meta-pyTorch/KernelAgent GitHub repository, uses large language models and a hardware-guided feedback loop to generate fast, verifiable Triton kernels from PyTorch programs.  

Key Features 

  • Multi-agent system: KernelAgent splits the complex task of kernel optimization into dedicated roles. ProfilerAgent monitors and collects hardware performance data; JudgeAgent analyzes requests to identify areas for improvement; and the Optimization manager coordinates the workflow and decides which optimizations to pursue. These agents work together in cycles.  
  • Hardware-guided optimization: Instead of relying on static models like traditional compilers, KernelAgent bases its choices on real hardware performance data, including compute usage and memory bandwidth, gathered with NVIDIA Nsight Compute (NCU).  
  • Ongoing feedback loop: The system uses a closed-loop workflow.  
  1. Profiling: The system collects hardware metrics when it runs the kernel for the first time  
  1. Diagnosis: A powerful language model reviews the data to find performance bottlenecks.  
  1. Optimization: another large language model creates an improved kernel based on these suggestions.  
  1. Verification & Benchmarking: The system tests the new kernel to ensure it is accurate and performs well.  
  1. Iteration: The process repeats, and agents learn from previous successes and failures saved in shared memory.  
  • The Optimization Manager explores several optimization paths in parallel, keeping only the best-performing kernels.  
  • KernelAgent identifies and fuses parts of PyTorch programs, replacing them with optimized Triton kernels.  

Performance 

On 100 L1 KernelBench tasks, KernelAgent achieved 2.02x speedup over previous kernels and averaged 1.56x faster than the default torch. compile, reaching 89% of hardware efficiency on an H100 GPU.  

Optimizing GPU kernels is becoming more important for today’s AI workloads. As models get bigger and more specialized, performance increasingly depends on kernel efficiency rather than just the algorithms. However, manually tuning kernels requires significant expertise and an in-depth understanding of GPU hardware, memory, and performance trade-offs. The challenge only grows as more channels and kernels are added, and each new GPU architecture requires new optimization strategies.  

In practice, skilled kernel engineers use a step-by-step approach to optimize kernels. They profile kernels with tools such as NVIDIA Nsight Compute and examine hardware performance counters to identify bottlenecks and make targeted improvements.  

They ask questions like:  

  • Is the tiling strategy missing out on memory bandwidth?  
  • Does the kernel need a full redesign rather than just parameter tuning?  

Often, they have to evaluate several kernel designs, each with its own bottleneck, before finding one that fully utilizes the hardware. This process works well, but it usually takes days or even weeks.  

Modern compiler stacks have made big advances in automating kernel generation. For example, Torch.compile captures computation graphs and generates Triton kernels via graph transformations. Pattern matching and compiler rules, as well as other systems like TVM and XLA, employ similar tools to handle many common kernel patterns and deliver good performance from the start. Still, most compiler rules rely on static models rather than real measurements from running or actual hardware.  

KernelAgent seeks to automate this diagnosis-driven optimization process by harnessing real hardware signals to steer Kernel’s tuning of forward-pass (inference) kernels, which directly impact latency and throughput. This system is built on three fundamental principles:  

  • For every hardware decision, both bottleneck identification and optimization selection should be based on precise profiling data.  
  • Adapt multiple optimization tactics concurrently. Given identical hardware data, there may be several viable optimization pathways. KernelAgent evaluates these alternatives in parallel, saving time and synthesizing previous strategies to generate superior algorithms.  
  • Iterate by learning from every round using shared memory. Optimization agents review what succeeded or failed, storing insights collectively to inform future cycles and avoid repeating errors. 

Source: KernelAgent: Hardware-Guided GPU Kernel Optimization via Multi-Agent Orchestration 

The Gemini app provides embedding models that generate embeddings for text, images, video, and other content types. You can use these embeddings for activities such as semantic search, classification, and clustering, which often yield more accurate, context-aware results than keyword searches.  

The newest model, Gemini-Embedding-2-Preview, is the first from Gemini API to handle multiple content types, mapping text, images, video, audio, and documents into one shared embedding space. This enables searching, classification, and clustering across over 100 languages. For more details, check out the Multimodal Embedding section. If you only need text, Gemini-Embedding-001 remains available.  

If your product relies on retrieval, augmented generation (RAG) embeddings are crucial for making these systems more accurate, coherent, and context-aware for teams seeking a managed RAG solution. A file search tool makes RAG management easier and more affordable.  

Google has launched Gemini Embedding 2 for public previews, bringing enhancements over the previous version.  

As Google’s first native multimodal embedding model, Gemini Embedding 2 can map text, images, video, and documents into one shared embedding space. It was released alongside new AI features for Workspace apps.  

If you are new to this, embedding models are different from generative models like Gemini 3. Embedding models help computers understand context by turning text, images, or video into vectors, which are mathematical formats that computers can read and analyze. These embeddings yield more context-aware results across tasks such as semantic search, classification, and clustering than keyword-based methods.  

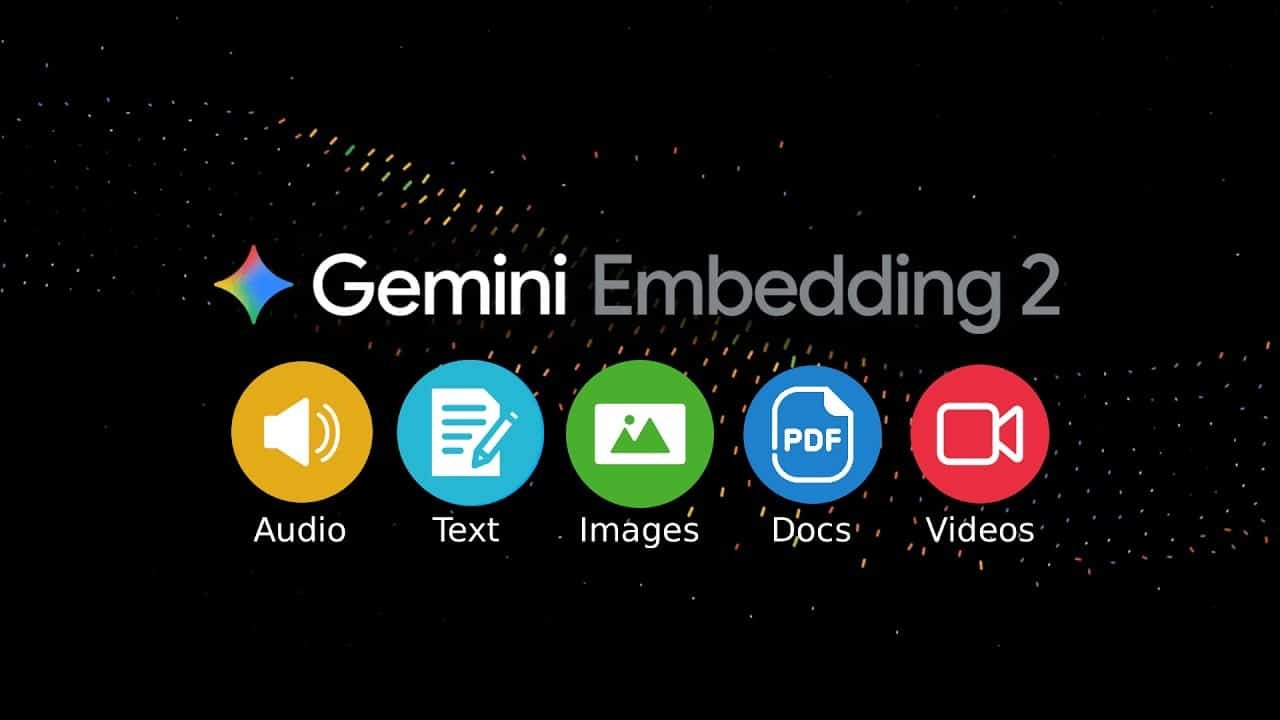
The first Google Embedding model only worked with text. Gemini Embedding 2 now supports text, images, videos, audio, and documents in a single unified embedding space across 100 languages. Below are the content limits:  

  • Text: up to 8192 tokens per request.  
  • Images: up to 6 images per request, supporting PNG and JPEG formats.  
  • Video: up to 120 seconds of video in MP4 or MOV format per request.  
  • Audio: processes and embeds audio data directly without needing transcriptions.  
  • Documents: can be PDFs up to 6 pages long.  

In a blog post, Google said the new model streamlines complex pipelines and enhances a wide variety of multi-modal downstream tasks from retrieval-augmented generation (RAG) and semantic search to sentiment analysis and data clustering. The model can analyze detailed relationships among different media types by accepting multiple media types in a single request, such as images and text.  

For example, Google noted that Gemini embeddings can help legal professionals find important information during the discovery phase of litigation. The multimodal embedding improves precision and recall across millions of records and enhances image and video search.  

Gemini embeddings (Gemini-embeddin-2-preview) are now available for public preview through Gemini, the Gemini API, and Vertex. The Gemini-embedding-001 model is still available for text-only needs.

Source: Embeddings 

Google releases Gemini Embedding 2 AI model with multimodal support

Quantum computing is rapidly advancing, challenging enterprise security strategies to evolve just as quickly. This change prompts a critical question: Do you know what cryptography your business depends on today?  

Most organizations cannot fully answer this question. Quantum-computation methods pose a threat to today’s asymmetric cryptography, and new regulations, such as NIST’s PQC guidance, now require stronger systems. Discovering, analyzing, and planning for cryptographic changes is essential.  

Additionally, with the latest release of IBM Quantum Safe Explorer, clients running Z-Linux platforms, including IBM Linux, can now use it via the command line interface (CLI). This update delivers Quantum Safe visibility directly to mission-critical workloads, seamlessly extending these capabilities.  

Meet IBM Quantum Safe Explorer. 

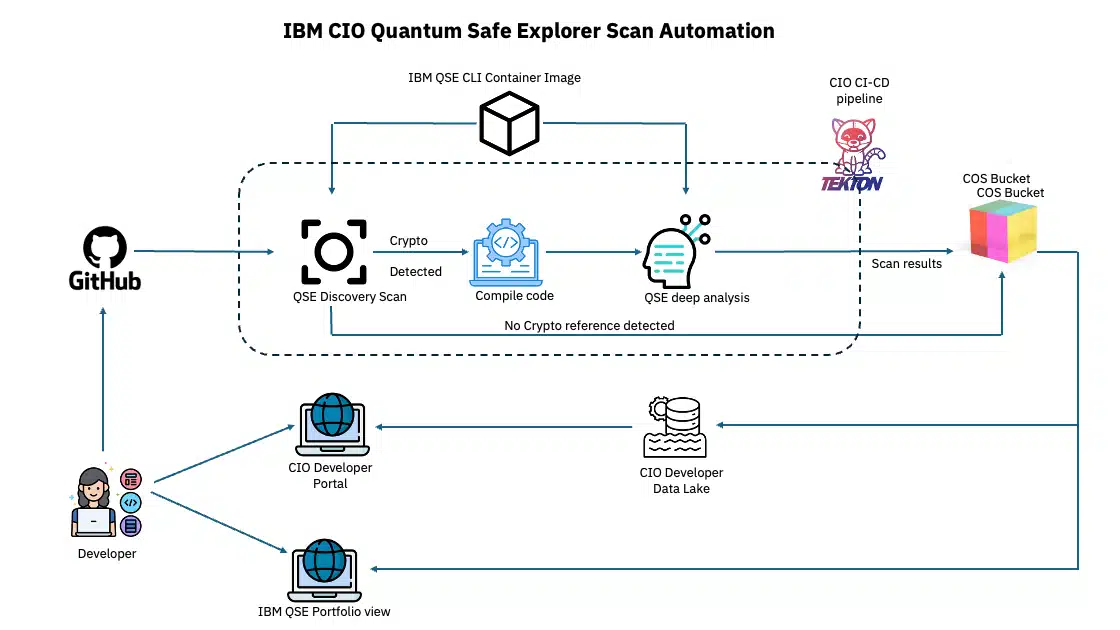
IBM Quantum Safe Explorer enables developers and security teams to quickly pinpoint cryptographic elements in application code, APIs, and environments. This utility streamlines cryptographic inventory and assessment for evaluating quantum readiness.  

The tool helps track cryptographic assets, such as algorithms, keys, certificates, and libraries, across applications and infrastructure. It can generate cryptographic bills of materials (CBOMs) and assess cryptographic risks to prepare for quantum-safe transitions.  

Security and compliance professionals can use the tool to answer critical questions about quantum readiness.  

  • Users can identify which cryptographic algorithms are deployed.  
  • Assess whether they are outdated or insecure.  
  • Locate where these algorithms reside.  
  • Determine which applications use them and evaluate preparedness to adopt post-quantum solutions.  

With these new capabilities, clients using Z Linux and Linux One environments gain targeted answers to previously unresolved cryptographic questions, directly aligning with Quantum Safe Explorer’s core value.  

Unlocking Crypto Agility with IBM Quantum Safe Explorer 

Preparing for a quantum-safe future requires more than technical vulnerability scans. Organizations need visibility, agility, and management over encryption systems. IBM Quantum Safe Explorer supports diverse stakeholders, positioning CBOIMs at the center of risk management and long-term crypto-agility goals.  

Value Delivered At Two Levels 

  1. For InfoSec and DevSecOps Leads: Portfolio Visibility & Governance 

Security and development leads gain clear visibility into cryptographic risks across portfolios. CBs provide a unified inventory for audits and compliance, highlight high-risk areas, and automate inventory generation in each development cycle for continuous oversight.  

Dashboards display essential metrics, including new crypto components, changing risk scores, and remediation coverage across projects. This helps DevSecOps teams add cryptographic checks to the CI/CD pipeline with little disruption.  

  1. For Leadership & the C-suite, translating risk into action 

Executive dashboards distill technical details into clear business insights. Leaders quickly understand which applications depend on vulnerable cryptography, the completeness of cryptographic inventories, and areas needing agility improvements. Quantum Safe Explorer equips executives with compliance-ready evidence to demonstrate NIST quantum-safe conformance to regulators, supporting both current mandates and future requirements, such as the U.S. federal mandate for a cryptographic inventory by 2025. This enables leadership to prioritize risk mitigation and facilitate strategic planning for crypto agility investments.  

This shift allows leadership to proactively manage cryptographic risk at the business level, ensuring strategic alignment and operational readiness for evolving security requirements.  

Crypto Agility Anti-Patterns: What to Watch For 

Crypto agility requires the ability to update cryptographic algorithms across systems efficiently and reliably. Quantum Safe Explorer identifies any practices that may hinder this flexibility, including embedded algorithm versions, absent fallback mechanisms, or inconsistent library implementations.  

By identifying and mapping these issues to code paths, our solution provides teams with a clear plan for fixing them. This supports both current compliance and future resilience.  

New CLI support for Quantum Safe Explorer on Z Linux. 

This release adds CLI support for zLinux, making it easy to integrate into secure environments such as financial systems, public cloud platforms, and other regulated workloads.  

This means clients can now:  

  • Run cryptography discovery natively on Z Linux without moving data off the platform.  
  • Integrate QSE into CI/CD pipelines or system automation scripts.  
  • Generate CBOMs on demand for audit compliance or quantum readiness planning.  
  • Build a roadmap for replacing vulnerable cryptographic components over time.  

The CLI was designed for Enterprise DevOps teams to get started: install it on zLinux and configure the required access credentials. Add CLI commands to existing process scripts or automation workflows to perform cryptographic discovery. Generate CBO and reports, and track assets. Run these steps at defined intervals or during build and deployment stages to ensure up-to-date visibility.  

Why IBM LinuxOne 5? 

IBM Linux One 5 provides a secure platform for IBM Quantum Safe Explorer, allowing firms to prepare applications for the future with post-quantum cryptography.  

The system uses secure boot technology to prevent malware from being loaded during startup, improving cyber resiliency, and keeping the system safe. The crypto express 8s (CEX8s) hardware security module supports both classical and quantum-safe cryptography, meeting needs for confidentiality, integrity, and non-repudiation.  

LIDEX One 5 protects sensitive data both when stored and in use, thanks to its cybersecurity and privacy features. Its built-in crypto accelerators, confidential computing, and NIST-standardized post-quantum cryptography provide a strong foundation for quantum resistance in modern IT systems.  

Integration That Delivers: Security, Compliance, And Agility 

Combining IBM Quantum Safe Explorer with IBM LinuxOne 5 brings multiple technical benefits, such as:  

  • Quantum Safe Explorer leverages LinuxOne 5’s crypto accelerators and confidential computing, enabling deep cryptographic analysis and protecting sensitive data throughout its lifecycle.  
  • Simplified compliance: the combined solution makes it easier to comply with regulations such as PCI DSS, FIPS, GDPR, and the EU’s Digital Operations Resilience Act (DORA).  

What does this mean for LinuxOne clients? 

IBM LinuxOne clients are familiar with security and availability. These systems are built to process sensitive workloads with built-in encryption, hardware isolation, and high availability.  

However, even the most secure systems use cryptographic algorithms that may be decades old, and some of them are now at risk due to quantum computing. Many organizations also do not know where or how these algorithms are used.  

With this release, LinuxOne clients can now perform cryptographic discovery directly on the platform without exposing data. They can identify algorithm dependencies early, enabling crypto agility before major changes are necessary. This also helps them prepare for new NIST post-quantum standards.  

The solution makes it easier to meet compliance requirements for regulations such as FIPS, GDPR, and PCI DSS, which now require greater insight and control over cryptographic assets.  

To summarize, Quantum Safe Explorer on Z-Linux helps organizations improve their cryptography practices and plan for the future directly within their LinuxOne environments, securely, efficiently, and at scale.

Source: Extending quantum-safe visibility to LinuxONE: IBM Quantum Safe™ Explorer now available with CLI support on Z-Linux 

As the semiconductor industry moves from general-purpose computing toward specialized AI acceleration, AMD’s upcoming Gen 6 architecture, known as Morpheus, will introduce a major change: Coron, native support for IMT (for Bit integer) instructions.  

This shift toward INT4 is a significant evolution from previous architectures that emphasized FP16 and INT8 for machine learning. The transition reflects not only technological advancement but also aligns with industry trends for efficient edge inference.  

The Move to 4-bit Precision 

The main challenge for local AI, whether on a desktop PC or a workstation, is memory bandwidth and cache pressure. Large language models (LLMs) and diffusion models consume significant memory. With INT4 quantization, it can compress models much more than the current int8 standard.  

Instructions let the processor fit more data into the same amount of memory cache. For example, a model that once needed 16 GB of VRAM or system memory can now be compressed to 4-6 GB using 4-bit weights, with little loss in accuracy. For most consumer tasks with native hardware support, these operations avoid the usual quantization tax, which is the extra software work needed to convert 4-bit data back to 3 higher precision for calculations.  

Architectural Synergy: AVX 512 and the AI Engine 

NT4 support in Zen 6 is not simply an add-on; it is built into the updated AVX-512 execution units. By expanding the vector map to support 4-bit-packed integers, AMD delivers a significant boost in Token-Per-Second performance for running Local LLMs.  

Zen6 will also have closer integration between its x86 cores and the XDNA3 Neural Processing Units (NPU). The NPU manages ongoing background AI tasks, while the Zen6 cores use INT4 instructions for large on-demand tasks, such as real-time code completion or live translation. This hybrid setup keeps the CPU as a key part of the AI processing pipeline.  

Impact On Local AI Development 

For US developers using frameworks like PyTorch and TensorFlow, native int8 support makes it easier to run small language models (SLMs) like Llama3 or PHI3. In the past, running these models locally needed a high-end GPU. With Zen6, the CPU can handle adversarial inference on its own, reducing the need for cloud APIs and improving data privacy for businesses.  

Key Benefits of Gen 6 INT4 Support Include: 

  • Reduced memory bottlenecks: lower-precision data moves faster through the Infinity Fabric and memory controllers.  
  • Improved power efficiency: fewer bits per operation translates directly to lower joules per inference.  
  • Enhanced cache locality: more parameters fit in L2 and L3 caches, reducing the need to fetch data from slower system RAM.  

Conclusion: The Future of the AI PC 

By building iMT4 support into Zen6, AMD demonstrates that the AI PC is no longer just an idea it’s an imminent, practical reality. As late 2026 nears, Zen6 is poised to reshape the expectations for performance and autonomy in local AI. For developers and businesses, the barriers to running advanced AI locally are on the verge of vanishing.

Source: AMD Introduces Ryzen AI Embedded Processor Portfolio, Powering AI-Driven Immersive Experiences in Automotive, Industrial and Physical AI 

Policy in Amazon Bedrock AgentCore lets developers set up and enforce security controls for how AI agents interact with tools, creating a secure boundary around agent activities. AI agents can adapt to handle a range of tasks, from answering customer questions to automating workflows across multiple tools and systems, but this flexibility can also introduce new security risks as agents might misunderstand business rules or exceed their intended limits.  

In AgentCore, developers can build policy engines. These are software components that automatically enforce rules. Developers store explicit policies in these engines and connect them to gateways, which control and monitor the flow of requests. The system checks all agent traffic passing through Amazon Bedrock AgentCore gateways. It ensures each request complies with the defined policies before agents can access tools.  

Policies are written in Cedar, an open-source language for creating and enforcing authorization rules. This helps developers clearly define what agents can access and what actions they can take. Policy in AgentCore also lets developers write policies in plain English, so they do not have to use Cedar. The system deciphers these natural-language rules, generates possible policies, checks them against the tools set up, and uses automated checks to spot overly broad, overly strict, or impossible-to-make rules. This helps customers find and fix problems before policies are enforced.  

Policy in AgentCore provides detailed rights based on user identity and tool inputs, making it safer to use autonomous agents at scale by handling security outside the agency’s code. Developers can focus on building new features while maintaining strong security. This removes the need for custom security work and lowers the risk of agents bypassing policies.  

Key Benefits 

PolAgentCore policy delivers three main benefits for secure, scalable AI agent deployment. Fine-grained Control: Define the actions agents can take, the tools they can use, and the conditions under which they can use them.   

  • Deterministic Enforcement: Consistently enforce policies outside agent code for reliable security. Accessible Authoring: Create policies in English or Cedar for broad team adoption.EnfAll enforcement decisions are logged in CloudWatch for compliance purposes.  

Key Features 

Policy in AgentCore provides a full set of tools to manage agent interactions with policies. Main features include:  

  • Policy enforcement: the system checks all agent requests against set policies before granting access to tools.  
  • Access Controls: allow detailed permissions driven by user identity and tool input.  
  • Policy authoring: Write clear, validated policies in Cedar. You can also create policies in plain English, which the system translates and checks.  
  • Policy Monitoring integrates with Amazon CloudWatch (a monitoring service that collects and tracks metrics) to observe policy checks and decisions.  
  • Structure collaboration works with VPC security groups and other AWS security tools.  
  • Audit Logging keeps comprehensive logs of policy decisions for compliance and troubleshooting.

Source: Policy in Amazon Bedrock AgentCore: Control Agent-to-Tool Interactions 

Google Cloud regularly works with customers, partners, and registrars to deliver technology that meets their needs. We have been helping customers with digital sovereignty solutions for almost ten years.  

With this longstanding commitment, we are excited to share technical and commercial updates to our sovereign cloud solutions, enabling customers to gain greater control, choice, and security in the cloud without sacrificing functionality.  

Building on the first sovereign solutions we introduced years ago, we’ve massively scaled our global infrastructure footprint, now comprising more than:  

  • 42 cloud regions  
  • 127 zones  
  • to work at the network edge locations  
  • 33 subsea cable investments  

We have built important partnerships across Asia, Europe, the Middle East, and the United States. Our partners include:  

  • Schwarz Group and T-Systems in Germany  
  • S3NS in France  
  • Minsait in Spain  
  • Telecom Italia in Italy  
  • Clarence in Belgium and Luxembourg  
  • CNTXT in Saudi Arabia  
  • KDDI in Japan  
  • Worldwide Technology in the United States  

Our Pledge To Customer Choice 

Digital sovereignty means more than just managing encryption keys. It supports giving customers the flexibility their global businesses need. It also allows them to use multiple clouds and secure their data with advanced technologies.  

We have always supported customers in choosing providers and solutions that work for them. Because cloud sovereignty varies by customer, we offer a range of solutions to address different needs and risk levels.  

We back our strong customer commitments with reliable sovereign controls and solutions, all available now. Our updated Sovereign Cloud solution portfolio includes:  

  • Google Cloud Data Boundary lets customers decide where content is stored or processed, and allows them to manage encryption keys (which lock and unlock data) outside Google’s infrastructure. This helps them meet specific data control needs in any market.  

Google Cloud Data Boundary customers can access a broad range of Google Cloud products, including AI services. They benefit from features such as confidential computing and external key management with key access justifications, which let them control and deny access to their data as needed. With data boundaries, sovereign controls, customers can limit data processing to the United States or the EU, select countries for local data storage, and use client-side encryption to prevent unauthorized access, even by Google, to their most critical content.  

We are also introducing User Data Shield, which uses Mandiant services (security experts) to check the security of customer applications built on the Google Cloud data boundary. User Data Shield performs regular security testing of these customer applications to help confirm that sovereignty rules are being followed.  

  • Google Cloud Dedicated delivers a solution created to meet local sovereignty requirements, enabled by independent local and regional partners. For example, Google Cloud has partnered with Thales since 2021 to build a first-of-its-kind, S3NS-trusted cloud for Europe.  

This offering with Thales is intended to provide a rich set of Google Cloud services with GPUs to support AI workloads. It is operated by S3NS, a standalone French entity currently in preview. S3NS solution is designed to satisfy the rigorous security and functional resilience requirements of France’s SecNumCloud standards. We are expanding our Google Cloud dedicated footprint globally and will include Launch Next in Germany.  

For France to truly embrace digital sovereignty, it is essential to have a cloud solution that unites the greater power of hyperscale technology with the strictest local security and administrative controls. S3NS is committed to providing French organizations with access to advanced cloud services, including critical AI capabilities, all operated within France by a European operator to meet and exceed the rigorous SecNumCloud standards, said Christophe Solomon, EVP Information Systems and Secured Communications at Thales.  

  • Google Cloud air-gapped is a standalone solution designed to operate without any direct or indirect connection to external networks; ie, an air-gapped system. It is intended for customers in fields such as intelligence and defense that require high-level data security and data residency controls, meaning strict oversight of where data is stored. Google, the customer, or a Google partner can take responsibility for deploying and managing this solution.  

This solution uses open-source components and includes selected AI, database, and infrastructure services. Relying on open-source technology helps ensure business continuity and resilience during service disruptions. In 2024, Google Cloud Air Gapped was approved to host the US government’s top secret and secret-level data.  

Working with Google Cloud to introduce sovereign offerings can give our joint clients greater control, choice, and security in the cloud without jeopardizing the functionality of their underlying cloud architectures, said Scott Alfieri, Senior Managing Director and Google Business Group Lead at Accenture. Google Cloud’s extensive global infrastructure, coupled with Accenture’s transformation and industry expertise, helps organizations build an agile and scalable foundation, unlocking chances for growth and continuous innovation.  

Local Control Global Security 

Security and sovereignty go hand-in-hand. When customers control their data and operations locally, they can feel more confident about security; however, true security sovereignty is not possible if outdated infrastructure exposes data to loss or theft.  

According to the Google Threat Intelligence Group and Google Cloud’s Office of the CISO (Chief Information Security Officer), cyber attacks globally are becoming more advanced. Attackers are now leveraging Artificial Intelligence (AI) tools and techniques to exploit weaknesses in older software platforms and outdated systems.  

With Google Cloud, customers receive sovereign solutions along with top security features. These include Secure by Design technology and the expertise of the Google Threat Intelligence Group and Mandiant Consulting, which work at the front lines of cyber defense and partner with over 80 governments globally.  

Google Cloud CyberSheild uses AI and intelligence-driven tools to help governments defend against large-scale threats. Mandiant managed defense services also let customers around the world strengthen their security teams with our experts.  

Google’s Sovereign Cloud Solutions let customers leverage Google Cloud’s secure foundation and access state-of-the-art security features, including:  

  • Confidential Computing  
  • Zero Trust  
  • Post Quantum Cryptography  
  • AI-Driven Defenses  

These features can be delivered faster and at a lower cost than building them in-house.  

Sovereign Solutions For Any Organization 

We are committed to building trust, giving our customers control, and helping organizations confidently handle digital sovereignty. We continue to work with customers, partners, and regulators to improve and deliver the sovereign cloud solutions needed.  

Learn more about our digital sovereignty support on our website or by contacting your account manager.

Source: Advancing sovereignty, choice, and security in the cloud for our customers May 21, 2025 

Samsung SDI announced it will present advanced battery solutions and new technologies for the AI era at InterBattery 2026, held March 11-13 at COEX in Seoul.  

At this year’s exhibition, the company will unveil a pouch-type all-solid-state battery sample under development for physical AI applications such as humanoid robots. This product aims to provide greater safety and longer operational time, emphasizing Samsung SDI’s global leadership in all-solid-state battery technology.  

Samsung SDI will also present battery solutions that boost reliability for energy storage systems (ESS) and provide more stable, high-power batteries for uninterruptible power supplies (UPS) and battery backup units (BBU). These solutions strengthen essential AI infrastructure by ensuring continuous operation and rapid response during power fluctuations.  

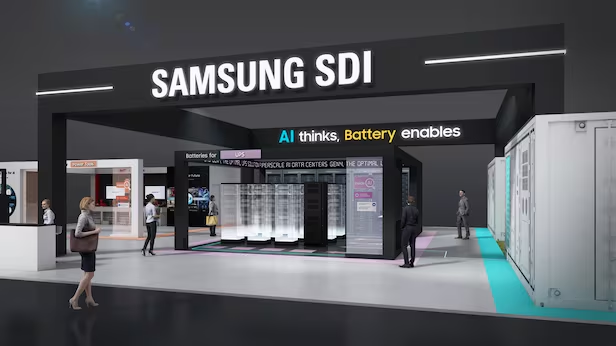
United by the slogan “AI thinks battery enables,” Samsung SDI will have the largest booth, featuring innovative technologies and products.  

Our goal is to show how Samsung SDI’s battery technology brings the complete potential of the AI era to life. A company official said, “With decades of expertise, we will present premium battery solutions designed for the changing needs of AI-powered industries.”  

First Public Display of Pouch-Type All-Solid-State Battery for Physical AI 

Samsung SDI will introduce its All-Solid State Battery technology at InterBattery2026. This technology, still in development, targets mass production in the second half of next year.  

The company will show a pouch-type or solid-state battery sample for the first time, designed for new physical AI applications.  

Robots have limited space for batteries and require small, lightweight cells with high energy density for long run times. They also need high power output during motion, so batteries must deliver it without overheating.  

Samsung SDI is developing all-solid-state batteries that offer superior safety and high-power output for physical AI applications, using a pouch designed to reduce weight. After focusing on prismatic batteries for electric vehicles, the company now plans to offer a wider range of battery shapes for different applications, including humanoids, robots, aviation, and next-generation wearables.  

To align with these technological advancements, this year’s exhibition theme is Inside AI, giving visitors an up-close look at how batteries are used in industries and everyday life.  

The main booth will resemble a real IT data center, allowing visitors to feel like they are inside a working facility.  

At the center of the booth, a US UPS mock-up will feature Samsung HDI’s U8A1 battery for UPS uses.  

The U8A1 combines a unique prismatic shape and LMO chemistry for high power and safety. Designed for data centers, it offers greater energy density and volume efficiency for stable, rapid power delivery.  

Unlike regular UPS batteries that only power during outages, the U8A1 also helps keep power steady during sudden spikes in AI power consumption. This feature enables continuous operation and prevents downtime, making it better suited to changing customer needs.  

Behind the UPS area, Samsung SDI will debut its high-power BBU battery, installed in data center servers to provide instant backup during outages and prevent data loss.  

The BBU uses high-nickel NCA cathodes (which store more energy) and SCN anodes (which allow faster charging) in a cylindrical battery. Annually, at the bottom, it helps release heat, reduces internal temperature, and extends battery life, enhancing overall safety.  

By connecting high-power, high-capacity cells directly to servers, the system gives instant support during power peaks and can increase data storage time by over 50% during outages, enhancing operational continuity and protecting critical information.  

Pop Art Collaboration With Um Jaewon And Exhibition Highlights 

To begin, visitors can check out power tools that use Samsung’s HDI cylindrical batteries. This gives everyone a chance to see the company’s high-power cylindrical technology up close.  

Samsung SDI’s cylindrical batteries use tapped technology, increasing power output and charging speed. For example, a circular saw with these batterie’s cuts wood faster and recharges in 15 minutes.  

In addition to the technology displays, Samsung HDI is presenting five artworks created in collaboration with Korean artist Um Jaewon, inspired by the theme Fun-tastic Power: Energy that powers joy in everyday life. These pieces contribute a creative element to the exhibition. In his work, Um Jaewon portrays ESS as a quiet hero safeguarding sustainable energy in the AI era, and he represents Samsung HDI’s high-power batteries as small cells with significant potential, symbolizing how innovation can empower and enhance daily life.

Source: SAMSUNG SDI Unveils All-Solid-State Battery for Physical AI 

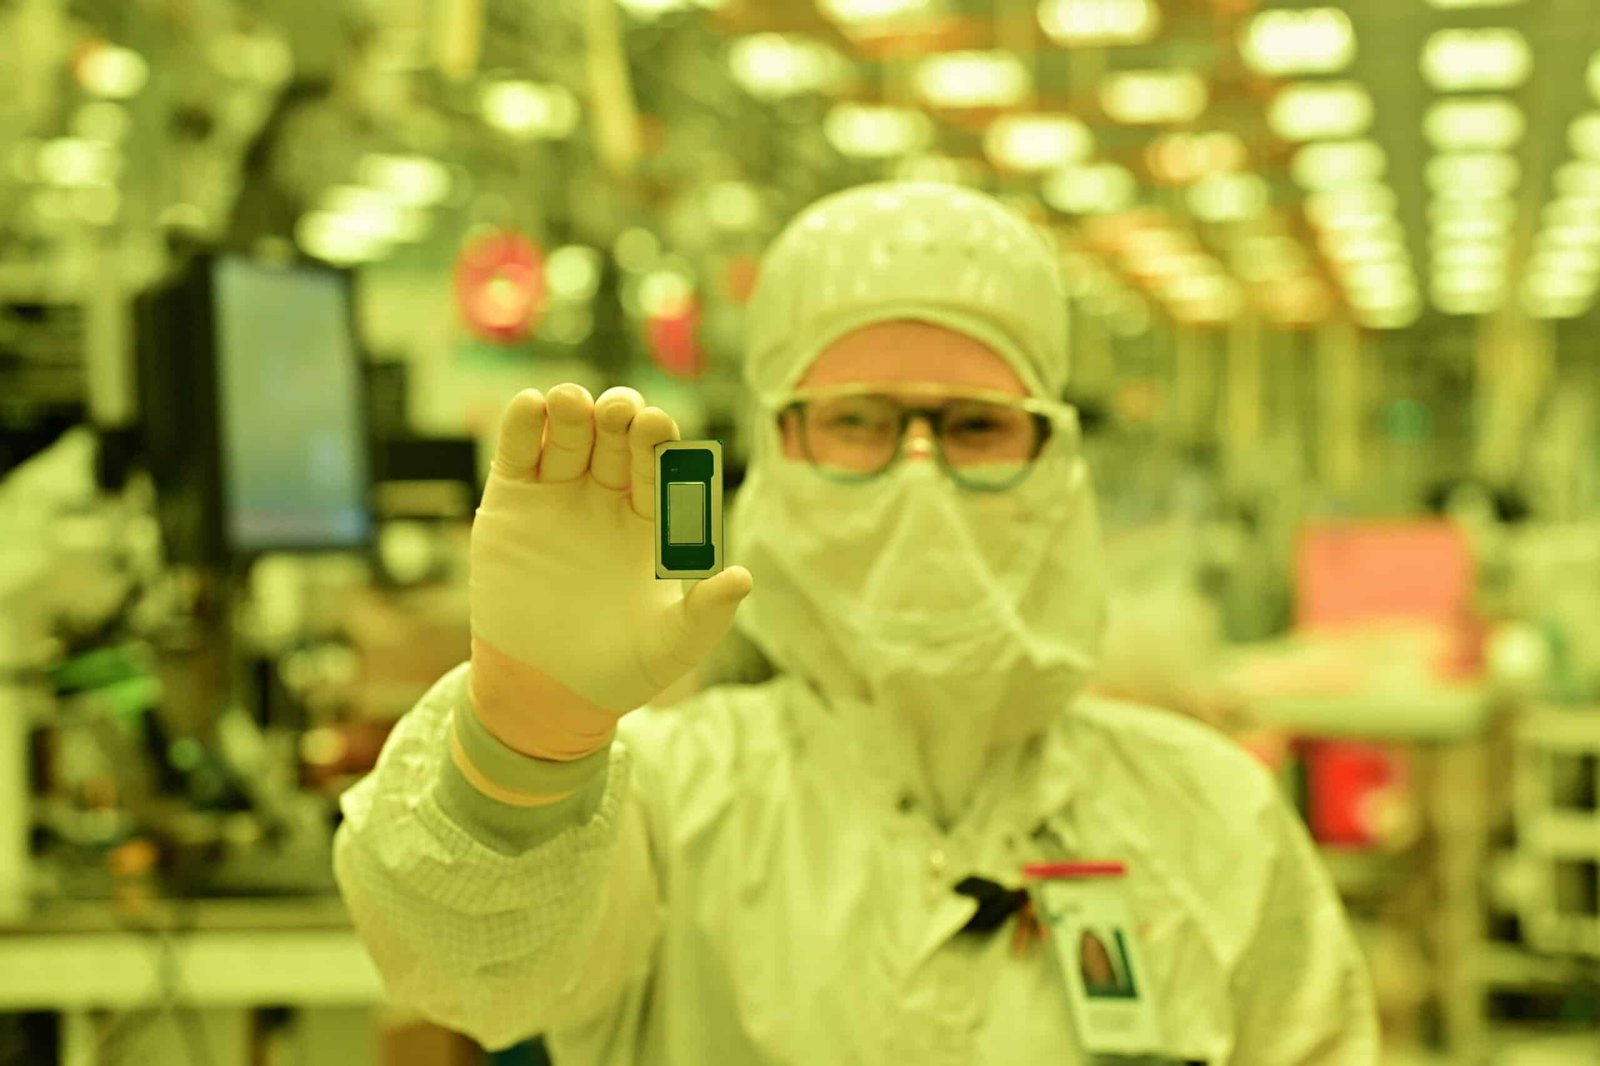
At its Vision 2025 conference, Intel announced the start of risk production for its 18A process node. This marks the beginning of low-volume test manufacturing for the node.  

Intel’s Kevin O’Buckley, the senior vice president of Foundry Services, made this announcement as Intel approaches the completion of its goal to deliver five new process nodes in a four-year period a program starting in 2021 under ex-CEO Pat Gelsinger. This Vision 2025 conference is also the first to feature Intel’s new CEO, Lip-Bu Tan, on stage.  

Intel announced its four-year development plan in June 2021. Within this plan, Intel canceled high-volume manufacturing of the 20A node to reduce costs and shifted its focus to preparing it for production. The 18A node is nearing completion, and the 5N4Y plan emphasizes having nodes ready within the four-year window rather than immediately launching high-volume manufacturing for each.  

Risk production is a key step toward launching a new node. It shows Intel believes the node is close to high-volume manufacturing. The company has already built many 18A test chips, sometimes with several designs per wafer.  

During the risk production stage, Intel manufactures wafers with a single-chip design in low volumes to refine the manufacturing process and test the node and its process design kit. Following earlier research, design, and prototyping phases, Intel expects to ramp up production later in 2024.  

Risk production entails low yields and performance as Intel refines manufacturing. Customers use this stage for qualification or engineering samples without the strict yield guarantees of fully qualified manufacturing nodes.  

Some customers accept these risks to evaluate the node early and gain a head start on competitors.  

Intel has not said whether the 18A risk production is for its Panther Lake processors, due later this year, or for outside customers. Panther Lake, the first 18A processors, will enter mass production later this year. Thus, Panther Lake likely leads the risk production, matching Intel’s usual timeline from risk production to high-volume manufacturing.  

Although Intel pioneered several new technologies on its cancelled 20A node, the 18A chips will be the first productized chips to feature both backside power delivery and ribbon-FET gate-all-around (GAA) transistors. Power via provides refined power routing to improve performance and transfer transistor density, while ribbon-FET offers higher density and faster switching in a smaller area.  

Intel is also working on its broader foundry map, including the upcoming 18A node, its first to use high NA EUV lithography. Additional node extensions will help Intel Foundry Services serve more applications.  

These changes are occurring as Intel Foundry faces challenges amid shifting economic conditions. For example, Intel has delayed building its Ohio site until 2030. Still, the news about 18A risk production matches reports that Intel is already making its first 18A wafers in Arizona.  

Additional details about Intel’s timeline and future production stages will likely be provided at the Foundry Direct Connect event scheduled for late April 2024.  

Risk production, while it sounds scary, is actually an industry-standard terminology. The importance of risk production is that we have reached a point where we can freeze it. Buckle O’Buckley explained: “Our customers have validated that 18A is good enough for any product, and we now have to do the risk part, which is to scale from making hundreds of units per day to thousands, tens of thousands, and then hundreds of thousands. Risk production is scaling manufacturing up and making sure that we can meet not just the capabilities of the technology but the capabilities at scale.”

Source: Intel CEO embraces its 18A node for external customers as 18A-P gets ‘inbound interest’ — company cites increasing yields 

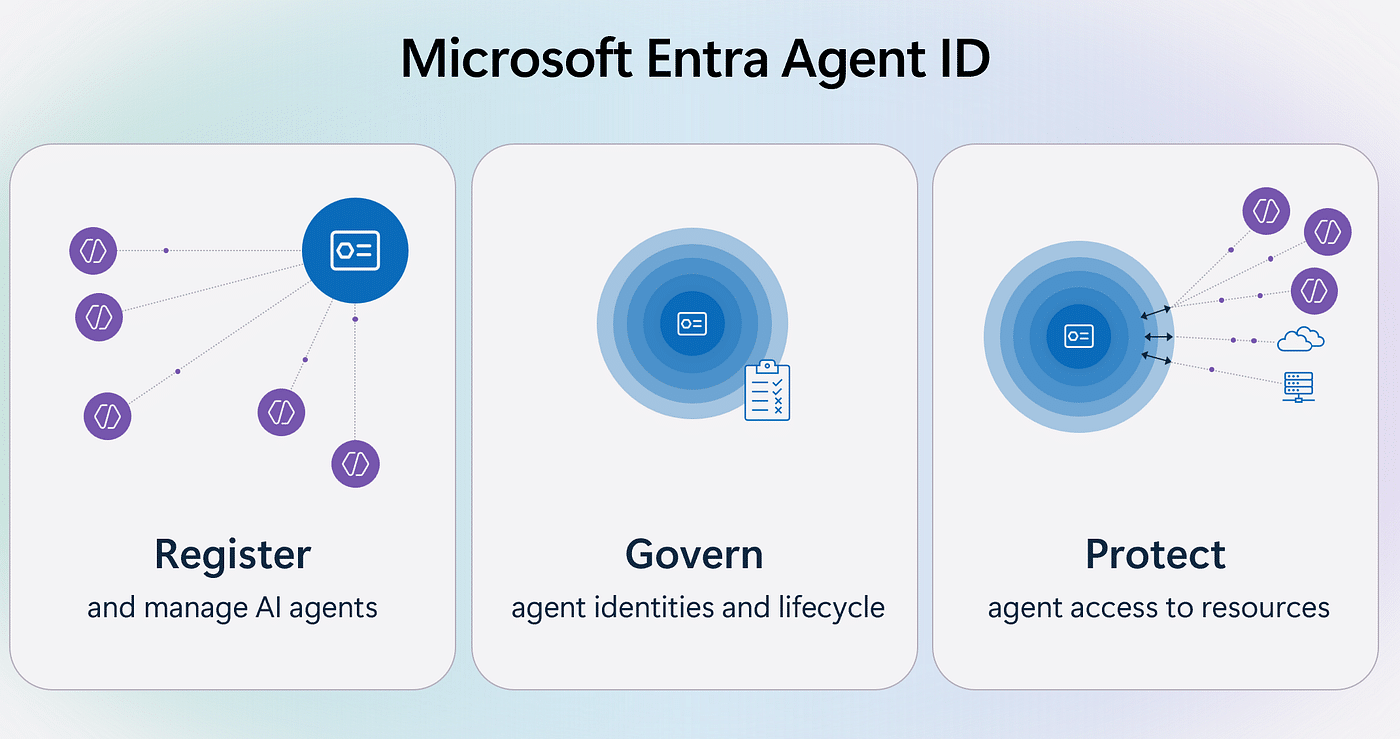
AI agents are evolving from simple tools to virtual team mates that help us work more efficiently. As teams adopt these agents, tracking them can be challenging. Their ability to handle complex tasks independently makes it critical to manage their identities, permissions, life cycles, and resource access securely.  

Our goal is simple, we want to give AI agents, the new digital teammates, the same protections and controls you already use for your workforce identities. The main benefit is that you can manage the security and life cycle of all AI agents from a single central location, just as you do with your human users. Today, I’m happy to tell you about the public preview of Microsoft Entra Agent ID, announced at Microsoft Build. In this first release, we’ve created a single directory for all agent identities in Microsoft Copilot Studio and Azure AI Foundry. This means that whether an agent is built by a developer or an information worker, you can see and manage the agent securely in the Microsoft Entra admin center.  

In the next six months, we’ll add more features for access management, security, and identity governance to Microsoft Entra Agent ID. We’ll also add support for agents from Security Copilot, Microsoft 365 Copilot, and other third-party solutions.  

How To Get Started 

As organizations increasingly adopt AI solutions, it’s important to know which agents have access to their environments. Starting today, you will see a new application type in the Microsoft Entra admin center that allows these agent identities. The agent ID application type lets you quickly view and track agent identities in your directory.  

To get started, sign in to the Microsoft Entra Admin Center and go to Enterprise Applications. At the top of the list, use the filter bar, set the application type dropdown to Agent ID (preview), and review the AI agents created with Copilot Studio or Azure AI Foundry in your tenant. Begin by selecting an agent, exploring its permissions and lifecycle settings, and making any required security updates. This will ensure you are actively managing your agents securely from today.  

What’s Next for Microsoft Entra Agent ID 

The features we offer today are just the beginning of our work to help you secure and manage AI Agent Identities. We understand you need more than visibility, so we are developing new tools to give you greater control over AI Agents and their access to resources.  

For example, we plan to make Microsoft Entra Agent ID work not just with agents built on Microsoft AI platforms. It will also support agents created using many other AI development tools.  

Over the next few months, Microsoft Entra Agent ID will add new features. These updates will help you strengthen your Zero Trust security and save time for both developers and identity teams.  

For Developers 

  • Built-in security controls: Agent identities in Microsoft Entra will use a least-privilege approach. They will request just-in-time, limited tokens for the resources the agent needs, such as a specific file or Teams channel.  
  • Instant Enterprise Boarding: agent identities will be full of identities in Microsoft Entra, so identity teams can find, approve, and audit your organization’s agents with the same tools they use for apps and users. There is no need for extra security reviews or custom co-auth flows once your agent has an identity in other Microsoft Entra tenants, each with its own policies, while you maintain a single codebase and telemetry stream.  

For Identity Practitioners 

  • Richer access controls: You can set detailed conditional access policies and permissions. This ensures AI agents access only the resources they need, using real-time signals and context.  
  • Enhanced lifecycle management: You will be able to automate least-privileged access from the beginning and manage AI agent identities as carefully as you do for users and services, from creation to removal.  
  • Expanded auditing and monitoring: You will gain access to detailed logs and visibility into agent activities for compliance and security. You can track what each agent does.  

Better Together: We Are Working With The Industry, Our Partners, And You  

We’ve always believed security is a team sport, and this will be especially true in protecting AI agents and their identities. That’s why I am so energized by the progress we are making together as an industry. Two weeks ago, Microsoft announced our support for the agent-to-agent (A2A) protocol, and we are actively partnering with the industry to design enterprise-grade identity support for both the A2A and the popular MCP protocols.  

Here is a demo of A2A in action. Our team used Azure AI Foundry and Microsoft Entra Agent ID to create a Teams agent that finds Entra and meeting room agents in the Entra registry, then uses them to book a meeting room and invite team members.   

Today, I am also excited to announce that we are partnering with ServiceNow and Workday. As part of this, we will integrate Microsoft Entra Agent ID with the ServiceNow AI platform and the Workday agent system on record. This will enable automated provisioning of agent identities that can perform duties alongside human employees in parallel. We are working to integrate ServiceNow and Workday agent-enabled applications with Microsoft Entra ID so that every agent created in ServiceNow or Workday has its own identity.  

As the next step, try out the new Microsoft Entra Agent ID features by managing a few AI agents in your environment. Provide feedback or questions in the comments below to help us improve. We are excited about what’s next for Microsoft Entra Agent ID and look forward to hearing how you use these features.  

Ensure every identity human or agent is managed and secured together.

Source: Announcing Microsoft Entra Agent ID: Secure and manage your AI agents