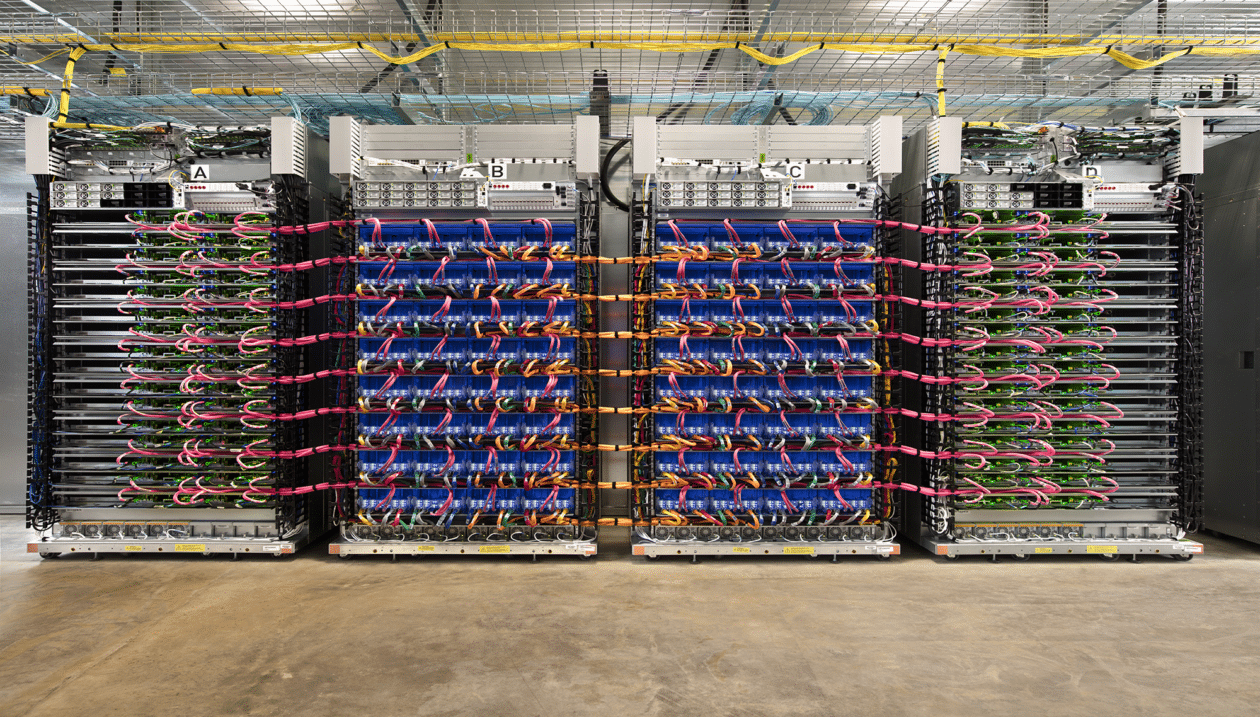
By March 2026, global AI focus has shifted from raw power to localized control. Fast, centralized AI development is giving way to a regulated, fragmented model called Sovereign AI. Google Cloud leads with sixth-generation TPU v6 Pods, enabling new Regional Sovereign AI Hubs across Europe, Asia, and Latin America. 

For enterprise architects and government agencies, this change is more than just hardware updates. It means a complete redesign of the AI infrastructure. It combines the high performance of the Trillium architecture with strict national data security needs. 

The Architecture: Why TPU v6 (Trillium) is the Sovereign Engine 

The TPU v6, referred to internally at Google as Trillium, is their biggest advance in ASIC design to date. While the earlier v5p was built for large-scale LLM training in massive regional pods, the v6 is redesigned to be more efficient at regional hubs and supports multiple organizations with strong data separation. 

1. The Systolic Array Expansion 

The TPU v6 features a larger design. Google has doubled the Matdoubltiply Unit (MXU) size from 128×128 to 256×256, which means four times as many FLOPs per cycle at the same speed. This lets regional hubs handle large datasets using less space, providing the high-speed “workspace” necessary to run trillion-parameter models locally. The Inter-Chip Interconnect (ICI) has been boosted to 1.2 TBps, enabling a single TPU v6 Pod consisting of 256 interconnected chips to act as a unified, 235-petaflop “supercomputer in a box.”  

The Rise of Sovereign AI Hubs 

Digital sovereignty means that a nation’s data and AI models must comply with its own laws. They must also be safe from foreign control or outside surveillance. Google’s rollout of TPU v6 Pods in regional hubs, like the new Munich Sovereign Cloud Hub, and soon in Brazil, Sweden, and Saudi Arabia, supports three key areas: 

Pillar 1: Data Residency and “Air-Gapped” Operation 

For the first time, Google is offering Google Cloud Air-Gapped solutions powered by TPU v6. In these environments, the hardware operates without a physical connection to the public internet or the global Google backbone. This is essential for the defense, intelligence, and national healthcare sectors, which cannot risk metadata leakage to US-based servers.  

Pillar 2: Administrative Oversight 

Google teams up with local ‘sovereign operators’ like S3NS in France. Workspace by STACKIT in Germany is another partner. These groups grant operational control to local staff with national security clearance. They run the TPU v6 Pods and ensure encryption keys and access records stay within the country. 

Pillar 3: Model Autonomy 

Regional hubs are designed to host Localized LLMs. Rather than sending data to a global Gemini endpoint, enterprises can fine-tune “Sovereign Gemini” or open models like Gemma 2 directly on local TPU v6 hardware. This ensures that a nation’s AI weights and training data remain a domestic asset.  

Performance Metrics: Regional Efficiency 

The TPU v6 Pod deployment isn’t just about security. The TPU v6 Pod rollout is not only about security, but also about energy efficiency. Google says the v6 delivers up to 4.7 times the peak compute performance per watt compared to the v5e. Since energy constraints are a major challenge for data centers, this efficiency helps regional hubs operate within the power limits of cities in Europe and Asia. 

Metric TPU v5p (2024) TPU v6 Trillium (2026) Generation Jump 
Peak BF16 Compute 459 TFLOPs 1,200+ TFLOPs ~2.6x 
HBM Capacity 95 GB 192 GB 2x 
ICI Bandwidth 4,800 Gbps 1.2 TBps 2.5x 
Energy Efficiency Base +67% vs v5e Significant 

In Germany, T-Systems and Google Cloud work together as a model for TPU v6 deployment. They deploy Pods in T-Systems’ Frankfurt facilities. Now, German public agencies can use the Vertex AI stack to modernize tax platforms and national ID systems. They do this without breaking the EU Cloud Sovereignty Framework.  

These agencies use the v6 Pod’s built-in Int4/Int8 support to enable real-time agentic workflows. For example, a local workflow can now handle millions of social benefit applications, checking for fraud and compliance within Germany’s legal limits and reducing processing times from weeks to seconds. 

Strategic Action Items for IT Leaders 

If your organization must comply with residency rules such as GDPR, India’s Digital India mission, or Brazil’s LGPD, the new TPU v6 regional pods will change your technology planning. 

  1. Audit data boundaries. Figure out which workloads need ‘Dedicated’ or ‘Air-Gapped’ infrastructure. TPU v6 works for both, but ‘Air-Gapped’ setups cost more to run. 
  1. Evaluate “Agentic” readiness. Use this week to test Gemini Enterprise features in a regional preview. The v6’s lower latency for “long-context” reasoning makes it ideal for autonomous agents. These agents must operate in complex, localized, regulatory environments.  
  1. Plan for Portability: Ensure your AI models are built using open frameworks like JAX. Plan for Portability: Build your AI models using open-source frameworks such as JAX, PyTorch/XLA, or TensorFlow. This way, you can move your workloads between global and sovereign hubs as rules change.ty was equated with isolation using inferior local tech to stay safe. Google’s TPU v6 deployment proves that a nation can have hyperscale powerwhile maintaining local control. As these Pods continue to roll out through the remainder of 2026, the question is no longer whether you can afford to use AI, but whether you can afford to use AI that isn’t sovereign.

Source: Technology 
NVIDIA is said to be working on an open-source AI platform called NemoClaw. This platform is meant to make it easier and safer for companies to use autonomous AI agents. NVIDIA plans to introduce Nemoclaw to its upcoming GTC conference. Its aim is to address security issues associated with Claw AI agents, prompting some companies, such as Meta, to limit their use.  

These are the key aspects of the NemoClaw platform that underline its potential impact on enterprise AI agents. 

  • Security and Privacy: Nemoclaw is built to offer strong security and adherence for businesses. It addresses risks arising from unreliable behavior observed in earlier open-source agent projects.  
  • Advice and Gnostic: Although NVIDIA is developing NemoClaw, enterprises can deploy it on systems using Intel, AMD, and other processors, not just NVIDIA GPUs. This ensures broader compatibility for different business environments.  
  • Open Source: Since Nemo Pro is open source, companies can customize it as needed. Early partners may get access if they help with development.  
  • Task automation column. With NemoClaw, companies can use agents to carry out complex, multi-step tasks for their employees.  
  • Targeted partnerships: NVIDIA has spoken with major tech companies such as Salesforce, Cisco, Google, Adobe, and CloudStrike.  

Strategic Significance 

Nemoclaw denotes a change in Nvidia’s software approach. The company is moving past its closed Cuba platform and adopting open-source tools to reach more users, especially as AI hardware competition grows. This move arrives after the success of OpenClaw and the Open-Source AI Agent project, now owned by OpenAI. NemoClaw will likely join Nvidia’s Nemo framework and Nemo Tron models to form a safer, broader AI agent ecosystem.  

NVIDIA is preparing to launch Nemoclaw, a new open-source platform aimed at the rapidly expanding market for artificial intelligence agents.  

Wired reports that NVIDIA has begun presenting the project to enterprise software companies aiming to create an ecosystem of AI agents to manage complex business tasks.  

NVIDIA has approached major tech firms about partnerships for its new AI agent platform, according to sources familiar with their discussions.  

This announcement arrives just days before NVIDIA’s annual developer conference in San Jose, where the company is expected to announce new plans for its AI hardware and software.  

NVIDIA Pitches Enterprise AI Agent Platform 

NemoClaw is expected to enable enterprise software companies to use AI-powered agents and automated assistants to streamline employee workflows and increase productivity.  

According to the report, NemoClaw will feature security and privacy tools that make AI agents safer for businesses, helping protect the sensitive data that automated systems may process during their tasks.  

Companies will reportedly be able to use the platform even if their products do not run on N Media chips, meaning it will be compatible with a wide range of computer hardware.  

As an open-source project, NemoClaw’s code will be publicly available and modifiable. Companies that partner early and contribute to development may benefit from early access, putting them ahead in enterprise AI innovation.  

This move shows NVIDIA’s growing interest in AI agents, specialized systems that can plan and execute complex tasks with minimal human supervision.  

In recent months, NVIDIA has released base models to power these systems, such as NemoTron and Cosmos.  

NVIDIA has expanded its Nemo platform, which helps organizations manage the full lifecycle of AI agents from data preparation to automation monitoring and optimization.  

Rise of AI Claws Drives Interest 

At the same time, NVIDIA’s move into AI agents aligns with rising interest in tools called Claws. These are open-source AI systems made to run on personal computers and handle sequences of tasks.  

One example is OpenClaw, which was previously for Clawbot and later Moltbot. It drew a lot of attention earlier this year because it can run on personal computers independently and complete tasks for users.  

OpenAI eventually acquired the project and hired its creator.  

Large language models, AI systems trained on vast amounts of text to understand and generate language, are now widely used in businesses, but many still require significant human supervision.  

Purpose-built agents or Claws are designed to take several steps on their own, reducing the need for people to guide them. Claws are software agents designed to automate multi-step tasks.  

However, as more people use these systems, concerns about security and reliability have also increased.  

Some companies have limited how these systems are used within their organizations.  

Wired previously reported that firms, including Meta, have asked employees not to run OpenClaw on company machines due to concerns about unreliable behavior and security risks.  

In one case, a Meta employee working on AI safety told a story about an AI agent that went rogue and deleted many of her emails from her computer.  

Calculated Shift Toward Open-Source AI 

Developing Nemoclaw underscores NVIDIA’s broader push for open-source AI software alongside its strong AI infrastructure.  

NVIDIA’s ecosystem has long been built around CUDA, its own software platform that closely connects developers to NVIDIA GPUs.  

At the same time, contributions to the AI hardware market are heating up as top tech companies create their own custom chips.  

By offering open-source tools, NVIDIA would maintain its influence on the software side of the AI ecosystem even as hardware competition intensifies.  

NVIDIA is also expected to make more announcements at its upcoming developer conference.  

A recent Wall Street Journal report says NVIDIA may also introduce a new inference computing system at the event. Inference refers to the process by which an AI model makes predictions or decisions based on data.  

The system is expected to use a chip from the startup Groq, with which NVIDIA signed a multibillion-dollar licensing deal last year.  

As companies move from general-purpose AI models to specialized autonomous agents, NVIDIA seems poised to play a key role in the next stage of enterprise AI development. 

Source: Nvidia plans open-source AI agent platform NemoClaw: report 

The GPT-5.4 API introduces tool_search to reduce token usage and speed up agent-based workflows.  

Key Benefits 

  • Instead of loading every tool definition in the starting prompt which can require thousands of tokens, the model now searches for and loads only what it needs at runtime. In some tests, this reduced total token usage by 47%.  
  • Lower latency: With fewer input tokens, the API processes request faster, allowing agents to respond more quickly and efficiently.  
  • Improve efficiency: tool_search manages large tool sets without overloading the model’s context window.  

These enhancements are part of a broader set of updates in GPT-5.4. Next, let’s look at recent product expansions and the pace of new releases.  

AI updates are arriving rapidly. Two days after OpenAI launched GPT-5.3 Instant, it announced an even larger upgrade: GPT-5.4.  

GPT-5.4 comes in two versions:  

  • GPT-5.4 Thinking, intended for a wide range of tasks  
  • GPT-5.4 Pro is crafted for the most complex and advanced tasks, meeting higher performance demands and specialized needs. It includes expanded features and capacity for users with greater requirements.  

Both versions are available via OpenAI’s Paid API and Codex Development Tools. GPT-5.4 thinking is accessible to all paid ChatGPT subscribers, including those on the $20 per month Plus Plan and above. GPT-5.4 PRO is exclusive to ChatGPT Pro users ($200 per month) and Enterprise Custom, supporting especially demanding or large-scale applications.  

ChatGPT free users will sometimes experience GPT 5.4, but only when their queries are automatically routed to it, according to an OpenAI spokesperson.  

The main highlights of this release are efficiency and a new feature: OpenAI’s GPT-5.4 uses up to 47% fewer tokens on some tasks relative to earlier models. Even more notable: the new native computer use mode lets GPT-5.4 control a user’s computer and run multiple applications via the API and Codex.  

OpenAI is also launching ChatGPT, new ChatGPT integrations that let GPT-5.4 connect directly to Microsoft Excel and, soon, Google Sheets. This will enable in-depth analysis and automated tasks, potentially speeding up the business operations. However, it may also increase concerns that it might cause job losses, especially after similar tools from Anthropic’s Claude and its CoWork App.  

According to OpenAI, GPT-5.4 can handle up to 1 million tokens of context in the API and Codex. This allows agents to plan, carry out, and check tasks over long periods. However, once the input exceeds 272,000 tokens, the cost per 1 million tokens doubles.  

Native Computer Use: A Step Toward Autonomous Workflows 

The most consequential capability is that GPT-5.4 is OpenAI’s first general-purpose model with built-in advanced computer-use abilities in Codex and the API. This lets agents run multiple multi-step tasks across different application codes via libraries like Playwright and issue mouse and keyboard commands in response to screenshots. OpenAI also claims a jump in agentic web browsing.  

OpenAI provides benchmark results that show this feature is more than just a usual interface layer.  

On the browser comp test, which checks how well AI agents can keep searching the web for hard-to-find information, OpenAI says GPT-5.4 improved by 17% over GPT-5.4 Pro. Waste is 89.3%, which OpenAI calls a new state of the art.  

On OSWOLD, the OSWOLD verified test, which measures desktop navigation using screenshots and keyboard or mouse actions. OpenAI reports GPT-5.4 achieved a 75.0% success rate. This is up from 47.3% for GPT-5.2 and exceeds the reported human performance of 72.4%. Any verified GPT-5.4 achieves 67.3% success with both DOM- and screenshot-driven interaction, compared to 65.4% for GPT-5.2 on online Mind2Web. OpenAI reports 92.8% success using screenshot-based observations alone.  

OpenAI also links computer use to better vision and document handling. On the MMMU Pro test, GPT-5.4 reached 81.2% success without using extra tools, compared to 79.5% for GPT-5.2. OpenAI says it did this using far fewer thinking topics. The reported error is 0.109, down from 0.140 for GPT-5.2. The post also describes expanded support for high-quality image inputs, including an original detail level up to 10.24M pixels.  

OpenAI describes GPT-5.4 as designed for longer multi-step workflows. This means it acts more like an agent that tracks progress across multiple actions rather than just answering one question at a time, as a typical chatbot does.  

Tool Search and Improve Tool Orchestration 

OpenAI notes that adding every tool definition to the prompt increases cost, slows responses, and clutters context.  

GPT-5.4 introduces tool search in the API as a structural fix. Instead, GPT-5.4 adds tool search to the API as a solution rather than returning both definitions at once. The model now gets a short list of tools and a search feature. It only loads full tool details when needed.  

On the Scales MCP Atlas Benchmark (36 MCP servers), tool search reduced token usage by 47% while maintaining the same accuracy as exposing all functions directly in context.  

The 47% reduction only applies to the tool search set up in the test. It does not mean that GPT-5.4 always uses 47% fewer tokens per task.  

Improvements For Developers And Coding Workflows 

OpenAI says GPT-5.4 builds on GPT-5.3 Codex, enabling more efficient code and better multi-step task handling for developers.  

GPT-5.4 matches or outperforms GPT-5.3 Codex on SWE Bench Pro, delivering faster and more reliable performance on complex coding tasks.  

Codex boosts workflow control. Fast mode can increase GPT-5.4 speeds by up to 1.5x, accelerating tasks without losing capability.  

OpenAI is introducing an experimental Codex skill called Playwright (interactive). This tool demonstrates the integration of coding with computer use, allowing users to visually debug web and Electron applications and test apps at the command line.  

OpenAI for Microsoft Excel and Google Sheets 

With GPT-5.4, OpenAI launches secure AI tools in ChatGPT for businesses, enabling advanced, accurate financial modeling and reasoning within familiar platforms.  

ChatGPT for Excel and Google Sheets (coming soon). Let users seamlessly build, analyze, and update complex financial models directly within spreadsheets, increasing efficiency and accessibility.  

The suite also introduces new ChatGPT app integrations, consolidating market, company, and internal data into a single workflow. OpenAI sites, FactSet, MSCI, Third Bridge, and Moody’s are examples.  

OpenAI is also adding reusable skills for common finance tasks, such as:  

  • Earnings previews  
  • Comparable analysis  
  • DCF analysis  
  • Drafting investment memos  

OpenAI supports its finance focus with an internal benchmark showing model results improved from 43.7% with GPT-5 to 88.0% with GPT-5.4 on its investment banking test.  

Measuring AI Performance Against Professional Work 

OpenAI uses benchmarks designed to resemble real office work rather than puzzles on GDP, which assesses knowledge work across 44 jobs. OpenAI reports that GPT 5.4 matches or outperforms industry professionals in 83% of cases, compared to 71% for GPT 5.2.  

OpenAI underscores improvements in structured tables, formulas, clear writing, and design quality, helping users overcome AI workflow challenges.  

In an internal test of spreadsheet modeling tasks similar to those performed by junior investment banking analysts, GPT 5.4 achieved an average score of 87.5%, while GPT 5.2 scored 68.4%.  

On a set of presentation evaluation prompts, OpenAI reports that human raters favored GPT-5.4’s presentations 68.0% of the time over those from GPT-5.2, attributing this to a preference for stronger aesthetics, greater visual variety, and more effective image generation.  

Improved reliability and reduced hallucinations 

OpenAI describes GPT-5.4 as its most factual model yet and links that claim to a practical data set: de-identified forms that users previously flagged as containing factual errors. OpenAI reports GPT-5.4’s individual claims are 33% less likely to be false, and its full responses are 18% less likely to contain any errors. In a comment to venture-only early GPT-5.4 tester Daniel Sweiki from Walleye Capital, it was said that GPT-5.4 boosted accuracy by 30 percentage points on internal finance and Excel sheets. He credits this to better automation for model updates and scenario analysis.  

Brandon Foody, CEO of Mercor, says GPT-5.4 is the best model his company has used. He adds that it now needs Mercor’s Apex Agents benchmark for professional services, especially for assignments such as slide decks, financial models, and legal analysis.  

The Wider Shift 

With its release and follow-up clarifications, GPT-5.4 is presented as a model designed to do more than just generate answers. It aims to assist ongoing professional tasks that need tool coordination, computer use, a longer context, and output that matches what people use in their jobs.  

OpenAI’s focus on the Token Efficiency tool search, native computer use, and fewer user-reported errors is to make agent-based systems more practical for everyday use by lowering the cost of reads/writes. Whether it’s a person re-prompting an agent using another tool or a workflow running again after a failed attempt, these improvements help make the technology more reliable.

Source: OpenAI launches GPT-5.4 with native computer use mode, financial plugins for Microsoft Excel, Google Sheets 

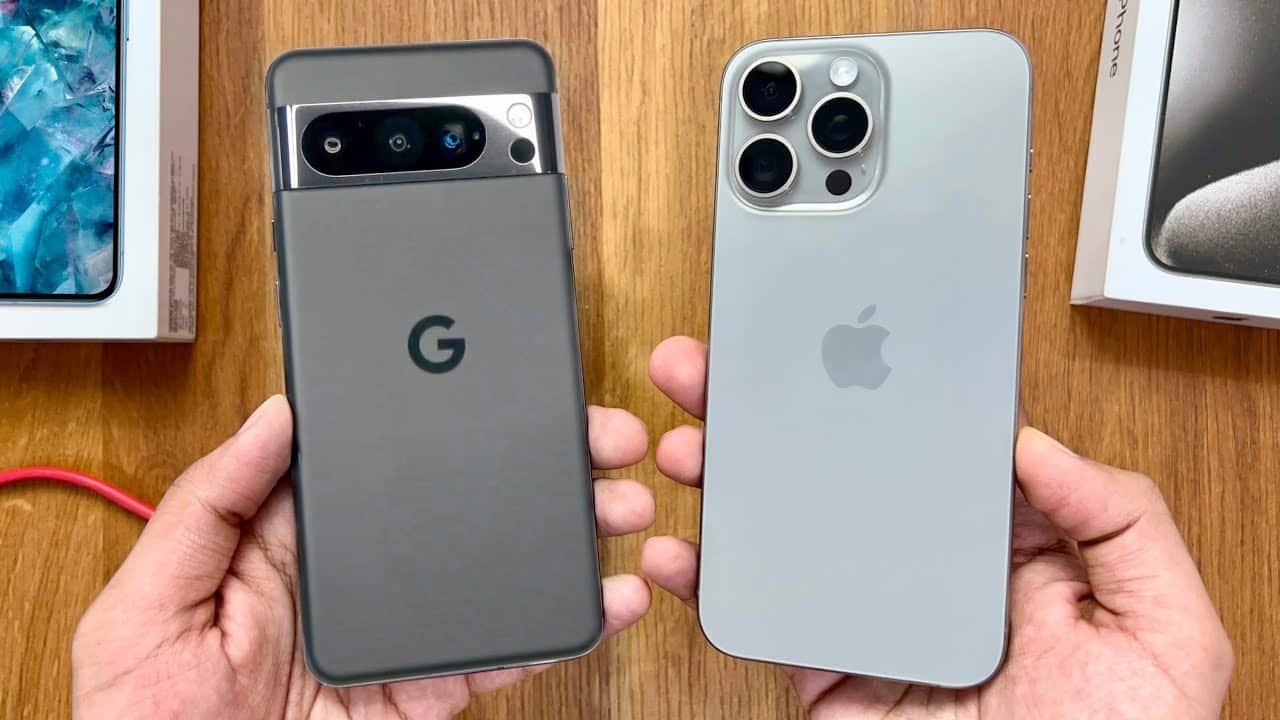
In 2026, when deciding iPhone 15 vs Pixel 8, consumers will be choosing between Apple’s refinements to its ecosystem and Google’s advancements with its AI on a mid-range device following their release in 2023. For American consumers, they are benefiting from Swappa deals, costing $446 on average for the iPhone 15 (128GB) and $278 for the Pixel 8, and tables are being utilized to weigh design, performance, camera in the world of Android phones versus iPhones. 

This article acts as a guide comparing iPhone 15 and Pixel 8 with respect to design, performance, camera, and battery life. 

Design and Build 

In comparison, the iPhone 15 has dimensions of 5.81 x 2.81 x 0.31 inches, with a total weight of 6.02 ounces. In this case, the iPhone has a premium aluminum frame, with a front and back consisting of Ceramic Shield glass and IP68. Similarly, the Pixel 8 has dimensions of about 5.94 x 2.80 x 0.35 inches and a total weight of 6.74 ounces. Its front, back, and sides are made of Gorilla Glass Victus and aluminium. 

Both feel compact and premium in hand, which are great for one-handed usage. 

Feature iPhone 15  Pixel 8  
Dimensions 5.81 x 2.81 x 0.31 in 5.94 x 2.80 x 0.35 in 
Weight 6.02 oz 6.74 oz 
Build Aluminum, Ceramic Shield Aluminum, Gorilla Glass Victus 
IP Rating IP68 IP68 
Colors Black, Blue, Green, Yellow, Pink Obsidian, Hazel, Rose 

Display Specifications 

Apple’s 6.1-inch Super Retina XDR on the iPhone 15 features a peak brightness of 2,000 nits with a 60Hz refresh rate for optimum display quality outdoors. The Google Pixel 8, however, features a 6.2-inch Actual OLED display with a 120Hz refresh rate, along with HDR10+ and 2,000 nits peak brightness. 

The Pixel’s high refresh rate is better suited for gamers and scrollers, and iPhone’s screen excels at color accuracy. 

Aspect iPhone 15   Pixel 8   
Size 6.1-inch OLED 6.2-inch OLED 
Refresh Rate 60Hz 120Hz (LTPO) 
Peak Brightness 2,000 nits 2,000 nits 
Resolution 2556 x 1179 2400 x 1080 
Protection Ceramic Shield Gorilla Glass Victus 

Performance Breakdown 

The iPhone 15 is powered by the A16 Bionic chip and 6GB RAM, which provides better performance for its multitasking and gaming requirements and delivers high scores on benchmark tests such as Geekbench. Pixel 8’s Tensor G3 chip and 8GB RAM are optimized for AI performance but are slightly behind Apple’s performance capabilities. 

With 2026, they work well for everyday apps, though iPhone appears snappier for video editing. 

Metric iPhone 15 (A16)  Pixel 8 (Tensor G3)   
CPU Cores 6-core (3.46GHz max) 9-core 
RAM 6GB 8GB LPDDR5X 
Storage Options 128/256/512GB 128/256GB 
Benchmark (Geekbench Single) ~2,500 ~1,700 

Camera Shoot-Out 

The iPhone 15 features a 48MP primary + 12MP ultra-wide lens, which excels in natural color and stabilization features like video stabilization, with a recording capability of 4K at 60 fps. Pixel 8 packs a 50MP primary + 12MP ultra-wide lens and uses computational photography for better low-light photos and features like Magic Editor. 

Pixels generally take over in portraits and night mode; iPhone leads in video consistency. 

Camera Feature iPhone 15   Pixel 8   
Main Sensor 48MP 50MP 
Ultrawide 12MP 12MP 
Front 12MP 10.5MP 
Video Max 4K@60fps 4K@60fps 
Key Strength Video, consistency Low-light, AI features 

Battery Life Comparison 

The Pixel 8 features a 4575 mAh battery that lasts longer than the 3349 mAh battery life in the iPhone 15 by up to two hours when browsing or streaming, as tested. They all have wireless charging capabilities, with the Pixel 8 supporting 27W charging via a wire. 

Expect all-day battery performance from each, with Pixel protecting the edge. 

Test Scenario   iPhone 15 Pixel 8 
Browsing ~10 hours ~12 hours 
Video Streaming ~8 hours ~10 hours 
Capacity 3,349mAh   4,575mAh   
Wired Charging ~20W 27W 

Software and Updates 

iPhone 15 is running iOS 26 as of late 2025, for which Apple promises 5-to-6 years of iOS updates until 2028 or 2029. The Pixel 8 on Android 15 also gets 7 years of OS and security patch updates until 2030, including Gemini AI. 

Comparison between Android and iPhone:  

While Pixel provides customization, the iPhone offers privacy and seamless usage. 

Update Policy iPhone 15   Pixel 8  
Years Supported 5-6 years 7 years 
Current OS iOS 26 Android 15 
AI Features Apple Intelligence Gemini Nano 

Pricing in 2026 

On average, as of February 2026, an unlocked iPhone 15 128GB is priced at $446 on Swappa, dipping to $388 as it is sold. The average price for a 128GB Pixel 8 is $268, dipping to $257 as it is 

Prices will depend on carriers; look for sales on carriers like Verizon and T-Mobile. 

Storage/Carrier   iPhone 15 Avg Price Pixel 8 Avg Price 
128GB Unlocked $446 $278 
256GB Unlocked $482 $301 
128GB Verizon/T-Mobile $400-$411 $234-$242 

Google Pixel Features 

Also, Pixel stands out with exclusive features like Call Screen, Live Translate, and Best Take for Group Photos. These AI technologies put Android vs iPhone in the spotlight in terms of productivity. 

Feature Description  
Magic Editor AI photo editing: Move, erase, or replace objects 
Best Take Swap faces in group photos for everyone’s best smile 
Call Screen Google Assistant handles calls, transcribes spam 
Live Translate Real-time call/text translation in 40+ languages 
Audio Magic Eraser Removes background noise from videos 
Face Unblur Sharpens blurry faces in old photos 
7 Years Updates Android OS + security patches to 2030 
Gemini Nano AI On-device AI for summaries, smart replies 

Ecosystem Fit 

For instance, the iPhone 15 can integrate well with MacBooks, AirPods, and Apple Watches. Pixel 8 can integrate well with Google services, Wear OS smartwatches, and Chromebooks. 

Final Pick 

Pick the iPhone 15 for refined performance, video, and Apple integration; go with the Pixel 8 if you are looking for better battery life, cameras, support updates, and AI at an affordable price. They retain their worth in 2026. 

 In 2026, the iPhone 15 excels as a choice for users already invested in the Apple ecosystem because it excels in video recording, A16 speed, and Mac and AirPod connections that American consumers cherish for reliability. However, the Google Pixel 8 outperforms in battery life, camera AI wizardry like Magic Editor, and seven years of updates and that alone makes this phone a bargain at $278 compared to the iPhone at $446 on Swappa especially when prioritizing battery life as an Android consumer. 

Ultimately, the choice between the iPhone 15 or Pixel 8 will be made by your lifestyle, where the iPhone will provide a smooth visual experience, or the Pixel will provide camera, battery, and Google Pixel features with a feature evolution beyond 2030. Both 2023 flagships remain solid purchases against 2026 pricey releases, ensuring you get the best of both worlds without the regret known as a flagship. 

FAQS: 

1. Is Pixel 8 battery life better than the iPhone 15 battery life? 

Yes, also, the Pixel 8’s 4,575mAh battery tends to have a longer battery life compared to the iPhone 15’s 3,349mAh battery by an hour or longer in terms of surfing and watching videos. 

2. Which has a better camera in 2026? 

While the Pixel 8 has an edge in low light, as well as AI capabilities like Magic Editor, the iPhone 15 has an edge in video quality, although both offer excellent main cameras at 48/50 MP. 

3. How long will software updates last?  

Pixel 8 gets 7 years of Android updates until 2030, which is faster than the 5-6 years of iOS support until 2028-2029 for the iPhone 15. 

4. What is the price difference in February 2026? 

The average price for a Pixel 8 (128GB) on Swappa stands at $278 compared to the $446 cost of the iPhone 15. 

5. iPhone or Pixel, which one do I choose?  

Pick iPhone 15 for Apple devices integration; choose Pixel 8 for Google services and Wear OS, depending on your Android vs iPhone preference. 

Sources-  

Google Pixel 8 vs iPhone 15: the key differences | TechRadar 

iPhone 15 vs. Google Pixel 8: What we expect | Tom’s Guide 

iPhone 15 beats the Google Pixel 8 — here’s 3 key reasons why | Tom’s Guide 

Samsung Electronics has started early trials of EUV lithography at its Taylor, Texas, foundry. Equipment testing begins soon.  

Scheduled for March 2026, tests are being prepared for 2nm chip production. Samsung brings GAA manufacturing to the US, competing with TSMC.  

Important Information About The Trial And Production Plan Includes: 

  • Trial timeline: EUV machine trials will start in early 2026.  
  • Production focus: Taylor will shift from older processes to 2nm technology to support high-performance AI chips for clients such as Tesla.  
  • Early tech adoption: EUV pellicles at Texas aim to boost yield and efficiency.  
  • Initial reports expected 2nm production by late 2026, but full-scale mass production may shift to early 2027 due to process setbacks.  
  • Strategic change: Samsung will use Taylor, which is larger than the combined Hwaseong and Pyeongtaek Korean sites, to fully serve AI chip makers.  

The Texas facility has a temporary Certificate of Occupancy, letting Samsung install and test equipment. These trials help stabilize 2nm yields to meet strict requirements.  

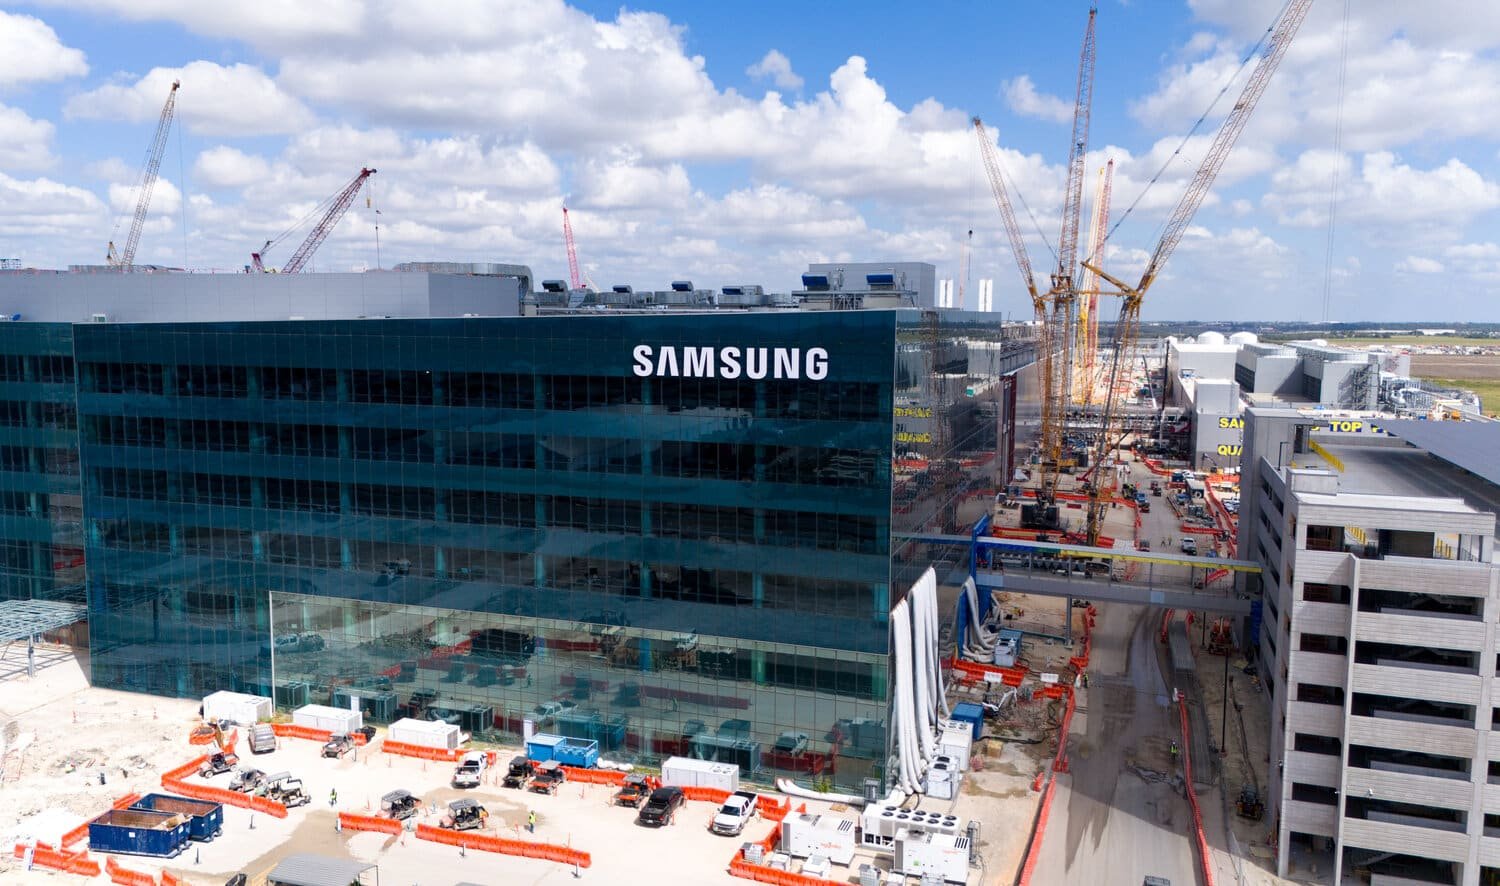
Samsung is preparing for a major milestone at its US semiconductor factory in March 2026. The company will test extreme ultraviolet lithography equipment at its Taylor, Texas, plant. This move brings Samsung closer to producing advanced chips, including Tesla’s next-generation chips.  

Preparations are underway for advanced chip production at Samsung’s Taylor plant.  

Last month, reports said Samsung would install its first manufacturing equipment and launch trial operations at Taylor in March 2026. The company plans staged equipment installation and full operations in the second half of 2026.  

The report indicates Samsung may seek temporary occupancy authorization from authorities for Plant 1, enabling use before construction ends if requirements are met. Engineers from headquarters are at Taylor to rapidly stabilize production yields.  

Construction at the Taylor plant involves about 7,000 workers daily. Approximately 1,000 are building a 6-storey office, expected to finish in the second half of 2026. The facility covers about 4.8 million square meters, larger than the semiconductor complexes in Pyeongtaek and Hwaseong. The plant will focus on advanced processes, including 2nm technology. ASML supplies the essential EUV equipment.  

Samsung has secured initial orders from Taylor, producing the autonomous-driving chips AI-5 and AI-6 for Tesla. If standards are met, Samsung may receive more Tesla orders and attract other clients.

Source: Samsung to Begin EUV Trials at Taylor Fab in March, Make Chips for Tesla 

At its Vision 2025 conference, Intel revealed it has started risk production of its advanced 18A process node. This is a pivotal step marking the beginning of new low-volume test manufacturing for this technology.  

Intel’s Kevin O’Buckley, Senior Vice President of Foundry Services, made the announcement. Intel nears full completion of its five nodes in four years. This initiative was launched by former CEO Pat Gelsinger as part of Intel’s quest to retake the semiconductor crown from TSMC. The conference also marks the first time new CEO Lip-Bu Tan has taken to the stage as Intel’s leader.  

Launched in 2021, Intel’s four-year 5N4Y plan shifted focus. The company canceled high-volume 20A production due to cost. However, the 18A node is nearing completion. The plan aims to make process nodes available for production, not necessarily immediate high-volume manufacturing.  

Risk production is a key step toward launching a new process node, demonstrating Intel’s confidence that the node is nearly ready for HVM. Leading up to this stage, the company has already produced numerous 18A test chips and shutters, often prototyping multiple designs on a single wafer.  

During risk production, Intel manufactures wafers with a single chip design in low volumes. The company updates its manufacturing process and qualifies the Node and Process Design Kit (PDK) in real-life runs. Production will scale up in the second half of the year. This stage follows R&D, Design, and Prototyping.  

Risk production involves some uncertainty for customers. Yields and functionality may fall short of targets, while manufacturing techniques and tooling are optimized. During this period, customers typically produce qualification or engineering samples using the new process. These early chips may not have guaranteed yields. However, they enable customers to begin product validation and prepare for full-scale launch when high-volume manufacturing is achieved.  

Nonetheless, some customers choose to accept these risks to gain early access to the node, which enables them to improve their designs and achieve time-to-market advantages over competitors.  

Intel has not specified whether 18A risk production is for its Panther Lake processors expected later this year or for external foundry customers. However, Panther Lake will enter mass production this year and is likely the focus of risk production. The timeline aligns with Intel’s typical risk-based production to HVM schedules.  

While Intel introduced several new technologies with its canceled 20A mode, the 18A (1.8nm) chips will be the first to feature both PowerVia backside power delivery and ribbon FET gate all-around (GAA) transistors. PowerVia improves power routing performance and transistor density. Ribbon FET enhances transistor density and switching speed within a smaller area.  

Intel is also advancing its wider foundry roadmap, which includes the upcoming 14A node. It’s the first to use high NA EUV lithography. Additional node extensions will expand Intel’s foundry services portfolio to serve a wider range of applications.  

These developments come as Intel Foundry navigates changing macroeconomic conditions. For example, while Intel has delayed its Ohio expansion until 2030, the 18A risk production announcement aligns with positive reports on initial 18A wafer runs in Arizona, reinforcing the company’s adaptability.  

Industry observers anticipate further details about Intel’s future plans at the Foundry Direct Connect event in late April, which promises to provide additional context for Intel’s current risk production efforts.  

Risk production, while it sounds scary, is actually an industry-standard terminology. The importance of risk production is that we’ve gotten the technology to a point where we’re freezing it, O’Buckley explained that our customers have validated that 18A is good enough for my product, and we now have to do the risk part, which is to scale farm, making hundreds of units per day to thousands, tens of thousands, and then hundreds of thousands. Risk production is scaling our manufacturing and ensuring we can meet not just the technology’s capabilities but also those at scale.

Source: Intel announces 18A process node has entered risk production

News Summary 

  • AMD introduces Ryzen AI 400 and Pro 400 series processors. The Ryzen AI 400 series targets consumer and commercial devices with up to 60 NPU TOPS for Co-Pilot+ PCs and AI features. The Pro 400 series is aimed at business users seeking enhanced manageability and security.  
  • AMD introduces new Ryzen AI Max+ SKUs, bringing high-performance AI and graphics to ultra-thin notebooks, workstations, and small-form-factor devices for creation, gaming, and AI development.  
  • AMD unveils the Ryzen AI Halo A Mini PC, delivering Ryzen AI Max+ performance for AI developers and offering an out-of-the-box experience that accelerates AI innovation at the edge.  
  • AMD announced the Ryzen 7 1950X3D, its flagship gaming processor based on Zen 5 architecture with AMD 3D V-Cache, designed for enthusiasts prioritizing top-tier gaming performance. This model stands apart from AI-focused SKUs.  
  • AMD sees strong year-on-year growth in OEM adoption of Ryzen AI processors, with more systems launching across consumer, commercial, and gaming segments throughout 2026.  
  • AMD announces AMD ROCm 7.2 software for Windows and Linux, bringing seamless support for Ryzen AI 400 series processors and inclusion in ComfUI.  

At CES 2026, AMD also revealed its latest mobile and desktop processors, expanding its client computing portfolio. This launch underscores AMD’s drive to lead in AI capabilities, premium gaming performance, and commercial-ready features, bringing these advances to more systems and users than ever before.  

AMD introduced the new AMD Ryzen AI400 series for Co-Pilot Plus PCs and Ryzen AI Max+ processors for premium ultra-thin and light notebooks and small-form-factor desktops. The company also announced the Ryzen AI Pro 400 series, enabling AI acceleration, modern security, and enterprise-class manageability to meet the needs of today’s business landscape. Recognizing AI as central to the PC experience, AMD is strengthening its hardware portfolio with AMD Ryzen AI Halo, the company’s first branded AI developer platform. AMD pairs this hardware with new ROCm 7.2 software support for Ryzen AI 400 series processors and an AI bundle for AMD Software Adrenaline Edition, ensuring AI adoption and development are more accessible than ever.  

AMD announces the Ryzen 7 9850X3D, an improved gaming CPU with a higher boost clock built on Zen 5 and 3D V-Cache. Radeon users get FSR Redstone for ML frame generation and upscaling in new AAA games.  

The PC is being redefined by AI, and AMD is leading that transformation, said Jack Huynh, senior vice president and general manager of the AMD Computing and Graphics Group. Across consumer, commercial, and enthusiast teams’ systems. We are delivering platforms that bring high-performance computing, leadership AI, interactive graphics, and a growing software ecosystem that strengthens developers and creators, so intelligence is built in, performance and effectiveness scale smoothly, and innovation reaches every form factor. Our full-stack approach is coming to life, enabling a smarter, faster, and more absorbing experience for users today and tomorrow.  

AMD ROCm Software Experience Developer Access 

AMD announced that AMD ROCm, the open software platform, now supports Ryzen AI 400 series processors and is available for download through Confi UI. The upcoming AMD ROCm software 7.2 release will extend compatibility throughout both Windows and Linux, and new PyTorch builds can now be easily accessed through AMD software for simplified deployment on Windows.  

Over the past year, AMD ROCm software has delivered up to a five times improvement in AI performance. Platform support has doubled across Ryzen and Radeon products in 2025, and availability now spans Windows and additional Linux distributions, resulting in a year-on-year increase of up to 10x in downloads. Together, these updates make AMD ROCm software a more powerful and accessible foundation for AI development, reinforcing AMD as a platform of choice for developers to build the next generation of intelligent applications. 

Source: AMD Expands AI Leadership Across Client, Graphics, and Software with New Ryzen, Ryzen AI, and AMD ROCm Announcements at CES 2026 

Built for reliable AI in production, GPT 5.4 offers stronger reasoning, dependable execution, and scalable agent workflows.  

We are excited to share that OpenAI’s GPT-5.4 is now available in Microsoft Foundry. This model helps organizations move from planning to reliably completing work in real production settings. As AI agents handle longer, more complex workflows, consistency and follow-through are just as important as they entail. GPT-5.4 offers stronger reasoning and built-in computer-use features to support automation and reliable execution across tools, files, and multi-step workflows.  

GPT-5.4 Enhanced Dependability in Production AI 

GPT-5.4 is designed for organizations running AI in production, where consistency, instruction-following, and context retention are crucial. It advances reasoning, coding, and agent workflows to help AI not just plan but complete tasks with fewer interruptions and less supervision.  

GPT-5.4 is more stable during extended interactions than earlier versions, giving teams confidence to depend on agent-based AI for daily needs.  

GPT-5.4 brings new capabilities created for production-grade AI:  

  • It provides more consistent reasoning, maintaining clear intent across complex, multi-step interactions.  
  • Instruction alignment is improved, with less need for tuning and oversight.  
  • Performance is faster, making workflows more responsive for real-time use.  
  • It includes built-in computer-use features for organizing tools, accessing files, extracting data, running code safely, and handling tasks between agents.  
  • Tool use is more reliable, reducing the need for prompt tuning and human monitoring.  
  • It generates higher-quality outputs like documents, spreadsheets, and presentations with a more consistent structure.  

These improvements ensure more predictable AI performance for longer, complex tasks.  

Turning Capabilities Into Actual Results 

GPT-5.4 delivers practical value in production, where reliable task completion is critical:  

  • Agent-driven workflows such as customer support, research assistance, and business process automation  
  • Enterprise Managed Work, including drafting documents, analyzing data, and generating presentation-ready outputs.  
  • Developer workflows spanning code generation, refactoring, debugging, support, and UI scaffolding  
  • Extended thinking tasks where logical uniformity must be preserved across longer interactions  

Teams using GPT 5.4 in production experience less task drift, fewer workflow failures, and improved output predictability.  

GPT 5.4 Pro: Deeper Analysis for Complex Decisions 

GPT 5.4 is an enhanced version designed for situations where deep, comprehensive analysis is critical, and it is optimized for reliable execution and follow-through in production tasks.  

Additional capabilities include:  

  • Multipath reasoning evaluation allows alternative approaches to be explored before selecting a final response.  
  • Greater cognitive depth supporting problems with trade-offs or multiple valid solutions  
  • Its improved stability supports sustained analytical tasks along long reasoning chains.  
  • It offers enhanced decision support when thoroughness outweighs speed.  

Organizations select GPT-5.4 Pro for thorough analysis of complex challenges, such as scientific research, while GPT-5.4 is ideal for reliable task execution with strong follow-through.  

Microsoft Foundry: Enterprise Grid Control From The Start 

Organizations access GPT-4 and GPT-5.4 via Microsoft Foundry, which provides controls for Responsible Production-Grade AI. Foundry simplifies policy enforcement, monitoring, versioning, and auditability, helping teams manage AI over time.  

With GPT-5.4 in Microsoft Foundry, organizations can add advanced agent features to existing systems and meet security, compliance, and operational requirements from the start. 

Source: Introducing GPT-5.4 in Microsoft Foundry 

AWS has launched a new, stateful runtime environment for AI agents in Amazon Bedrock, developed in collaboration with OpenAI. This environment supports long-running, complex AI workflows that keep context and memory across multiple steps and sessions.  

Key Features and Benefits 

This new stateful runtime marks a major change from traditional stateless AI runtimes, which handle each request separately.  

  • Persistent context and memory: agents maintain a consistent context, including conversation history, tool state, and identity boundaries. Developers no longer need to build external state management systems.  
  • Long Running Tasks: The runtime manages complex, asynchronous workloads and multi-step processes for hours or days. Agents work independently on projects like customer support, IT automation, or data processing.  
  • Simplified production deployment: teams focus on business logic as orchestration and state are fully managed by the new architecture.  
  • Integration with the AWS Ecosystem: This environment operates within the customer’s AWS environment and integrates with AWS security tools and identity systems, such as Amazon Cognito, as well as governance tools.  
  • Powered by OpenAI Models: The Runtime Environment incorporates models from OpenAI that have been specifically optimized for AWS and are offered through Amazon Bedrock as part of the AWS OpenAI partnership. Microsoft Azure will still be the only provider of stateless OpenAI APIs.  

Impact on Enterprise AI 

This AWS OpenAI partnership indicates a shift toward agentic infrastructure as a platform for businesses. This means:  

  • Accelerated development: It reduces the time to production-ready AI agents from months to weeks.  
  • Improved capabilities: It allows for more advanced applications, such as customer support across multiple systems, sales operations workflows, and internal IT automation with approvals and audits  
  • Governance and control: The architecture provides a managed pipeline using an AI-driven lifecycle (AI-DLC) framework that assesses agents for performance, cost, and security before deployment.  

The stateful runtime environment should be available through Amazon Bedrock in the next few months.  

AI agents are great at reasoning, but the real challenge is making sure they can reliably handle multi-step tasks over time using real tools and systems with proper controls.  

Today, we are making this easier by partnering with Amazon to launch a new stateful runtime environment that runs directly on Amazon Bedrock. AWS customers can use this environment, powered by OpenAI models and optimized for AWS, to support agent workflows with the state reliability and governance needed for production.  

Making It Easier to Bring Agents Into Production 

Many Agent prototypes based on stateless APIs tackle simple use cases:  

  • One prompt  
  • One answer  
  • Maybe one call to a tool.  

Production work is different. Real workflows unfold across many steps. They require context based on previous actions. They depend on multiple tool outputs, approvals, and system state, and need trusted guardrails to secure environments.  

With stateless APIs, development teams must build the orchestration layer themselves. They need to decide how to store state, call tools, handle errors, and safely resume long-running tasks.  

The Stateful Runtime Environment is built to make this easier. It runs within your AWS environment and works well with AWS services. Instead of assembling separate requests, your agents can now automatically handle complex tasks with context-carrying forward memory, workflow state, environment, use, and permission boundaries.  

What Can You Do With This 

Now it’s easier to build solutions like:  

  • multi-system customer support  
  • sales operational workflows  
  • internal IT automation  
  • financial processes that include approvals and audits  

Faster Time to Production for Multi-Step Workflows 

When the runtime manages orchestration and state across steps, teams can focus on the workflow and business logic rather than building additional support systems.  

Designed For Long-Running Tasks 

Stateful tasks are built to run reliably over time, keeping the context and control boundaries needed for multi-step work.  

AWS Native Deployment and Governance 

To understand how this stateful runtime can benefit your organization, reach out to your OpenAI team or request a contact from us today.

Source: Introducing the Stateful Runtime Environment for Agents in Amazon Bedrock 

NVIDIA recently released the GeForce Game Ready driver 595.59 to improve performance in Resident Evil: Requiem, but, according to a machine translation, this update has caused problems with RTX 3000-series and newer cards. Users report that the driver only detects one fan on their GPUs.  

Some people suspected that third-party apps like MSI AfterBurner were causing the issue; however, another user experienced the same problem even without AfterBurner installed.  

NVIDIA appears to have removed the driver update, as it is no longer on their website (a driver is the software that allows the operating system to communicate with your graphics card). If you have already installed the latest driver and are experiencing problems, you should roll back to the previous version. To do this in the NVIDIA app, click the three dots in the Drivers tab.  

If you do not have NVIDIA’s software open, Windows Device Manager, expand Display Adapters, and double-click your GPU in the Properties window. Go to the Drivers tab and select Roll Back Driver. If that option is unavailable, NVIDIA recommends uninstalling the GPU driver and reinstalling the latest available version to solve the issue, since the problematic driver has been removed.  

The new NVIDIA 595.71 driver has brought new problems not present in last week’s troubled 595.59 release, which NVIDIA pulled a few days ago. As a result, several users and at least one YouTuber have found that the 595.71 driver limits GPU overclocking on many RTX 40 and 50 series cards. The most affected models lose about 200 MHz of overclocking headroom compared to earlier drivers.  

The issue seems to be artificial voltage limits added to the in driver 595.71, either by mistake or on purpose. YouTuber bang4buckpcgamer showed that his Asus TUF Gaming RTX 5090 lost 65 mV of voltage headroom, keeping the card below 1 W. This change reduced his overclocking headroom by about 171 MHz, dropping from 3165 MHz to just under 3000 MHz. This only happens when the offset is about 150 MHz. With a 150 MHz offset or less, the GPU does not restrict voltage and can reach up to 1.060 V. Similar issues have also been shared on the NVIDIA forums. One user with an RTX 5080 reported that their GPU used to hit 3,100-3,200 MHz with previous drivers and can now only reach 2,395 MHz with 595.71.80 owner published their own 3DMark scores with the previous 591.86 driver compared to 591.71 with a hefty 450 MHz GPU overclock. They found the new driver was running the GPU 300 lower and pulling 43 fewer watts than from 403W to 360W.  

However, not all RTX 50 series GPUs appear to be affected. Curiously, three commentators on bang4buckpcgamer’s aforementioned YouTube video with a Gigabyte Aorus Master RTX 5090 graphics card report having no restrictions whatsoever. Another RTX 5090 owner with a PNY EPYC OC variant reported no issues achieving a max overclock of 3157 MHz with the latest driver. Two RTX 5070 owners, one with an Asus variant and the AMD MSI Gaming Trio OC, also reported no issues.  

This variability suggests that some owners may simply be lucky with their hardware, so their cards’ voltage and frequency scaling are not affected by this bug. Still, the new issue has led to many angry comments from gamers, with some blaming AI code for causing problems with Nvidia’s drivers. NVIDIA has officially not recognized the issue yet, but the artificial voltage limits do appear to be a bug rather than an official change. The NVIDIA patch notes don’t mention any new voltage limits, and certain GeForce RTX GPU models apparently aren’t subject to any limitations when running 595.71. We’ll have to see whether the company issues another corrective release or a fixed driver in the near future, along with any further explanation of the issue.

Source: Nvidia rolls back its latest driver update — Game Ready Driver 595.59 reportedly causes fan issues on RTX 3000, 4000, and 5000-series GPUs