Santa Clara, California 

Every quarter, a Fortune 500 legal team spends over $100,000 on cloud egress fees. This cost is not for storage or large-scale computing, but only for moving confidential documents to and from a vendor’s inference endpoint. The data could have stayed on-site. NVIDIA NIMs were created to solve this problem. 

NVIDIA NIMs, which stand for NVIDIA Inference Microservices, are pre-optimized containers for enterprises. They include an extensive language model, its inference engine, validated quantization profiles, and all necessary runtime dependencies in a single package. This is not simply a prototype; it is meant for actual use. The key feature is that the entire inference process can run on a workstation right next to an engineer, without any data going to the cloud. 

What Nvidia NIMs Actually Are—and Why the Container Design Matters 

At their core, Nvidia NIMs are an orchestration layer for vLLM, a high-performance inference engine, packaged for enterprise use. The NIM LLM 2.0 architecture uses a clear ‘one container, one backend’ approach. Earlier versions combined TensorRT-LLM, Triton, and vLLM into a single container, but version 2.0 keeps each backend separate for more predictable results and easier coordination with upstream updates. This lucidity is especially important in regulated industries where security teams need to certify every software component before deployment. 

The internal structure has three layers. The first is the orchestration layer, called nim-llm, which manages startup, merges configuration settings from command-line flags and environment variables, and adds enterprise features like Low-Rank Adaptation (LoRA) adapters. Below that is nimlib, which selects the best hardware profile, downloads models, and manages API endpoints. The inference engine, vLLM, runs on an internal port and is never exposed outside the container. A lightweight nginx proxy handles external routing, TLS termination, and CORS. If either the inference engine or the proxy stops unexpectedly, the container shuts down so the orchestrator can restart it properly. 

This design isn’t merely for the sake of abstraction. It works like circuit breakers in electrical systems, ensuring the system fails predictably rather than without warning. 

On Device Optimization: The Shift That Changes Enterprise Risk Calculus 

People often treat ‘on-device optimization‘ as a minor technical detail, but it deserves attention at the highest levels of an organization. When a model runs locally, either on an RTX-equipped workstation or a GPU cluster in a private data center, the organization keeps full control of its data. There are no API logs at outside vendors, no inference data sent elsewhere, and no risk from shared infrastructure. 

For example, a pharmaceutical R&D team working with unpublished compound data faced a tough choice: accept the compliance risks of cloud inference or spend months building a custom inference system. With Nvidia NIMs on-device local optimization, deployment collapses at that timeline. According to NVIDIA’s own benchmarks, a NIM can be deployed in under five minutes with a single container pull. The December 2024 NIM 1.4 release was 2.4 times faster than the previous version, and independent tests show NIM can process about 1,201 tokens per second on Llama 3.1 8B, compared to 613 tokens per second on a similar H100 setup. Cloudera also reported a 36 times performance boost with NIM-integrated workloads. 

These improvements are not purely theoretical. They are real results achieved on hardware that enterprise teams already have. 

When a NIM container is deployed, it checks the local hardware and automatically picks the best model version for the GPU. For supported NVIDIA GPUs, it downloads an optimized TensorRT engine and runs inference with TRT-LLM. For other NVIDIA GPUs, it uses vLLM by default. The system makes these choices automatically, not the engineer. This hardware-aware selection is what makes on-device optimization practical for workstations, not just for specialized inference clusters. 

Local AI Infrastructure: The Hidden Cost Savings Executives Are Beginning to Notice 

Many people assume cloud inference is cheaper because it avoids upfront costs. However, this idea does not hold up when you look at large-scale egress fees. Local AI infrastructure, such as GPU-accelerated workstations and on-premises clusters running containerized inference, changes the cost model from unpredictable and unclear to fixed and easy to track. 

NIM architecture supports this shift by providing a model-free container option in version 2.0. Instead of including a pre-packaged model manifest, a model-free NIM creates its manifest at runtime, pulling models from NGC, Hugging Face, Amazon S3, or a local directory. For enterprise security teams, this means they only need to approve one container for multiple models. Security and compliance reviewers check one artifact, and the approved container can then serve any model the team sets up. This significantly reduces overhead for organizations that follow FedRAMP, HIPAA, or SOC 2 requirements. 

The monitoring features are also designed for enterprises. Prometheus-compatible metrics, such as request latency, throughput, and GPU usage, are available at /v1/metrics. Health checks indicate whether the container is running and whether the model is ready. Structured JSON logs with tracing headers fit easily into existing SIEM and APM systems. When an enterprise uses local AI infrastructure, it does not lose visibility; it actually gains more, since every inference event stays on hardware the organization controls and monitors. 

NVIDIA NIMs on Device Local Optimization Deployment: What the Architecture Permits for Engineering Teams 

The benefits of Nvidia NIMs with local optimization go beyond just saving money and meeting compliance needs. They also expand what engineering teams can do. With local inference, iteration cycles are much faster. A machine learning engineer testing a fine-tuned Llama 3 model does not have to wait for API limits or deal with shared cloud quotas. The model runs directly in a container on the workstation, making the feedback loop much quicker. 

NVIDIA’s NIM Anywhere project on GitHub takes this even further by combining NIM containers with a retrieval-augmented generation (RAG) setup that runs fully on local GPU resources. For example, a company with a confidential internal database that cannot be shared with third-party APIs can connect its language model to that database locally. This allows for accurate, context-aware responses without giving up control of the data. 

The OpenAI-compatible API endpoints that NIM exposes by default mean that teams do not have to rewrite application code when shifting from cloud inference to local deployment. LangChain, LlamaIndex, and Haystack integrations that pointed at a hosted endpoint simply redirect to the local NIM container. That portability is architectural confidence: the organization can move between deployment modes without accumulating technical debt. 

The Risk of Standing Still 

In the next two years, the companies under the most pressure will not be those without AI strategies, but those whose strategies rely on always-on cloud use. Data residency rules are getting stricter in the EU, India, and Southeast Asia. Large-scale inference costs are not dropping as fast as expected. The performance gap between optimized local deployment and general-purpose cloud inference is growing, not shrinking. 

NVIDIA NIMs provide a proven solution to a question many enterprise architecture teams have put off: What does production-grade AI look like when data must stay on-site? The container architecture is complete, the runtime is well documented, and the hardware-aware profile selection works automatically. 

The workstation on an engineer’s desk is no longer the limiting factor. Now, the real challenge is whether organizations are willing to rethink how they deploy AI.

Source: Nvidia Newsroom 
Redmond, Washington 

On October 9, 2025, a cache overload during routine maintenance caused an Azure Front Door outage that affected enterprise customer service operations worldwide. Thousands of AI-powered support agents stopped working. Tickets accumulated. Revenue slowed. The incident lasted for hours, which seemed endless to organizations relying on real-time customer engagement through Microsoft Azure AI. This event revealed a vulnerability that every AI-focused business worries about: a single infrastructure failure quietly shutting down the intelligent systems they depend on. 

Microsoft took notice and responded by rethinking its system architecture. 

How Microsoft Azure AI Redrew the Line Between Fragile and Resilient 

Traditionally, AI infrastructure robustness was handled reactively. When a system failed, engineers found the cause and fixed it. This approach was fine for static web services, but it does not work for large language model deployments. If there is a token-per-minute (TPM) quota breach or a regional compute spike, the system does not show a clear error; instead, it freezes. Customer service agents built on Microsoft Azure AI would stop mid-conversation, providing no response or an error, leaving users waiting while operations teams rushed to fix the problem. 

The problem gets worse at scale. For example, a major retailer running 50,000 AI agent sessions during a busy sales event does not see token overload as just a number. Instead, one overloaded deployment causes request queues to back up, latency to increase, and upstream systems to time out. Within minutes, an entire regional customer support team can go offline. The difference between a 200-millisecond response and a 30-second delay is not simply about speed; it can mean losing customers. 

Microsoft’s answer to this problem came through two parallel engineering tracks: the Azure Resiliency platform, introduced at Microsoft Ignite 2025, and automated agent failovers baked directly into Microsoft Foundry’s Agent Service. 

The Mechanical Architecture of Automated Agent Failovers 

At the infrastructure level, automated agent failovers on Microsoft Azure AI use what Microsoft calls a warm standby model. Instead of starting backup systems only after a failure, the system maintains a mirrored environment in a secondary region. This standby account is fully networked, synchronized, and prepared to take over. When Azure Service Health detects a regional issue, automated scripts trigger failover procedures immediately, without waiting for human approval. 

Details are important. The standby environment copies the primary region’s network setup. Egress controls and firewall rules stay in sync at all times, not just during failover. This is not a cold backup that takes 20 minutes to set up. Instead, it is a warm environment that can handle traffic within the recovery time set by the business continuity plan. 

Automated agent failovers also work with Azure Site Recovery, which now supports up to five times higher churn rates, or about 500 MB per second per virtual machine. This allows the platform to handle high-IOPS workloads during the busy moments right after a regional shift. Microsoft also added support for Premium SSD v2 and Ultra Disks to prevent slowdowns during recovery, since an agent that survives a failover but runs much more slowly is only slightly better than one that stops working. 

Intercepting Token Overload Before the Freeze 

A more complex problem is token overload, not just regional failure. Regional outages are clear and easy to detect. Token overload is harder to spot. It builds up slowly, appears as elevated latency, and often reaches the breaking point while the agent is still responding, causing the system to fail mid-session. 

Microsoft Azure AI now handles this through multi-region, multi-provider load balancing, with automatic failover built into the Foundry Agent Service. The system honors policy-based model selection and pre- and post-LLM hooks, so traffic-rerouting decisions respect enterprise governance rules rather than blindly routing requests to the first responding endpoint. 

This is important because a simple token-overload failover can cause another issue called the thundering herd. When an endpoint is overloaded and returns 429 rate-limit errors, basic systems retry right away, adding even more requests to an already busy backend. Microsoft Azure AI solves this with exponential backoff and health-based routing. Overloaded deployments are given time to recover before traffic is sent back to them. The router tracks the health of each endpoint and adjusts as performance improves. 

For companies using Microsoft Azure AI automated agent failover recovery systems at the scale of a regional bank or a large e-commerce platform, the difference between basic retry logic and intelligent traffic management can mean a two-minute disruption instead of a two-hour outage. 

LLM Self Healing: From Passive Monitoring to Active Remediation 

LLM self-healing is the biggest change in Microsoft’s resilience strategy. The Azure Resiliency agent, now available in public preview via Azure Copilot, does more than just monitor systems and send alerts. It can diagnose problems, recommend solutions, and take action. 

An operations team can simply ask, “Are all my tier-1 workloads protected in a secondary region?” The resiliency agent checks the deployment setup, identifies resources that are present in only one availability zone, assesses the risk, and creates scripts to fix the issue. LLM self-healing means the agent understands the resiliency model of each Azure service, knows which ones support redundancy, and applies this knowledge to give specific solutions, not just general advice. 

LLM self-healing also works in production by running continuous checks. Automated failure simulations test recovery processes without affecting live workloads. If a drill detects a problem, such as a PostgreSQL instance without a standby replica in the secondary zone, the agent flags it, creates the fix, and can implement it with operator approval. One-click failover drills become a regular practice rather than a rare event. 

For a financial services company that uses AI-powered document review and customer service agents, this has clear benefits. Instead of finding out during a regional outage that their top agents lack cross-zone redundancy, they discover it during a scheduled drill on a regular day. The fix is made right away. 

What This Means for Enterprise AI Operations 

The Microsoft Azure AI automated agent failover recovery systems demonstrate a better understanding of where AI deployments typically fail. The problem is rarely the model itself. Instead, it is the underlying infrastructure, such as token quotas, regional routing tables, disk IOPS during failover, and delays in syncing between primary and standby environments. 

Automated agent failovers are now a standard feature, not just an advanced option. Microsoft has made them a default expectation for any business using AI agents in production. LLM self-healing is moving from a research idea to a regular part of operations. 

The bigger challenge now is organizational. Microsoft can build a system that catches token overload failures in milliseconds. But companies still need to run drills, review reports, and, most importantly, treat the resiliency agent’s recommendations as required engineering work rather than optional advice. 

The systems are in place. The next step is building the discipline to use them effectively.

Source: Microsoft Azure Blog 

Arlington, Virginia  

When a fourth-and-goal snap crosses the line of scrimmage, and your Amazon Fire TV stream lags by four seconds, watching at home gets frustrating. You hear your neighbor cheer before your screen even catches up. This is not a network issue. It is an architecture problem, and Amazon has finally decided to fix it. 

This month, Amazon quietly rolled out a significant firmware update to compatible devices, tackling one of the biggest complaints from home entertainment fans: inconsistent live-stream delivery during busy events. The latest Amazon Fire TV Update focuses on the core system that handles live data on the device, and this could have a big impact on multi-camera sports broadcasts. 

The Amazon Fire TV Update and What It Actually Changes 

Amazon’s engineering team confirmed that this firmware update brings the Fire TV device-level stream caching update 2026, which aims to reduce the erratic buffering that has affected high-bitrate live feeds. Core to this update is the Local Cache Partition, a dedicated part of the device’s storage set aside just for live-stream buffering and kept separate from other app data. 

Before this update, Fire TV devices handled live-stream data using a shared memory system. This setup worked well enough for on-demand content, where the player could pre-fetch and buffer deeply, hiding any network issues from viewers. Live content is a different challenge. When many people are watching at once, like during the Super Bowl or Champions League final, the operating system has to juggle the live-stream buffer, background apps, and system functions simultaneously. Something must give, and usually, it is your stream. 

How the Local Cache Partition Works.  

The new Local Cache Partition approach sets aside a fixed amount of storage, reportedly between 256MB and 512MB depending on the device model, for use only by the live-stream playback engine.ne. No other process can use this space during playback. It is like having a dedicated express lane on a highway, separate from the lanes used by everyone else. 

In practice, this means the device can keep a more reliable pre-buffer window. The playback engine no longer has to compete for memory in real time; it simply uses its reserved space without interruption. Early tests from third-party streaming labs show that startup latency dropped by about 18 percent on Fire TV Stick 4K Max devices when streaming 4K HDR at bitrates above 15 Mbps. 

Multi-angle streaming: The Feature That Makes This Issue 

The Local Cache Partition may appear as a minor detail in a typical firmware update, but it is important because it enables stable Multi Angle Streaming. This is where the update goes from a simple fix to something that can truly change how people watch live sports. 

Multi-angle streaming means the device must buffer data from several camera feeds simultaneously, such as end-zone, sideline, aerial, and player-tracking views. While you watch one angle, the others are kept ready in the background. When you switch angles, the change should be instant, not a two-second black screen followed by more buffering. Without dedicated buffer management, this smooth switch is hard to achieve. 

Amazon’s integration of NFL Sunday Ticket and its new partnerships with multi-camera broadcast providers made this update a top engineering priority. The Fire TV device-level stream caching update 2026 is what makes Multi Angle Streaming actually work, rather than just a feature that looks good on paper but does not deliver. 

What This Means for Broadcasters and Rights Holders 

The impact goes beyond just viewers at home. Broadcast engineers who set up multi-camera systems for live sports have always faced limits due to the capabilities of client devices. A production truck might send out twelve camera feeds at once, but if the device at home can only buffer two without problems, the system has to make tough choices about which feeds to compress or drop. 

Now that Fire TV hardware has the Local Cache Partition, rights holders can start creating streaming packages with four or more camera angles at once, without worrying about device limitations. Amazon has not released a formal developer guide yet, but sources say an updated media playback API, which will let developers control the partitioned buffer, is expected before the NFL regular season starts in September 2026. 

The Amazon Fire TV Update in the Context of the Streaming Wars 

Amazon is not the only company making these changes. Roku’s OS 14 added adaptive buffer sizing in early 2026, and Apple TV’s tvOS 18.3 introduced a background stream prefetch feature for live events. Google TV has also been improving its low-latency HLS support since mid-2025. This competition matters because every platform knows that live sports rights are extremely valuable, and gadget performance is now a real way to stand out. 

However, Amazon is the only major platform that also owns top live sports rights, including Thursday Night Football, the NBA, and a growing international soccer lineup. This vertical integration gives the Amazon Fire TV Update a competitive advantage that competitors cannot easily match. When Amazon improves device stream caching, it directly increases the value of the content it already owns and delivers. 

Which Devices Receive the Update 

The Fire TV device level stream caching update 2026 is available for Fire TV Stick 4K (second generation and later), Fire TV Stick 4K Max, Fire TV Cube (third generation), and certain Fire TV-embedded smart TVs from 2023 onward. First-generation and 1080p-only devices will not receive the Local Cache Partition due to hardware memory limitations. Amazon says the update is rolling out automatically in stages, and users with eligible devices should see the new firmware version in Settings > My Fire TV > About within the next two to three weeks. 

If you subscribe to multi-camera broadcast packages through Prime Video or third-party sports apps on Fire TV, you do not need to change any settings. The Multi Angle Streaming improvements appear in the app’s interface, while the device manages the buffer automatically in the background. 

Reading the Signal 

Amazon does not usually announce firmware updates with the same excitement as hardware launches. The Amazon Fire TV Update coming out this month did not get a press conference. This low-key approach shows that the company is focused on building infrastructure, not just creating a marketing event. 

The Fire TV device-level stream caching update 2026 and its Local Cache Partition show the kind of engineering investment that sets apart platforms serious about live sports from those that just license content and hope for the best. As new Multi Angle Streaming packages come to market, with features like AI camera selection, real-time stats, and customized viewing angles, hardware capability will decide which platforms viewers rely on when it matters most. Amazon has just made a big step forward in that area.

Source: What’s new on Prime Video in June 2026, including ‘The Legend of Vox Machina’ Season 4, WNBA games, and more 

Seattle, Washington 

Time is running out, and many people are not sure how much time they have left. 

Amazon Prime Day 2026 ends on Friday, June 26, at 11:59 PM PT, which is 2:59 AM ET on Saturday, June 27. This detail surprises East Coast shoppers every year. If you are refreshing your cart and wondering if you missed the window, you have not. But you are closer to the end than you might think. 

Amazon Prime Day 2026: The Biggest Edition Yet 

This year’s event is one of Amazon’s longest Prime Day runs so far. Many retailers and analysts are calling the extended sale a “Prime Week” shopping experience, and that is not an exaggeration. Amazon Prime Day 2026 officially started on Tuesday, June 23, at 12:01 AM PDT and continues until midnight on Friday, June 26, giving Prime members four days of deals across more than 35 categories. 

The move to a four-day sale is intentional. Amazon started this longer format in 2025, and it looks like it may become the standard. More time may seem like a good thing for shoppers, but it can create a false sense of security. The best deals rarely last until the final hour. 

Why the Final Hours Are the Most Dangerous — and the Most Rewarding 

Here is what many buyers overlook: new deals can appear as often as every five minutes during certain times of the event. This is not simply a marketing tactic from Amazon. Their pricing system uses real-time inventory signals to trigger automatic price changes, especially electronics. 

Lightning Deals and limited-stock promotions can disappear within hours, making early shopping essential. A shopper who waits until Thursday night to buy a USB-C hub that was $12 on Tuesday morning may find it back at $28 — or simply gone. 

The risk here is behavioral, not logistical. Consumers tend to procrastinate during multi-day sales, assuming the window stays open uniformly. It does not. Flash tech discounts function more like an auction than a traditional markdown: the price is set by time, demand, and quantity simultaneously. 

Flash Tech Discounts: What’s Actually Moving 

Today’s Big Deals drop three times daily during the event — at 12:00 AM PT, 8:00 AM PT, and 1:00 PM PT — with deals spanning across categories including beauty, tech, kitchen, clothing, and outdoor. For tech buyers specifically, the 8 AM window has historically carried the highest-value inventory resets. 

PCWorld’s editorial team found multiple standout flash tech discounts worth mentioning. For example, you can get two Anker 100-watt USB-C cables for $10, a 17% discount, and a Ugreen 14-in-1 USB-C Docking Station for $80, $80 off its usual price. These are real savings on useful hardware, not just inflated discounts. 

For buyers tracking specific products, Amazon’s Alexa for Shopping tool can alert you when specific products or brands go on sale and when products you frequently buy drop in price. Price trackers like CamelCamelCamel can independently verify whether a listed discount represents an actual historic low or a cosmetic markdown. 

The Amazon Haul Storefront: A Separate Category Worth Knowing 

Hidden within this event is a shopping destination that many Prime members miss. The Amazon Haul Storefront, Amazon’s ultra-low-price section, launched about a year ago and has its own Prime Day deals running alongside the main event. 

Customers can shop more than a million ultra-low-priced products on Amazon Haul. Deals cover a wide range of categories, including self-care and beauty items under $5, home decor and organization essentials under $8, and fashion finds up to 70% off. 

Amazon Haul offered 50% off sitewide on Day 1, with some exclusions. After that, shoppers can get 5% off orders of $50 or more and 10% off orders of $75 or more. These combined discounts make the Amazon Haul Storefront especially helpful for buyers who want to bundle several small purchases into a single cart. 

Best Tech Deals Under Ten Dollars Prime Day 2026: They Exist, and They Are Legitimate 

The most underrated category at this event requires the smallest budget. The best tech deals under ten dollars in the Prime Day 2026 category are not a gimmick section — they contain functional accessories from brands with real market credibility. 

Amazon Haul offers tech and gadgets starting at $3, with crafting essentials from $1 and fashion finds under $5. PCWorld confirmed a list of the best tech deals under ten dollars for Prime Day 2026, including items from brands like Anker, Logitech, and Acer. All of these have been verified as good buys at these prices. 

A $6 cable organizer from Anker or a $9 screen-cleaning kit from a trusted brand can be a better value than a $300 device at 15% off. Frugal buyers often skip this section because the prices seem too low to matter, but for anyone setting up a home office or travel kit, these best tech deals under ten dollars Prime Day 2026 can add up quickly. 

Competing Retailers Are Running Simultaneous Events 

One thing affecting prices this week is that Amazon is not the only one running big sales. Walmart’s Deals Event ran from June 22 through 28, both in-store and online, overlapping with Amazon Prime Day 2026. Target Circle Deal Days happened around the same time. This competition puts real pressure on prices across all three platforms, so a product listed as a “Prime exclusive deal” might actually be cheaper at Walmart, and you do not need a membership there. 

Smart shoppers are not loyal to just one store this week. They look for the lowest verified price. That is the only strategy that really works during a big sale event with multiple retailers. 

The Membership Math 

A Prime membership costs $14.99 per month or $139 per year, and eligible members can sign up for a free 30-day trial. For anyone using the trial, June 26 at 11:59 PM PT is more than the end of Amazon Prime Day 2026. It is also time to decide whether the savings from the past four days are enough to make a paid subscription worthwhile. 

The answer depends entirely on how you shop the rest of the year, not just this week. Anyone who spent $20 total across the event should cancel the trial before the billing date. Anyone who saved $200 on a single appliance has already justified six months of membership fees. 

That calculation, not the countdown clock, is the real deadline to pay attention to before Amazon Prime Day 2026 ends tonight.

Source: When is Amazon Prime Day 2026? Prime members get four days of exclusive savings June 23-26 

Round Rock, Texas 

Round Rock, Texas, is at the heart of a major change in enterprise AI infrastructure. This shift isn’t about a big cloud deal, but about what Dell Technologies is doing locally, at the edge, away from large data centers. 

Utilities and industrial operators no longer wonder if AI can improve grid management; that is already clear. Now, they are asking if the latency, data control, and costs of cloud-based AI are acceptable for systems where delays could cause outages for many customers. More grid operators are saying no, and the Dell AI Factory aims to solve this problem. 

The Dell AI Factory and the Case for Local Inference 

The Dell AI Factory is not just one product. It is a set of Dell hardware, software, and services designed to bring AI workloads closer to where data is created. The main idea is to challenge the belief that advanced AI must rely on large cloud providers. Instead, Dell shows that small, dedicated local inference nodes can outperform big cloud systems regarding latency, cost, and control. 

Imagine a transmission substation that monitors real-time voltage changes on a 345 kV line. A cloud-based model adds at least 80 to 120 milliseconds of delay in the best network situations, and even more during storms or network issues exactly when operators need quick insights. A local inference node using Small Language Models can make decisions in under 10 milliseconds. For relay logic and fault detection, this speed difference can mean the difference between safely isolating a fault and a widespread failure. 

Rugged PowerEdge XR: The Hardware Doing the Work 

The Rugged PowerEdge XR servers are Dell’s solution for tough situations where regular rack servers would not last long. Substations are not like climate-controlled data centers. They face temperatures from -40°F in Alberta winters to 140°F in Texas summers, and deal with electromagnetic interference that standard hardware cannot handle. 

The Rugged PowerEdge XR series, especially the XR11 and XR12 models, is built with shock and vibration resistance, wide temperature ranges, and special airflow systems to keep out dust and particles found in factory conditions. With NVIDIA L4 or L40S GPUs in a compact design, these servers can now handle inference tasks that required a whole server room just five years ago. 

This is not just theory. One regional transmission organization tested this setup and moved its AI-assisted anomaly detection from the cloud to Rugged PowerEdge XR nodes at 14 substations. As a result, they cut monthly inference costs by 61% and no longer rely on WAN connections for urgent alerts. 

Small Language Models and Why Bigger Is Not Better at the Edge 

For three years, the enterprise AI market focused on building bigger models with more parameters and larger training sets. This approach worked for knowledge workers using AI in a browser. But it does not meet the needs of a relay engineer who just needs a model to determine whether a voltage pattern indicates a transformer fault or a harmless spike. 

Small Language Models, which have between 1 and 7 billion parameters and are fine-tuned on specific datasets, perform better than large general-purpose models on particular, high-stakes tasks. They need much less GPU memory, so they can run on edge hardware that cannot handle huge models. Fine-tuning on specific tasks also gives higher accuracy, and the cost per query is much lower. 

A Small Language Model trained on 18 months of SCADA data from a specific grid setup will consistently outperform GPT-class models at fault-signature classification. It also keeps all queries inside the substation, so no data leaves the site. 

On-Premises Task-Specific Language Models Edge Deployment: The Financial Architecture 

The financial argument for using on-premises, task-specific language models edge deployment should be as carefully considered as any major infrastructure investment. The real comparison is not cloud versus nothing, but cloud API costs versus the cost of hardware and operations over time. All-inclusive per day across monitoring applications, cloud API costs at current commercial rates run approximately $18,000–$26,000 per month, depending on the model tier and token volume. A Rugged PowerEdge XR node with sufficient GPU capacity to handle that workload costs roughly $28,000–$45,000 in capital expenditure, with a hardware lifecycle of five to seven years. The break-even point for on-premises, task-specific language model edge deployment typically falls between 8 and 14 months. Everything beyond that window is operating cost savings — frequently exceeding $200,000 over a standard asset lifecycle. 

There is another financial benefit that is often overlooked but is very important for regulated industries: data that stays on-site never triggers a regulatory disclosure. For utilities following NERC CIP standards, local inference is not just cost-effective. It also meets compliance requirements in ways that cloud-based AI cannot. 

What Round Rock Is Building Toward 

Dell chose to base its AI Factory development and testing in Round Rock for both practical and representative reasons. The campus brings together the engineering teams that test Rugged PowerEdge XR servers, the software teams working on inference optimization with tools like NVIDIA TensorRT-LLM, and the services group that manages field deployments for critical infrastructure clients. 

Having all these teams in one place speeds up the feedback between hardware design and actual use. This is important when customers are installing Small Language Models on servers at substations in Saskatchewan or solar farms in West Texas. 

The time to modernize the grid is short, and the choices made now will shape operations for the next 15 to 20 years. Utilities and grid operators who carefully compare on-premises, task-specific language models with cloud options—considering latency, data rules, and long-term costs—are most likely to end up with AI systems that genuinely meet the grid’s needs. 

The Dell AI Factory, built on the Rugged PowerEdge XR platform and custom Small Language Models, is not waiting for the market to catch up. It is already being used in real-life contexts.

Source: The Farewell to the Round Trip: Why Your AI Needs a Local Address 

Santa Clara, California 

A single misread sensor on a warehouse floor can quickly lead to a costly liability claim. At a large distribution center in Memphis, Tennessee, a robotic arm moving at full speed failed to detect a maintenance worker who entered its operating area. The safety system was in place, but the edge computing node processing the sensor data lagged by 340 milliseconds. That small delay made a big difference. Now, Intel Xeon 6 processors are central to industry-wide efforts to solve this problem. 

Why Processing Speed Is a Safety Variable 

When logistics company executives discuss automation risk, they usually focus on uptime or throughput. They rarely consider the latency of the computing systems that control their robots. Overlooking this can have serious consequences. 

Modern automated distribution centers use LiDAR arrays, pressure-sensitive floor tiles, overhead cameras, and nearby sensors. These all produce constant streams of Factory Floor Telemetry that need to be processed almost instantly. Sending this data to a central cloud server causes delays that make it impossible to make fast safety decisions. Processing data locally on edge hardware inside the facility is the only way to meet the timing needs of today’s fast-moving robots. 

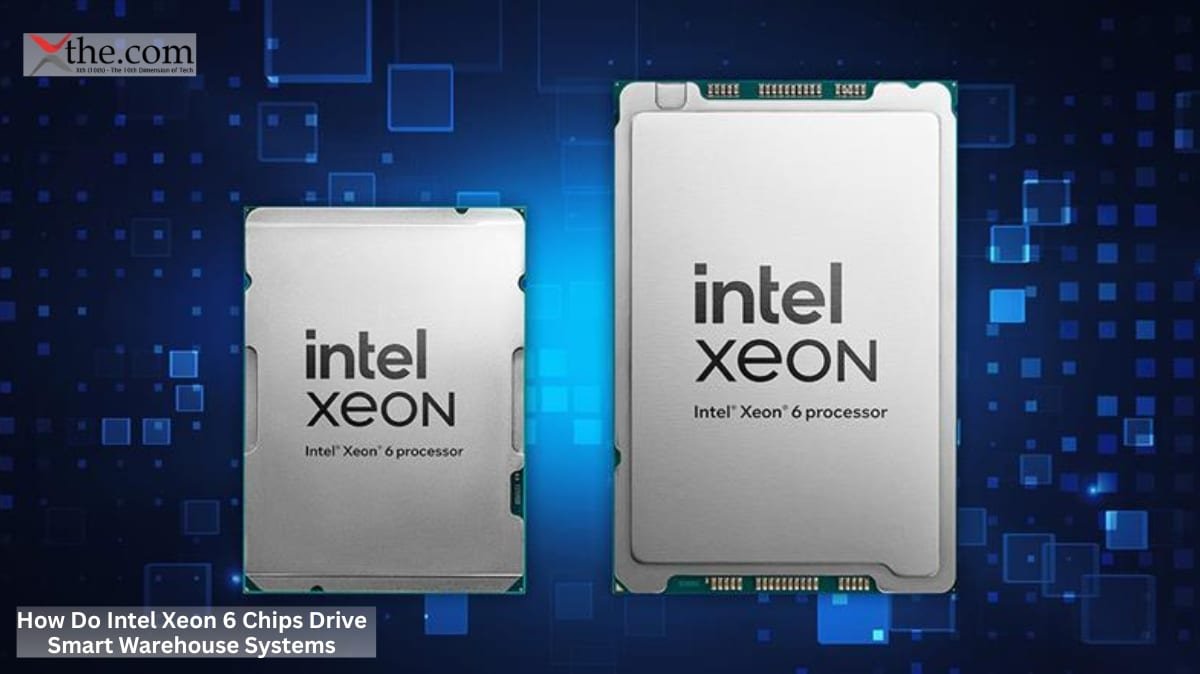
Intel Xeon 6 chips tackle this challenge directly. Built on Intel’s Intel 4 process node, they combine many cores with large on-chip cache and strong integration with Intel’s I/O and memory systems. This allows the processor to handle several tasks at once, like collision avoidance, path recalculation, and anomaly detection, without needing to send work to remote servers. 

The Role of Industrial Edge Reference Architectures 

No processor works alone. Using Intel Xeon 6 in warehouses depends on the software and system frameworks that support it. Intel’s Industrial Edge Reference architecture offers this needed structure. 

The Industrial Edge Reference framework outlines approved hardware configurations, software stacks, and network designs for running computing systems within a facility. In a 400,000-square-foot distribution center, this means detailing how edge servers with Intel Xeon 6 processors connect to controllers, how sensor data flows into analytics systems, and how the system continues to operate smoothly if some nodes fail. 

One real-world use is zone management. In busy fulfillment centers, different floor areas have different speed and distance rules based on whether people are present. A setup using Intel Xeon 6 and following the Industrial Edge Reference can continuously ingest data from overhead cameras, adjust zone boundaries as needed, and send new instructions to robots all within the building’s local network, with no data leaving the site. 

This is important for more than just speed. Facilities that handle pharmaceuticals or certain defense-related goods must follow rules that prevent operational data from being stored in public cloud systems. In these cases, processing Factory Floor Telemetry locally is more than better performance than required for compliance. 

Intel Xeon 6 Edge Computing Multi Axis Robotics: The Hard Problem 

The toughest challenge in this area is managing Intel Xeon 6 edge computing for multi-axis robotics, where several robotic arms operate in the same space and must avoid collisions. 

A six-axis robotic arm that picks items from a shelf and places them on a conveyor belt simultaneously produces joint-angle data, force feedback, and vision system outputs. When two arms work close together, as is frequent in fast sortation lines, the computing system must predict both robots’ paths and prevent collisions before they occur. 

Intel Xeon 6 processors solve this by using many cores and AVX-512 instruction support, which lets them run multiple floating-point calculations for robot movement simultaneously. In real use, this means one edge server with Intel Xeon 6 can handle the coordination for several robotic stations, where before each arm needed its own computer. 

The cost savings are significant. One major automotive parts distributor tested this setup and went from 14 separate computers to just 4 Intel Xeon 6-core edge servers. This cut hardware licensing costs and made the network easier for IT teams to manage. 

Factory Floor Telemetry as an Operational Intelligence Layer 

Processing Factory Floor Telemetry locally does more than just enable quick safety responses. Over time, it creates a detailed operational record that was not possible before. 

Vibration data from conveyor motor bearings, collected by accelerometers and analyzed in real time by Intel Xeon 6 edge nodes, can show wear patterns weeks before a breakdown. Thermal imaging at charging stations can detect battery problems in autonomous robots before they affect performance. These are not just ideas they are already being used in facilities run by major logistics companies on the U.S. East Coast. 

The Industrial Edge Framework Reference architecture supplies the data pipeline needed for this kind of analysis. Instead of requiring data scientists to write custom code for each sensor, the framework standardizes multiple Factory Floor Telemetry streams into a single format. This lets analytics tools work across the whole facility without extra integration for each data source. 

The Competitive Pressure Behind Edge Compute Investment 

Amazon’s robotics division has said its fulfillment centers handle billions of sensor events every day. Companies competing with Amazon for contracts cannot build their own custom chips. They need commercial hardware that offers similar performance and fits into standard IT purchasing processes. occupies that position in the market. It fits into standard server form factors, integrates with established virtualization platforms, and carries the vendor support infrastructure that enterprise procurement teams require. For a mid-sized third-party logistics provider looking to upgrade its edge compute layer without a multi-year custom development program, this offers a realistic path to deploying the instant processing capability that high-speed warehouse automation demands. 

The most productive logistics facilities of the next decade will not be defined by faster conveyor belts or bigger robotic arms. Instead, they will be built around computing systems that let every machine in the building share a clear, real-time view of what is happening. With Intel Xeon 6, used in Industrial Edge Reference frameworks and processing constant Factory Floor Telemetry, much of the real-time picture is coming together, millisecond by millisecond.

Source: Intel Newsroom 

Armonk, New York  

If a hypervisor is set up incorrectly in a shared cloud, it can expose an enterprise’s sensitive data to another tenant’s workload. This is not simply a theory it has happened before. That’s why CISOs at global banks, defense contractors, and medical institutions want something most cloud providers can’t offer: true physical separation, enforced by hardware instead of software. 

IBM Secure Cloud was designed from the start to meet this need. 

The Vulnerability That Software Controls Cannot Patch 

Multi-tenant cloud setups have a basic trade-off. To be efficient, clients share physical processors, memory, and network controllers. Logical partitioning the software that keeps each tenant’s workload separate usually works well until it fails. 

Specter and Meltdown, revealed in January 2018, showed that speculative execution in modern CPUs can leak data across logical boundaries. While patches helped, they slowed performance and created an important question: if the boundary is only logical, can it ever be completely secure? 

For a CISO responsible for regulated financial data or classified contracts, “probably not” is not good enough. They need a hardware partition architecture to be sure. 

How IBM Builds the Physical Wall 

IBM’s approach to hardware partition architecture starts at the processor level. The IBM z16 mainframe, the infrastructure backbone for IBM Secure Cloud in regulated industries, uses hardware-enforced memory domains that keep physical address spaces separate. Each logical partition, or LPAR, gets its own dedicated memory. The processor’s memory controller enforces these boundaries at the microcode level, below the level at which any hypervisor or operating system vulnerability could reach. 

This is important because it removes an entire category of attacks. When memory is physically separated, even if the hypervisor is compromised, tenant data stays protected. Attackers cannot get past the hardware barrier. 

This architecture also covers I/O channels. In a typical x86 cloud, PCIe lanes and DMA controllers can give attackers ways to cross logical partition boundaries. IBM’s channel subsystem assigns I/O hardware to each LPAR, and the hardware checks dedicated channel path identifiers to enforce this separation. 

Cryptographic Keys and the Chain of Trust 

Physical isolation stops unauthorized access through hardware. Cryptographic keys address another risk: ensuring that data leaving the protected environment, whether in transit or at rest, remains unreadable to anyone who intercepts it. 

IBM Secure Cloud uses a layered key management system based on the IBM Crypto Express hardware security module. Each HSM is a physical device that responds to tampering, not just a software simulation. It generates, stores, and manages cryptographic keys without ever exposing them to the host operating system. Keys exist only inside the HSM, or not at all, in a usable form. 

For enterprise clients who must meet FIPS 140-3 Level 4 the highest certification, which requires physical security measures that detect and respond to tampering this architecture, is the only viable option. Software-based key stores, no matter how strong the encryption, can’t meet this standard because they depend on the host system’s security. 

For a CISO running a global payment operation, this means that even if an unauthorized administrator gained root access to the cloud, the cryptographic keys protecting cardholder data would remain locked inside the HSM, out of reach of the operating system. 

Zero Trust Physical Memory Isolation Enterprise Architectures in Practice 

The framework that enterprise security teams are now using is zero-trust physical memory isolation architectures. This approach takes zero-trust principles beyond just network segmentation and identity checks, applying them to the physical hardware of computing systems. The architectures reject the assumption that any workload-sharing physical hardware can be implicitly trusted, regardless of logical controls. The architecture instead demands verification at every layer: cryptographic attestation of the boot environment, hardware-enforced memory boundaries, and HSM-anchored key management that removes humans from the key custody chain wherever possible. 

IBM’s version of zero-trust physical memory isolation enterprise architectures contains Secure Execution for Linux. This feature encrypts each virtual machine’s memory with a unique key created inside the Ultravisor, a firmware layer below the hypervisor that the hypervisor cannot see. Even IBM’s cloud staff cannot access a client’s decrypted workload memory. The technical control backs up the policy promise. 

What This Means for Enterprise Risk Posture 

These architectural choices clearly reduce risk. Verizon’s 2024 Data Breach Investigations Report found that cloud assets are involved in more breaches, and that system intrusion patterns including hypervisor-level attacks account for a large share of enterprise incidents. 

An IBM Secure Cloud setup with full hardware partitioning and HSM-managed cryptographic keys removes those surfaces of vulnerability from the threat model. It does this not by making them harder to exploit, but by making them physically unreachable. 

For a CISO explaining risk to a board audit committee, this difference is important. Logical controls can fail, but a properly implemented physical boundary cannot be bypassed by software exploits. 

The Architecture That Earns the Audit Report 

For the past decade, enterprise security has focused on the network perimeter as it shifted to cloud, mobile, and distributed systems. Now, organizations are moving on not by adding more policies to shared hardware, but by choosing infrastructure in which the necessary separation is built into the hardware from the start. 

IBM Secure Cloud’s hardware rings are more than a marketing term. They are the real answer to a question that regulated industries have asked since multi-tenant cloud became common: where does my data end, and where does the shared infrastructure begin? 

The answer, in Armonk’s architecture, is found in microcode and hardware, not in policy documents.

Source: IBM Newsroom 

San Jose, California. 

A zero-day vulnerability can go unnoticed in your data center switching fabric for months. Instead of being discovered by a security researcher, it might be found by an AI model within hours, which then starts probing enterprise perimeters at scale. With the traditional patching model, your choices are tough: schedule an emergency maintenance window, reboot the affected systems, deal with downtime, and hope the exploit is fixed before it causes damage. For IT teams managing hundreds of Nexus switches in a hybrid cloud, this approach is no longer practical. 

Cisco Cloud Control was designed to solve this exact problem. It was introduced at Cisco Live 2026 in Las Vegas, not as a simple product update, but as a complete rethinking of how enterprises run and protect their critical IT infrastructure. 

What Cisco Cloud Control Actually Delivers 

Cisco Cloud Control is an integrated platform designed to serve both people and AI agents in managing, monitoring, and protecting critical IT infrastructure. With just one login, users get a single view of Cisco networking, security, computing, observability, and alliance in a secure environment. People and AI agents operate within the same operational context and system of action, a significant change from the fragmented tools most enterprise IT teams use today. 

The main difference is in the architecture. Tools like Terraform, Ansible, and Python scripts made infrastructure programmable, but they all rely on humans to write the logic, connect systems, and decide on changes. Cisco Cloud Control takes a different approach. It offers standard APIs, telemetry, identity, and enforcement points, enabling both people and AI agents to work effectively within the same controlled environment. 

Imagine a financial services company with 400 Nexus switches spread across three data centers. In the past, a new CVE disclosure would trigger weeks of coordination among the security team, network operations, and change management. With Cisco Cloud Control, the same event can now trigger an automated response that is analyzed, scoped, and resolved, all while the network continues to run. 

The AgenticOps Platform Model: What Changes for IT Teams 

The idea of unified infrastructure management for human and AI agents is not simply a product positioning statement. It shows a real operational shift that Cisco has branded as AgenticOps. The AgenticOps Platform is the operating model on which Cisco Cloud Control is founded — one where people and agents work from a single data layer, and humans keep control over the actions taken. 

This is important because most enterprise AI deployments today lack trust rather than ability. AI agents can analyze infrastructure data, but devoid of clear boundaries, permissions, audit trails, and ways for humans to override actions, IT leaders cannot use them responsibly. The AgenticOps Platform solves this by building identity, policy, and zero trust directly into the control path, not as an add-on. It also includes governance that makes every agent action transparent, auditable, limited, reversible, and always subject to human approval. 

In practice, this means an AI agent in Cisco Cloud Control can spot unusual traffic patterns on a campus wireless controller, match that signal to a known vulnerability, and isolate the affected segment within seconds. It creates a full audit trail and does not need to wait for a human to notice the alert in the middle of the night. 

Customers can also create their own applications and agents using natural language directly in the platform. It connects to a wide range of services, including AWS, Linear, Microsoft, PagerDuty, ServiceNow, Slack, and Google Cloud. The AgenticOps Platform is open and unrestricted. 

Live Protect Security: The End of Reboot-Dependent Patching 

The most operationally consequential piece of the Cisco Cloud Control architecture is Live Protect Security. The concept is simple; the execution is sophisticated. 

Traditional CVE patching requires maintenance windows and reboots, and can cause downtime. Live Protect Security takes a different approach by applying security policies to live systems without requiring a switch reboot. It provides immediate protection as soon as a threat is found, well before a standard PSIRT upgrade is scheduled. 

When set to enforce mode, Live Protect Security blocks or reduces detected threats in real time. This enforcement occurs at the kernel level, so threats can be stopped immediately without requiring software upgrades, reboots, or downtime. Enforce mode uses NXSecure, which is built into NX-OS, to apply kernel-level security shields. This keeps Nexus 9000 series switches protected against new CVEs while ensuring the network remains stable and online. 

Live Protect Security is powered by extended Berkeley Packet Filter (eBPF) technology. Live Protect Security delivers kernel-level visibility and enforcement to protect against zero-day attacks, privilege escalation, and advanced DDoS threats. Controls can be set to monitor, log, or enforce mode, allowing instant CVE mitigation without reboots, disruptive updates, or maintenance windows. 

Cisco is also collaborating with AI red-teaming firm Armadin to independently validate Live Protect Security shields before deployment. Live Protect Security is currently shipping on Nexus 9000 switches, with expansion to SD-WAN Manager, Catalyst campus wireless controllers, switches, and other platforms planned. 

For hospital networks or stock exchanges, where any unforeseen downtime can have regulatory and financial impacts, this feature is a major shift. It completely changes how organizations think about security. 

Quantum Readiness and the Longer Arc 

Cisco Cloud Control and the AgenticOps Platform do not address only the threats visible today. “Harvest now, decrypt later” attacks are already collecting encrypted data to unlock when quantum capabilities mature. Cisco is responding with post-quantum protection extensions across its core portfolio, pledging to enable quantum-safe communications across the majority of Cisco’s core portfolio by December 2026. 

New enterprise and data center routers, switches, and firewall series will be quantum-safe by default. Cisco Cloud Control will highlight this change through its unified visibility layer, giving security teams a real-time view of your quantum readiness. 

Unified Infrastructure Management for Human and AI Agents: The Competitive Reality 

Cisco Cloud Control’s unified infrastructure management for human and AI agents is not unique, as every major infrastructure vendor is moving toward similar consolidation. What sets Cisco apart is how deeply integrated its platform is. The same system that manages a Catalyst campus switch also lets a security agent fix a kernel-level exploit on a Nexus data center fabric, all without changing tools, consoles, or data sources. 

As AI agents start working across different clouds, the network is no longer just a passive transport layer. It becomes part of the intelligence stack. Companies that use Cisco Cloud Control only to simplify management will get some benefits. But those who make it the foundation of their AgenticOps Platform strategy will be best prepared for the next AI-driven zero-day threat. All signs show that these threats are coming faster than ever. 

The organizations that will withstand the next wave of infrastructure threats are those that stop waiting for maintenance windows and start defending at the speed of machines.

Source: Cisco Unveils Agentic Platform for Operating and Defending Critical IT Infrastructure 

Fremont, California 

Qualcomm engineers spent years showing the industry that a phone chip could power a laptop. Now, the ASUS Zenbook might prove that a laptop chip can replace an AI server rack, at least for the most important boardroom tasks. 

The ASUS Zenbook That Thinks Without Asking Permission 

In 2024, most laptops still send basic AI tasks like autocomplete, noise cancellation, and real-time translation to remote data centers. This round-trip takes hundreds of milliseconds. That delay is fine for a chatbot, but it can ruin a live courtroom transcript or a securities analyst’s real-time work. 

The new ASUS Zenbook with the Snapdragon X2 Elite processor is built to remove that delay completely. Its Neural Processing Unit delivers 80 TOPS, or eighty trillion operations per second, all on the device and offline, without contacting a server. This number is not just marketing it’s the real limit of what the chip can handle under heat, based on MLPerf benchmarks. 

Consider what 80 TOPS means in real use. Running a seven-billion-parameter language model locally, about the size of Meta’s Llama 3 8B when compressed, needs between 10 and 30 TOPS. The Snapdragon X2 Elite easily handles this. A financial analyst using Microsoft Copilot+ and running noise suppression during a video call won’t even reach the chip’s limit. 

Where the Battery Hides: A Hardware Detective Story 

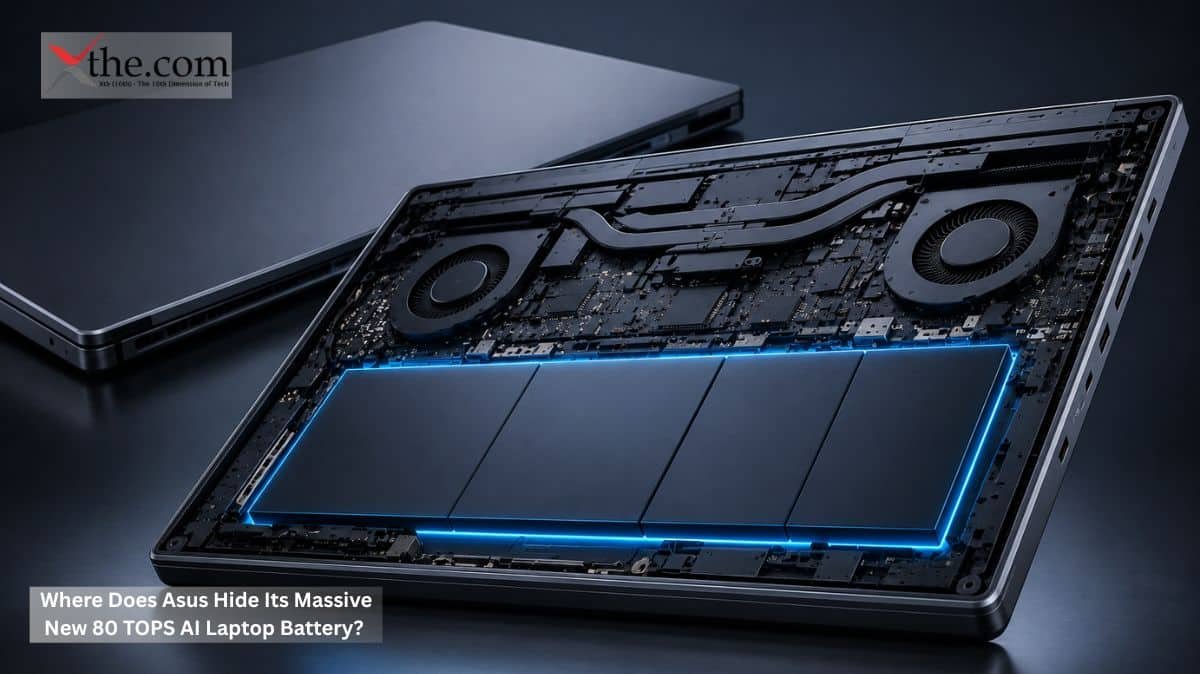
The most surprising part of this machine isn’t the processor it’s the 96 Wh battery hidden behind it. At first, putting a powerful AI chip and a big battery in a slim laptop seems impossible. ASUS solved this problem with the Ceraluminum Chassis. 

Ceraluminum, ASUS’s special aluminum-ceramic mix, is about 30% stiffer than regular 6061 aluminum of the same thickness. This extra stiffness lets ASUS make the panels thinner without losing strength, freeing up space for more battery cells. A normal aluminum lid with the same strength would be 1.2mm thick, but the Ceraluminum Chassis matches that at under 0.9mm, giving back valuable space inside the laptop. 

The thermal design adds another advantage. Ceramic materials spread heat more evenly than plain aluminum, so there are fewer hotspots near the Snapdragon X2 Elite chip. Lower peak temperatures let Qualcomm’s chip run at higher speeds for longer before thermal throttling kicks in, which is particularly relevant during sustained local AI processing on laptops, 80 TOPS Snapdragon X2 workloads that push the NPU close to its limit for several minutes. 

Localized Neural Engines vs. Legacy Cloud Computation 

The debate about architecture is clear. Cloud AI processing has three main weaknesses that are hard to accept at the enterprise level: latency, privacy, and availability. 

Latency hurts the user experience in any task that requires feedback within 200 milliseconds. For example, a surgeon using AI to review images during surgery can’t wait 400 milliseconds for a server reply. A trader using AI to spot patterns at market open can’t deal with network delays. Laptops with local AI processing, like those with 80 TOPS Snapdragon X2 chips, avoid these problems because the AI engine is built into the same chip as the CPU. 

Privacy is an even bigger issue for regulated industries. Healthcare organizations under HIPAA, financial firms regulated by the SEC, and defense contractors under ITAR all risk legal trouble if sensitive data is stored on third-party cloud servers, even if it’s encrypted or only stored there briefly. An on-device NPU keeps all data on the machine. The ASUS Zenbook with Snapdragon X2 Elite meets this need in a way that cloud-based laptops cannot, regardless of the encryption they use. 

Availability is the hidden problem. In February 2024, Microsoft Azure was down for about ten hours. All AI workflows that needed the cloud stopped working. But a device with 80 TOPS of local computing kept going. The value of real offline AI isn’t just theory it’s already been proven in real-life use. 

What the 80 TOPS Figure Actually Benchmarks 

People often mention TOPS numbers lacking much context. Here’s how the competition looks in mid-2025. 

Apple’s M4 Pro neural engine delivers 38 TOPS. Intel’s Core Ultra 200V Lunar Lake NPU gives about 48 TOPS. AMD’s Ryzen AI 300 series reaches 50 TOPS. The Snapdragon X2 Elite at 80 TOPS isn’t just a bit better it’s in a whole new class, offering performance that used to be found only in workstation hardware. 

Right now, consumer devices can handle on-device models up to about 13 billion parameters before quality drops too much. With 80 TOPS, the ASUS Zenbook can easily manage this. At 38 TOPS, running models this large causes the device to overheat and slow down within minutes. 

The Ceraluminum Chassis as Competitive Moat 

It’s hard for laptop makers to stand out with hardware. Processors are available to everyone, and screens are standard parts. The Ceraluminum Chassis is different, it’s hard to make because bonding ceramic and aluminum needs special kiln processes that most manufacturers can’t do at scale. ASUS spent years building this supply chain, and you can see the results in the material. 

When you run your finger across the lid of a laptop with the Ceraluminum Chassis, it feels slightly matte and almost ceramic-like, making it stand out from regular anodized aluminum. It’s also much harder to scratch about 8H on the pencil hardness scale, compared to around 3H for standard anodized aluminum. 

The Longer Arc 

The ASUS Zenbook with Snapdragon X2 Elite isn’t simply about looks or thin bezels. It shows that the cloud-based AI model, which has been the standard for five years, now has a real alternative at the edge. The 96 Wh battery, made possible by the strong Ceraluminum Chassis, makes this option practical for enterprise buyers who need a laptop that can handle a full day of local AI tasks without needing to plug in. 

The cloud isn’t going away, but the idea that you need it for serious AI work might already be outdated.

Source: Asus News 

Bellevue, Washington 

The registration window closes today. If you miss it, you might have to wait until 2027. 

Time is running out. To get a spot in the first purchase wave for the Valve Steam Machine, you need to register for the waitlist by 10:00 AM Pacific Time on June 25, 2026, which is today. Preorders also open on June 25, but you must join the waitlist to be eligible. The window to join closes at 12 PM ET or 10 AM PT. After that, late submissions shall not be included in the initial draw. For those who have followed this launch since November 2025, now is the time to decide. 

The Valve Steam Machine: What Is Actually Being Ordered 

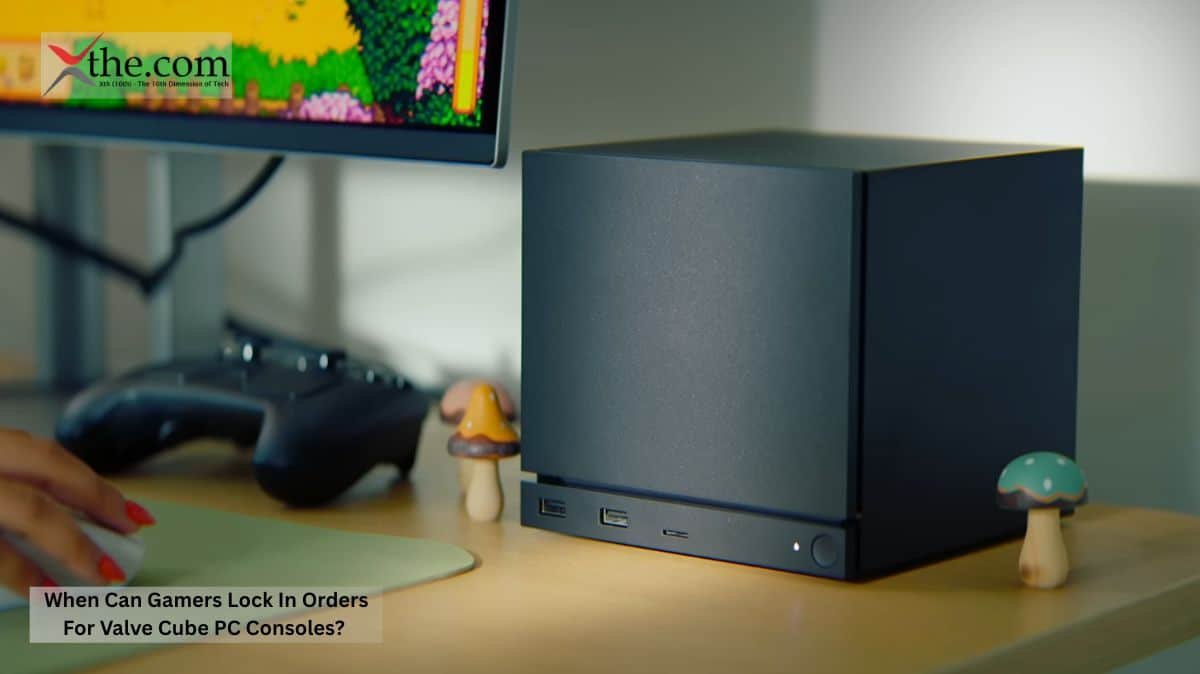
The Valve Steam Machine is not a gaming console in the same way as Sony or Nintendo devices, but it takes up the same amount of space in a living room cabinet. It runs on SteamOS, Valve’s own gaming-focused Linux-based operating system, which makes it much more open than a typical console like the Xbox or PlayStation. Users can install their own apps or even a different operating system. Gaming journalists and the community have started calling it the “GabeCube” because of its distinctive six-inch cube shape, measuring 156 by 152 by 162 millimeters, with a customizable magnetic bezel faceplate on the front. 

Unlike the unsuccessful multi-partner hardware initiative from a decade ago, Valve is manufacturing this Valve Steam Machine entirely under its own watchful eye. That distinction matters enormously for buyers who remember the fragmented, OEM-dependent Steam Machines from 2015. Now, it is a unified, first-party product with quality controlled from the factory to your doorstep. 

Zen 4 Architecture and What It Means For Performance 

The hardware specification is where context becomes essential. The Steam Machine features a semi-custom AMD processor built around a Zen 4 six-core, twelve-thread CPU paired with a semi-custom RDNA 3 GPU featuring 28 compute units. The Zen 4 Architecture represents a meaningful generational jump over the Zen 2 design in the first Steam Deck, though it does not reach the Zen 5 ceiling found in current top-tier AMD desktop parts. 

The CPU uses AMD’s Zen 4 Architecture rather than its latest Zen 5 design, which is a significant upgrade over the Steam Deck’s older Zen 2 design, but it still means the Steam Machine is not truly cutting-edge. The chip has six cores, putting it on par with the Ryzen 5 7600X. 

The memory setup is more like a console than a typical PC. Both versions come with 16GB of DDR5 memory, 8GB of GDDR6 VRAM, Wi-Fi 6E, Bluetooth 5.3, Gigabit Ethernet, a microSD card slot, and SteamOS 3. The base model has a 512GB NVMe SSD, while the premium version offers 2TB of storage. Having separate system RAM and dedicated GDDR6 graphics memory is rare for a device this size. This shows that Valve designed it as a true gaming system, not just a repurposed thin client. 

The Zen 4 CPU and semi-custom RDNA 3 GPU work together to deliver up to six times the performance of a Steam Deck. Valve says you can expect smooth 4K 60 fps gaming with AMD’s FSR 3 upscaling. In internal tests, Cyberpunk 2077 reportedly ran at about 65 fps on medium settings with ray tracing enabled, upscaled to 4K. This is impressive for a passively cooled six-inch box. 

The Direct Production System and How the Queue Works 

Understanding the Direct Production System is essential before the 10 AM cutoff. The registration window will officially lock down on Thursday, June 25th, at 10:00 AM Pacific Time. Once signups close, Valve will run a completely randomized drawing from the submission pool to determine the official reservation order. 

This approach straightforwardly addresses the disorder that plagued the Steam Controller launch and PlayStation 5 scalper bots. This is being done in reaction to challenges with preordering the Steam Controller. Valve says it gives users a fair amount of time to place an order while also giving Valve time to “do some extra checking on the signups to make sure they’re real accounts.” 

The Valve direct-production Steam Machine queue registration has specific eligibility rules to filter out bad actors. Applicants need a Steam account in good standing and must have made a Steam purchase before April 27, 2026. Only one reservation is allowed per household. This one-per-household rule also applies to payment method and shipping address. Submitting multiple entries with different email addresses will not increase your chances in this Direct Production System. 

Shortly after the drawing, users will receive an email notifying them whether they secured a confirmed spot in the initial allocation queue or were assigned to the waitlist for subsequent hardware production runs. The first batch of formal purchase invitations will drop into lucky users’ inboxes on Monday, June 29th. 

Pricing, Configuration Options, and Supply Realities 

The numbers are higher than the community anticipated. The base Steam Machine with 512GB of storage costs $1,049, while a bundle that includes the new Steam Controller costs $1,128. There’s also a 2TB model listed at $1,349, with the controller bundle priced at $1,428. 

The Steam Machine is a small, cube-shaped console with PC gaming specs that fall between a PlayStation 5 and a PS5 Pro. It is designed to match the most common specs of the average Steam user and aims to play most games at 4K 60FPS with FSR enabled. Valve has confirmed it is not selling these units at a loss. This is a strategic choice that keeps it outside the usual console subsidy model, but it does mean a higher upfront cost. 

Supply is limited. Valve says they are making fewer units than planned at first, so the first batch could sell out fast. For some later reservations, estimated availability has already moved into 2027. This shows why the morning queue registration is important. Missing the 10 AM window today isn’t only a small inconvenience; it could mean waiting an extra 12 months. 

What Happens If You Miss the Morning Cutoff 

Reservation access does not permanently disappear after June 25, but your position in the Valve direct-production Steam Machine queue registration resets entirely. Subsequent waves will draw from a separate pool, and Valve’s broader hardware reservation updates show that reservations remain open after the initial wave though later reservations have already slipped into 2027 availability periods. 

For buyers who are open to alternatives, the secondary market is a likely option. Since orders are limited to one per household and require a verified Steam account with purchase history, large-scale scalping is difficult, but not impossible. If the launch wave sells out, expect higher prices on resale platforms. 

The Larger Bet Valve Is Making 

The Valve Steam Machine launch is the most consequential hardware moment for Valve since the Steam Deck shipped in February 2022. Both the Zen 4 Architecture powering its processor and the Direct Production System governing its sales reflect a company that learned painful lessons from a ten-year-old failure and built more deliberately this time. 

The ten o’clock deadline is more than simply a logistical cutoff. It is the first real test of whether hardware fans trust Valve’s living-room plans enough to spend money before any independent reviews are out. If the initial queue fills before the draw happens, that will be a clear answer. A waitlist stretching into next year will show that the Valve Steam Machine has already succeeded before it ships a single unit.

Source: Steam Featured & Recommended