Security teams still miss threats that move faster than human response cycles. In one internal simulation, a lateral movement attack spread across multiple cloud workloads in under three minutes, well before analysts could intervene. This is where Google AI cybersecurity, Google Cloud, and threat-detection AI begin to redesign the defensive strategy. Google Cloud is testing autonomous agents that do not wait for alerts. They hunt, analyze, and act in real time.  

Why Threat Hunting Needs to Evolve 

Traditional security teams depend on alerts, logs, and people to investigate. This approach assumes threats will create clear signals and that analysts can respond fast enough. This is no longer the case.  

Attackers now use automated scripts and flexible techniques. They constantly test systems and adjust their behavior to avoid detection. This puts defenders on the back foot, always reacting.  

Cloud defense AI changes this situation. Instead of waiting for problems to appear, these systems actively look for signs of compromise. Threat detection becomes a constant process, not just something triggered by alerts.  

Inside Autonomous Threat Hunting Architecture  

Real-Time Analysis In AI Cybersecurity, Google Cloud Threat Detection AI 

Google Cloud builds intelligence right into its monitoring systems. Autonomous agents collect data from network traffic, identity systems, and application logs.  

These agents connect signals from different sources. One failed login might not mean much, but if it occurs alongside strange API calls and odd data access, it creates a risk profile.  

This is how autonomous security agents stand apart from traditional tools. They don’t just follow fixed rules. Instead, they look for ways to add context, adjust to new patterns, and keep improving their detection methods.  

Decision Making Without Human Delay 

When the system finds a threat, it doesn’t react right away. It first considers what actions to take based on the level of risk and possible impact.  

For example, if an agent detects suspicious lateral movement, it may isolate the affected workload. It can revoke compromised credentials or reroute traffic to contain exposure.  

These decisions are made in seconds. Cloud Defense AI helps ensure responses follow set policies and adapt in real time.  

Moving Beyond Alert-Based Security  

Limitations of Manual Threat Detection 

Alert fatigue remains a major problem. Security teams face thousands of alerts every day, many of which are false alarms. This makes it harder to focus and slows down response times.  

With AI cybersecurity, Google Cloud Threat Detection AI, the system filters noise before it reaches human analysts. Only high-confidence threats require escalation.  

This takes pressure off the team and lets them focus on the bigger picture strategy instead of always dealing with urgent alerts.  

Continuous Threat Hunting as a Default 

Autonomous systems view threat hunting as something they should always run. They look for small warning signs that people might miss.  

For example, a small change in how data is accessed could be an early sign of data theft. Human teams might not notice, but autonomous agents spot and check it right away.  

The role of autonomous security agents becomes central here. They operate persistently without downtime or fatigue.  

Operational Impact on Enterprise Security 

Organizations that use autonomous threat hunting can contain threats faster and reduce the damage from breaches. Finding problems early keeps attacks from spreading.  

In financial institutions, this can prevent unauthorized transactions. In healthcare, it protects sensitive patient data from exposure.  

The combination of predictive detection and automated response strengthens overall resilience. Cloud Defense AI ensures that defenses evolve alongside threats.  

Risks And Governance Challenges 

Transparency And Explainability 

Autonomous systems can create visibility gaps. Security teams might not always know how decisions are made, which makes auditing and compliance harder.  

If an agent blocks a real transaction, organizations need to know why. Without clear explanations, people may lose trust in the system.  

Balancing Automation With Control 

Full automation is not always the best choice. Sometimes human judgment is needed, especially when the stakes are high for the business.  

Organizations need to set clear limits. They should decide which actions agents can take on their own and which ones need approval. The essence of autonomous security agents depends on this balance. Too much autonomy increases risks. Too little reduces effectiveness.  

Strategic Implications for C-suite Leaders 

For executives, autonomous threat hunting means changing how they invest in cybersecurity. The focus shifts from buying separate tools to using systems that combine detection and response. Budgets will increasingly favor platforms that combine analytics, automation, and policy enforcement. This includes solutions based on Google Cloud’s AI-powered threat detection.  

Risk management strategies also need to change. Autonomous systems affect how incidents are found, reported, and handled. Governance roles must adapt as well.  

Industry Direction and Competitive Pressure 

Google Cloud’s move is part of a bigger trend. Cloud providers are adding more intelligence directly into their security systems.  

Other companies will probably offer similar features soon. Businesses will start to expect autonomous threat detection as a basic part of cloud security.  

This will set a new standard for cloud security. Organizations that wait too long to adopt it may fall behind.  

The Next Phase of Intelligent Cyber Defense 

Autonomous threat hunting is a major change in how organizations handle security. The focus moves from reacting to problems to anticipating them, and from just responding to alerts to always analyzing.  

As these systems improve, they will become an increasingly important part of everyday business processes. Security will not be a separate task, but will be built into everything organizations do.  

The future of cyber defense will rely on how well organizations mix human skills with machine insights. Those who find the right balance will set the new standard for staying strong in a world where threats keep growing.

Source: AWS News Blog 
A delay of just 200 milliseconds can cost a retail platform millions during busy periods. Even small latency spikes can spread through distributed systems. AWS latency, AI, and predictive scaling are starting to change how infrastructure handles these challenges. Rather than waiting for slowdowns, AWS is testing systems that can predict and prevent them.  

Why Latency Prediction Has Become a Strategic Priority 

Latency is no longer just a technical issue. It has a direct impact on revenue, customer loyalty, and system reliability. Companies operating across different regions often face unexpected delays due to traffic spikes, network congestion, and even workload spikes.  

Traditional scaling models only respond when certain limits are reached, when CPU usage goes up, alarms go off, and more resources are added. This approach often falls behind actual demand.  

AWS compute optimization changes this process. Now, systems analyze patterns over time to spot signs that often precede latency spikes. This helps infrastructure get ready before performance drops.  

Inside the Predictive Latency Engine.  

Real-Time Modeling in AWS Latency AI Predictive Scaling Cloud 

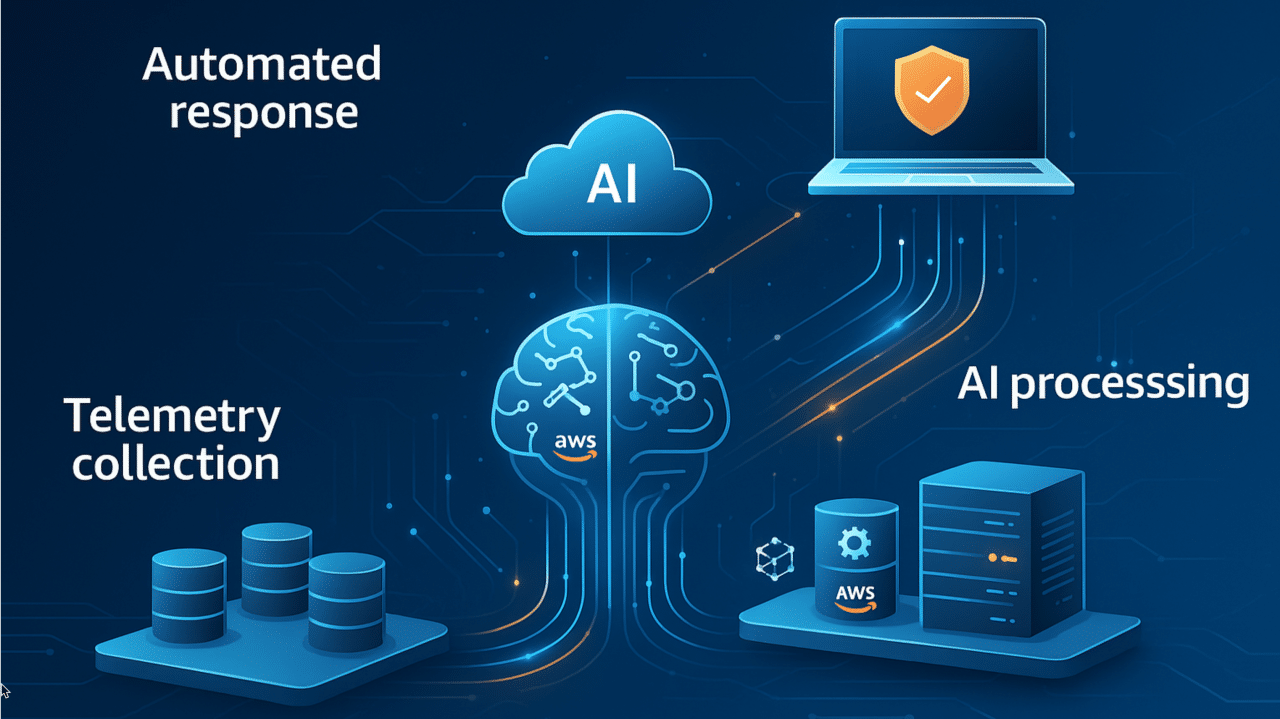
The AWS Latency Engine uses continuous telemetry to gather data from compute nodes, storage, and network paths. This information feeds machine learning models trained to spot early signs of congestion.  

Rather than waiting for clear signs of failure, the system watches for small changes. Even a slight rise in packet retransmissions or queue depth can prompt it to act early.  

At this point, multi-region routing AI becomes crucial. The system not only adds resources but also moves workloads to different locations to maintain steady performance.  

How Predictive Load Shifting Works 

The engine evaluates multiple variables, including current workload distribution, historical traffic patterns, regional latency benchmarks, and network health indicators, simultaneously.  

When the model expects a latency spike, it begins shifting the load. Traffic is routed to regions with greater capacity and lower risk of delays.  

For example, if an e-commerce platform sees demand growing in Asia, some traffic might be sent to nearby regions before servers get overloaded. This helps avoid bottlenecks instead of just responding to them.  

Moving Beyond Reactive Scaling 

Limitations of Traditional Autoscaling 

Reactive scaling uses set rules. These rules work well when demand is predictable, but they struggle to handle sudden spikes.  

Take a streaming platform during a big live event. Traffic can jump in just seconds. By the time scaling rules kick in, users might already notice buffering.  

With AWS Latency AI and Predictive Scaling Cloud, the system anticipates these surges. It allocates resources and adjusts routing before thresholds are crossed.  

Integrating Compute And Network Intelligence 

Predictive scaling involves more than just adding servers. It means coordination between the compute and network layers.  

Here, AWS compute optimization is key. The system decides which instances to scale, where to put them, and how to balance workloads effectively.  

Meanwhile, multi-region routing AI makes sure traffic takes the best possible paths. It looks at latency, cost, and regional availability as things happen.  

Operational Impact On Enterprise Workloads 

Organizations that use predictive latency systems can see real improvements. There is little downtime, and performance stays more consistent.  

In financial services, where every millisecond counts, predictive routing can cut down transactional delays. In gaming, it helps keep real-time play stable for players around the world.  

When AWS compute optimization and smart routing work together, infrastructure becomes stronger. Systems adjust all the time instead of only in set steps.  

Risks and Trade-Offs 

Reduced Visibility Into Decision-Making 

As systems get more automated, they become less transparent. Engineers might not always know why workloads are moved or resources are assigned in certain ways.  

The lack of visibility can make troubleshooting harder. If there are performance problems, finding the root cause is more challenging.  

Predictive scaling can use more resources. Allocating capacity in advance might increase operating costs.  

Organizations need to weigh performance improvements against the cost. Not every workload needs advanced prediction models.  

Strategic Implications for Cloud Leaders 

For executives, predictive latency systems mark a change in infrastructure strategy. The focus shifts from just planning capacity to using smarter orchestration.  

Investments will focus more on systems that blend data analysis with automation. This covers both multi-region routing AI and advanced scaling tools.  

Companies that use these features early could get ahead of the competition. Faster response and steady performance can help them stand out in busy markets.  

The Future of Predictive Cloud Infrastructure 

AWS’s work on latency prediction reflects a broader industry trend. Cloud providers are starting to build systems that act before problems show up.  

The integration of AWS latency AI, predictive cloud scaling and routing, and compute intelligence points to a more autonomous infrastructure model, one where decisions happen continuously, not in response to alerts.  

As these systems mature, the role of engineers will evolve. They will define policies and constraints while AI handles execution. The result is a cloud environment that anticipates demand, accepts in real time, and reduces the gap between expectation and performance.

Source: AWS News Blog 

A single commit buried inside an Intel toolchain repository revealed more than routine updates. It referenced an embedded Intel AI compiler, a semiconductor AI automation layer tied to a recent patent filing. That pairing signals a shift in fabrication workflows, where AI agents no longer assist engineers but actively participate in chip design decisions. The implication is immediate: optimization tasks once handled manually may soon be entirely delegated to autonomous systems.  

The Hidden Evolution Of Tool Chain Intelligence 

Intel’s toolchains have usually relied on predictable processes. Engineers set constraints, ran simulations, and iteratively improved designs. This approach has always needed a lot of human input.  

The introduction of AI for chip design changes this sequence. Instead of waiting for engineers to adjust parameters, AI agents can modify design variables in real time. These agents operate at the compiler layer, influencing how code is translated into physical layouts.  

This change goes deeper than a simple upgrade. It puts intelligence directly into the execution process. The compiler now acts as both a transistor and a decision maker.  

How Embedded AI Compilers Reshape Development  

Decision Loops Within Intel AI Compiler Semiconductor AI Automation 

The leaked information suggests that AI agents are now part of a recurring compilation cycle. Each cycle checks performance metrics like power efficiency, thermal limits, and signal integrity.  

Rather than creating a single output, the compiler now works in a feedback loop:  

  • It generates a design variant.   
  • It evaluates performance against constraints.  
  • It refines parameters autonomously.  

This loop keeps running until it meets set goals. Engineers no longer have to rerun simulations by hand for every change.  

The presence of fab optimization AI within this loop indicates that decisions extend beyond design. They influence manufacturability as well.  

Bridging Design And Fabrication 

In the past, chip design and fabrication were largely separate. Design teams focused on logic, while fabrication teams focused on improving yield and process efficiency. AI agents blur this boundary by integrating chip design AI with fabrication constraints. The system evaluates how design choices impact production outcomes.  

For example, an AI agent might adjust transistor placement to reduce the likelihood of defects during lithography. This is already happening and shows the kind of cross-domain optimization that embedded compilers can provide.  

The Decline of Manual Optimization  

When Human Iteration Becomes a Bottleneck 

Manual optimization takes both skill and time. Engineers test different scenarios, study the results, and improve designs. While this method works, it does not scale well.  

With the Intel AI Compiler, semiconductor AI automation, and increased iteration speeds, AI agents can explore thousands of design permutations in the time it takes a human to evaluate a handful.  

This marks a turning point. Manual methods simply cannot match the speed and range of automated exploration.  

Risks Of Overreliance On Autonomous Systems 

Moving forward, automation brings new concerns. AI-driven decisions can be hard to understand, and engineers might not always know why a certain design choice was made.  

The integration of fab optimization AI also raises accountability questions. If a design flaw emerges during production, tracing its origin becomes more complex.  

Organizations need to decide how much control they want to keep. Full automation is efficient, but it makes it harder to see how decisions are made.  

Strategic Implications for Semiconductor Leaders  

Rethinking Competitive Advantage 

For years, semiconductor companies gained an edge through engineering talent and unique processes. AI-driven toolchains are changing this situation.   

Companies adopting the Intel AI Compiler and semiconductor AI automation can accelerate development cycles. They can also achieve higher levels of optimization across performance and yield.   

This puts pressure on the whole industry. Companies that stick to traditional methods risk being left behind.  

Investment Priorities, and Organizational Shifts 

Switching to AI-driven toolchains takes more than just updating software. It also means changing team structures and how work gets done.  

Engineers will move from hands-on optimization to more supervisory roles. They will set constraints, check outputs, and handle exceptions.  

The role of chip design AI becomes central. It serves as both a collaborator and an executor, reshaping how engineering teams operate.  

Industry-Wide Ripple Effects 

Intel’s internal changes rarely stay private. Competitors watch these moves very closely. If AMD’s AI compilers work well, other semiconductor companies will likely follow suit.   

This could standardize the use of AI for CAD optimization in advanced nodes. Foundries may begin to expect AI-optimized designs as a baseline requirement.  

The impact extends beyond design teams and affects supply chains as well. Faster design cycles can shorten production timelines, influencing everything from sourcing parts to launching products.  

The Future of Autonomous Chip Design 

The integration of AI agents into toolchains marks a turning point. It moves intelligence to the core of semiconductor development, where decisions carry the most weight.  

As these systems improve, finding the right balance between automation and oversight will be key. Engineers will still be involved, but their roles will change.  

The future of semiconductor innovation will depend on how well organizations handle this change. Companies that combine human expertise with autonomous systems will lead the industry. 

Source: Follow Intel Newsroom on Social Media 

Just one conflicting instruction can disrupt an entire AI workflow. For example, in a test environment, two agents attempted to overwrite the same dataset simultaneously, resulting in a complete rollback. Azure AI agents, agent attestation, and multi-agent systems are now being built to prevent these kinds of problems. Microsoft’s new supervisor layer brings structured control to areas where autonomous agents once worked with little coordination.  

Why Agent Conflicts Are Becoming a Board-Level Concern 

Autonomous agents now work together rather than alone. Companies often use dozens, or even hundreds, of agents across finance, operations, and customer service. Without oversight, these agents can end up making decisions that conflict with each other.  

This is where Microsoft AI governance moves from theory to practice. Governance is no longer just about policy documents. Now it is built into the systems themselves, guiding agencies’ behavior in real time.  

Take a procurement system as an example: one agent focuses on cutting costs, while another aims to deliver faster. If they do not coordinate, their actions with suppliers can clash. This can lead to inefficiency or even financial risk.  

Inside the Supervisor Layer Architecture 

Embedding control in Azure AI agents, agent orchestration, and multi-agent systems 

Microsoft’s supervisor layer acts as an arbitration engine. It checks agent decisions before they are carried out and compares them to set rules.  

Rather than letting agents act on their own, the system adds checkpoints. Every action request is validated against rules, priority levels, and context checks.  

This method improves conflict resolution by adding structured steps. It catches conflicts before actions are taken, rather than after something goes wrong.  

Decision Mediation and Priority Alignment 

The supervisor layer gives agents different priority levels. These priorities can change depending on the situation, business rules, and past results.  

For example, in a logistics environment:  

  • A delivery optimization agent may dominate during peak hours.   
  • A cost control agent may take precedence during cost-peak cycles.  

This flexible system helps reduce conflicts between different goals. It also makes sure agent decisions support the company’s overall objectives.  

Operational Impact On Enterprise Systems 

Adding supervisory control changes how organizations use automation. Systems now focus on preventing problems before they occur rather than just fixing them after the fact.  

In large-scale multi-agent systems, this shift reduces error propagation. A single flawed decision no longer cascades across dependent processes.  

Companies also get better audit visibility. Every decision goes through a central layer, which creates records that can be traced. This supports Microsoft’s AI governance, especially in industries such as banking and healthcare that have strict rules.  

Balancing Autonomy With Oversight.  

The Limits Of Full Independence 

Total autonomy may seem efficient in theory, but in reality, it can lead to unpredictable results. Agents trained on different datasets often interpret goals differently.  

This is where agent conflict resolution becomes essential. Without it, systems may appear functional while quietly generating inconsistencies.  

The supervisory layer does not remove autonomy. Instead, it sets clear limits. Agents still work on their own, but within a system that keeps an eye on them.  

Latency vs Control Trade-Off 

Adding a supervisory layer requires more processing. Each decision needs to be checked, which can slow things down a bit.  

However, Microsoft’s design keeps this delay small. The system uses quick validation models that work almost instantly.  

For most enterprise use cases, the trade-off favors control. A slight delay is acceptable if it prevents systemic errors.  

Strategic Implications for C-Suite Leaders 

For executives, this change means they need to rethink AI investments. It is not just about performance anymore. Control, traceability, and alignment are just as important.  

Organizations deploying Azure AI agents, agent orchestration, and meta-agent systems must rethink their architecture. The focus moves from scaling agents to managing interactions between them.  

This also changes how companies handle risk. Autonomous systems without supervision can create hidden problems. With a supervisor layer, these risks can be seen and managed.  

Competitive Landscape and Industry Direction 

Microsoft’s new approach puts pressure on other cloud providers. Businesses will start to expect the same level of control from all platforms.  

The industry as a whole is moving toward layered AI systems. Basic agents handle tasks; supervisor layers control and coordinate; and governance frameworks ensure everything follows the rules.  

This layered setup shows how complex enterprise AI is becoming. It recognizes that autonomy needs structure to work at scale.  

The Next Phase of Controlled Autonomy 

Microsoft’s supervisor layer sets a new standard for managing smart systems. It shows that autonomy should be guided, not left to its own devices.  

As enterprises expand their use of meta-agent systems, the need for coordination will only intensify. Systems that can resolve conflicts before they surface will define the next phase of AI infrastructure.   

The real change is in how organizations view control. It is not a limitation, but a way to achieve reliable growth.

Source: Microsoft Foundry documentation 

Firmware logs emerging from NVIDIA’s Arizona fabrication environment reveal a system quietly rewriting how large-scale compute believes, behaves under stress. Engineers observed GPU nodes failing, rerouting, and reintegrating without human intervention. This development sits at the center of AI infrastructure in the USA, self-healing clusters, and GPU automation, where uptime is no longer tied to manual oversight. The implications extend beyond performance into governance and trust.  

Inside NVIDIA’s Experimental Cluster Design 

NVIDIA’s test environment is different from a standard lab. It closely matches real NVIDIA data centers where thousands of GPUs work together in tightly managed clusters. These clusters run distributed workloads that need constant coordination.  

The Arizona facility serves as a controlled testing ground. Engineers intentionally introduce failures to see how the system reacts. Rather than sending alerts, the system automatically fixes these problems.  

This change moves away from traditional fault management. In the past, engineers checked every recovery step. Now, the firmware and orchestration layers make these decisions automatically.  

How Self-Heal Mechanisms Operate 

Failure detection and autonomous rerouting in AI infrastructure, USA. Self-healing clusters, GPU automation. 

The system’s main feature is fast failure detection. GPUs continuously send telemetry signals, which are continuously checked. If something unusual happens, the system isolates the affected nodes in milliseconds.  

The system then moves workloads to healthy nodes. This is similar to rerouting traffic in a network, but on a much larger scale. It helps prevent a single failure from causing larger outages.  

These actions are governed by embedded AI recovery systems. They rely on historical patterns and predictive modeling. The system doesn’t just react; it anticipates instability.  

Role of Cluster Orchestration Layers 

The orchestration layer serves as the system’s decision maker. It manages resources, moves tasks, and keeps the system balanced. This is why cluster orchestration is so important.  

Unlike fixed schedulers, this system adapts in real time. It changes how computing power is distributed based on current needs. This flexibility helps clusters keep performing well even under pressure.  

This orchestration works closely with hardware signals. It connects the hardware and software layers. The result is a single control node that makes decisions quickly.  

Operational Gains and Efficiency Metrics 

Initial results from the Arizona tests show clear improvements. Downtime is shorter and happens less often. Sometimes failures are fixed so quickly that outside monitoring tools do not even notice them.  

This directly affects NVIDIA data centers. Less downtime means higher usage rates and less work for engineering teams.  

Efficiency improvements also reduce energy use. By spreading out workloads, the system avoids overloading certain nodes. This results in more balanced power use across the cluster.  

The Trade-Off: Visibility Versus Autonomy 

Reduced human oversight in AI infrastructure usage, self-healing clusters, and GPU automation. 

While autonomy makes systems more resilient, it also brings new challenges. Engineers can no longer see every step in the recovery process, which makes it harder to audit what happened.  

In traditional systems, every failure and fix is recorded for review. In this new setup, many actions happen out of sight. The system often solves problems before any alerts are sent.  

This creates gaps in monitoring. It becomes harder to find the root cause of problems later. For industries with strict rules, this lack of transparency could be a serious issue.  

Risks in AI-Driven Recovery Decisions 

The reliance on AI recovery systems also introduces uncertainty. These systems make decisions based on learned patterns. While effective, they are not always explainable.  

Unexpected interactions between nodes can cause problems that are hard to predict. Without human checks, these issues might last longer. This is especially worrying in critical environments.   

The main challenge is balancing speed and accountability. Quick recovery is important, but not if it means losing track of what happened. Each organization must decide how much control to keep.  

Implications for Future Data Center Architecture 

The Arizona experiment points to a bigger change in the future. NVIDIA data centers may focus more on autonomy than manual control. This could change how infrastructure is built and managed.  

Architectural data center designs will likely become more modular. Each part will need to work on its own, but still fit together smoothly. This aligns with the principles of large-scale cluster orchestration. Dors may also embed more intelligence directly into hardware. Stronger level decision-making reduces reliance on external systems. It brings resilience closer to the source of computation.  

Industry Response and Competitive Pressure 

Other companies in AI infrastructure are paying close attention. Autonomous recovery systems could set businesses apart. Those who use similar models may see better uptime and efficiency.  

However, whether these systems are adopted will depend on trust. Companies need to know how the systems act predictably. That’s why transparency and validation will be important.  

The conversation is shifting from capability to control. It’s no longer just about what systems can do, but how they do it. That distinction will shape future deployments.  

Balancing Autonomy And Accountability In AI Infrastructure USA Self-Healing Clusters GPU Automation 

The rise of self-healing clusters brings both benefits and challenges. Systems get stronger and more efficient, but the stacks that make them resilient become harder to see.  

Organizations need to rethink how they monitor these systems. Old tools might miss important details. New methods will be needed to see what’s happening without slowing down recovery.  

In the end, trust will decide if this model succeeds. Engineers need to feel confident in systems they can’t fully monitor. That confidence will shape how widely these technologies are used.  

Conclusion: Redefining Control in Autonomous Compute Systems 

NVIDIA’s Arizona tests show a major change in infrastructure design. Systems are starting to manage themselves, so they need less human help. This increases efficiency but also challenges old ideas about oversight.  

Bringing together cluster orchestration and smart recovery systems marks a new way of running data centers. The focus is now on keeping things running smoothly, not just on control. Still, this approach needs new ways to ensure accountability.  

As more companies use these systems, the industry will have to balance autonomy and oversight. The future of AI infrastructure will depend not only on how resilient systems are, but also on how openly that resilience is managed.

Source: Build a More Secure, Always-On Local AI Agent with OpenClaw and NVIDIA NemoClaw 

If just one credential is compromised, the entire hybrid environment can be put at risk. Many companies now face this challenge as identities spread across on-premises systems and multiple clouds. The biggest vulnerability is no longer the network edge; it is the way credentials are managed.  

In response, Google Cloud Security is now focusing more on protecting credentials in hybrid environments. They have added stronger identity controls and better integration with enterprise governance tools. The goal is to change how organizations check and monitor access across different systems, not just make small improvements.  

The Hybrid Identity Problem Isn’t Theoretical 

Hybrid environments are complex by nature. Many companies still use older applications on-premises while moving customer-facing tasks to the cloud. Credentials like API keys, service accounts, and OAuth tokens often move between these systems without consistent oversight.  

For example, a financial services company might run both internal trading systems and customer applications. A service account meant for internal use could accidentally get access to cloud analytics tools. Without a single view of all credentials, these overlaps can go unnoticed.  

This is why cloud infrastructure security and identity governance must work together. Google Cloud has improved its identity and access management (IAM) features, especially for hybrid setups.  

Strengthening Credential Lifecycle Controls 

Google Cloud’s recent updates are designed to reduce the risk of credential exposure at every step:  

  • Short-lived credentials replace long-standing keys, reducing the attack window period.  
  • Automated rotation policies ensure that even unused credentials don’t linger.  
  • Context-aware access evaluates user behavior, device posture, and location before granting permissions.  

These updates help meet stricter compliance requirements, especially in industries such as healthcare and finance, where audit trails and access controls must adhere to exact standards.  

Integrating Security Across Systems 

A common problem in hybrid environments is fragmentation. Security teams often use different tools for on-premises and cloud monitoring, creating blind spots.  

Google Cloud solves this by adding credential monitoring to its larger data protection systems. For example, the Security Command Center brings together signals from many sources, so teams can spot unusual activity like:  

  • Unusual login patterns across regions,  
  • sudden privilege escalations,  
  • dormant accounts becoming active.  

For example, a retail company preparing for busy shopping seasons can use these signals to spot suspicious vendor access during peak traffic. This lets teams act immediately rather than wait until after a breach.  

The Role Of Zero Trust Architecture 

Zero trust is now a practical approach, not just a theory. Google Cloud builds zero-trust principles into its hybrid security model. Every success request is checked, no matter where it comes from.  

This method strengthens enterprise security by making sure trust is never taken for granted. Even internet users must keep authenticating, especially when working with sensitive tasks.  

Compliance as a Design Constraint 

Regulators now have higher standards. Laws such as GDPR, HIPAA, and other regional regulations require strict controls over how credentials are created and used. Google Cloud’s new features address these needs.  

By building policy enforcement into IAM workflows, organizations can meet compliance standards without needing manual audits. For example:  

  • Access logs are automatically generated and retained.  
  • Policy violations trigger real-time alerts.  
  • Role-based access controls limit exposure to sensitive datasets.  

This approach makes security teams’ work easier and helps them stay ready for audits.  

Real World Impact: A Hypothetical Scenario 

Think of a global logistics company managing fleet data in many countries. Drivers, partners, and staff all need access to different systems. If a credential is compromised in one area, it could affect operations across the entire system.  

With improved Google Cloud security, the company can:  

  • Restrict access based on geographic context.  
  • Automatically revoke suspicious credentials.  
  • Monitor all identities from a centralized dashboard.  

The result is not only lower risk, but also smoother business operations.  

Balancing Usability And Security 

Security measures often fail if they get in the way of daily work. Google Cloud tries to balance strong controls with ease of use. Developers can still launch applications quickly, but with safety measures in place.  

For example, service accounts now come with predefined roles that follow cloud security best practices. This means there is less need for custom setups, which can sometimes create security gaps.  

At the same time, connecting with data protection systems helps keep sensitive information safe, even as more teams and regions get access.  

Where this Leaves Enterprise Security 

The move to hybrid credential security signals a broader shift in what matters to businesses. Identity is now the main line of defense. Companies that treat credentials as unchanging assets face more risk, while those that manage them actively become more resilient.  

Google Cloud’s new features now show a shift toward ongoing automated controls and better. For a company, this is more than a technical update. It is a key part of good governance.  

The next step will probably include more AI-powered threat detection and closer links between identity systems and business processes. As hybrid environments grow, how companies protect credentials across different areas will shape their security strategies.

Source: What’s new with Google Cloud 

The laboratory at Google’s Sycamore processor facility is no longer just the hum of dilution refrigerators; it is the sound of a structural shift in the physics of information. For decades, the primary problem in commercializing subatomic logic has been decoherence, the tendency of quantum states to collapse at the slightest thermal or electromagnetic touch. In early 2026, Google’s quantum computing efforts reached a pivotal inflection point by demonstrating a sustained reduction in logical error rates even as the physical chip scaled. This breakthrough suggests that we are moving past the era of noisy intermediate-scale quantum devices and toward the first generation of reliable error-corrected machines.  

The Engineering of Qubits Stability 

The heart of this milestone lies in the precision of qubit special stability, where researchers managed to suppress the noise that typically scrambles calculations. Unlike classical bits, which are either zero or one, qubits exist in a state of superposition. Maintaining this state requires temperatures colder than those of deep space and shielding that pushes the limits of materials science. By implementing a new grid-based architecture for their superconducting circuits, the research team achieved a ten percent improvement in the lifetime of their logical qubits. The progress shows that larger systems can become more stable when the right geometric controls are in place.  

This achievement is not merely a laboratory curiosity. It provides the necessary foundation for quantum research to move into complex chemical simulations that were previously impossible. For a pharmaceutical executive or a materials scientist, this means the timeframe for simulating molecular bonds at an atomic level has just contracted. We are seeing the transition from theoretical proofs to the conception of a programmable microscope for the subatomic world.  

Implementing Advanced Error Correction Systems 

The Achilles’ heel of quantum hardware has always been its fragility. To solve this, Google has deployed sophisticated error correction systems that distribute a single piece of information across multiple physical qubits. This redundancy allows the system to detect and flip a qubit’s state without actually measuring it, which would collapse the calculation. The latest data indicates that for the first time, adding more physical qubits actually reduced the logical error rate, a phenomenon known as crossing the breaking threshold.  

  • Surface code efficiency: The use of two-dimensional lattices enables the system to isolate errors locally, preventing them from cascading through the processor  
  • Real-time feedback loops: custom-built classical controllers now process error signals in nanoseconds, adjusting the quantum gates before decoherence can set in  
  • Thermal management: innovations in cryogenic wiring have reduced heat leakage into the processor, enabling longer gate sequences without a thermal reset.  

Managing the Quantum Security Risk 

As hardware matures, the conversation in C-suites is rapidly shifting toward quantum security risks. A stable, large-scale quantum machine could crack the RSA and ECC encryption standards that currently protect 95% of global internet traffic. While a cryptographically relevant quantum computer is still years away, the data intercepted today could be decrypted tomorrow. This harvest-now-decrypt-later strategy by adversarial actors makes the current focus on stability a double-edged sword for global finance.  

To mitigate this, the focus on post-quantum cryptography (PQC) has intensified. Government agencies and financial institutions are now racing to replace classical algorithms with lattice-based mathematics that are resistant to quantum attacks. This transition is a massive logistical undertaking. It requires updating every digital certificate, VPN gateway, and encrypted database in the corporate estate. Organizations that wait for the first crack to occur will find themselves irrevocably exposed.  

The Convergence of Quantum AI and Cloud 

The most immediate commercial application of these milestones is the acceleration of quantum AI. By offloading specific linear algebra tasks to a quantum processor, machine learning models can find optimal patterns in massive data sets with far fewer iterations. This hybrid approach, using classical CPUs for data ingestion and quantum units for complex optimization, is the new blueprint for high-performance computing. It turns out that Google quantum computing is not an island, but a specialized accelerator for the existing AI stack.  

Integration of these systems into the cloud integration strategy is already underway. Through the Vertex AI and Google Cloud platforms, developers can now access quantum-simulated environments that mirror the behavior of the latest Sycamore chips. This allows firms to write and test their code today, ensuring they are quantum-ready the moment the hardware scales. This cloud integration ensures that the power of subatomic logic remains accessible to more than just a handful of elite physicists.  

The Path to Commercial Cloud Quantum 

The availability of cloud quantum services represents the final stage of democratizing this technology. By offering access via standard APIs, the barrier to entry for a logistics firm or an energy company drops from $100 million in R&D to a manageable monthly subscription. This as-a-service model is essential for testing quantum advantage, the point where a quantum machine solves a real-world problem faster or cheaper than any classical supercomputer. Google’s quantum computing is positioning its infrastructure as the primary gateway for this transition.  

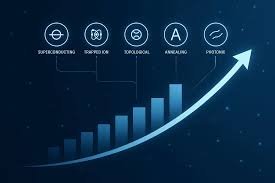
Furthermore, quantum research is increasingly focusing on cross-platform compatibility. As stability improves, the industry is moving toward a standard operating system for quantum gates. This would allow a researcher to write an algorithm once and run it on superconducting, trapped ion, or photonic hardware. This interoperability will be a catalyst for the surge in third-party software development, creating a quantum app store for specialized industrial problems.  

The stability milestones achieved this year indicate that the era of quantum theory has officially ended, and the era of quantum engineering has begun. The challenge for the modern executive is no longer understanding the physics, but preparing the organizational infrastructure for the arrival of non-binary logic. As we move toward the late 2020s, the quantum divide will separate those who can simulate reality from those who merely observe it. The focus must now shift toward crypto-agility and the aggressive adoption of hybrid workflows to stay ahead of the coming computational surge.

Source: AI & Machine Learning 

Security teams are drowning in alerts, yet breaches still slip through. A typical enterprise now tracks thousands of vulnerabilities, but only a fraction receive timely fixes. This imbalance has prompted the NIST NVD to rethink CVE prioritization, especially as cybersecurity risks grow in scale and complexity. The latest revisions aim to improve how organizations interpret data from the vulnerability database and respond to active security threats.  

Why CVE Prioritization Needs a Reset 

Volume Without Context 

The number of published vulnerabilities has surged over the past decade, yet not every entry in the vulnerability database carries the same level of risk. Many organizations still treat vulnerabilities as equal, relying heavily on severity scores without considering exploitability or business impact.  

This approach creates blind spots. A low-scoring issue tied to exposed APIs might pose a greater cybersecurity risk than a high-scoring flaw buried in an isolated system. The revised model from the NIST NVD aims to address the imbalance by emphasizing context over raw scoring.  

Shifting the Focus: From Severity to Exploitability.  

Real-World Threat Relevance 

The updated CVE prioritization framework places greater emphasis on whether vulnerabilities are actively exploited. This shift reflects the evolution of modern security threats. Attackers rarely target theoretical weaknesses; they focus on accessible, high-impact entry points.  

For example, if exploit code is found for a vulnerability in a popular authentication library, it becomes critical. With the new approach, these cases receive higher priority, regardless of their original severity score. This helps organizations match their fixes to real-world threats.  

The Role of Vulnerability Management Systems  

Moving Beyond Static Lists 

Organizations increasingly rely on vulnerability management systems to track and remediate issues. However, many of these systems still depend on static data fields that lack contextual insights. The revised prioritization model challenges vendors to enhance their platforms.  

Modern vulnerability management systems must now integrate dynamic data sources, including threat intelligence and exploit activity. This allows security teams to focus on vulnerabilities that pose immediate risks. It also reduces the noise generated by less relevant alerts.  

AI-Driven Discovery and Its Impact  

Identifying Patterns at Scale 

The surge in vulnerabilities has made manual analysis impractical. This is where AI-driven discovery is playing an increasingly important role. By analyzing large datasets, AI can identify patterns that human analysts might miss.  

For example, AI can spot links between new vulnerabilities and known attack campaigns. This helps organizations see possible threats early and prioritize fixes more accurately within the NIST NVD framework.  

Enhancing Cyber Risk Analysis  

From Data To Decision-Making 

Good cyber risk analysis is about more than just finding vulnerabilities. It means understanding how these issues affect business operations. The new CVE prioritization approach encourages organizations to look at the bigger picture.  

Take a financial institution that handles online transactions. A vulnerability in its payment system is riskier than one in a reporting tool used only inside the company. By conducting cyber risk analysis, organizations can allocate resources more effectively and reduce their risk.  

Enterprise Security Tools And Integration Challenges: Bridging Data Silos 

Many companies use several security tools, each handling different risks. But these tools often operate independently, limiting their effectiveness. The new prioritization model shows that better integration is needed. Meanwhile, by connecting enterprise security tools to centralized data sources such as the NIST MVD, service organizations can create a unified view of risk. This enables faster decision-making and more coordinated responses to security threats.  

Practical Implications For Security Teams  

Adapting To The New Framework 

The new CVE prioritization changes mean security teams need to work differently. Organizations should stop relying solely on checklists and adopt more flexible strategies.  

Key steps include:  

  • Incorporating threat intelligence into vulnerability assessments.  
  • Aligning remediation efforts with business impact.  
  • Leveraging automation to handle large volumes of data.  

These steps help organizations keep up with changing cybersecurity risks and use their resources more effectively.  

The Broader Impact On Cybersecurity Strategy 

Rethinking Risk Management 

The changes to the NIST NVD show a bigger shift in cybersecurity strategy. Organizations can’t just depend on standard scoring systems anymore. They need to think about context, how easily issues can be exploited, and the impact on their operations.  

This new way of thinking will also make it more important for companies to invest in technology tools that offer real-time analysis and work well with others. Organizations also need to ensure their processes can keep pace with evolving threats.  

Looking Ahead: A More Adaptive Security Model 

The changes in CVE prioritization show how security threats are getting more complex. As the number of vulnerabilities grows, organizations need to adopt more flexible risk management approaches.  

In the future, we can expect greater integration among data sources, more automation, and stronger predictive tools. AI and advanced analytics will play a larger role, helping teams make faster, more accurate decisions.  

Security teams that adapt to these changes will be better prepared for a world where threats are always evolving. Teams that cling to old models risk falling behind as attacks become more targeted and sophisticated. 

Source: National Vulnerability Database 

A one-second delay in a factory safety system can mean halted production or worse, yet many enterprises still rely on centralized processing that introduces latency at the worst possible moment. Microsoft is addressing this gap by extending Microsoft Azure AI capabilities into environments where decisions must be made instantly, pushing intelligence closer to devices through edge computing AI, and strengthening the foundation for distributed AI systems.  

Why Real-Time AI Demands New Architecture  

Moving Beyond Centralized Models 

Conventional cloud processing sends data from devices to central servers, which then return insights. This process works for analytics, but is too slow for situations where timing is critical. Industrial robots, self-driving cars, and live video analysis need responses in just milliseconds.  

Microsoft’s solution creates a cloud edge infrastructure that handles data locally while still working with central systems. This mix enables real-time AI while keeping things scalable. It also saves bandwidth by sorting data at the edge before sending it on.  

Microsoft Azure AI and Edge Computing AI 

Bringing Intelligence Closer to Action 

Microsoft has made Azure AI work smoothly in edge environments. This means it can connect to IoT devices, on-site servers, and locations with unreliable internet access. The main goal is to let edge AI work on its own when needed while still staying connected for updates and management.  

Take a logistics company with a fleet of delivery vehicles. Rather than sending all data to the cloud, the vehicles’ systems analyze routes, traffic, and driver habits right on board. This allows for instant decisions, making things safer and more efficient. At the same time, summary data is sent to central systems for bigger picture analysis.  

Distributed AI Systems in Practice 

Coordinating Intelligence Across Locations 

Distributed AI systems are advancing, making decisions across more places, not just one. Instead of using a single processing center, intelligence is shared across many points. Each one does its own job while also helping the whole system.  

The model is particularly effective for low-latency systems. For example, in smart manufacturing, sensors detect anomalies and trigger immediate responses without waiting for cloud confirmation. At the same time, data flows to centralized platforms for long-term optimization.  

Microsoft’s architecture supports this balance by enabling consistent model deployment across environments. Developers can build once and deploy across the cloud and edge with minimal changes, simplifying enterprise AI deployment.  

Cloud Edge Infrastructure and Performance Gains 

Reducing Latency Without Losing Scale 

Latency remains the defining challenge for real-time applications. By extending cloud edge infrastructure, Microsoft reduces the physical and network distance between data and computation. This directly improves response times.  

The advantages go beyond just speed. Processing data locally means systems don’t always need to be online, which is important for remote or mobile settings. It also keeps sensitive data closer to where it’s moved, improving security.  

Industries like healthcare and finance, where privacy is crucial, can use this method to comply with regulations while still performing well. Mixing local processing with central control makes systems stronger and more reliable.  

Gaming Infrastructure AI as a Test Case 

Real-Time Demands at Scale 

Few factors demand faster responses than gaming. Multiplayer environments require synchronization across thousands of players, often in real time. Microsoft’s investment in gaming infrastructure AI highlights how edge capabilities can support these requirements.  

When AI models are placed closer to players, systems can better predict reactions, reduce lag, and improve the experience. This also helps create content that adapts to players’ actions.  

What works in gaming can also help other fields. Any tool or app that needs instant feedback can use these setups. This includes things like augmented reality, live streaming, and interactive training.  

AI Compute and Resource Optimization  

Balancing Power and Efficiency 

Deploying AI at the edge introduces new challenges around AI compute. Devices must process complex models without the resources of large data centers. Microsoft addresses this by optimizing models for efficiency and enabling flexible deployment options.  

Companies can decide where to allocate their resources based on each job’s needs. Important tasks can run locally while less urgent ones go to the cloud. This way, cloud resources are used effectively, and edge devices aren’t overloaded.  

Managing resources well also cuts costs. By handling only the needed data at the edge, companies avoid extra data transfers and storage fees.  

Enterprise AI Development Strategies  

Integrating Edge and Cloud 

Successful enterprise AI development requires a clear strategy that integrates edge and cloud environments. Microsoft provides tools that simplify this process, allowing organizations to manage models, monitor performance, and update systems from a central platform.  

Key considerations include:  

  • Identifying workloads that require real-time processing.  
  • Determining data residency and compliance requirements.  
  • Balancing cost, performance, and scalability.  

By addressing these factors, enterprises can build systems that deliver consistent performance across environments. The integration of edge and cloud also supports future scalability as workloads evolve.  

The Role of Low Latency Systems in Competitive Advantage. 

Speed as a Differentiator 

Speed is no longer a technical metric; it is a business differentiator. Companies that deploy low-latency systems can respond to events faster, improve customer experiences, and reduce operational risks.   

For example, in retail, real-time inventory tracking can prevent stockouts and optimize supply chains. In energy, immediate analysis of grid data can prevent outages. These capabilities depend on the ability to process data at the edge while maintaining coordination with centralized systems.   

Microsoft’s focus on real-time AI positions it to support these use cases effectively. By combining edge and cloud capabilities, the company enables organizations to act on data as it is generated.  

Resources and Further Reading 

For those evaluating edge AI strategies, the following resources provide deeper insights:  

  • Microsoft Azure AI documentation and product updates.  
  • Azure IoT Edge and hybrid cloud deployment guides.  
  • Case studies on edge AI in manufacturing and healthcare.  
  • Research papers on distributed AI systems and latency optimization.  

These resources provide practical advice on using and adopting edge AI solutions.  

Looking Ahead: The Future of Real-Time Intelligence 

Microsoft’s move into edge computing shows a broader shift in how AI systems are built and used. The focus is now on making systems faster, stronger, and more flexible.  

As distributed AI systems mature and cloud-edge infrastructure evolves, organizations will increasingly rely on intelligence that operates at the edge, where data is generated. Those who align their strategies with this direction will gain an operational edge, not through larger models, but through faster, more precise decisions.

Source: Azure Updates