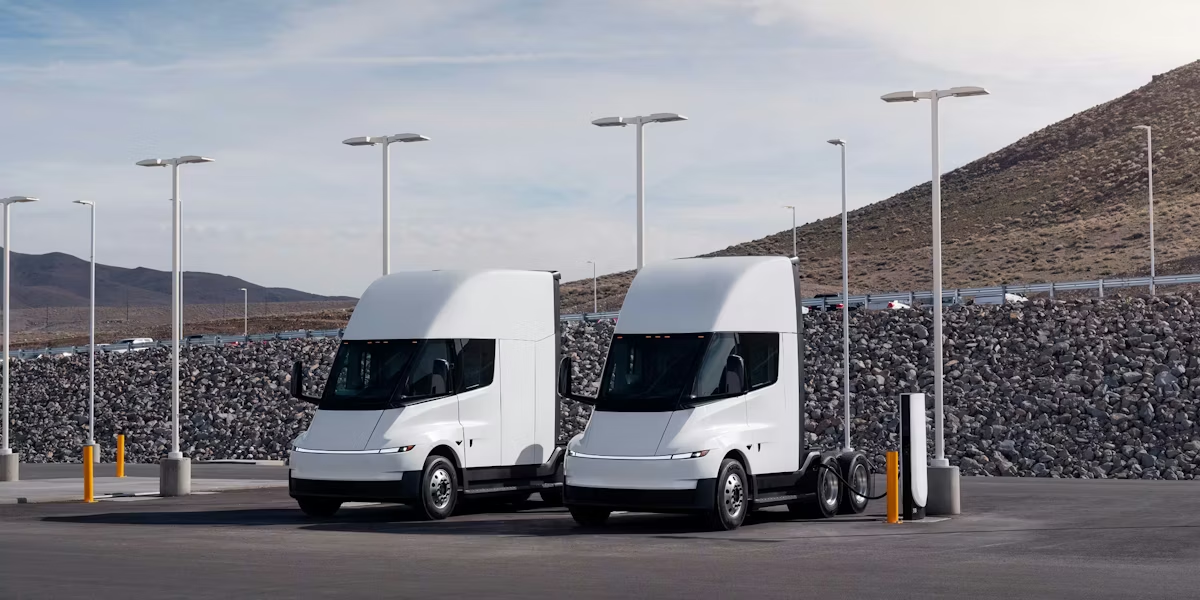
Austin, Texas: Margins in freight can disappear quickly. For example, a fleet operator with 200 Class 8 trucks might see fuel price swings change annual costs by millions. This is why many are looking at Tesla’s basecharger infrastructure, which is closely tied to semi manufacturing as a financial plan rather than just a sustainability move.   

The main question is no longer if electrification works. Now it’s about whether the financial numbers finally make sense.  

The Economics Behind the Tesla Basecharger Model 

The primary challenge in heavy-duty electric truck fabrication has always been infrastructure costs, depending on how much the system is used. Traditional high-output systems like the Mega Charger work great for quick charging, but they require major grid upgrades and high upfront costs. This meant that any fleet electrification only made sense for routes with heavy use.  

The Tesla basecharger takes a different approach. Most fleets do not run at full capacity all day, every day. Instead of focusing on fast charging, Tesla seems to be aiming for the lowest cost per kilowatt-hour delivered.  

This shift matters in a typical depot charging scenario. Trucks return to base overnight. Charging windows stretch across 6 to 10 hours. The need for ultra-fast charging diminishes, whereas infrastructure optimization becomes the dominant variable in logistics CapEx.  

Here’s a simple example. Imagine a region fleet with 50 electric trucks using Megachargers. Each truck requires a robust grid connection and cooling, which increases upfront costs. With the Tesla basecharger, slower but steady charging, lower installation complexity, and dynamic charging, the cost structure changes.  

Reframing ROI Through Infrastructure Design 

The real disruption lies in how ROI is calculated. Historically, commercial EV adoption hinged on fuel savings offsetting vehicle premiums. Infrastructure was treated as a sunk cost. That assumption no longer holds. New land with Tesla-based charging infrastructure becomes a strategic asset rather than a limitation. Lower installation costs and modular design let operators invest gradually as their fleets grow. This lowers financial risks and improves returns.   

A comparative cost analysis of Tesla base chargers versus megachargers for fleet operations clearly highlights this shift. While mega charger systems deliver higher throughput, their cost per installed megawatt often exceeds what mid-sized fleets can justify. Tesla base chargers, in contrast, lower the entry barrier, enabling greater participation in fleet electrification without excessively committing capital.  

High-speed charging still has its place. Long-haul routes will continue to need mega-charger networks, but for depot-based operations, a slower, more spread-out charging model now makes better financial sense.  

The Role of Semi-Manufacturing in Cost Alignment 

Infrastructure by itself does not change ROI. Vehicle production must match it. Tesla’s approach to semi manufacturing focuses on vertical integration to lower both vehicle costs and operational obstacles.  

Standardizing battery packs, simplifying power electronics, and making charging compatible all help reduce system complexity. This is important because fleet operators look at the whole ecosystem, vehicles, chargers, maintenance, and software, not just the trucks alone.  

When semi manufacturing works smoothly with depot charging via a Tesla base charger, the system behaves more like a single platform than a collection of separate assets. This reduces downtime, makes energy management more predictable, and simplifies financing.  

For CFOs, this means clearer depreciation schedules and more reliable cost forecasts. These two factors often decide if a project gets approved.  

Infrastructure Strategy Becomes a Competitive Edge 

Early adopters of commercial EV fleets learned that a charging strategy is key to profitability. If you build too much infrastructure, you tie up money in assets you don’t use. If you build too little, you encounter operational slowdowns.  

The Tesla base charger model brings a new path. It allows fleets to scale charging capacity incrementally, matching route density and vehicle deployment. Such flexibility reduces the risk associated with large upfront logistics CapEx commitments.  

At the same time, this changes how fleets compete. Those who use cost-efficient depot charging gain a real advantage. Their operating costs become more stable. They are no longer affected by diesel price swings and can bid on contracts with greater confidence.  

The comparative cost analysis of Tesla base chargers vs. megachargers for fleet operations underscores this advantage. It shows that while high-speed charging performs well in time-sensitive logistics, cost-optimized depot systems deliver stronger long-term margins for predictable routes.  

What This Means for Fleet Decision Makers 

Executives evaluating fleet electrification are no longer questioning whether the technology works. Now they want to know whether the financial model holds up under real-world challenges.  

The arrival of the Tesla base charger changes the equation. It shifts the focus from top performance to cost control. It matches infrastructure to real usage patterns rather than theoretical peaks, and it works closely with semi-manufacturing to reduce system inefficiencies.  

For many fleets, this will be the turning point. Electrification is not suddenly cheaper overall, but it is now more predictable, and predictability is what capital markets value most.  

A Structural Shift, Not A Tactical Adjustment 

Switching to a Tesla base charger is more than merely a new product. It denotes a greater change in how heavy-duty electrification is funded and implemented. Infrastructure is now central to ROI, not simply an afterthought.  

As more commercial EVs are adopted, the winners will not be those with the fastest chargers or the biggest fleets. Success will go to operators who bring together depot charging, logistics scheduling, and vehicle deployment into one clear system.  

This kind of alignment enables companies to rebuild their margins and shape the future of freight economics.

Source: Tesla Blog 
 Santa Clara, Calif.: Quantum processors usually make an error about once every thousand operations. Fixing this unreliability requires significant resources. IT teams often spend days manually tuning systems to run basic experiments. The NVIDIA Ising | Quantum AI framework changes this by automating calibration and fault correction. As a result, chief financial officers see calibration times drop from days to just hours when reviewing data center costs. 

The Cost of Traditional Calibration 

 
Manual calibration is a major cost for research institutions and tech companies. Technicians must continually measure and adjust physical qubits to preserve coherence. This ongoing work raises expenses and slows down research. 

The introduction of the new software alters the capital allocation strategy for enterprise quantum activities.  

Manual calibration is a major cost for research institutions and tech companies. Technicians must continually measure and adjust physical qubits to preserve coherence. This ongoing work raises expenses and slows down research. 

The introduction of the new software alters the capital allocation strategy for enterprise quantum activities. Instead of dedicating vast teams of physicists to manual adjustments, firms can deploy multimodal models to automate them. This change lowers the day-to-day operational burden and shifts the focus toward hybrid computing environments. 

Lowering the Financial Burden 

 
Procurement teams now need to consider how NVIDIA Ising in open models affects their hardware budgets. When labs use these new tools, less manual work is required, allowing managers to allocate more resources to high-performance computing clusters. Lower maintenance costs for delicate hardware make research and development more affordable. 

The news framework also uses a 3D convolutional neural network to decode errors as they happen. This lets current hardware handle bigger computations with fewer mistakes. Companies no longer need to buy additional processors to compensate for low accuracy. 

The Role Of Software-Driven Infrastructure 

 
Moving to software-driven calibration tools relies on the system’s architecture. The cuQuantum platform and its laboratories run on regular GPUs and connect to quantum processors through fast interconnects. This setup lets developers use open source AI to fix local errors before they become bigger problems. 

When companies use this architecture, they add classical GPUs to their current systems. This means some upfront spending on computing resources, but it saves money over time by extending processor lifespans. Using open-source AI also means researchers avoid paying for expensive software licenses, helping control costs. 

Integrating the Control Plane 

 
Modern machines need close coordination between different computing resources. Developers use CUDA Q to write mixed algorithms that run on CPUs, GPUs, and quantum units simultaneously. This flexibility allows research teams to adapt to different types of qubits without having to buy new controllers. 

For example, a national lab running large calculations on trap-ion hardware needs its control loop to keep up with the processor’s speed. By using CUDA-Q, the lab doesn’t have to build custom control hardware for every experiment. This standard approach lowers costs and enables faster evaluation of new designs. 

Managing the Shift in Infrastructure Budgets 
Switching to software-assisted direction changes how labs are built. In the past, organizations bought more physical qubits to boost computing power. Now they focus on balancing investments between classical GPUs and quantum computing units. 

Successful QPU integration requires laboratories to upgrade their interconnects to enable rapid communication between the GPU and the quantum chip. The NVIDIA Ising | Quantum AI framework needs these high-bandwidth connections to process error syndromes quickly. 

When upgrading, finance teams need to plan for the cost of faster interconnects. The upfront expense is balanced by the system’s data accuracy. With these tools, research institutions lower mistake rates and make their equipment more useful for applied optimization. 

Operational Modifications 

 
Enterprise infrastructure managers now face different choices when planning their annual budgets. The shift toward hybrid computing means that purchasing decisions emphasize data bandwidth over raw cubic count. The future of enterprise quantum infrastructure depends on this assimilation. Organizations that adopt the new AI models reduce their overall equipment spending while increasing the reliability of their systems. 

With the NVIDIA Ising | Quantum AI framework, companies can train their models on-site and keep their proprietary data secure. This local training lowers security risks and avoids the high costs of using external cloud services. 

Forward Looking Horizons 

 
AI-driven control systems are changing how labs manage their computing infrastructure. Companies that upgrade without planning for a software-first approach risk losing profit margins. The key measure for large hardware investments is the ability to scale processes while keeping costs steady.

Source: Nvidia Newsroom 

Redmond, Wash.: A Fortune 500 financial services company recently found that an automated workflow had been collecting sensitive client data for weeks because its permissions were too broad. This situation shows the serious security risks that autonomous AI agents can pose in enterprise Microsoft 365 environments. As these systems become more common in daily work, IT teams must prove that digital workers follow strict rules. The third-party audit is now the main way to test this. Organizations need to balance their first adoption of smart tools with the requirements of Agent 365 | AI identity protocols. 

When executives approve new automation, they often see it as just another software upgrade instead of a major change in how work gets done. This mistake can leave gaps in oversight. The Agent 365 | AI identity framework helps address this by providing unique, verifiable credentials to non-human entities. Without this step, IT teams cannot easily find the source of a problem or stop unauthorized access to old data. 

The Identity Crisis Within Modern Infrastructure 

 
Moving to agentic computing changes how we think about network security. In the past, security was focused on protecting people. Now it needs to focus on machines too. If organizations do not manage the identities of automated systems as carefully as they do for employees, serious problems arise. Microsoft security requires that every engagement be authenticated, but many companies do not apply this rule to non-human workflows. 

Administrators should use Entra ID to establish a clear access structure for these new automated entities. By treating automation as an important part of the identity system, companies can apply conditional access policies that adjust in real time. If a system tries to access something new, the policy should require another check. This helps contain any damage if an agent is compromised or behaves unexpectedly. 

The Governance Gap 

 
Good governance remains the most important hurdle for companies moving from pilot to production. Many teams deploy software without a clear understanding of the data pipeline. When autonomous agents make decisions, they create a trail of intent that requires constant monitoring. If the audit records are incomplete, compliance officers have no way to verify the rationale behind a major transaction. 

Real governance is more than just keeping logs. It means being involved in every stage of the agent’s life. Each automated entity needs a human sponsor who is responsible for what it does and what it can access. Without this accountability, there is no clear way to fix problems when they happen. 

Securing Compliance Under Pressure 

 
The 30-day audit period makes IT teams face tough questions about their setups. Are autonomous agents accessing files they should not? Does the Entra ID setup follow the concept of least privilege? These questions are hard to answer because developers may add new features so quickly. 

Microsoft Security offers the tools needed to see these connections clearly. By using built-in features to map how agents and data depend on each other, teams can spot over-privileged entities before they cause problems. This is not only about meeting compliance rules. It is an important step toward strengthening the system and supporting safer, faster innovation. 

The Future of Trusted Automation 

 
As agentic coding develops, trust will shape how people and machines work together. The most successful organizations will treat identity as the core of their operations, not just an extra step. Using the Agent 365|AI identity model gives companies the structure they need to grow safely. 

In the future, successful companies will treat user and machine access equally when assessing security risks. Each request will be seen as untrusted until it is verified. Leaders who accept this will find that strong security can help their businesses build trust into their systems, and businesses can create an environment where innovation and protection go hand in hand.

Source: Microsoft Source 

Washington, DC: One decision about materials can change the whole industry. When Apple’s supply chain leaders decided to use recycled cobalt, procurement teams across North America quickly noticed buying patterns. Supplier audits became stricter, contracts were renegotiated, and the real cost of sustainability became clear.  

The main challenge is not about appearances, but about controlling costs under pressure. Many executives now quietly wonder how Apple’s 100% recycled cobalt mandate will affect the costs of US tech manufacturing.  

The Deliberate Turn Behind Recycled Inputs 

Apple’s decision to use recycled cobalt in key battery components is about more than just demonstrating environmental commitment. It changes how Apple’s supply chain works with its suppliers, especially those involved with rare earth elements and battery materials.  

Historically, cobalt sourcing relied heavily on mined supply, often from geopolitically sensitive regions that exposed parts firms to procurement risks, price volatility, regulatory scrutiny, and reputational risks tied to labor practices. Through prioritizing recycled inputs, Apple narrows that exposure while complying with stricter ESG compliance frameworks now demanded by institutional investors and regulators.  

However, the switch is not free from challenges. The supply of recycled cobalt is still scattered. Refining abilities vary by region, and the quality of the refined product is sometimes lower than that of mined cobalt for certain uses. These issues make it harder to expand the use of recycled cobalt across Apple’s supply chain.  

Cost Pressures and Manufacturing Realignment 

The financial impact of using recycled cobalt is not simple or always negative. At first, costs rise because recycling facilities require investment and recycled materials require additional processing to meet battery standards.  

Federal incentives are starting to change the situation. Recent US policies offer subsidies for recycling facilities, tax credits for sustainable sourcing, and grants for advanced material recovery for manufacturers in Apple’s supply chain. These incentives help balance out the higher cost of recycled cobalt.  

Even so, executives need to balance two main pressures. They need to meet ESG compliance and investor demands, but they also face tight profit margins, especially in consumer electronics, where raising prices is challenging.  

Take, for example, a mid-sized battery supplier in Ohio. If it switches sixty percent of its cobalt to recycled resources, its costs could rise by eight to twelve percent in the first two years. But with federal incentives and long-term contracts with Apple, the company could steady its income and lower procurement risks, even with higher initial costs.  

Circular Economy As Competitive Advantage 

Switching to recycled cobalt is a real move toward a circular economy. Instead of the old model of extracting, producing, and discarding, the system now recovers materials from old devices and uses them again in new products.  

For the Apple supply chain, this creates a dual advantage. First, it insulates against disruptions in the rare earth elements market, where diplomatic strains can disrupt supply overnight. Second, it strengthens ESG compliance narratives, which increasingly influence capital allocation decisions.   

However, making this change work requires large-scale coordination. Recycling partners need to match production schedules, logistics must handle materials moving in both directions, and data systems have to track where materials come from for audits. Each step offers both difficulties and new opportunities.  

Procurement Risk In A Fragmented Market 

Even with strong policy backing, the market for recycled cobalt remains uneven. Supply focus among a handful of recyclers introduces new procurement risks. In contrast to traditional mining contracts, where output volumes are relatively predictable, recycled supply depends on collection rates and processing yields.  

Procurement leaders in Apple’s supply chain need a new approach. They must work with several recycling partners, set clear quality and volume terms in contracts, and update their forecasts to handle changes in recycled material availability.  

At the same time, using recycled materials reduces the risk of sudden regulatory changes in the rare-earth mining industry. The trade-off is less geopolitical risk but more operational complexity, which now shapes how procurement works.  

ESG Compliance Moves From Narrative to Enforcement 

Five years ago, ESG compliance was mostly about reporting. Now it is enforced. Regulators check sourcing details. Investors want to see real progress, and customers expect clear information.  

By embedding recycled cobalt into its sourcing strategy, Apple effectively raises the baseline for the entire Apple supply chain. Suppliers that fail to meet these standards risk exclusion. Those who adapt gain preferred partner status, often accompanied by longer-term contracts.  

This change also makes federal incentives more important. Companies that follow sustainability rules receive financial support, while those that do not may face higher costs and risk being left out of the market.  

The Cost Equation Executives Can’t Ignore 

The main question remains open: how will Apple’s 100% recycled cobalt rule affect US tech market manufacturing costs? Early data show higher costs at first due to limited supply and infrastructure, but as recycling grows and circular systems improve, these extra costs may go down.  

Executives should see this as a gradual change, not just a simple cost increase. Early investments deliver better benefits, such as lower procurement risk, stronger ESG compliance, and alignment with policy incentives. Over time, these advantages may outweigh the initial costs.  

A Supply Chain Reset in Motion 

Switching to recycled cobalt shows a bigger shift in industry priorities. Apple’s supply chain now focuses not just on cost and efficiency, but also on sustainability, resilience, and regulatory compliance.  

As federal incentives grow and circular economy models become more common, competition will change. Companies that adapt early will set new standards for costs and supplier partnerships. Those who wait may face fewer, but more costly, choices.  

This transformation is already happening, not through big headlines but through many small procurement decisions quietly changing the economics of US tech manufacturing. 

Source: Apple Newsroom 

 Round Rock, Texas: a typical deep learning studio wastes nearly 12 hours per week correcting color inaccuracies in generative model renders. This financial loss forces creative directors to rethink their monitor procurement cycles. When designers work with generative models, standard sRGB panels simply cannot display the true depth of the latent space. The introduction of the Dell UltraSharp | QD OLED AI solves this problem by providing precise contrast and high color precision. However, adopting this new monitor class requires clients to reexamine their overall computing budgets. Technology leaders must now calculate the hardware requirements for high-quality AI video generation monitoring before deploying these displays across their studios. 

The Economics of Dell UltraSharp | QD OLED AI Introduction 

 
Moving to quantum-dot OLED monitors means creative agencies must invest more. These monitors control each pixel, delivering an infinite contrast ratio and preventing color blooming found in older IPS or mini LED screens. For teams with strict model pipelines, this brings confidence. However, maintaining these high standards comes at a higher cost. 

When working with physical AI models, color precision can slow down operations. Designers must seek precise lighting plus shadows for their new neural networks. The Dell Ultrasharp | QD OLED Air meets this need by providing high-quality color. 

Organizations with complex modeling pipelines see higher costs when switching to OLED displays. Regular monitors do not perform well in bright rooms, so studios frequently need to lock costly light-controlled spaces. Dell solves this by adding special anti-glare tech to the panel surface. 

Take a large film studio training a physical AI algorithm for digital characters. The team checks each frame to ensure lighting and textures are correct. Achieving this level of visual quality adds about fifteen percent to the workstation budget. This extra cost is due to the micro-lens arrays needed for deep blacks and bright highlights. 

Advanced Panel Calibration and Ergonomic Demands 
Administering complex calibration is tough for corporate IT teams. Creative teams must follow strict rules for handling client color spaces. Monitors with DisplayHDR True Black 500 certification ensure training and output images display the correct gamma curves during grading. To meet these color standards, companies often need to choose more expensive monitors. 

Imagine a major production post-production firm checking footage from a visual synthesis engine. They need monitors with accurate hardware LUTs (lookup tables). This requirement raises the budget for visual synthesis workstations by almost 25% compared to regular office monitors. 

The higher price is due to the materials used in quantum dot panels. Since each pixel produces its own light, it creates more heat. This heat means the monitor needs active cooling inside. As a result, system administrators may need to change the studio layout to avoid overheating, which increases costs. 

Hardware Comparison in Professional Enhancements 

 
The difference between consumer and professional hardware is clear. Unlike the gaming-focused Alienware Pro series, professional monitors use uniform brightness stabilization. This feature prevents the screen from dimming on fully white backgrounds, so users can see image details clearly. 

Market Dynamics and Enterprise Budgets 

 
Switching to emissive displays changes the economic prospects for creative studios. In the past, hardware makers competed on brightness and refresh rates. Now, capabilities such as integrated anti-glare tech and pixel-level dimming are standard. This shift now affects chief technological officers as they plan their purchases. 

When planning hardware projects, finance teams need to include the cost of special panel features. For example, a typical 100-station audio sees display costs rise by 25% when switching to professional QD OLED models. This increase comes from panels being more complex to make. 

Picture a design team testing a video generation model. They need a display with Display HDR True Black 500 to see shadow details clearly. If the monitor cannot show these details, the team spends more time fixing and grading the footage. 

Professional features set this display apart from consumer options like the Alienware Pro. While Alienware Pro is built for low input lag and fast refresh rates for gaming, the professional model focuses on deep color and even brightness. 

Optimizing Budgets Under New Constraints 

 
Tech leaders need to cut these extra costs without losing visual qualities. One way is to use professional monitors only where needed. Instead of upgrading every workstation, teams can give the new displays to technical artists and colorists. This helps keep operating costs down. 

Another option is to use enterprise leasing programs for the new monitors. By agreeing to use them for three years, companies can reduce their upfront costs. 

Forward-thinking companies use monitoring means to track how OLED panels wear out. By reviewing daily usage, IT teams can remove unnecessary monitors and reallocate resources where they are most needed. 

Adding the Dell UltraSharp | QD OLED AI to a regular workstation setup changes how the studio works. The monitor needs different cables to handle high-bandwidth video without compression. Studios also need to upgrade their graphics cards and connection hubs. 

Future Horizons 

 
Bringing in quantum dot technology denotes a lasting change in how studios manage their budgets. Companies that upgrade screens without careful planning may see their profits and profit margins shrink. The key measure for large hardware investments is the ability to add more workstations without significantly increasing operating costs.

Source: Dell Technologies Newsroom 

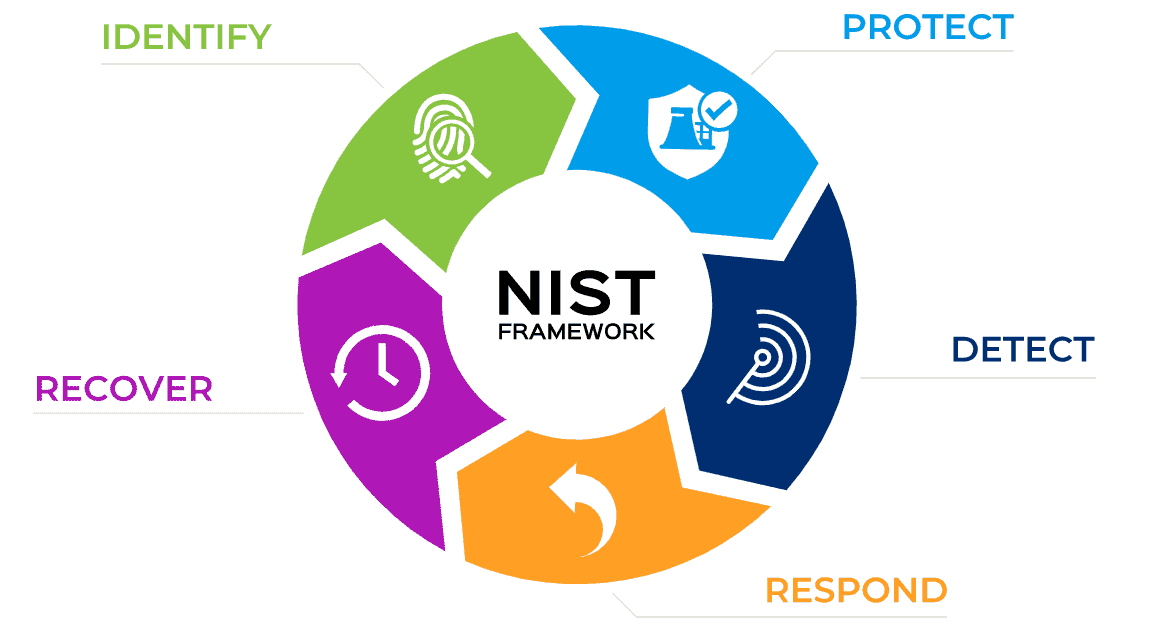
Redmond, WA.: a federal contract is paused due to one key issue: being ready for cryptography needs after 2030. The challenge is not about cost or performance, but meeting compliance standards. For Microsoft, this means Azure security must review identity systems built over the last ten years. NIST compliance is now a firm requirement in procurement, not simply a suggestion.  

The Compliance Trigger Behind Identity Overhaul. 

New rules from the National Institute of Standards and Technology mean most enterprise platforms need to adopt identity systems, including RSA and ECC cryptography, which could soon become outdated as post-quantum cryptography standards arrive. The deadline is approaching. Federal agencies expect vendors to present their plans for migrating to new standards before quantum threats become urgent.  

For Microsoft, this requires a new review of the authentication layers in Azure Active Directory. Azure security needs more than just minor updates. It needs a major redesign, especially in how credentials are created, verified, and stored across systems.   

These changes impact all Azure users, whether they work in healthcare, finance, defense, or any other sector.  

Azure security meets NIST compliance mandates. 

Compliance is more than just following a checklist. It shapes how systems are designed. The new NIST compliance rules require stronger identity assurance, such as phishing-resistant authentication and hardware-backed credentials. These rules support a zero-trust approach, where no user or device is trusted by default.  

Microsoft has begun making these changes, but the new standards raise the bar. Conditional access, multi-factor authentication, and device checks now need to work well with quantum-resistant algorithms. Engineering teams must rethink how to keep systems fast, scalable, and compatible.  

At the same time, identity protection is progressing beyond just detecting unusual activity. It is becoming a system that can predict when credentials may be at risk, even in the face of new threats like advanced quantum technology.  

The Role Of Cloud Sovereignty In Identity Design. 

Compliance requirements now mix with political issues. More governments are seeking cloud sovereignty, meaning data and identity systems must remain within their own countries. For Azure, this means identity-based services operate separately and independently. For example, a European defense contractor cannot use identity checks that pass through US systems. This makes Azure security design more complex because encryption, key management, and authentication must comply with local laws while meeting NIST requirements.  

The result is a layered identity system. One layer gives regions control, while another maintains global policies. Keeping both secure without adding risks is a major change for engineers.  

Procurement Pressure And The Federal Mandate 

The main driver is that federal procurement contracts now clearly note the impact of NIST post-quantum standards on U.S. government cloud deals. Vendors must demonstrate compliance now and have a plan to adapt their cryptography going forward.   

Failure to meet these requirements has direct financial consequences. Losing even one contract could cost billions of dollars. For Microsoft, updating identity systems is essential to remain in the government cloud services market.   

This pressure goes beyond federal agencies. State governments and regulated industries often follow federal standards, spreading NIST compliance requirements into the private sector.  

Engineering the Shift to Post Quantum Identity 

Switching to post-quantum cryptography brings technical challenges beyond simply changing algorithms. Key size increases, modifying how data is saved and sent. Authentication steps must be improved to avoid slowing performance, especially in large organizations.  

Microsoft engineers also need to ensure older systems work. Companies cannot switch everything at once. Using both classical and quantum-resistant algorithms together is necessary. This effort adds extra work but keeps systems running smoothly.  

At the same time, zero-trust systems require constant checks every time someone tries to access something. The system must verify it with cryptography. This makes efficiency crucial. If not designed well, the system could slow down users.  

Identity Production as a Tactical Layer 

As threats evolve, identity protection is becoming a key part of strategy, not just a reactive measure. Machine learning now looks for unusual behavior that may indicate credentials are at risk. With new compliance rules, these systems must work with cryptographic protections to build strong, layered defenses.  

If an employee’s credentials are exposed, older systems might only reset the password and send alerts. With improved Azure security, the system now adds additional authentication steps, separates sessions, and assesses risk using both behavioral and cryptographic analysis.  

This new type of integration highlights a broader trend in NIST compliance: security is built into every part of the system, not added later.  

Strategic Consequences for Enterprise Leaders 

Executives face a challenging environment. Investing in cloud systems now means committing to and evolving compliance standards. Choosing Azure means adhering to Microsoft’s security and NIST compliance standards.  

The benefits are evident: advanced security, compliance with federal standards, and preparedness for future threats. But there are also risks. The costs of moving, integration issues, and potential disruptions could be considered in long-term plans.  

Organizations that update identity policies, invest in hardware-backed authentication, and follow zero-trust principles will handle this transition more smoothly.  

The combination of compliance, cryptography, and procurement is changing cloud identity in significant ways. How Microsoft responds will determine the future of Azure security and alter the broader enterprise world.  

As quantum computing becomes a reality, the need for NIST compliance will increase. Identity systems must keep up, upholding security, ease of use, and regulatory requirements.  

Organizations that view this change as an opportunity to improve rather than just a compliance task will be better prepared for a future where trust is always verified and never assumed.

Source: A podcast from Microsoft and Gimlet Creative about making the future happen 

Cupertino, Calif.: A finance chief updating a company laptop notices something unusual. Workflows that used to need cloud services now run on local machines, cutting recurring costs by half. This change starts with the hardware, not the accounting. Newland, the launch of the Apple M3 Pro is changing how companies judge laptop performance, especially for LLM processing. Tasks that once required powerful servers can now run on a laptop, affecting both performance standards and overall costs.  

The Economics of Logical Intelligence 

For a long time, companies saw cloud costs as unavoidable for AI tasks. But as LLM processing moves to local devices, that is changing. With on-device AI tasks like document summarization, code generation, and internal searches run locally with little delay, this leads to fewer API calls, less bandwidth use, and less risk from changing cloud models.  

Take a legal team reviewing thousands of contracts. Before, every search used a cloud model, which added costs each time. With an Apple M5 Pro running macOS Tahoe, the same work can be done on the laptop with uniform performance and no extra fees. Over three years, these savings add up and lower operating costs.  

Apple M5 Pro and the rise of efficient LLM processing 

Performance depends on the chip design. Apple’s approach is based on strong NPU performance instead of relying on separate GPUs. The MacBook Pro 2026’s neural processing unit handles complex tasks efficiently, moving– improving battery life and consistent performance.  

This has real benefits. A data scientist tuning models does not have to wait for cloud delays. LLM processing happens instantly, so experiments go faster. Over time, this speeds up development and improves productivity.  

macOS Tahoe also brings better integration between the system and AI tasks. Built-in APIs let business apps use on-device AI without major changes. This reduces development work and speeds up company-wide robots.  

Procurement Shifts And Budget Realignment 

The implications reach beyond engineering teams. Enterprise procurement departments now face a different calculus. Instead of budgeting for high recurring cloud expenses, they can justify greater upfront hardware investments in devices like the MacBook Pro 2026 equipped with Apple M5 Pro.  

A mid-sized consulting firm shows how this works. By moving 40% of its tasks to local devices, it saved almost $1.2 million a year on cloud costs. The team used those savings to buy better laptops and broke even in 18 months. This approach changes how companies buy equipment, favoring upfront spending with steady depreciation instead of unpredictable operating costs.  

Performance Benchmarks, and Practical Impact 

Raw benchmarks only tell part of the story. What matters is continuous improvement, performance, and real workloads. The NPU performance in Apple’s latest chips enables parallel processing of multiple inference tasks without throttling. This proves critical for professionals who run concurrent applications, IDE environments, data visualization tools, and AI assistants on a single machine.  

Older systems struggle to keep up as workloads grow. This is clear during long work sessions. Developers who compile code and run local models experience fewer slowdowns on the MacBook Pro 2026, leading to fewer interruptions and more work per hour.  

Evaluating The Long-Term Return 

ROI is a key topic. Comparing the M5 Max to the M1 Max for local AI work is helpful. Early users say the new chips cut outside computing needs by up to 60%, and they speed up development cycles even before cloud computing is tested. Even before factoring in cloud savings, the productivity boost makes the upgrade worthwhile.  

On-device AI also improves privacy, which is increasingly important to companies. Sensitive information stays on the device, meeting stricter rules. This reduces legal risks and simplifies data management.  

Strategic Consequences for Enterprise Leaders 

Leaders making tech decisions now need to consider a mixed approach in which laptops handle more of the computing. With Apple M5 Pro, better LLM processing, and strong NPU performance, companies can rely less on central servers.  

This shift does not remove the need for the cloud. Instead, it changes how it is used. Large-scale training and specialized tasks still run in data centers, while everyday tasks move to local devices. This leads to better resource use.  

This change also affects hiring. Teams with powerful laptops need fewer infrastructure specialists. Developers and analysts can work more independently, reducing delays and speeding up decision-making.  

A New Baseline For Laptop Learning 

Old ways of judging business laptops like battery life, screen quality, and portability are not enough anymore. Now, value comes from how well a laptop handles LLM processing, works with macOS Tahoe, and supports on-device AI.  

Companies that adapt to this change early will adjust their pricing accordingly. Those who wait may end up with higher costs and slower progress.  

As chips continue to improve, the line between local devices and data centers will blur further. The MacBook Pro 2026 shows what is coming: Computing that is closer to the user, more efficient, and easier to control.

Source:  PRESS RELEASE Apple reports second quarter results 

Santa Clara, Calif.: Enterprise data centers are dealing with a $12 billion shortfall in accelerated computing investments. Because of this, large cloud providers need to quickly reconsider how they buy hardware. For example, when Microsoft reviews its early data center spending, it moves from Blackbird to the AI infrastructure. Velocity means making fast changes. Developers are planning bigger models that can plan, run code, and handle complex tasks on their own. These new workloads need updated hardware to prevent slowdowns. Microsoft has changed its buying strategy to support the next generation of agentic AI systems.  

Why the AI infrastructure | Vera CPU Reshapes Budgets 

Building a large-scale supercomputer requires a big investment from cloud providers. Switching from older chips to the latest hardware causes costs to jump quickly. The AI infrastructure, Vera CPU, uses ARM-based technology and LPDDR5X memory to reduce energy consumption, but the upfront costs remain very high.   

Consider a hyperscale deployment of 10,000 servers. The migration to new custom silicon requires teams to replace existing motherboard trays and liquid cooling systems. This upgrade cycle accelerates the Fiscal impact of autonomous AI agent hardware deployment, pushing technology executives to reassess their quarterly procurement budgets.  

The Economics of High-Density Interconnects 

The highest cost in today’s data centers comes from how hardware components are returned. The Rubin platform uses new interconnect technology, enabling its GPUs to transfer data at very high speeds. When engineers add a dedicated NVLink switch, data moves between processors smoothly without delays between chiplets.  

Upgrading the Server Topology 

To keep up with the bandwidth needs of trillion-parameter models, Microsoft has to buy thousands of these interconnect boards. Each ambivalent switch is expensive, adding millions to monthly spending. Because of this, finance teams often put off regular server upgrades and instead focus their budgets on specialized high-performance clusters.  

Testing centers such as THCC Horizon have found that using multiple racks requires major changes to buying structures. Facilities need to strengthen floors and upgrade power systems to support the heavy racks and high heat. These changes add extra costs that must fit into already tight budgets.  

Navigating Component Scarcity and New Architectures 

Lying strategies also have to consider logistics problems. High bandwidth memory, especially HBM4, is hard to make and often in short supply because there aren’t enough chips. Prices for the NVIDIA Rubin architecture go up.  

If a cloud region suddenly sees more demand for reasoning models, the provider can’t easily switch to other hardware. Their software is built for the NVIDIA Rubin design, so they are locked in and have little power to negotiate better prices.  

The Role of Testing Facilities 

Centers like TACC Horizon give important data on how well systems work. They test new chip setups under heavy use. Their findings show that running thousands of software environments simultaneously requires a balanced mix of CPUs and GPUs. Microsoft uses this data to make better hardware buying decisions and keep its server racks running efficiently.  

Managing the Shift toward Autonomous Systems 

As data centers move to self-directed, reasoning workloads, their power and space requirements change. Software now does more than summarize text. It handles complex tasks and connects to outside databases. This kind of agentic AI needs large context windows and fast processing. To sustain this performance, the data center’s CapEx must shift toward specialized processing units. Microsoft must allocate a larger share of its budget to two chips designed specifically for data movement and cognitive reasoning.  

Conclusion: The Horizon of Data-Center Economics 

Switching to new accelerated processing platforms denotes a lasting change in how companies spend on technology. If businesses upgrade hardware without careful planning, they could see their profit margins shrink. And the key measure for data center investments is to grow service clusters while keeping costs steady.  

Source: Nvidia Newsroom 

SAN DIEGO, Calif. —A recent chipset-level upgrade to Qualcomm edge  AI chips update 2026 is driving innovation across connected devices and proving its impact on the future of the US market in the smartphone, wearable, and IoT sectors. As demand for more sophisticated solutions that run faster and more efficiently grows, edge AI products have become essential. The recent upgrade, completed in just six hours, made significant progress in chip-level processing without requiring excessive interaction with cloud-based solutions. In turn, the demand for mobile AI chips and intelligent systems is growing increasingly rapidly. 

On-Device Edge AI Evolution 

With the update, there is a substantial improvement in Snapdragon on device AI Inference functionality, enabling data processing on-device without requiring off-device server processing. This makes processes faster, more efficient, and more private. 

Some of the changes made are: 

  • Inference is faster through edge AI cloud dependency reduction 
  • Performance is improved in IoT smart device AI acceleration USA 
  • Efficiency in the IoT AI environment 
  • Processing optimization from mobile AI chips 

Patent / Spec Signal 

The update supports patents submitted to the United States Patent and Trademark Office related to edge AI acceleration and low-power inference systems. On-device processing is emphasized. This suggests that Snapdragon on device AI intereferance and edge computing will continue to improve, enhancing AI performance in IoT smart devices AI acceleration USA. 

Cross-Manufacturer Ripple Effect 

The update is making a ripple effect in the wider smart device environment: 

  • Apple emphasizes on-device intelligence. 
  • Samsung advances AI features on smartphones. 
  • Use of fewer cloud-based processing systems 
  • More features of AI in IoT smart devices AI acceleration USA 

As Qualcomm’s edge AI chip update 2026 continue to develop, competition will increase in the mobile and IoT industries. 

Acceleration of Smart Device Growth. Industries are increasingly embracing intelligent systems, suggesting that Qualcomm’s edge AI update is positively affecting US smart device growth across industries. 

Among the positive impacts of the Qualcomm edge AI update on US smart device growth are: 

  • Edge AI devices growth 
  • AI devices expansion 
  • Mobile AI chips development 
  • Edge computing improvement 

This demonstrates that chips are making significant contributions. 

The Future of Edge AI Ecosystems 

There is an increasing trend toward edge computing as autonomous and intelligent devices proliferate. These developments have significantly transformed how data is collected and used. 

Trends in the future will include: 

  • Increasing the use of Snapdragon on device AI interferance 
  • Dependence on edge computing 
  • IoT AI applications will be widespread. 
  • Constantly innovating with mobile AI chips. 

These are some ways that edge AI devices are transforming the future of connectivity. 

Conclusion 

This new update to Qualcomm AI chips represents a major development for on-device AI. It is a step towards the future of smart devices through the use of edge AI devices. There are continued advances in Snapdragon on-device AI inference, edge AI, cloud dependency reduction, computing, and mobile AI chips, and devices are becoming more efficient and powerful. The integration of AI and IoT expands the possibilities in connected systems. All these developments point to the Qualcomm edge AI update, which is impacting US smart device growth.

Source: Qualcomm Newsroom

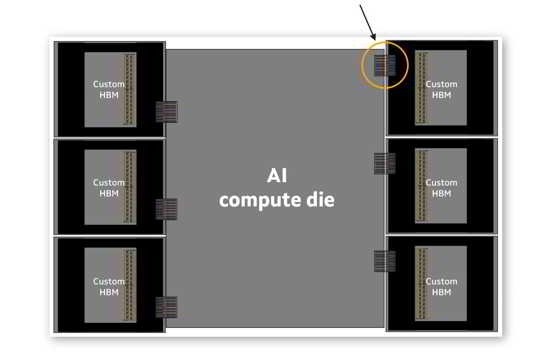
SANTA CLARA, Calif.:  There appears to be an ongoing silent revolution within the US cloud ecosystem, centered on the introduction of a highly efficient engineering update from Marvell AI accelerator chip 2026 that may well change the future architecture of hyperscaler computing systems. Given the increasing competition around performance and expenses, the move towards efficiency appears inevitable. In this case, efficiency comes from the use of purpose-built AI accelerators that can complete inference workloads faster and use less energy than general-purpose GPUs. The approach will allow cloud providers to tune specific computing processes without wasting excessive computing power. 

Efficiency Takes the Lead 

With the current engineering update, custom AI chip cloud infrastructure can perform specific workloads more efficiently. Rather than scaling out broadly, the cloud industry players are learning how to scale effectively. 

Among the most notable updates are: 

  • Enhanced inference acceleration in data center chips 
  • Energy-efficient chip deployment per task 
  • Real-time processing at lower latency levels 
  • Cost-effective deployments on massive scales 

Influence on Hyperscaler Strategy 

Currently, the big cloud players are adapting their AI inference GPU alternative hyperscaler strategy towards domain-specific silicon. This update reflects the broader industry trend, as custom silicon is increasingly seen not only as an addition to GPU clusters but also as an alternative. 

  • Higher adoption of custom silicon among US-based cloud vendors 
  • Decreased dependence on GPU-focused architecture 
  • Increased adaptability of load distribution 

In doing so, the Marvell AI accelator chip 2026  offer another option in a market monopolized by GPU suppliers. 

Industry-wide Competitive Impact 

The ripple effect of this update has already begun to manifest. While NVIDIA continues to lead in training applications, inference optimization is emerging as the next frontier of efficient cloud infrastructures. 

  • US cloud vendors are fast-tracking the adoption of customized silicon solutions. 
  • GPU suppliers face challenges in inference-focused loads 
  • AI-accelerated hardware is becoming more popular for budget-oriented applications. 

As cloud AI chip cost efficency diversification continues, performance per dollar will become the new competitive metric. 

Cost Efficiency Takes Center Stage 

Among the most important consequences of this development is its impact on costs. Scalable but cost-efficient solutions are required for AI inference tasks. The integration of Marvells AI accelator chip 2026 enables cloud providers to reduce costs without sacrificing performance. 

In terms of cost efficiency: 

  • Reduced power usage increases margins. 
  • Silicon optimization eliminates unnecessary hardware. 
  • Efficient AI scaling avoids costly infrastructure redundancy. 

It sets the stage for specialized processors becoming a major factor in cloud infrastructure economics in the next generation. 

The Future Direction of Cloud Infrastructure Design 

Going forward, it is anticipated that cloud computing will migrate towards hybrid compute architectures that combine GPU and accelerator hardware. It would allow cloud providers to select the most efficient compute unit based on the workload’s requirements. 

Projected future trends include: 

  • Increased use of custom processors in data centers across hyperscale networks 
  • Experimentation with hybrid computing stacks 
  • Fast-evolving design philosophies among AI inference GPU alternative hyperscaler. 

With the growing role of AI accelerators, cloud infrastructure is likely to be defined by cost efficiency rather than scale alone in the future. 

Cross-manufacturer ripple effects 

In addition to the direct consequences for Marvell’s own offerings, we should consider the implications of the update for competitors and other market actors. 

  • NVIDIA encounters increasing competition for its inference-oriented deployments 
  • Hyperscale clouds continue developing their custom silicon strategies. 
  • AWS and Google broaden their efforts in in-house chip design 
  • Manufacturers drive developments in cloud hardware performance benchmarks. 

In light of such initiatives to rethink hyperscale infrastructure, the availability of Marvell AI chips allows companies to build flexible hybrid architectures. 

Economics of Cloud Infrastructure 

One of the most prominent implications of the update is cost-efficiency. To effectively support AI computations, cloud operators require a scalable, yet highly optimized, architecture. The introduction of a specialized processor from Marvell allows for a different approach to the economics of cloud buildout. 

These advantages can be listed as follows: 

  • Minimized operational expenses due to efficient computing 
  • Energy savings by optimizing the power consumption of data center processors 
  • Efficient use of the computing resource without over-provisioning 
  • Improved scaling strategies for cloud AI applications 

Conclusion 

The recent update on Marvell AI chip technology highlights the emerging trend in cloud infrastructure development. In its current form, this infrastructure tends to focus less on the power of its components and much more on specialization for specific purposes, thanks to AI accelerators. 

Following this trend, hyperscalers should expect increasing demand for AI scaling and optimal cloud hardware. The impact of these developments on innovation in data center chips and market competition suggests this change may become permanent. 

Overall, the development of such technology represents the first step towards a more productive and efficient future in the US cloud system infrastructure.

Source: Marvell Newsroom